

The DOI matches its Crossref record; 120 of the 120 references it cites were found in a registry or an index.
ChatGPT for shaping the future of dentistry: the potential of multi-modal large language model
Open accessAbstract
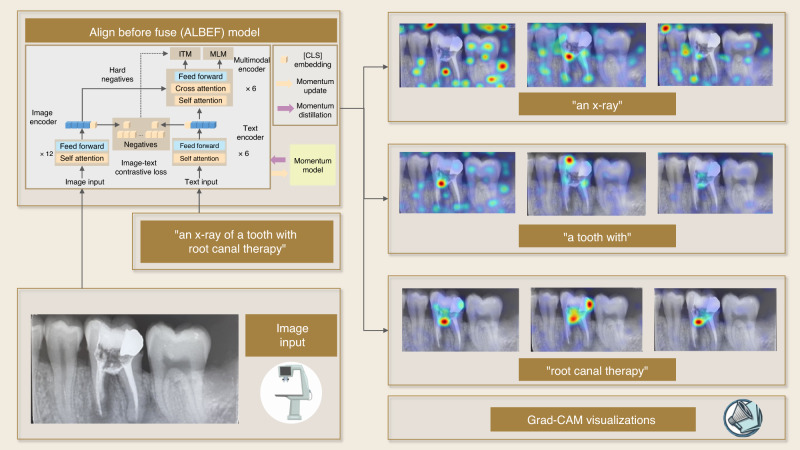
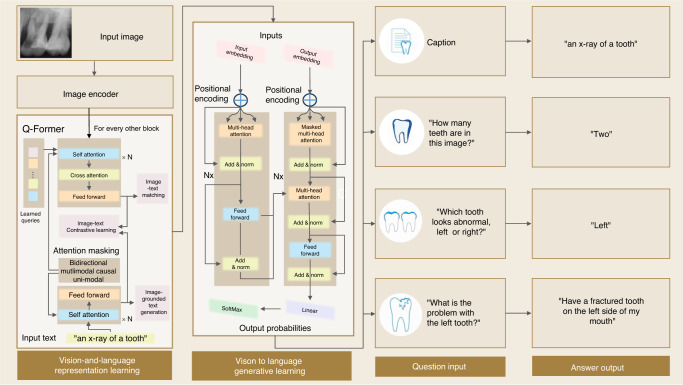
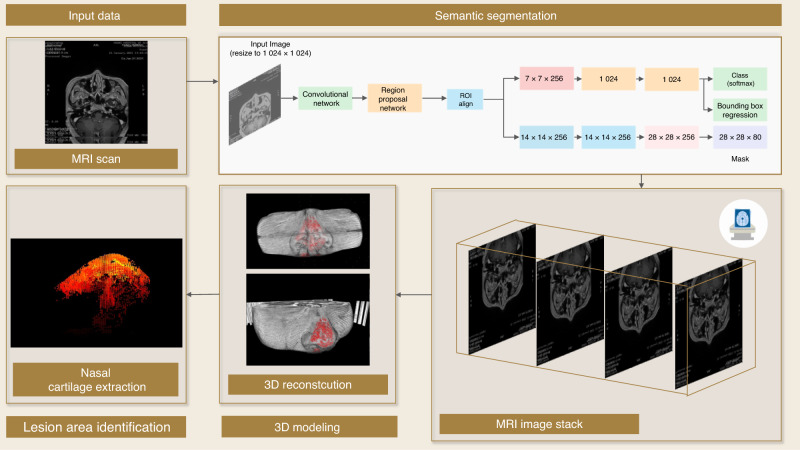
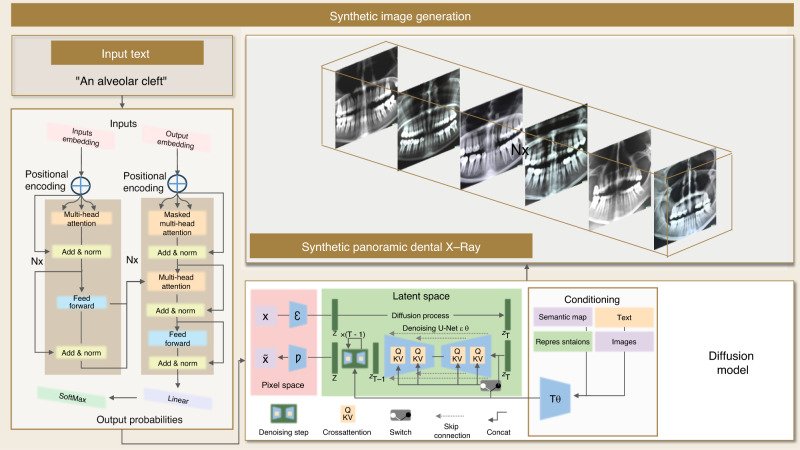
The ChatGPT, a lite and conversational variant of Generative Pretrained Transformer 4 (GPT-4) developed by OpenAI, is one of the milestone Large Language Models (LLMs) with billions of parameters. LLMs have stirred up much interest among researchers and practitioners in their impressive skills in natural language processing tasks, which profoundly impact various fields. This paper mainly discusses the future applications of LLMs in dentistry. We introduce two primary LLM deployment methods in dentistry, including automated dental diagnosis and cross-modal dental diagnosis, and examine their potential applications. Especially, equipped with a cross-modal encoder, a single LLM can manage multi-source data and conduct advanced natural language reasoning to perform complex clinical operations. We also present cases to demonstrate the potential of a fully automatic Multi-Modal LLM AI system for dentistry clinical application. While LLMs offer significant potential benefits, the challenges, such as data privacy, data quality, and model bias, need further study. Overall, LLMs have the potential to revolutionize dental diagnosis and treatment, which indicates a promising avenue for clinical application and research in dentistry.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
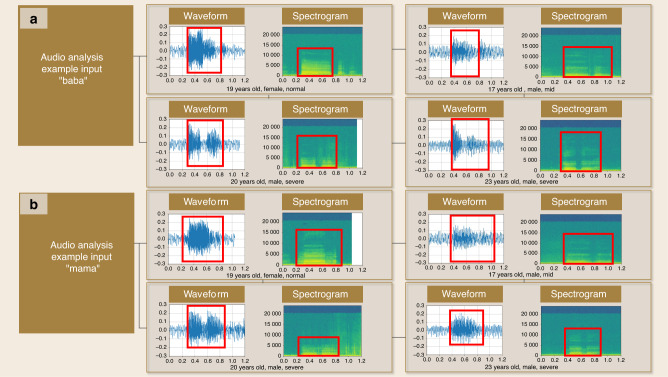
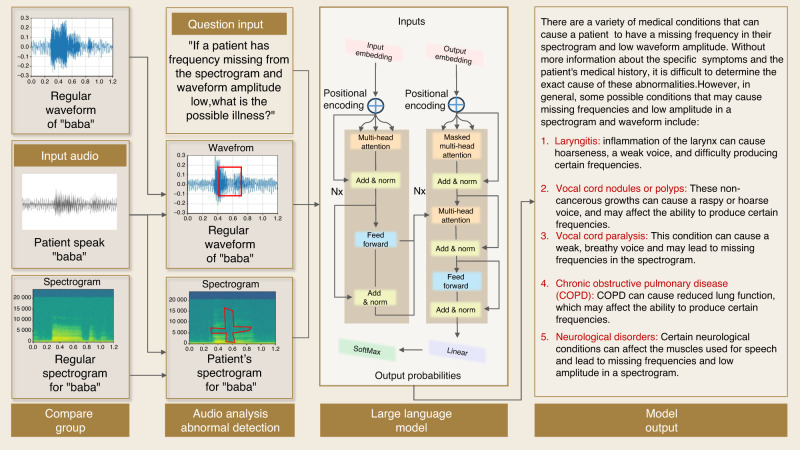
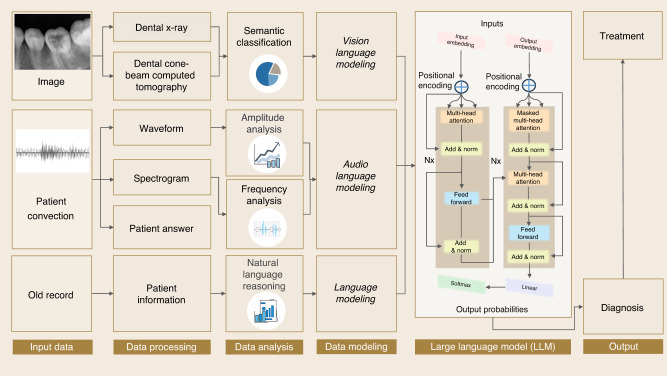
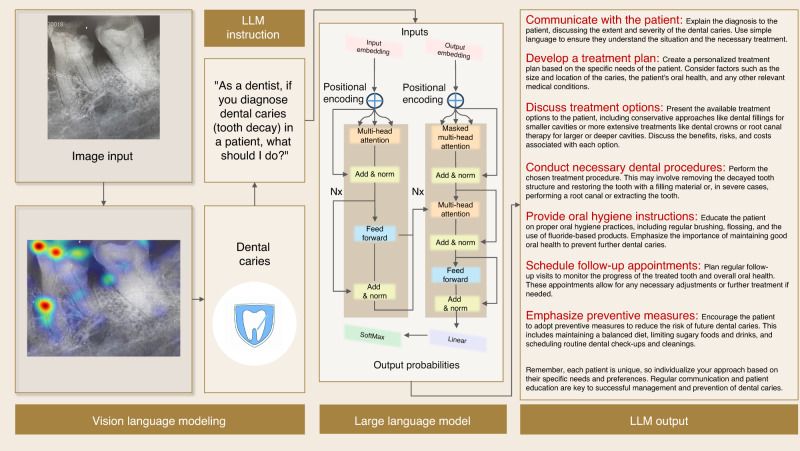
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“Third, although the challenges of integrating diverse data types into M-LLMs are recognized, there is limited exploration of possible solutions or ongoing research aimed at overcoming these technical barriers [38,39].”
From Multimodal Large Language Models in Health Care: Applications, Challenges, and Future Outlook. (2024) · cites this paper as [39]
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“First, the range of data modalities examined is often restricted to text, images, videos, and audio [38], with some studies focusing narrowly on a limited number of clinical applications [39].”
From Multimodal Large Language Models in Health Care: Applications, Challenges, and Future Outlook. (2024) · cites this paper as [39]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Highly accurate protein structure prediction with AlphaFold
Jumper, J., Evans, R., Pritzel, A., Green, T., Figurnov, M., Ronneberger, O., Tunyasuvunakool, K., Bates, R., Žídek, A., Potapenko, A., et al. (2021) · Nature · doi:10.1038/s41586-021-03819-2 · Cited by 43,764
High-Resolution Image Synthesis with Latent Diffusion Models
Rombach, R., Blattmann, A., Lorenz, D., Esser, P., & Ommer, B. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.01042 · Cited by 20,302
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
SciBERT: A Pretrained Language Model for Scientific Text
Beltagy, I., Lo, K., & Cohan, A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1371 · Cited by 3,218
Scalable and accurate deep learning with electronic health records
Rajkomar, A., Oren, E., Chen, K., Dai, A. M., Hajaj, N., Hardt, M., Liu, P. J., Liu, X., Marcus, J., Sun, M., et al. (2018) · npj Digital Medicine · doi:10.1038/s41746-018-0029-1 · Cited by 2,648
Self-citationPhotorealistic Text-to-Image Diffusion Models with Deep Language Understanding
Saharia, C., Chan, W., Saxena, S., Li, L., Whang, J., Denton, E., Ghasemipour, S. K. S., Ayan, B. K., Mahdavi, S. S., Lopes, R. G., et al. (2022) · arXiv · doi:10.48550/arxiv.2205.11487 · Cited by 2,528
Research works printed but not linked: 3
- Choi, E., Xiao, C., Stewart, W. & Sun, J. MiME: multilevel medical embedding of electronic health records for predictive healthcare. Adv. Neural Inf. Process. Syst. 31, 19 (2018).
- Ramesh, A., Pavlov, M., Goh, G., Gray, S., Voss, C., Radford, A. & Sutskever, I. Zero-shot text-to-image generation. In International Conference on Machine Learning, pp. 8821–8831 (PMLR, 2021).
- Gurram, S., Chan, D., Fang, A., & Canny, J. LAVA: Language Audio Vision Alignment for Data-Efficient Video Pre-Training. In First Workshop on Pre-training: Perspectives, Pitfalls, and Paths Forward at ICML (2023).
Cited by
Sorted by citations
Multimodal Large Language Models in Health Care: Applications, Challenges, and Future Outlook.
AlSaad, R., Abd-alrazaq, A., Boughorbel, S., Ahmed, A., Renault, M.-A., Damseh, R., & Sheikh, J. (2024) · Journal of medical Internet research · doi:10.2196/59505 · Cited by 349
“Recent studies [38,39] have explored the capabilities of M-LLMs within the health care sector.”
Giannakopoulos, K., Kavadella, A., Aaqel Salim, A., Stamatopoulos, V., & Kaklamanos, E. G. (2023) · Journal of Medical Internet Research · doi:10.2196/51580 · Cited by 227
Wang, L., Wan, Z., Ni, C., Song, Q., Li, Y., Clayton, E. W., Malin, B., & Yin, Z. (2024) · Journal of Medical Internet Research · doi:10.2196/22769 · Cited by 239
ChatGPT in Dentistry: A Comprehensive Review
Alhaidry, H., Fatani, B., Alrayes, J. O., Almana, A. M., & Alfhaed, N. K. (2023) · Cureus · doi:10.7759/cureus.38317 · Cited by 149
Metadata
- Authors
- Huang, H., Zheng, O., Wang, D., Yin, J., Wang, Z., Ding, S., Yin, H., Xu, C., Yang, R., Zheng, Q., & Shi, B.
- Affiliations
- Sichuan University (CN)
- University of Central Florida (US)
- Southwest Jiaotong University (CN)
- Corresponding author
- Huang, Hanyao
- Zheng, Ou
- ORCID
- Venue
- International Journal of Oral Science
- Published
- 2023-07-28
- Volume
- 15
- Issue
- 1
- Pages
- 29-29
- ISSN
- 1674-2818 (ISSN-L)
- 2049-3169
- PMC
- PMC10382494
- OpenAlex
- W4385346108
- Cited by
- 324
- References
- 97
- Citations by year
- 2026: 68 · 2025: 119 · 2024: 107 · 2023: 30
- FWCI
- 3.81
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- International Journal of Oral Science (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Funders
- Sichuan Provincial Postdoctoral Science Foundation (TB2022005)
- Sichuan University (RD-02-202107)
- Sichuan Province Science and Technology Support Program (2022NSFSC0743)
- West China Hospital, Sichuan University
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Health Sciences › Dentistry › Oral Surgery › Dental Radiography and Imaging
- Keywords
- ChatGPT, large language models, multimodal large language models, dental diagnosis, automated diagnosis, natural language reasoning, clinical decision support, data privacy, model bias, data quality
- MeSH terms
- Artificial Intelligence, Dentistry
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
