

The DOI matches its Crossref record; 3 of the 3 references it cites were found in a registry or an index.
A framework for mitigating malicious RLHF feedback in LLM training using consensus based reward
Open accessAbstract
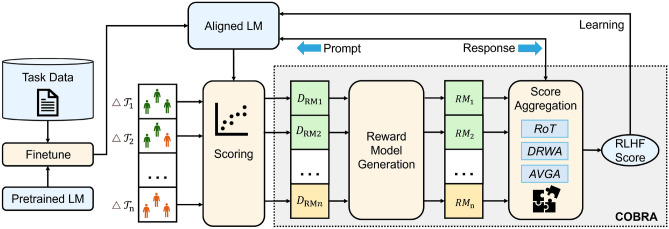
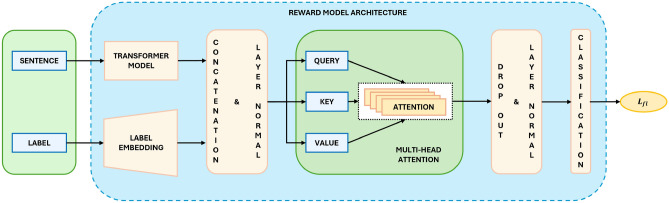
Large Language models (LLMs) have demonstrated impressive capabilities in natural language processing and understanding. LLMs are being rapidly adopted in major industry sectors including mobile computing, healthcare, finance, government, and education driven by technology giants such as NVIDIA, OpenAI, Microsoft, Apple, Meta, Google, Broadcom, AMD, and IBM. However, due to the emerging nature of this technology, many security/privacy challenges remain unresolved that we must tackle before rolling out LLMs to critical applications (e.g. Healthcare, Legal). In this article, we focus on the Reinforcement Learning via Human Feedback (RLHF) process that is widely used for training LLMs giving them the human-like feel most applications value. The RLHF process involves employing human experts to generate feedback based on an LLM's query-response pairs and using this feedback to then retrain (fine-tune) the model. However, RLHF can also expose the LLM to malicious feedback generated by one or more individuals in the process leading to degraded performance of the LLM and harmful responses. Most state-of-the-art (SOTA) solutions to this problem involve utilizing a KL-Divergence-based brute-force update-rejection approach that can render the whole RLHF process completely useless (model quality is not improved) in the presence of malicious entities in the process. We propose the COnsensus-Based RewArd framework (COBRA), a consensus-based technique that can effectively negate the malicious noise generated by a certain segment of the RLHF human-expert pool, leading to improved LLM training performance in a mixed-trust scenario. We have evaluated COBRA for two separate LLM use cases, Sentiment Analysis and Conversational Task. We have experimented with a wide range of LLM models (e.g. GPT-2 XL - 1.5B parameters). COBRA outperformed the standard unprotected reward generation scheme by [Formula: see text] for the generative conversational task and by [Formula: see text] for the sentiment analysis task. We have also quantitatively compared COBRA with Coste et al. and observed state-of-the-art performance, particularly when a lower number of reward models are used ([Formula: see text] increased reward accuracy at [Formula: see text]).
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Also, as [61] discusses, getting preference-based feedback is plausible for paid labelers but not for real users using real deployed systems.”
From RLHF Deciphered: A Critical Analysis of Reinforcement Learning from Human Feedback for LLMs (2026) · cites this paper as [61]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Deep reinforcement learning from human preferences
Christiano, P., Leike, J., Brown, T. B., Martic, M., Legg, S., & Amodei, D. (2017) · arXiv · doi:10.48550/arxiv.1706.03741 · Cited by 1,058
InfoRM: Mitigating Reward Hacking in RLHF via Information-Theoretic Reward Modeling
Miao, Y., Zhang, S., Ding, L., Bao, R., Zhang, L., & Tao, D. (2024) · arXiv · doi:10.48550/arxiv.2402.09345 · Cited by 9
Research works printed but not linked: 29
- Ziegler, D. M. et al. Fine-tuning language models from human preferences (2020). arXiv:1909.08593. · arXiv
- Bai, Y. et al. Training a helpful and harmless assistant with reinforcement learning from human feedback. arXiv:2204.05862 (2022). · arXiv
- Rando, J. & Tramèr, F. Universal jailbreak backdoors from poisoned human feedback. arXiv:2311.14455 (2023). · arXiv
- Gao, L., Schulman, J. & Hilton, J. Scaling laws for reward model overoptimization. arXiv preprint arXiv:2210.10760 (2022). · arXiv
- Wei, J. et al. Finetuned language models are zero-shot learners. arXiv:2109.01652 (2022). · arXiv
- Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. arXiv:1810.04805 (2019). · arXiv
- Radford, A. et al. Improving language understanding by generative pre-training (Tech. Rep, OpenAI, 2018).
- Vaswani, A. et al. Attention is all you need. Adv. Neural Inf. Process. Syst. 30 (2017).
- Zheng, R. et al. Secrets of rlhf in large language models part i: Ppo. arXiv preprint arXiv:2307.04964 (2023). · arXiv
- Schulman, J., Wolski, F., Dhariwal, P., Radford, A. & Klimov, O. Proximal policy optimization algorithms. arXiv:1707.06347 (2017). · arXiv
- Zellers, R. et al. Defending against neural fake news. Adv. Neural Inf. Process. Syst. 32 (2019).
- Gupta, A. & Krishna, A. Adversarial clean label backdoor attacks and defenses on text classification systems. arXiv preprint arXiv:2305.19607 (2023). · DOI
- Zhang, X., Ma, Y., Singla, A. & Zhu, X. Adaptive reward-poisoning attacks against reinforcement learning (2020). arXiv:2003.12613. · arXiv
- Goldblum, M. et al. Dataset security for machine learning: Data poisoning, backdoor attacks, and defenses (2021). arXiv:2012.10544. · arXiv
- Liu, Y., Yi, Z. & Chen, T. Backdoor attacks and defenses in feature-partitioned collaborative learning (2020). arXiv:2007.03608. · arXiv
- Casper, S. et al. Open problems and fundamental limitations of reinforcement learning from human feedback (2023). arXiv:2307.15217. · arXiv
- Coste, T., Anwar, U., Kirk, R. & Krueger, D. Reward model ensembles help mitigate overoptimization. arXiv preprint arXiv:2310.02743 (2023). · arXiv
- Wang, J., Wu, J., Chen, M., Vorobeychik, Y. & Xiao, C. On the exploitability of reinforcement learning with human feedback for large language models (2023). arXiv:2311.09641. · arXiv
- Baumgärtner, T., Gao, Y., Alon, D. & Metzler, D. Best-of-venom: Attacking rlhf by injecting poisoned preference data (2024). arXiv:2404.05530. · arXiv
- Dubois, Y. et al. Alpacafarm: A simulation framework for methods that learn from human feedback (2024). arXiv:2305.14387. · arXiv
- Guo, J. et al. Trove: A context-awareness trust model for vanets using reinforcement learning. IEEE Internet Things J. 7, 6647–6662 (2020). · DOI
- Guo, J. et al. Icra: An intelligent clustering routing approach for uav ad hoc networks. IEEE Trans. Intell. Transp. Syst. 24, 2447–2460 (2022). · DOI
- Xia, Y. et al. Fcllm-dt: Enpowering federated continual learning with large language models for digital twin-based industrial iot. IEEE Internet Things J. 1–1. https://doi.org/10.1109/JIOT.2024.3510553 (2024). · DOI
- Jiang, J. et al. Enhancements of attention-based bidirectional lstm for hybrid automatic text summarization. IEEE Access 9, 123660–123671 (2021). · DOI
- Mostafazadeh Davani, A., Díaz, M. & Prabhakaran, V. Dealing with disagreements. Looking beyond the majority vote in subjective annotations. Trans. Assoc. Comput. Ling. 10, 92–110. https://doi.org/10.1162/tacl_a_00449 (2022). · DOI
- Socher, R. et al. Recursive deep models for semantic compositionality over a sentiment treebank. In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing, 1631–1642 (Association for Computational Linguistics, Seattle, Washington, USA, 2013). · DOI · Paper page
- Radford, A. et al. Language models are unsupervised multitask learners. OpenAI Blog 1, 9 (2019).
- Bai, Y. et al. Training a helpful and harmless assistant with reinforcement learning from human feedback (2022). arXiv:2204.05862. · arXiv
- Wang, J., Wu, J., Chen, M., Vorobeychik, Y. & Xiao, C. Rlhfpoison: Reward poisoning attack for reinforcement learning with human feedback in large language models (2024). arXiv:2311.09641. · DOI
Cited by
Sorted by citations
RLHF Deciphered: A Critical Analysis of Reinforcement Learning from Human Feedback for LLMs
Chaudhari, S., Aggarwal, P., Murahari, V., Rajpurohit, T., Kalyan, A., Narasimhan, K., Deshpande, A., & Castro da Silva, B. (2026) · ACM Computing Surveys · doi:10.1145/3743127 · Cited by 92
“Various approaches have been proposed, such as SAFE RLHF with dual objectives for helpfulness and harmlessness [33], Equilibrate RLHF using fine-grained data-centric alignment [183], and the COBRA framework for mitigating biases by aggregating RMs [60].”
Metadata
- Authors
- Haider, Z., Rahman, M. H., Devabhaktuni, V., Moeykens, S., & Chakraborty, P.
- Affiliations
- University of Maine (US)
- Illinois State University (US)
- Corresponding author
- Haider, Zafaryab
- Venue
- Scientific Reports
- Published
- 2025-03-17
- Volume
- 15
- Issue
- 1
- Pages
- 9177-9177
- ISSN
- 2045-2322 (ISSN-L)
- PMC
- PMC11914620
- OpenAlex
- W4408507277
- Cited by
- 9
- References
- 3
- Citations by year
- 2026: 5 · 2025: 4
- FWCI
- 3.61
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Scientific Reports (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Computer Science › Artificial Intelligence › Privacy-Preserving Technologies in Data
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Keywords
- large language model training, reward models, human feedback, sentiment analysis, LLM security
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: A framework for mitigating malicious RLHF feedback in LLM training using consensus based reward. https://app.cochat.ai/papers/10.1038/s41598-025-92889-7
- The paper
- Haider, Z., Rahman, M. H., Devabhaktuni, V., Moeykens, S., & Chakraborty, P. (2025). A framework for mitigating malicious RLHF feedback in LLM training using consensus based reward. Scientific Reports. https://doi.org/10.1038/s41598-025-92889-7
