PreprintCited by 148Single-cell and spatial transcriptomicsGene Regulatory Network AnalysisGenomics and Chromatin Dynamics

The DOI matches its Crossref record; 75 of the 75 references it cites were found in a registry or an index.

GeneCompass: Deciphering Universal Gene Regulatory Mechanisms with Knowledge-Informed Cross-Species Foundation Model

Open access
Yang, Xiaodong, Liu, Guole, Feng, Guihai, Bu, Dechao, Wang, Pengfei, Jiang, Jie, Chen, Shubai, Yang, Qinmeng, Zhang, Yiyang, Man, Zhenpeng, Liang, Zhongming, Wang, Zichen, Li, Yaning, Li, Zheng, Liu, Yana, Tian, Yao, Li, Ao, Dong, Jingxi, Hu, Zhilong, Fang, Chen, Miao, Hefan, Cui, Lina, Deng, Zixu, Jiang, Haiping, Cui, Wentao, Zhang, Jiahao, Yang, Zhaohui, Li, Handong, He, Xingjian, Zhong, Liqun, Zhou, Jiaheng, Wang, Zijian, Long, Qingqing, Xu, Ping, The X-Compass Consortium, Wang, Hongmei, Meng, Zhen, Wang, Xuezhi, Wang, Yangang, Wang, Yong, Zhang, Shihua, Guo, Jingtao, Zhao, Yi, Zhou, Yuanchun, Li, Fei, Liu, Jing, Chen, Yiqiang, Yang, Ge, Li, Xin·2023·Cell Research

Preprint — published as 10.1038/s41422-024-01034-y · Paper page

Abstract

Deciphering the universal gene regulatory mechanisms in diverse organisms holds great potential to advance our knowledge of fundamental life process and facilitate research on clinical applications. However, the traditional research paradigm primarily focuses on individual model organisms, resulting in limited collection and integration of complex features on various cell types across species. Recent breakthroughs in single-cell sequencing and advancements in deep learning techniques present an unprecedented opportunity to tackle this challenge. In this study, we developed GeneCompass, the first knowledge-informed, cross-species foundation model pre-trained on an extensive dataset of over 120 million single-cell transcriptomes from human and mouse. During pre-training, GeneCompass effectively integrates four types of biological prior knowledge to enhance the understanding of gene regulatory mechanisms in a self-supervised manner. Fine-tuning towards multiple downstream tasks, GeneCompass outperforms competing state-of-the-art models in multiple tasks on single species and unlocks new realms of cross-species biological investigation. Overall, GeneCompass marks a milestone in advancing knowledge of universal gene regulatory mechanisms and accelerating the discovery of key cell fate regulators and candidate targets for drug development.

Overview

The claims and statistics of this paper haven’t been checked yet.

Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.

A few free checks a day · papers already verified open instantly · results are public

Integrity signals

Registry

Crossref · 10.1101/2023.09.26.559542

Cites

75 of 75 references verified0 citation errors · 0 not checkable

Statistics

Figures

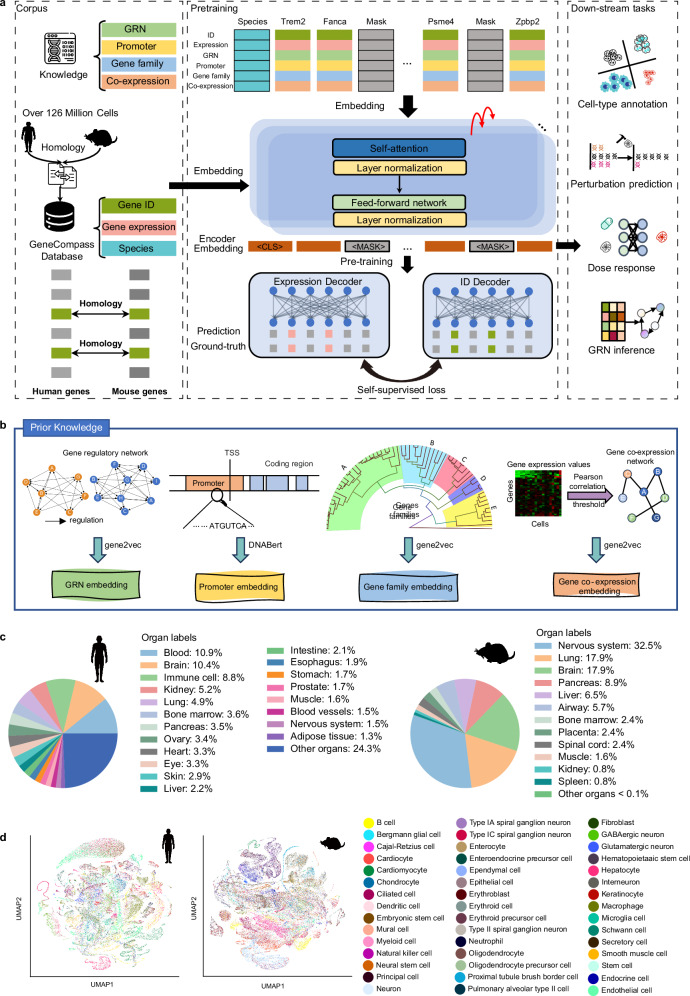
Fig. 1 GeneCompass architecture and pre-training corpus. a The framework of GeneCompass. The model was pre-trained on large-scale single-cell transcriptomes of humans and mice and used for multiple downstream tasks, including cell-type annotation, perturbation prediction, dosage response prediction, GRN inference, and etc. b Embedding of four types of prior knowledge, including GRN, promoter sequence, gene family and co-expression. c Organ types of humans and mice in scCompass-126M. d Uniform Manifold Approximation and Projection of different cell types of a sampled subset from scCompass-126M.
Fig. 1 GeneCompass architecture and pre-training corpus. a The framework of GeneCompass. The model was pre-trained on large-scale single-cell transcriptomes of humans and mice and used for multiple downstream tasks, including cell-type annotation, perturbation prediction, dosage response prediction, GRN inference, and etc. b Embedding of four types of prior knowledge, including GRN, promoter sequence, gene family and co-expression. c Organ types of humans and mice in scCompass-126M. d Uniform Manifold Approximation and Projection of different cell types of a sampled subset from scCompass-126M.CC BY · PubMed Central
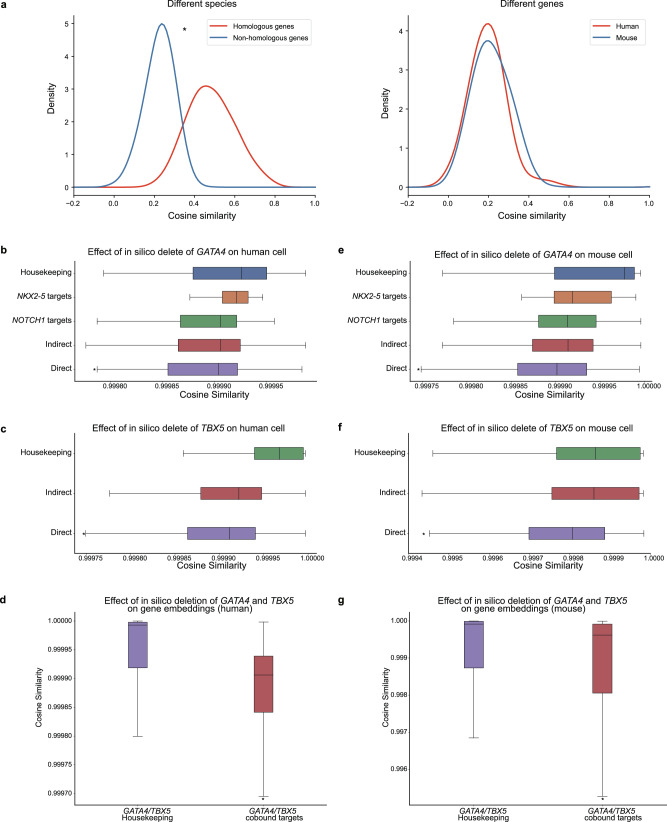
Fig. 2 Analysis of gene embedding generated from GeneCompass. a Cosine similarity between homologous genes as well as non-homologous ones of different species (left panel), and that between different genes in the same mouse or human cell (right panel). b, c Effects of in silico deletion of GATA4 and TBX5 on different gene types, including their direct targets, indirect targets, NOTCH1 targets, NKX2-5 targets and housekeeping genes in human cardiomyocytes, respectively. d Effects of the individual and combined deletion of GATA4 and TBX5 as well as their combinatorial deletion with other genes that are not known to co-bind housekeeping genes and target genes in humans. e, f Effects of in silico deletion of GATA4 and TBX5 on different gene types, including their direct targets, indirect targets, NOTCH1 targets, NKX2-5 targets and housekeeping genes in mice which are obtained by homologous mapping. g Effects of the combined deletion of GATA4 and TBX5 on housekeeping genes and co-bound target genes in mice. (*P < 0.05, wilcoxon-test, NS no significance).
Fig. 2 Analysis of gene embedding generated from GeneCompass. a Cosine similarity between homologous genes as well as non-homologous ones of different species (left panel), and that between different genes in the same mouse or human cell (right panel). b, c Effects of in silico deletion of GATA4 and TBX5 on different gene types, including their direct targets, indirect targets, NOTCH1 targets, NKX2-5 targets and housekeeping genes in human cardiomyocytes, respectively. d Effects of the individual and combined deletion of GATA4 and TBX5 as well as their combinatorial deletion with other genes that are not known to co-bind housekeeping genes and target genes in humans. e, f Effects of in silico deletion of GATA4 and TBX5 on different gene types, including their direct targets, indirect targets, NOTCH1 targets, NKX2-5 targets and housekeeping genes in mice which are obtained by homologous mapping. g Effects of the combined deletion of GATA4 and TBX5 on housekeeping genes and co-bound target genes in mice. (*P < 0.05, wilcoxon-test, NS no significance).CC BY · PubMed Central
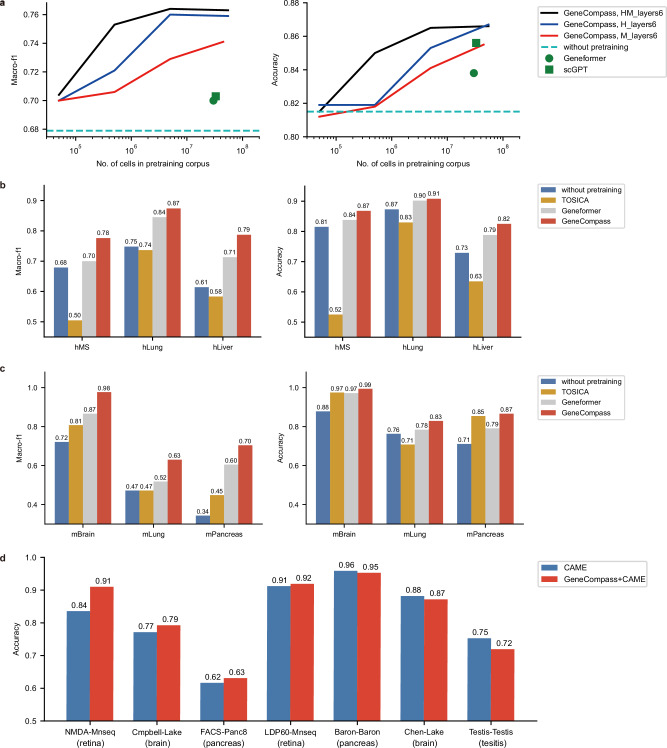
Fig. 3 GeneCompass boosts the performance of cell-type annotations from single species to cross species. a Comparison of the performance of GeneCompass and other baseline methods on the downstream task of cell type annotation in the human multiple sclerosis (hMS) dataset. GeneCompass was pre-trained using human & mouse (HM, black line), human (H, blue line), and mouse (M, red line) single-cell transcriptome corpus with different cell numbers. The green circle point and green square point represent Geneformer and scGPT, respectively. “Layers6” denotes GeneCompass with a 6-layer transformer. b Comparison of the performance of GeneCompass and other baseline methods on hMS, hLung, and hLiver datasets. c Comparison of the performance of GeneCompass and other baseline methods on mBrain, mLung, and mPancreas datasets. d Comparison of the performance of GeneCompass+CAME with original CAME on cross-species cell type annotation (Mouse and human data were used as reference and target species, respectively). A 7.5% improvement was observed in NMDA-Mnseq, a retina dataset (the first column). The datasets in b–d derived from humans and mice are marked as “h” and “m”, respectively. Detailed information on datasets can be found in the Supplementary Methods. “Without pre-training” denotes that the parameters of GeneCompass were randomly initialized and fine-tuned directly without the pre-training process.
Fig. 3 GeneCompass boosts the performance of cell-type annotations from single species to cross species. a Comparison of the performance of GeneCompass and other baseline methods on the downstream task of cell type annotation in the human multiple sclerosis (hMS) dataset. GeneCompass was pre-trained using human & mouse (HM, black line), human (H, blue line), and mouse (M, red line) single-cell transcriptome corpus with different cell numbers. The green circle point and green square point represent Geneformer and scGPT, respectively. “Layers6” denotes GeneCompass with a 6-layer transformer. b Comparison of the performance of GeneCompass and other baseline methods on hMS, hLung, and hLiver datasets. c Comparison of the performance of GeneCompass and other baseline methods on mBrain, mLung, and mPancreas datasets. d Comparison of the performance of GeneCompass+CAME with original CAME on cross-species cell type annotation (Mouse and human data were used as reference and target species, respectively). A 7.5% improvement was observed in NMDA-Mnseq, a retina dataset (the first column). The datasets in b–d derived from humans and mice are marked as “h” and “m”, respectively. Detailed information on datasets can be found in the Supplementary Methods. “Without pre-training” denotes that the parameters of GeneCompass were randomly initialized and fine-tuned directly without the pre-training process.CC BY · PubMed Central
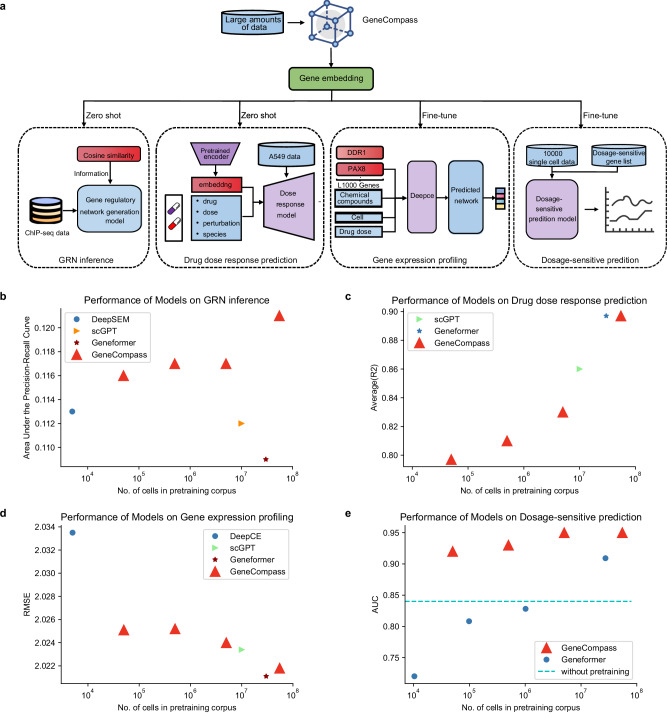
Fig. 4 GeneCompass demonstrates enhanced performance for GRN inference, drug dose response prediction, gene expression profile prediction, and gene dosage sensitivity prediction tasks. a The workflow of integrating gene embeddings generated from GeneCompass to four downstream tasks: GRN inference, drug dose response prediction, gene expression profiling and gene dosage sensitivity prediction. b Performance comparison of each model on the GRN inference task in terms of AUPRC. The red line denotes the results of GeneCompass trained by different amounts of data. The blue, orange and brown dots represent results of DeepSEM, scGPT and Geneformer, respectively. c Performance comparison, in terms of R-squared value, for each model is conducted on the drug dose response prediction task. The red line denotes the results of GeneCompass trained by different amounts of data. The green and blue dots represent results of scGPT and Geneformer, respectively. d Performance comparison of each model on the gene expression profile prediction task. Root Mean Squared Error is applied as the metric. The red line denotes the results of GeneCompass trained by different amounts of data. The blue, green and brown dots represent results of DeepCE, scGPT and Geneformer, respectively. e Performance comparison of each model on the dosage sensitivity prediction task. We use AUC as the metric. The red and blue lines denote the results of GeneCompass and Geneformer, respectively, trained by different amounts of data. The dashed line represents the result of GeneCompass without pretraining.
Fig. 4 GeneCompass demonstrates enhanced performance for GRN inference, drug dose response prediction, gene expression profile prediction, and gene dosage sensitivity prediction tasks. a The workflow of integrating gene embeddings generated from GeneCompass to four downstream tasks: GRN inference, drug dose response prediction, gene expression profiling and gene dosage sensitivity prediction. b Performance comparison of each model on the GRN inference task in terms of AUPRC. The red line denotes the results of GeneCompass trained by different amounts of data. The blue, orange and brown dots represent results of DeepSEM, scGPT and Geneformer, respectively. c Performance comparison, in terms of R-squared value, for each model is conducted on the drug dose response prediction task. The red line denotes the results of GeneCompass trained by different amounts of data. The green and blue dots represent results of scGPT and Geneformer, respectively. d Performance comparison of each model on the gene expression profile prediction task. Root Mean Squared Error is applied as the metric. The red line denotes the results of GeneCompass trained by different amounts of data. The blue, green and brown dots represent results of DeepCE, scGPT and Geneformer, respectively. e Performance comparison of each model on the dosage sensitivity prediction task. We use AUC as the metric. The red and blue lines denote the results of GeneCompass and Geneformer, respectively, trained by different amounts of data. The dashed line represents the result of GeneCompass without pretraining.CC BY · PubMed Central
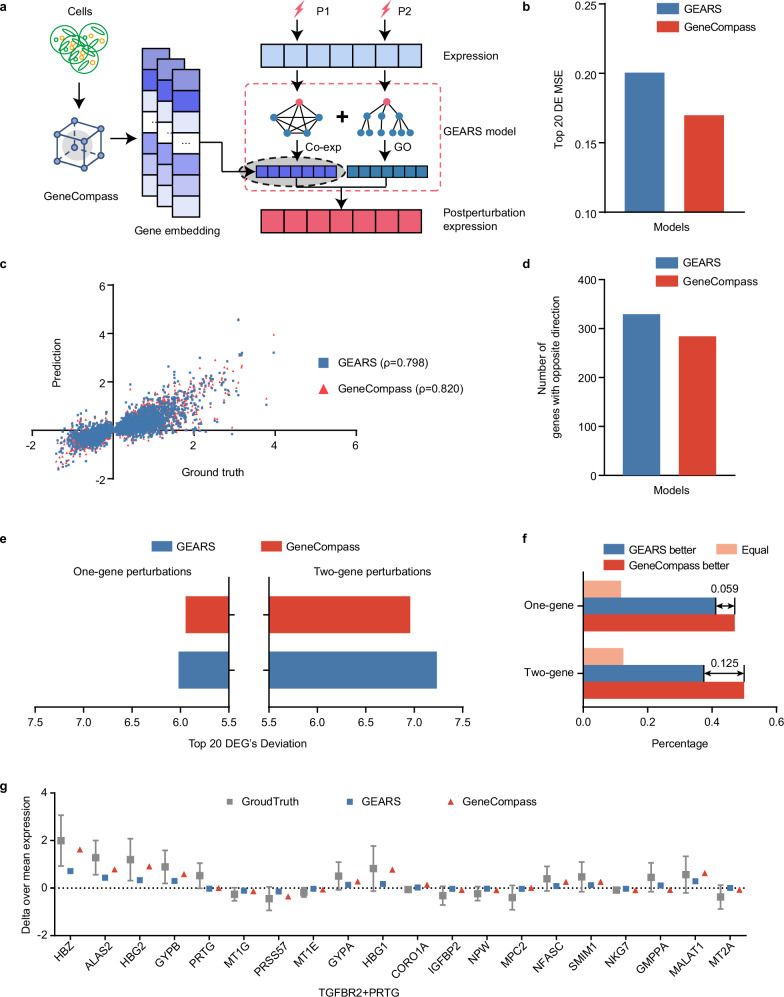
Fig. 5 GeneCompass shows enhanced performance for the gene perturbation prediction task. a The workflow of GeneCompass for the perturbation prediction task. b MSE in predicting the expression changes in the top 20 DEGs by GeneCompass and GEARS. MSE only considered on the top 20 most DEGs. c Scatter plot of the predicted and true changes in gene expression. Each dot represents a specific gene, and Spearman’s correlation is marked as “ρ”. d Total number of the top 20 DEGs genes where the predicted post-perturbation differential expression was in the incorrect direction of the ground truth. e Expression deviation between the predicted and true changes in gene expression for the top 20 DEGs analyzed by GeneCompass and GEARS. f Percentage of perturbations that exhibited a smaller deviation between the prediction results and ground truth when comparing GeneCompass with GEARs, using the deviation in the top 20 DEGs as the criterion. “GeneCompass better” is defined as GeneCompass having a smaller deviation than GEARS. g Expression changes for the combined TGFBR2 and PRTG perturbation in true experiment post perturbation were predicted by GeneCompass and GEARS. The grey error bar denotes the ground truth of mean gene expression change with standard deviation after perturbing the gene combination TGFBR2 and PRTG (n = 205). The red triangle symbol shows the gene expression change predicted by GeneCompass with TGFBR2 and PRTG perturbation excluded during training. The blue square symbol shows the gene expression change predicted by GEARS.
Fig. 5 GeneCompass shows enhanced performance for the gene perturbation prediction task. a The workflow of GeneCompass for the perturbation prediction task. b MSE in predicting the expression changes in the top 20 DEGs by GeneCompass and GEARS. MSE only considered on the top 20 most DEGs. c Scatter plot of the predicted and true changes in gene expression. Each dot represents a specific gene, and Spearman’s correlation is marked as “ρ”. d Total number of the top 20 DEGs genes where the predicted post-perturbation differential expression was in the incorrect direction of the ground truth. e Expression deviation between the predicted and true changes in gene expression for the top 20 DEGs analyzed by GeneCompass and GEARS. f Percentage of perturbations that exhibited a smaller deviation between the prediction results and ground truth when comparing GeneCompass with GEARs, using the deviation in the top 20 DEGs as the criterion. “GeneCompass better” is defined as GeneCompass having a smaller deviation than GEARS. g Expression changes for the combined TGFBR2 and PRTG perturbation in true experiment post perturbation were predicted by GeneCompass and GEARS. The grey error bar denotes the ground truth of mean gene expression change with standard deviation after perturbing the gene combination TGFBR2 and PRTG (n = 205). The red triangle symbol shows the gene expression change predicted by GeneCompass with TGFBR2 and PRTG perturbation excluded during training. The blue square symbol shows the gene expression change predicted by GEARS.CC BY · PubMed Central
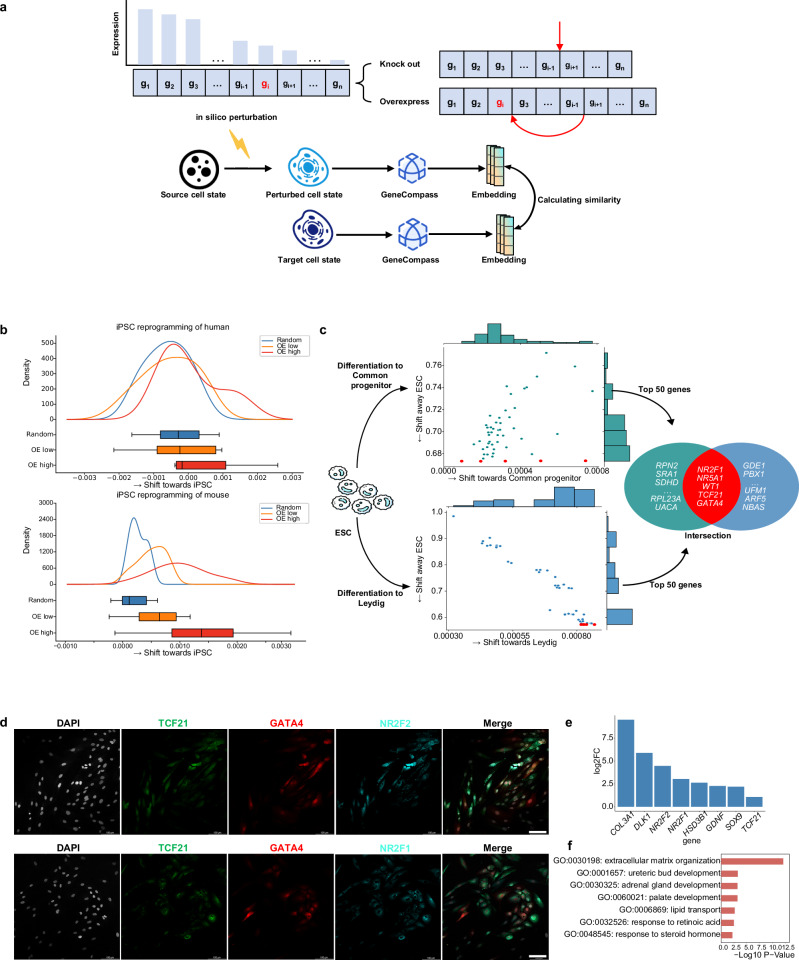
Fig. 6 In silico quantitative perturbation for cell reprogramming and differentiation. a Diagram of in silico cell fate transition. In silico knockout or overexpression experiment is performed by removing or shifting the highlighted gene in red forward within the ranking genes. b In silico low-level or high-level overexpression of OSKM is performed in human (upper) or mouse (bottom) fibroblasts to calculate the cosine similarity of the simulated cell states with iPSCs. In silico overexpression of four other random genes is used as control. In each simulation group, all embedding pairs between perturbed fibroblast cells and iPSCs are used to compute the cosine similarity. The cosine similarity of all pairs in each group is simultaneously presented using probability density and box plots. c Distribution of candidate genes that drive the shift of cell embeddings towards Leydig cell status and gonadal progenitor status in response to in silico overexpression in human ESC cells. Top 50 genes shifting towards Leydig cell (lower) or gonadal progenitor (upper) status and away from the ESC status are presented. Five genes in the intersection set of Venn diagram are selected as candidate genes for gonadal differentiation. d Protein co-immunofluorescence staining for markers of interstitial/Leydig lineage and Sertoli cells with GATA4 (GATA4+, red; TCF21+, green; NR2F2/NR2F1+, cyan),). Scale bars: 100μm e The identification of upregulated gonadal lineage-related marker genes in the GATA4 overexpression group compared to cells derived from wild-type ESCs, with fold changes exceeding 2-fold. f Gene ontology (GO) enrichment analysis was performed using DAVID for the total up-regulated genes with a 2-fold change in the GATA4 overexpression group compared to cells derived from wild-type ESCs. (*P < 0.05, Wilcoxon-test).
Fig. 6 In silico quantitative perturbation for cell reprogramming and differentiation. a Diagram of in silico cell fate transition. In silico knockout or overexpression experiment is performed by removing or shifting the highlighted gene in red forward within the ranking genes. b In silico low-level or high-level overexpression of OSKM is performed in human (upper) or mouse (bottom) fibroblasts to calculate the cosine similarity of the simulated cell states with iPSCs. In silico overexpression of four other random genes is used as control. In each simulation group, all embedding pairs between perturbed fibroblast cells and iPSCs are used to compute the cosine similarity. The cosine similarity of all pairs in each group is simultaneously presented using probability density and box plots. c Distribution of candidate genes that drive the shift of cell embeddings towards Leydig cell status and gonadal progenitor status in response to in silico overexpression in human ESC cells. Top 50 genes shifting towards Leydig cell (lower) or gonadal progenitor (upper) status and away from the ESC status are presented. Five genes in the intersection set of Venn diagram are selected as candidate genes for gonadal differentiation. d Protein co-immunofluorescence staining for markers of interstitial/Leydig lineage and Sertoli cells with GATA4 (GATA4+, red; TCF21+, green; NR2F2/NR2F1+, cyan),). Scale bars: 100μm e The identification of upregulated gonadal lineage-related marker genes in the GATA4 overexpression group compared to cells derived from wild-type ESCs, with fold changes exceeding 2-fold. f Gene ontology (GO) enrichment analysis was performed using DAVID for the total up-regulated genes with a 2-fold change in the GATA4 overexpression group compared to cells derived from wild-type ESCs. (*P < 0.05, Wilcoxon-test).CC BY · PubMed Central

Verification

Claims the paper makes

The claims and statistics of this paper haven’t been checked yet.

Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.

A few free checks a day · papers already verified open instantly · results are public

Claims other papers make about this one

Each is checked against this paper’s own text: does it say what the citing paper says it does?

Self-check

Percentages, sums and reported differences re-computed from the paper’s own numbers.

The self-check needs the paper’s full text.

Citations

Cites

Show all 75 references

Research works printed but not linked: 2

  1. 10.1126/SCIENCE.ABL4896/SUPPL_FILE/SCIENCE.ABL4896_MDAR_REPRODUCIBILITY_CHECKLIST.PDF · DOI
  2. Paszke, A. , et al. PyTorch: An Imperative Style, High-Performance Deep Learning Library. in Neural Information Processing Systems. (2019).

Cited by

Sorted by citations

See all 148

Metadata

Authors
Yang, X., Liu, G., Feng, G., Bu, D., Wang, P., Jiang, J., Chen, S., Yang, Q., Zhang, Y., Man, Z., Liang, Z., Wang, Z., Li, Y., Li, Z., Liu, Y., Tian, Y., Li, A., Dong, J., Hu, Z., Fang, C., Miao, H., Cui, L., Deng, Z., Jiang, H., Cui, W., Zhang, J., Yang, Z., Li, H., He, X., Zhong, L., Zhou, J., Wang, Z., Long, Q., Xu, P., The X-Compass Consortium, Wang, H., Meng, Z., Wang, X., Wang, Y., Wang, Y., Zhang, S., Guo, J., Zhao, Y., Zhou, Y., Li, F., Liu, J., Chen, Y., Yang, G., & Li, X.
Affiliations
Chinese Academy of Sciences (CN)
Corresponding author
Zhao, Yi
Venue
Cell Research
Publisher
openRxiv
Published
2023-09-28
Volume
34
Issue
12
Pages
830-845
ISSN
1001-0602 (ISSN-L)
OpenAlex
W4403174218
Cited by
148
References
75
Citations by year
2026: 63 · 2025: 63 · 2024: 20 · 2023: 1
FWCI
19.82
Type
journal article
Language
en
Open access
Licence
cc-by
Locations
  • Cell Research (publishedVersion, cc-by)
  • bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion)
  • PubMed Central (publishedVersion, cc-by)
  • PubMed (publishedVersion)
Funders
  • National Natural Science Foundation of China (62202455, No.91954201, No.32341013, 31971289, 91954201, No.62202455, No.31971289, 32341019, 32341013)
  • Chinese Academy of Sciences (YSBR‐076, CAS-WX2021SF-0101, YSBR-034)
  • Institute of Zoology, Chinese Academy of Sciences
Topics
  • Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Single-cell and spatial transcriptomics
  • Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Gene Regulatory Network Analysis
  • Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Chromatin Dynamics
Keywords
gene regulatory mechanisms, single-cell transcriptomics, self-supervised learning, cell fate transitions, gonadal differentiation, human embryonic stem cells, drug target identification
MeSH terms
Animals, Cell Differentiation, Gene Expression Regulation, Humans, Species Specificity, Mice, Gene Regulatory Networks, Single-Cell Analysis, Transcriptome

About these checks

Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.

Statistics and arithmetic are recomputed, not judged.

Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.

What counts as a claim ›How we measure confidence ›How we check this ›

Are you an author, or do you see a problem with this page? Request a review