

The DOI matches its Crossref record; 49 of the 50 references it cites were found in a registry or an index, and 1 are not checked yet; none of the 4 sources its claims cite is checked for support yet.
Benchmarking large language models for handwritten text recognition
Open accessAbstract
Purpose: The aim of this work is to provide an overview of the current capabilities of Multimodal Large Language Models (MLLMs) for Handwritten Text Recognition (HTR), assessing their potential when compared to traditional task-specific, supervised models. Design/methodology/approach: The approach is that of using a set of openly-available benchmarks to compare different LLMs with strong task-specific supervised baselines for the task of HTR. Findings: The results show that LLMs currently show a strong performance on English texts, yet they demonstrate a weaker performance on languages other than English, and do not possess a significant capability for self-correction. Moreover, their comparison with Transkribus’s models highlight the fact that proprietary LLM models are the best performing, in particular on modern handwriting, while for historical documents the overall performance comparison between LLMs and Transkribus is not consistent. Originality/value: The authors are not aware of a similar study relying on open benchmarks.
Checked 2026-11-13 · 1 reference not checked yet
Overview
CoChat Summary
TL;DR
This paper benchmarks eight multimodal LLMs against Transkribus models for handwritten text recognition using open datasets and zero-shot plus self-correction prompts. It finds LLMs are strong on English and modern handwriting, weaker on non-English and historical documents, and do not reliably self-correct.
Key findings
- LLMs perform well on English and modern handwriting: on IAM, GPT-4o-mini reaches 1.71% CER and 3.34% WER; on RIMES, GPT-4o reaches 1.69% CER (Table 5).
- Performance declines for non-English and historical material: for Italian, Claude Sonnet 3.5 is best but still poor, with 20.55% CER / 27.78% WER on LAM and 26.43% CER / 35.08% WER on Leopardi; for German/multilingual, The Text Titan achieves 40.63% CER / 64.28% WER on READ2016 and 14.40% CER / 29.40% WER on ICDAR2017.
- Self-correction is inconsistent: the best improvement was GPT-4o on ICDAR2017 with an 8% CER and 4.7% WER decrease, but results remained unusable; open-source models failed to improve and often increased error rates.
- A masked-word pre-training check found minimal correct guesses: Claude Sonnet 3.5 guessed 27/300, GPT-4o 17/300, and open-source models 0–2/300.
Methods
- Benchmarked eight MLLMs—three proprietary (GPT-4o, GPT-4o-mini, Claude 3.5 Sonnet) and five open-source (MiniCPM-V-2 6, Qwen2-VL-7B, Pixtral-12B, InternVL2-8B, Phi-3-mini-instruct-128k)—against Transkribus models (The Text Titan I, Italian Handwriting M1) on seven open datasets: IAM, RIMES, LAM, Leopardi, Bentham, READ2016, and ICDAR2017.
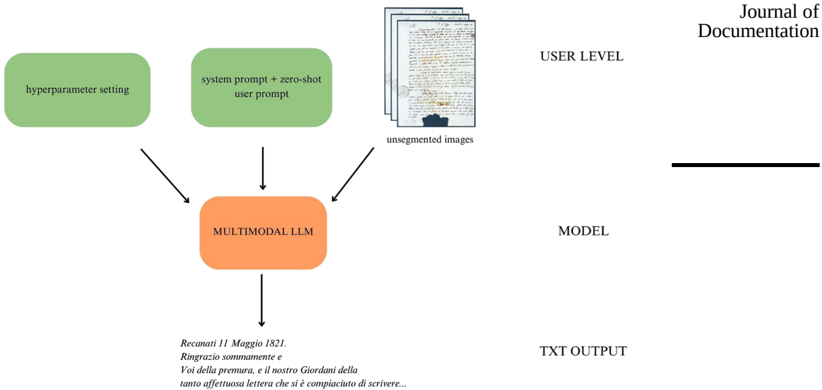
- Used zero-shot prompting with the same prompts and hyperparameters across models (temperature 0/greedy decoding; repetition penalty 1.2), then a three-step self-correction procedure; evaluated with CER, WER, and WER-BoW.
- Ran a name-cloze masked-word test on 100 pages / 300 masked words to assess whether HTR benchmark datasets may have been in LLM pre-training.
Limitations
- Paper-stated: dataset choice was limited to available HTR datasets in a few languages and does not fully capture multilingual contexts; the baseline prompt lacked contextual elements that could improve results; open-source models were limited to up to 12B parameters due to computational constraints.
- Evident from the text: the study is a snapshot of models available as of October 2024, uses only zero-shot and intrinsic self-correction without fine-tuning, and does not cover ideographic or non-Latin scripts.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 0 Not valid · 4 Not checked · 45 Own results and interpretations
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In particular, it can be observed that post-corrections produced by open-source models reduced accuracy overall.”
§ Benchmarking large language models for handwritten text recognition > 5. Conclusion and future developments
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Moreover, their comparison with Transkribus's models highlight the fact that proprietary LLM models are the best performing, in particular on modern handwriting, while for historical documents the overall performance comparison between LLMs and Transkribus is not consistent.”
- Also stated in: § 4. Analysis of results and discussion · hedged
“However, it cannot be broadly stated that Transkribus models consistently outperform LLMs, as accuracy varies depending on the specific use case.”
§ Benchmarking large language models for handwritten text recognition > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 4. Analysis of results and discussion · hedged
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While The Text Titan achieves the best outcome with 7.07% CER and 12.41% WER, LLMs are not far behind.”
§ Benchmarking large language models for handwritten text recognition > 4. Analysis of results and discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“open-source model performance decreases significantly for historical documents in other languages.”
§ Benchmarking large language models for handwritten text recognition > 5. Conclusion and future developments
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While the accuracy is similar between proprietary and open-source models on modern handwriting and English materials”
§ Benchmarking large language models for handwritten text recognition > 5. Conclusion and future developments
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
21 more claims
Create a free account to see all 49 claims and to verify the 1 reference still open.
- It may state two separate claims as one. 17
- The quote only partly states this claim. 1
- Probably not a substantial claim. 6
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Benchmarking large language models for handwritten text recognition > 4. Analysis of results and discussion
“On IAM, GPT-4o-mini attains 1.71% CER and 3.34% WER, while on RIMES, GPT-4o reaches 1.69% CER and 3.66% WER, outperforming Transkribus' supermodel.”
§ Benchmarking large language models for handwritten text recognition > 5. Conclusion and future developments
“| Gpt-4o-2024-08-06 | 1.69% | 3.76% | 3.30% |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Benchmarking large language models for handwritten text recognition > 4. Analysis of results and discussion
“In German and multilingual datasets, The Text Titan surpasses LLMs, achieving 40.63%CER and 64.28% WER on the READ2016 dataset and 14.40% CER and 29.40% WER on ICDAR2017.”
§ Benchmarking large language models for handwritten text recognition > 5. Conclusion and future developments
“| The Text Titan I | 14.40% | 29.47% | 24.69% |”
Citations
Cites
Binary Codes capable of currecting deletions, insertions, and reversals
Levenshtein, V. I. (1965) · Soviet physics. Doklady · Cited by 10,358
The IAM-database: an English sentence database for offline handwriting recognition
Marti, U.-V., & Bunke, H. (2002) · International Journal on Document Analysis and Recognition · doi:10.1007/s100320200071 · Cited by 1,589
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Dao, T., Fu, D. Y., Ermon, S., Rudra, A., & Ré, C. (2022) · arXiv · doi:10.48550/arxiv.2205.14135 · Cited by 1,214
TrOCR: Transformer-Based Optical Character Recognition with Pre-trained Models
Li, M., Lv, T., Chen, J., Cui, L., Lu, Y., Florencio, D. A. F., Zhang, C., Li, Z., & Wei, F. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i11.26538 · Cited by 923
CTRL: A Conditional Transformer Language Model for Controllable Generation
Keskar, N. S., McCann, B., Varshney, L. R., Xiong, C., & Socher, R. (2019) · arXiv · doi:10.48550/arxiv.1909.05858 · Cited by 751
Large Language Models Cannot Self-Correct Reasoning Yet
Huang, J., Chen, X., Mishra, S., Zheng, H. S., Yu, A. W., Song, X., & Zhou, D. (2023) · arXiv · doi:10.48550/arxiv.2310.01798 · Cited by 712
Are Multidimensional Recurrent Layers Really Necessary for Handwritten Text Recognition?
Puigcerver, J. (2017) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2017.20 · Cited by 365
A full English sentence database for off-line handwriting recognition
Marti, U.-V., & Horst Bunke, A. (1999) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.1999.791885 · Cited by 250
Handwriting Recognition with Large Multidimensional Long Short-Term Memory Recurrent Neural Networks
Voigtlaender, P., Doetsch, P., & Ney, H. (2016) · International Conference on Frontiers in Handwriting Recognition · doi:10.1109/icfhr.2016.0052 · Cited by 229
Scan, Attend and Read: End-to-End Handwritten Paragraph Recognition with MDLSTM Attention
Bluche, T., Louradour, J., & Messina, R. (2017) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2017.174 · Cited by 205
Pay attention to what you read: Non-recurrent handwritten text-Line recognition
Kang, L., Riba, P., Rusiñol, M., Fornés, A., & Villegas, M. (2022) · Pattern Recognition · doi:10.1016/j.patcog.2022.108766 · Cited by 196
Pay Attention to What You Read: Non-recurrent Handwritten Text-Line Recognition
Kang, L., Riba, P., Rusiñol, M., Fornés, A., & Villegas, M. (2020) · Pattern Recognition · doi:10.48550/arxiv.2005.13044 · Cited by 187
Speak, Memory: An Archaeology of Books Known to ChatGPT/GPT-4
Chang, K. K., Cramer, M. H., Soni, S., & Bamman, D. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.453 · Cited by 176
End-to-End Handwritten Paragraph Text Recognition Using a Vertical Attention Network
Coquenet, D., Chatelain, C., & Paquet, T. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2022.3144899 · Cited by 169
Archives and AI: An Overview of Current Debates and Future Perspectives
Colavizza, G., Blanke, T., Jeurgens, C., & Noordegraaf, J. (2022) · Journal on Computing and Cultural Heritage · doi:10.1145/3479010 · Cited by 162
Self-citationDAN: A Segmentation-Free Document Attention Network for Handwritten Document Recognition
Coquenet, D., Chatelain, C., & Paquet, T. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3235826 · Cited by 148
Start, Follow, Read: End-to-End Full-Page Handwriting Recognition
Wigington, C., Tensmeyer, C., Davis, B., Barrett, W. A., Price, B. L., & Cohen, S. D. (2018) · Lecture notes in computer science · doi:10.1007/978-3-030-01231-1_23 · Cited by 122
HTR-VT: Handwritten text recognition with vision transformer
Li, Y., Chen, D., Tang, T., & Shen, X. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110967 · Cited by 121
ICFHR2016 Competition on Handwritten Text Recognition on the READ Dataset
Sánchez, J. A., Romero, V., Toselli, A. H., & Vidal, E. (2016) · International Conference on Frontiers in Handwriting Recognition · doi:10.1109/icfhr.2016.0120 · Cited by 109
Muehlberger, G., Seaward, L., Terras, M., Ares Oliveira, S., Bosch, V., Bryan, M., Colutto, S., Déjean, H., Diem, M., Fiel, S., et al. (2019) · Journal of Documentation · doi:10.1108/jd-07-2018-0114 · Cited by 108
A survey of OCR evaluation tools and metrics
Neudecker, C., Baierer, K., Gerber, M., Clausner, C., Antonacopoulos, A., & Pletschacher, S. (2021) · doi:10.1145/3476887.3476888 · Cited by 104
Yousef, M., & Bishop, T. E. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.01472 · Cited by 97
Advancements and Challenges in Handwritten Text Recognition: A Comprehensive Survey
AlKendi, W., Gechter, F., Heyberger, L., & Guyeux, C. (2024) · Journal of Imaging · doi:10.3390/jimaging10010018 · Cited by 96
Full Page Handwriting Recognition via Image to Sequence Extraction
Singh, S. S., & Karayev, S. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-86334-0_4 · Cited by 81
Unlocking the archives: Using large language models to transcribe handwritten historical documents
Humphries, M., Leddy, L. C., Downton, Q., Legace, M., McConnell, J., Murray, I., & Spence, E. (2025) · Historical Methods: A Journal of Quantitative and Interdisciplinary History · doi:10.1080/01615440.2025.2500309 · Cited by 72
Full-Page Text Recognition: Learning Where to Start and When to Stop
Moysset, B., Kermorvant, C., & Wolf, C. (2017) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2017.147 · Cited by 68
Transformer for Handwritten Text Recognition Using Bidirectional Post-decoding
Wick, C., Zöllner, J., & Grüning, T. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-86334-0_8 · Cited by 67
ICDAR2017 Competition on Handwritten Text Recognition on the READ Dataset
Sánchez, J. A., Romero, V., Toselli, A. H., Villegas, M., & Vidal, E. (2017) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2017.226 · Cited by 64
Handwriting Recognition of Historical Documents with Few Labeled Data
Chammas, E., Mokbel, C., & Likforman-Sulem, L. (2018) · IAPR International Workshop on Document Analysis Systems (DAS) · doi:10.1109/das.2018.15 · Cited by 51
Multimodal LLMs for OCR, OCR Post-Correction, and Named Entity Recognition in Historical Documents
Greif, G., Griesshaber, N., & Greif, R. (2025) · arXiv · doi:10.48550/arxiv.2504.00414 · Cited by 49
Hodel, T., Schoch, D., Schneider, C., & Purcell, J. (2021) · Journal of Open Humanities Data · doi:10.5334/johd.46 · Cited by 47
The implications of handwritten text recognition for accessing the past at scale
Nockels, J., Gooding, P., & Terras, M. (2024) · Journal of Documentation · doi:10.1108/jd-09-2023-0183 · Cited by 42
Language Model Integration for the Recognition of Handwritten Medieval Documents
Wüthrich, M., Liwicki, M., Fischer, A., Indermühle, E., Horst Bunke, A., Viehhauser, G., & Stolz, M. (2009) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2009.17 · Cited by 35
Transformer-based HTR for Historical Documents
Ströbel, P., Clematide, S., Volk, M., & Hodel, T. (2022) · Zurich Open Repository and Archive (University of Zurich) · doi:10.48550/arxiv.2203.11008 · Cited by 33
A Prompt Pattern Catalog to Enhance Prompt Engineering with ChatGPT
(2024) · Proceedings of the 30th Conference on Pattern Languages of Programs · doi:10.64346/plop2023p05 · Cited by 32
Europeana Newspapers OCR Workflow Evaluation
Pletschacher, S., Clausner, C., & Antonacopoulos, A. (2015) · International Workshop on Historical Document Imaging and Processing (HIP) · doi:10.1145/2809544.2809554 · Cited by 29
End-to-End Handwritten Text Detection and Transcription in Full Pages
Carbonell, M., Mas, J., Villegas, M., Fornés, A., & Lladós, J. (2019) · International Conference on Document Analysis and Recognition Workshops (ICDARW) · doi:10.1109/icdarw.2019.40077 · Cited by 29
Training Full-Page Handwritten Text Recognition Models without Annotated Line Breaks
Tensmeyer, C., & Wigington, C. (2019) · IAPR International Conference on Document Analysis and Recognition (ICDAR) · doi:10.1109/icdar.2019.00011 · Cited by 29
The LAM Dataset: A Novel Benchmark for Line-Level Handwritten Text Recognition
Cascianelli, S., Pippi, V., Maarand, M., Cornia, M., Baraldi, L., Kermorvant, C., & Cucchiara, R. (2022) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr56361.2022.9956189 · Cited by 27
Liu, J., Ma, X., Wang, L., & Pei, L. (2024) · Journal on Computing and Cultural Heritage · doi:10.1145/3690391 · Cited by 27
Early evidence of how LLMs outperform traditional systems on OCR/HTR tasks for historical recordsPreprint
Kim, S., Baudru, J., Ryckbosch, W., Bersini, H., & Ginis, V. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2501.11623 · Cited by 27
Terras, M. (2022) · Digital humanities research · doi:10.14361/9783839455845-008 · Cited by 25
Handwriting Recognition in Historical Documents with Multimodal LLMPreprint
Li, L. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.24034 · Cited by 23
Learning to Read L’Infinito: Handwritten Text Recognition with Synthetic Training Data
Cascianelli, S., Cornia, M., Baraldi, L., Piazzi, M. L., Schiuma, R., & Cucchiara, R. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-89131-2_31 · Cited by 18
CLOCR-C: Context Leveraging OCR Correction with Pre-trained Language ModelsPreprint
Bourne, J. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.17428 · Cited by 18
Evaluation of HTR models without Ground Truth Material
Ströbel, P., Volk, M., Clematide, S., Schwitter, R., Hodel, T., & Schoch, D. (2022) · Language Resources and Evaluation Conference (LREC) · doi:10.63317/5q7mf345k9h5 · Cited by 14
GPT-4 Doesn't Know It's Wrong: An Analysis of Iterative Prompting for Reasoning Problems
Stechly, K., Marquez, M., & Kambhampati, S. (2023) · arXiv · doi:10.48550/arxiv.2310.12397 · Cited by 11
Terras, M., Anzinger, B., Gooding, P., Mühlberger, G., Prien, M., Nockels, J., Romein, C. A., Stauder, A., & Stauder, F. (2025) · Open Research Europe · doi:10.12688/openreseurope.18747.2 · Cited by 11
Chapter 6: Supervised and Unsupervised: Approaches to Machine Learning for Textual Entities
Hodel, T. (2022) · Digital Humanities Research · doi:10.14361/9783839455845-007 · Cited by 4
Research works printed but not linked: 3
- Augustin, E., Carré, M., Grosicki, E., Brodin, J., Geoffrois, E. and Prêteux, F. (2006), “RIMES evaluation campaign for handwritten mail processing”, available at: https://www.semanticscholar.org/paper/RIMES-evaluation-campaign-for-handwritten-mail-Augustin-Carr%C3%A9/1a08e3055dd76c307f5f2993d54465dd407ad1ab (accessed 14 January 2025).
- Cascianelli, 2021, Computer Analysis of Images and Patterns. CAIP 2021. Lecture Notes in Computer Science, 340
- Ströbel, P.B. (2023), “Flexible techniques for automatic text recognition of historical documents”, PhD dissertation, University of Zurich, available at: https://core.ac.uk/outputs/574072779/?source=2 (accessed 15 January 2025).
Cited by
Belot, M., Tuberosa, J., Preuss, L., Svezhentseva, O., Claessen, M., Bölling, C., Schuster, F., & Léger, T. (2026) · Methods in Ecology and Evolution · doi:10.1111/2041-210x.70235 · Cited by 4
Ardanuy, M. C., Berganzo‐Besga, I., Huesca, R. S., & Cuadrada, C. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-04624-6_20 · Cited by 3
A Multi-Stage Pipeline for Accurate Handwritten Information Extraction from Financial Forms
Wang, G., Yu, J., Zhang, X., Deb, T., Liu, X., & He, P. (2025) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw69036.2025.00634 · Cited by 1
METATR: A Multilingual, Evolving Benchmark for Automatic Text Recognition
Boillet, M., Tarride, S., & Kermorvant, C. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-36039-7_2 · Cited by 1
Semi-automatic pipeline for constructing HTR corpora from Ukrainian-language historical documents
Івасечко, А. В., & Lipianina-Honcharenko, K. (2026) · doi:10.55056/ceur-ws.org/vol-4159/paper12.pdf · Cited by 1
Metadata
- Authors
- Crosilla, G., Klic, L., & Colavizza, G.
- Affiliations
- University of Bologna (IT)
- Digital Humanities Lab, Villa I Tatti , ,
- University of Copenhagen (DK)
- Venue
- Journal of Documentation
- Publisher
- Emerald
- Published
- 2025-08-15
- Volume
- 81
- Issue
- 7
- Pages
- 334-354
- ISSN
- 0022-0418 (ISSN-L)
- 1758-7379
- OpenAlex
- W4414311642
- Cited by
- 34
- References
- 50
- Citations by year
- 2026: 30 · 2025: 4
- FWCI
- 8.09
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Journal of Documentation (publishedVersion, cc-by)
- Research at the University of Copenhagen (University of Copenhagen) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- Archivio istituzionale della ricerca (Alma Mater Studiorum Università di Bologna) (submittedVersion, other-oa)
- arXiv (Cornell University) (cc-by)
- Funders
- Harvard University Center for Italian Renaissance Studies
- Harvard University
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Handwritten Text Recognition Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Vehicle License Plate Recognition
- Keywords
- multimodal large language models, handwriting recognition, benchmarking, Transkribus, self-correction, historical documents, multilingual performance
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-13, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-13 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
