

A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition
Open accessThe DOI matches its Crossref record; 48 of the 62 references it cites were found in a registry or an index; 10 of the 34 sources its claims cite were checked for support.
Abstract
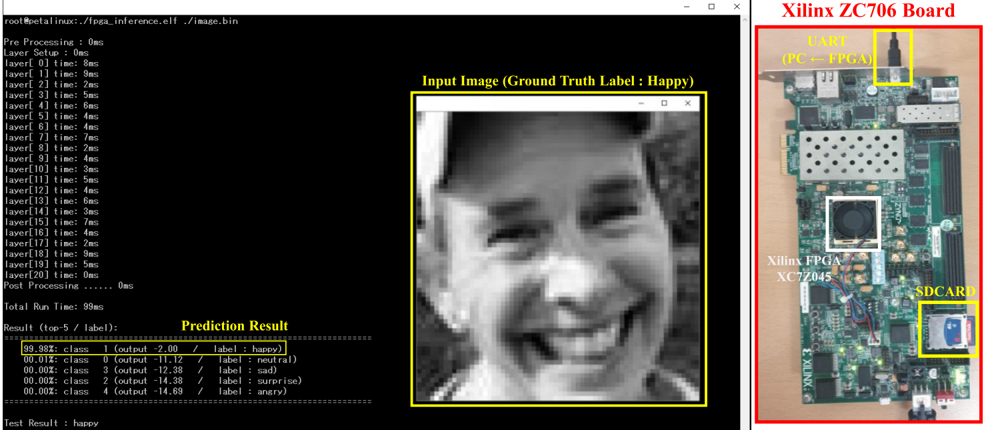
Recently, many researches have been conducted on recognition of facial emotion using convolutional neural networks (CNNs), which show excellent performance in computer vision. To obtain a high classification accuracy, a CNN architecture with many parameters and high computational complexity is required. However, this is not suitable for embedded systems where hardware resources are limited. In this paper, we present a lightweight CNN architecture optimized for embedded systems. The proposed CNN architecture has a small memory footprint and low computational complexity. Furthermore, a novel hardware-friendly quantization method that uses only integer-arithmetic is proposed. The proposed hardware-friendly quantization method maps the scale factors to power-of-two terms and replaces multiplication and division operations using scale factors with shift operations. To improve the generalization and classification performance of the CNN, we create the FERPlus-A dataset. This is a new training dataset created using a variety of image processing algorithms. After training with FERPlus-A, quantization has been performed. The size of a quantized CNN parameter is about 0.39 MB, and the number of operations is about 28 M integer operations (IOPs). By evaluating the performance of the quantized CNN that uses only integer-arithmetic on the FERPlus test dataset, the classification accuracy is approximately 86.58%. It achieved higher accuracy than other lightweight CNNs in prior studies. The proposed CNN architecture that uses only integer-arithmetic is implemented on the Xilinx ZC706 SoC platform for real-time facial emotion recognition by applying parallelism strategies and efficient data caching strategies. The FPGA-based CNN accelerator implemented for real-time facial emotion recognition achieves about 10 frame per second (FPS) at 250 MHz and consumes 2.3 W.
Overview
CoChat Summary
TL;DR
The paper proposes a lightweight CNN and log level threshold quantization (LLTQ) for integer-arithmetic-only facial emotion recognition on FPGA. It reports ~86.58% accuracy on the FERPlus test dataset, 0.39 MB parameters, 28 M IOPs, and an FPGA accelerator using 5,090 LUTs, 7,588 FFs, 61 BRAMs, 49 DSPs at ~2.3 W and ~10 FPS.
Key findings
- FERPlus-A was built by adding 143,545 images to the 28,709 FERPlus training images, resulting in 172,254 images; training on FERPlus-A improved accuracy from ~71.85% to ~86.58% (~14.73% improvement) on the same FERPlus test dataset.
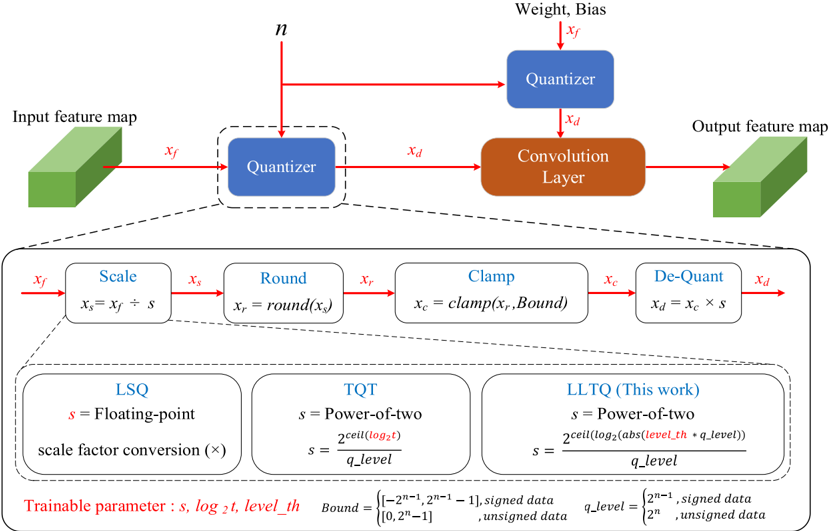
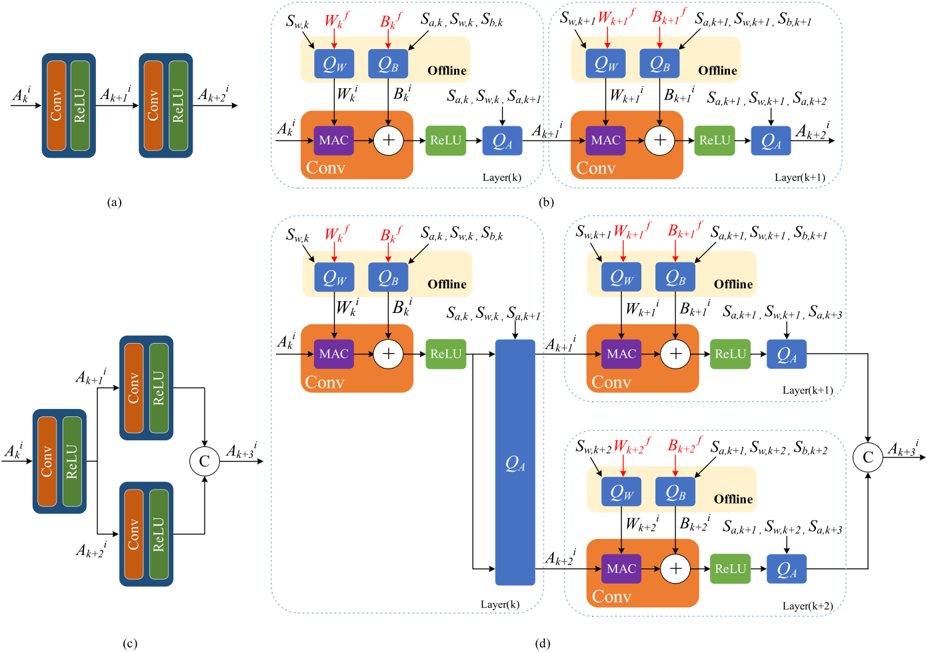
- With 8-bit quantization-aware training, LSQ improved accuracy by ~0.13% over floating-point but was not hardware-friendly; TQT reduced accuracy by ~0.45%; LLTQ showed no accuracy drop relative to floating-point and used only integer-arithmetic.
- The proposed CNN has 0.39 MB parameters, 28 M IOPs, and ~86.58% accuracy; compared with lightweight CNNs, it achieved the highest accuracy among the considered methods, e.g., vs [17] it is 6.33× smaller and 3.28% more accurate but uses 1.4× more operations, and vs [23]-3 it is 1.67× smaller, uses 6.07× fewer operations, and is 0.91% more accurate.
- The FPGA accelerator on Xilinx ZC706 used 5,090 LUTs, 7,588 FFs, 61 BRAMs, and 49 DSPs, consumed ~2.3 W, and achieved ~10 FPS at 250 MHz; INT8 Type-2 vs FP32 Type-1 reduced LUTs by 3.23×, FFs by 4.39×, BRAMs by 1.97×, and DSPs by 4.18×, with total power decreased by 1.87×.
Methods
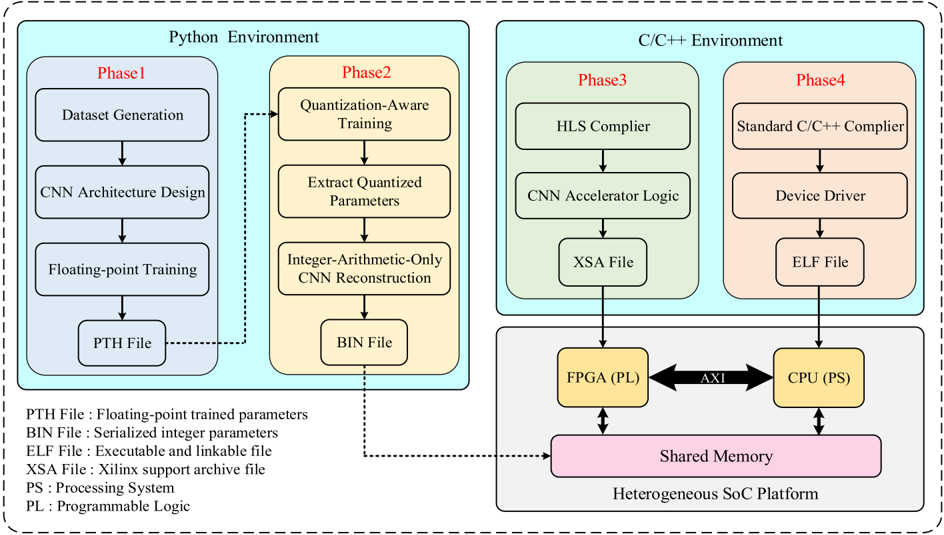
- Design flow: FERPlus-A was created by applying bilateral filtering, CLAHE, and sharpening to FERPlus training images; a lightweight CNN was trained in floating-point, then LLTQ quantization-aware training and integer scale conversion were applied; the CNN accelerator IP was designed with HLS and a device driver with C/C++ on a heterogeneous SoC.
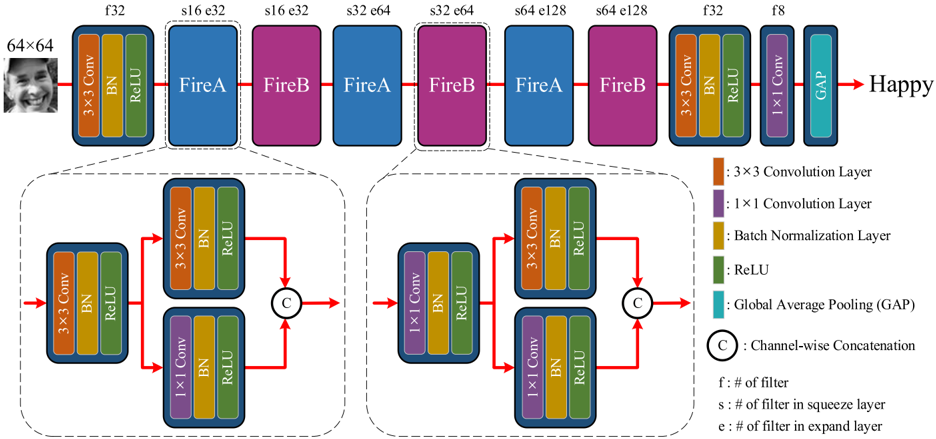
- Architecture: the CNN consists of 21 convolution layers and one global average pooling layer, using modified SqueezeNet fire modules (FireA and FireB), only 3×3 or 1×1 convolutions, power-of-2 feature-map resolution, output channels in multiples of four, ReLU, and BN fusion.
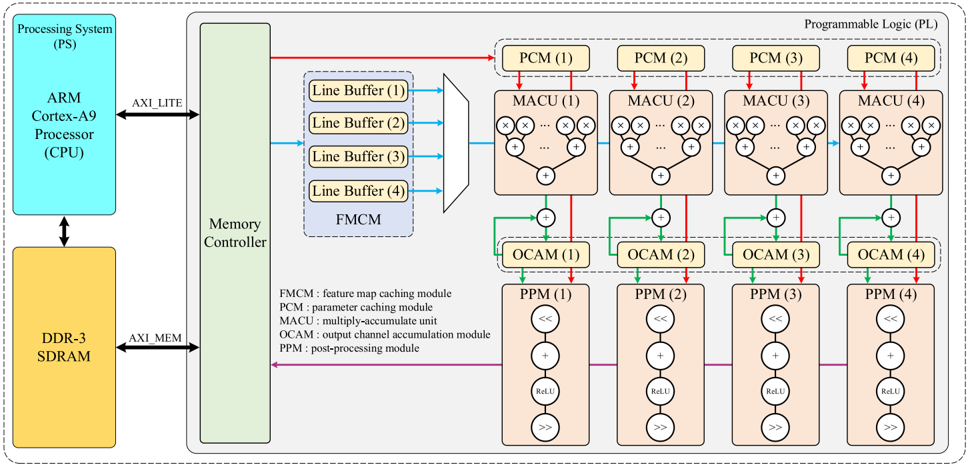
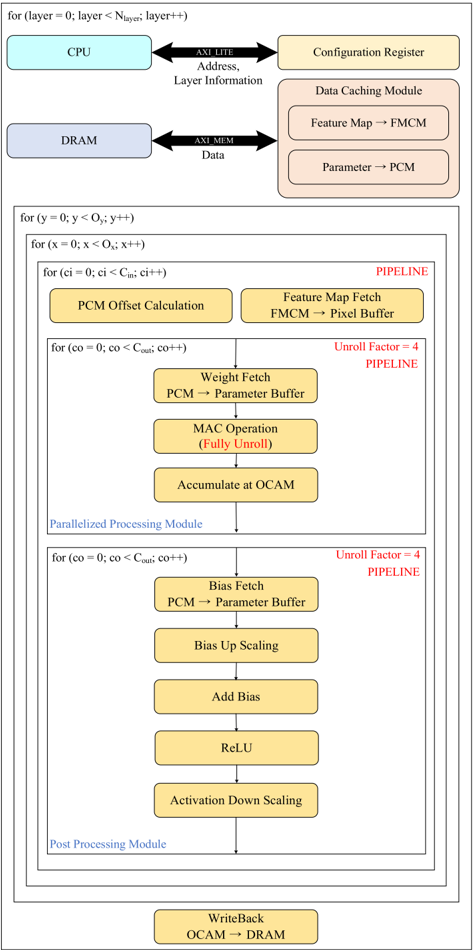
- Hardware and evaluation: implemented on Xilinx Zynq-7000 SoC ZC706 (dual-core ARM Cortex-A9 PS and XC7Z045 PL) using Vivado HLS 2019.2 at a 250 MHz target; parallelism included intra-convolution fully unrolled MACU (9 multipliers, 8 adders for 3×3) and inter-feature-map parallelism with unroll factor 4, plus FMCM/PCM/OCAM caching and a post-processing module; training used FP batch size 64, 200 epochs, Adam with lr 1e-2 and weight decay 1e-5, and QAT batch size 32, 100 epochs, initial lr 1e-5 for weights/biases and 1e-3 for scale factors/log-thresholds/level-thresholds.
Limitations
- The paper does not state a limitations section.
- Evident from the text: compared with [42], the proposed accelerator is more accurate but has a frame rate about 5 FPS slower; compared with [17], it uses 1.4× more operations, though it uses only integer-arithmetic.
- Evident from the text: evaluation is reported only on the FERPlus test dataset, and hardware results are only for the Xilinx ZC706 platform.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
8 Valid · 2 Not valid · 22 Not checked · 49 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“The proposed CNN is optimized the number of operations and memory footprint using the modified fire module in SqueezeNet [13] as the basic computation module.”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > I. INTRODUCTION
What the sources say
- Supportedcites [13] 13. F. N. Iandola, S. Han, M. W. Moskewicz, K. Ashraf, W. J. Dally, and K. Keutzer, ''SqueezeNet: AlexNet-level accuracy with 50x fewer param- eters and <0.5 MB model size,'' 2016, arXiv:1602.07360. [Online]. Avail- able: https://arxiv.org/abs/1602.07360 source
Section 3 (p. 3) introduces the Fire module as SqueezeNet’s building block, and Section 3.3 (p. 4) says SqueezeNet contains eight Fire modules. The citation identifies the module the citing authors say they modified; it does not attribute their CNN design to the SqueezeNet paper. (LLM, conf=0.91)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Compared with the methods in [43] and [44], the proposed method uses fewer resources.”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > D. HARDWARE IMPLEMENTATION ON FPGA
What the sources say
- Partly supportedcites [43] 43. R. Ding, G. Su, G. Bai, W. Xu, N. Su, and X. Wu, ''A FPGA-based accelerator of convolutional neural network for face feature extraction,'' in Proc. IEEE Int. Conf. Electron Devices Solid-State Circuits (EDSSC), Xi'an, China, Jun. 2019, pp. 1-3. sourceExperimental — accuracy not yet measured
In D. Comparison with State-of-the-Art (page unavailable), the paper reports that its DenseNet models have fewer parameters than VGG13 and says they achieve the best tradeoff between accuracy and latency among the models tested. Our copy does not establish that the proposed method uses fewer resources than both methods labeled [43] and [44] in the citing document; those references cannot be identified from the sentence alone. (LLM, conf=0.76)
- Not checked — no full text of the sourcecites [44] 44. R. Ding, X. Tian, G. Bai, G. Su, and X. Wu, ''Hardware implementation of convolutional neural network for face feature extraction,'' in Proc. IEEE 13th Int. Conf. ASIC (ASICON), Chongqing, China, Oct. 2019, pp. 1-4. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“but it reduced accuracy by approximately 0.45% compared to the floating-point result.”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > B. COMPARISON OF OTHER QUANTIZATION WORKS
What the sources say
- Partly supportedcites [39] 39. S. R. Jain, A. Gural, M. Wu, and C. H. Dick, ''Trained quantization thresholds for accurate and efficient fixed-point inference of deep neural networks,'' in Proc. Mach. Learn. Syst., Mar. 2020, pp. 112-128. sourceExperimental — accuracy not yet measured
Section 6.1 (p. 7) reports that INT4 accuracy falls short of FP32, so the paper does describe some accuracy loss. It does not report an approximately 0.45% loss for TQT as a general result; Section 6.2 (p. 8) says its INT8 MobileNet result matches floating-point accuracy with no loss. (LLM, conf=0.83)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Compared to [17], the new method is 6.33 times smaller parameter size”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > C. COMPARISON WITH OTHER LIGHTWEIGHT CNNs
What the sources say
- Partly supportedcites [17] 17. R. K. Pandey, S. Karmakar, A. G. Ramakrishnan, and N. Saha, ''Improving facial emotion recognition systems using gradient and Laplacian images,'' 2019, arXiv:1902.05411. [Online]. Available: https://arxiv.org/abs/1902.05411 sourceExperimental — accuracy not yet measured
Table IV (Experiments and Results, p. 4) reports 0.65 million parameters for the source paper’s base model and variants, providing a possible comparator. The source does not report the citing paper’s new method or a 6.33-fold comparison, so it cannot establish the stated ratio. (LLM, conf=0.82)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“and 3.28% more accurate.”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > C. COMPARISON WITH OTHER LIGHTWEIGHT CNNs
What the sources say
- Partly supportedcites [17] 17. R. K. Pandey, S. Karmakar, A. G. Ramakrishnan, and N. Saha, ''Improving facial emotion recognition systems using gradient and Laplacian images,'' 2019, arXiv:1902.05411. [Online]. Available: https://arxiv.org/abs/1902.05411 sourceExperimental — accuracy not yet measured
Tables I and II (p. 3) and Table IV (p. 4) report accuracy figures that could serve as a comparison benchmark. They do not identify the citing authors’ proposed method or establish that it is 3.28% more accurate; that difference cannot be verified from this source alone. (LLM, conf=0.78)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
62 more claims · 3 with their cited sources checked
Create a free account to see all 81 claims and every source verdict.
- Probably not a substantial claim. 2
- It may state two separate claims as one. 9
- The quote only partly states this claim. 4
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > 1) LOG LEVEL THRESHOLD QUANTIZATION (LLTQ)
“The second step, called the round process, converts all real values mapped to an integer value range into integers.The third step is the clamp process.”
§ A Resource Efficient Integer-Arithmetic-Only FPGA-Based CNN Accelerator for Real-Time Facial Emotion Recognition > 1) LOG LEVEL THRESHOLD QUANTIZATION (LLTQ)
“The clamp(x, Bound) function is the second step of the uniform quantizer and cuts the rounded value (x) to fit inside the Bound.The round(•) function is the third step of the uniform quantizer.”
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Very Deep Convolutional Networks for Large-Scale Image Recognition
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1409.1556 · Cited by 114,148
Densely Connected Convolutional Networks
Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.243 · Cited by 48,566
MobileNetV2: Inverted Residuals and Linear Bottlenecks
Sandler, M., Howard, A., Zhu, M., Zhmoginov, A., & Chen, L.-C. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00474 · Cited by 28,755
A decision-theoretic generalization of on-line learning and an application to boosting
Freund, Y., & Schapire, R. E. (1997) · Journal of Computer and System Sciences · doi:10.1006/jcss.1997.1504 · Cited by 20,466
Rapid object detection using a boosted cascade of simple features
Viola, P., & Jones, M. (2005) · Proceedings of the 2001 IEEE Computer Society Conference on Computer Vision and Pattern Recognition. CVPR 2001 · doi:10.1109/cvpr.2001.990517 · Cited by 18,300
Bilateral Filtering for Gray and Color Images
Tomasi, C., & Manduchi, R. (2002) · Sixth International Conference on Computer Vision (IEEE Cat. No.98CH36271) · doi:10.1109/iccv.1998.710815 · Cited by 8,177
Active Shape Models-Their Training and Application
Cootes, T. F., Taylor, C. J., Cooper, D. H., & Graham, J. (1995) · Computer Vision and Image Understanding · doi:10.1006/cviu.1995.1004 · Cited by 7,190
(2016) · arXiv (Cornell University) · Cited by 6,201
SqueezeNet: AlexNet-level accuracy with 50x fewer parameters and <0.5MB model size
Iandola, F. N., Han, S., Moskewicz, M. W., Ashraf, K., Dally, W. J., & Keutzer, K. (2016) · arXiv · doi:10.48550/arxiv.1602.07360 · Cited by 6,201
Research works printed but not linked: 2
- 48. JIN-KU KANG (Senior Member, IEEE) received the B.S. degree from Seoul National University, Seoul, South Korea, in 1983, the M.S. degree in electrical engineering from New Jersey Insti- tute of Technology, Newark, NJ, USA, in 1990, and the Ph.D. degree in electrical and computer engineering from North Carolina State University, Raleigh, NC, USA, in 1996. From 1983 to 1988, he was with Samsung Electronics, Inc., South Korea, where he was involved in memory design. In 1988, he was with Texas Instruments, South Korea. From 1996 to 1997, he was with Intel Corporation, Portland, OR, USA, as a Senior Design Engineer, where he was involved in high-speed I/O and timing circuits for processors. Since 1997, he has been with Inha University, Incheon, South Korea, where he is currently a Professor and leads the System IC Design Laboratory, Department of Electronics Engineering. His research interest includes high-speed/low-power mixed-mode circuit design for high-speed serial interfaces.
- 49. YONGWOO KIM (Member, IEEE) received the B.S. and M.S. degrees from Inha University, Incheon, South Korea, in 2007 and 2009, respec- tively, and the Ph.D. degree in electrical engi- neering from Korea Advanced Institute of Science and Technology, Daejeon, South Korea, in 2019. From 2009 to 2017, he was a Senior Engineer with Silicon Works Company Ltd., Daejeon. From 2019 to 2020, he was a Senior Researcher with the Artificial Intelligence Research Division, Korea Aerospace Research Institute, Daejeon. Since 2020, he has been with Sangmyung University, Cheonan, South Korea, where he is currently an Assistant Professor with the Department of System Semiconductor Engi- neering. His current research interests include image/video processing algo- rithm, super-resolution, and deep learning hardware architecture for vision processing.
Cited by
Systematic Review of Emotion Detection with Computer Vision and Deep Learning
Pereira, R., Mendes, C., Ribeiro, J., Ribeiro, R., Miragaia, R., Rodrigues, N. M. M., Costa, N., & Pereira, A. M. D. J. (2024) · Sensors · doi:10.3390/s24113484 · Cited by 112
“Simultaneously, lightweight solutions [93,134] target embedded systems and edge computing with improved results over state-of-the-art CNNs [104,119,124,132,136].”
BackgroundUllah, Z., Qi, L., Hasan, A., & Asim, M. F. (2022) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2022.105486 · Cited by 40
6G toward Metaverse: Technologies, Applications, and Challenges
Peng, H., Chen, P.-C., Chen, P.-H., Yang, Y.-S., Hsia, C.-C., & Wang, L. (2022) · IEEE VTS Asia Pacific Wireless Communications Symposium (APWCS) · doi:10.1109/apwcs55727.2022.9906483 · Cited by 49
“However, generating vivid expressions of humans requires emotion recognition, which usually comes from video, audio, and EEG signals [42], [43].”
BackgroundShehada, D. J. M., Turky, A. M., Khan, W., Khan, B., & Hussain, A. J. (2023) · IEEE Access · doi:10.1109/access.2023.3264268 · Cited by 39
“Another lightweight approach is proposed in [17] for real-time expression detection.”
BackgroundMethodA Low-Cost Fully Integer-Based CNN Accelerator on FPGA for Real-Time Traffic Sign Recognition
Kim, J., Kang, J.-K., & Kim, Y. (2022) · IEEE Access · doi:10.1109/access.2022.3197906 · Cited by 23
Self-citationA Low-Power Hardware Architecture for Real-Time CNN Computing
Liu, X., Cao, C., & Duan, S. (2023) · Sensors · doi:10.3390/s23042045 · Cited by 21
“[16] designed lightweight CNNs by quantizing the data from floating-point numbers to fixed-point numbers, and specifically considering the hardware structures, to reduce the overall cost.”
BackgroundNAGNet: A novel framework for real‐time students' sentiment analysis in the wisdom classroom
Zhu, H., Hu, P., Tang, X., Xia, D., & Huang, H. (2023) · Concurrency and Computation Practice and Experience · doi:10.1002/cpe.7727 · Cited by 20
Real-Time Facial Expression Recognition Based on Image Processing in Virtual Reality
Gong, Q., Liu, X., & Ma, Y. (2025) · International Journal of Computational Intelligence Systems · doi:10.1007/s44196-024-00729-9 · Cited by 17
“One of the most common ways people convey and amplify non-verbal information in everyday interactions is through facial expressions [6].”
A Comprehensive Multimodal Humanoid System for Personality Assessment Based on the Big Five Model
Jaffar, A., Ali, S., Iqbal, K. F., Ayaz, Y., Ansari, A. R., Fayyaz, M. A. B., & Nawaz, R. (2024) · IEEE Access · doi:10.1109/access.2024.3412931 · Cited by 18
“Accuracies achieved on the FER + dataset are 92.02% [28], 89.50% [41], 84.633% [44], and 86.58% [47].”
InfluentialKreß, F., Sidorenko, V., Schmidt, P., Hoefer, J., Hotfilter, T., Walter, I., Harbaum, T., & Becker, J. (2023) · Computer Networks · doi:10.1016/j.comnet.2023.109759 · Cited by 20
Sledević, T., Serackis, A., & Plonis, D. (2022) · Agriculture · doi:10.3390/agriculture12111849 · Cited by 17
Oh, H. W., & Lee, S. E. (2023) · IEEE Access · doi:10.1109/access.2023.3276411 · Cited by 14
Fata, J. S., Elmannai, W., & Elleithy, K. M. (2025) · IEEE Access · doi:10.1109/access.2025.3594348 · Cited by 15
“• Integer Arithmetic-Only Computation, introduced by Kim et al. in [9], eliminated floating-point units and kept integer mathematics only.”
InfluentialFrom methods to datasets: a detailed study on facial emotion recognition
Nidhi, & Verma, B. (2023) · Applied Intelligence · doi:10.1007/s10489-023-05052-y · Cited by 17
LiteFer: An Approach Based on MobileViT Expression Recognition
Yang, X., Lan, Z., Wang, N., Li, J., Wang, Y., & Meng, Y. (2024) · Sensors · doi:10.3390/s24185868 · Cited by 9
Machine Learning for Agile FPGA Design
Pal, D., Deng, C., Ustun, E., Yu, C., & Zhang, Z. (2022) · Springer eBooks · doi:10.1007/978-3-031-13074-8_16 · Cited by 8
Saurav, S., Saini, R., & Singh, S. K. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-19012-2 · Cited by 12
Design and implementation of an efficient CNN accelerator for low-cost FPGAs
Xu, Y., Wang, S., Li, N., & Xiao, H. (2022) · IEICE Electronics Express · doi:10.1587/elex.19.20220370 · Cited by 10
An FPGA-Based BNN Real-Time Facial Emotion Recognition Algorithm
Zhao, G., Wei, W., Xie, X., Fan, S., & Sun, K. (2022) · IEEE International Conference on Artificial Intelligence and Computer Applications (ICAICA) · doi:10.1109/icaica54878.2022.9844526 · Cited by 8
Shehada, D. J. M., Tawfik, H., Bouridane, A., & Hussain, A. J. (2025) · Sensors · doi:10.3390/s25237320 · Cited by 12
“Similarly, Kim et al. [12] applied Log-Level Threshold Quantization (LLTQ) to reduce computation, achieving 86.5% accuracy on FER+, though energy consumption remained high [13].”
InfluentialResearch on Face Detection and Face Attribute Recognition based on Deep Learning
Zhang, W., Guan, S., Wang, C., Zhang, Y., & Zhou, X. (2021) · IEEE International Conference on Intelligent Data Acquisition and Advanced Computing Systems: Technology and Applications (IDAACS) · doi:10.1109/idaacs53288.2021.9660982 · Cited by 5
Patil, S. B., & Shirgave, S. (2024) · The Visual Computer · doi:10.1007/s00371-024-03369-4 · Cited by 5
An FPGA System for Driver Mobile Usage Detection and Heart Rate-Based Health Monitoring
Heenetimulla, H. D. S. M., Das, S. K., Sahoo, G. K., et al. (2022) · doi:10.1109/odicon54453.2022.10010243 · Cited by 4
“[15] proposed a system for FPGA-based CNN accelerator for real-time facial emotion recognition.”
BackgroundLow-Cost FPGA-Enhanced CNN Accelerator for Real-Time YOLO Object Detection and Classification
Fata, J. S., & Elmannai, W. (2026) · IEEE Access · doi:10.1109/access.2026.3669451 · Cited by 5
“While studies have integrated hardware pruning and quantization algorithms independently [8], [15], [21], [25], [26] due to accuracy loss concerns, the proposed approach integrates both by optimizing each algorithm to reduce accuracy loss.”
Kim, J., Kang, J.-K., & Kim, Y. (2025) · IEEE Transactions on Very Large Scale Integration (VLSI) Systems · doi:10.1109/tvlsi.2025.3621624 · Cited by 4
Self-citationCNN Accelerator Using Proposed Diagonal Cyclic Array for Minimizing Memory Accesses
Son, H.-W., Al-Hamid, A. A., Na, Y.-S., Lee, D.-Y., & Kim, H. (2023) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2023.038760 · Cited by 2
“Furthermore, a hardware-friendly quantization uses only integer arithmetic with power-of-two scale factors to replace multiplication and division operations with shift operations can be utilized to reduce the memory footprint and complexity of computations [6].”
MethodNAGNet: A Convolutional Neural Network for Real-Time Sentiment Analysis of Students
Zhu, H., Hu, P., Tang, X., & Xia, D. (2022) · International Conference on Information Technology in Medicine and Education · doi:10.1109/itme56794.2022.00027 · Cited by 2
Shehada, D. J. M., Tawfik, H., Bouridane, A., & Hussain, A. (2026) · Computers · doi:10.3390/computers15030139 · Cited by 1
Dritsas, E., & Trigka, M. (2026) · AI and Ethics · doi:10.1007/s43681-026-01004-7 · Cited by 2
“…a distinct ethical failure mode known as consent fatigue , in which repeated requests desensitize users and erode sub-stantive autonomy despite formal compliance [ 23 ]. knowledge distillation techniques have been proposed as promising solutions for improving computational efficiency [ 29–31 ].”
An SoC-based CNN accelerator for face recognition using HWCK data scheduling
Tsai, T., & Hsu, C. (2025) · Multimedia Systems · doi:10.1007/s00530-025-01838-x · Cited by 1
LLTQ+: A Hardware-Friendly Quantization Framework for Modern YOLO Architectures
Seo, Y., Kim, J., Kang, J.-K., & Kim, Y. (2025) · IEEE Access · doi:10.1109/access.2025.3603536 · Cited by 2
“References [21] and [22] Additionally, batch normalization layers are commonly fused into adjacent convolution layers before Quantization-Aware Training (QAT) to mitigate quantization issues associated with batch normalization.”
InfluentialSelf-citationEnhanced Lightweight Facial Emotion Recognition Systems for Visually Impaired People
Shehada, D. J. M., Turky, A. M., Rabie, T. F., & Hussain, A. J. (2024) · IEEE Conference on Systems, Process and Control · doi:10.1109/icspc63060.2024.10862684 · Cited by 1
“An addition a CNN with log-level quantization model [12] achieved 86.5% accuracy on FER+[13].”
InfluentialFacial Expression Recognition System Using DNN Accelerator with Multi-threading on FPGA
Ando, T., & Inoue, Y. (2024) · International Symposium on Computing and Networking Workshops (CANDARW) · doi:10.1109/candarw64572.2024.00025 · Cited by 1
“Consequently, only facial expression recognition methods have been proposed [11], [12].”
Autoencoder-based Knowledge Distillation For Quantized YOLO Detector
Seo, Y., Kang, J.-K., & Kim, Y. (2024) · International SoC Design Conference · doi:10.1109/isocc62682.2024.10762165 · Cited by 1
“In this paper, we quantized weights, biases, and activations in the network, using the LSQ [1] and LLTQ [2] methods.”
InfluentialSelf-citationDesign of Low-power EEG Detection System for Emotion Classification
Mo, Z., Yuan, Y., Shi, W., Mai, J., Zeng, D., Liu, X., & Li, G. (2024) · International Conference on Electronics Technology (ICET) · doi:10.1109/icet61945.2024.10673238 · Cited by 1
“Jaemyung Kim team proposed a lightweight CNN structure using the modified SqueezeNet [7] as a computing module [8].”
MethodEnhancing Facial Expression Recognition through Ensemble Deep Learning
Agustin, T., Purwidiantoro, M. H., & Rahmadi, M. L. (2023) · International Conference on Cybernetics and Intelligent System (ICORIS) · doi:10.1109/icoris60118.2023.10352183 · Cited by 4
“The study by [13], an in-depth analysis was carried out on the effect of the proposed methods on the FER classification task on embedded systems.”
MethodEngagement Analysis of Learners Using Emotions: The SimEng System
Malekshahi, S., & Fatemi, O. (2023) · International and National Conference on E-Learning and E-Teaching (ICeLeT) · doi:10.1109/icelet58996.2023.10139905 · Cited by 1
“Many practical works have been done in this area [19][20], but more effective models are still being presented to adapt to new systems [21].”
BackgroundAcceleration of Neural Network training algorithms via FPGA devices
Zoltán-Valentin, G.-N. (2023) · Procedia Computer Science · doi:10.1016/j.procs.2023.10.259 · Cited by 2
FPGA-Based Integer-Only Hardware Accelerator for YOLOv3-Tiny Model
Kim, J., Kim, J., Kang, J.-K., et al. (2025) · doi:10.1109/isocc66390.2025.11330141
“A. Log-Level Threshold Quantization (LLTQ) LLTQ [1] is a hardware-friendly quantization method for Quantization-Aware Training (QAT).”
InfluentialSelf-citationEmerging Field of NoC-Based Convolution Architecture with Systolic Arrays
Gadikota, C., & Vijaya Lakshmi, P. (2025) · IEEE International Conference on Communication Systems and Network Technologies (CSNT) · doi:10.1109/csnt64827.2025.10967793
“To address these challenges, researchers have been exploring the use of Field-Programmable Gate Arrays (FPGAs) to accelerate CNNs. H. Fan et al. [32], proposed that FPGAs have emerged as a promising platform for accelerating CNNs, offering high performance, low power consumption, and flexibility.”
Unveiling emotions in real-time: a novel approach to face emotion recognition
Gowthami, & Vijayalakshmi, S. (2025) · Elsevier eBooks · doi:10.1016/b978-0-443-26765-9.00008-1
ConvMap: Boosting Convolution Throughput on FPGAs with Efficient Resource Mapping
Das, S., Rao, N., & Sinha, S. (2024) · doi:10.1109/ipdpsw63119.2024.00049
A Review on Facial Emotion Recognition of Subjects Using Deep Learning Techniques
Kumar, P. S., Nikhil, M., Rudresh, P. H. S., Kiran, K. S., Charan, K., & Prasad, K. S. (2024) · International Conference on Social and Sustainable Innovations in Technology and Engineering (SASI-ITE) · doi:10.1109/sasi-ite58663.2024.00016
Real-Time Emotion Recognition System for Dynamic Real-World Environments
Madnani, M. (2023) · International Conference on Developments in eSystems Engineering (DeSE) · doi:10.1109/dese60595.2023.10469007 · Cited by 1
FPGA-Based Convolutional Neural Network for Classifying Image Blocks
Vysotskiy, A. S., Zinkevich, A. V., & Sai, S. V. (2023) · International Russian Automation Conference (RusAutoCon) · doi:10.1109/rusautocon58002.2023.10272870
“Functions from the Deep Learning Toolbox (DLT) library of the MATLAB environment based on the MNIST database were used to create and train the neural network [4-11].”
MethodSYNTACTIC ANALYSIS OF ARITHMETIC EXPRESSIONS FOR OPTIMIZING THE OPERATION OF PROGRAMS
Peretiaha, M., Poltavets, M., Smelyakov, K., & Chupryna, A. (2023) · ГРААЛЬ НАУКИ · doi:10.36074/grail-of-science.14.04.2023.039
“In [8], as well as in [6], the authors proposed a solution for building an accelerator for a convolutional neural network based on FPGA based on the cost of computing resources; the algorithm uses only integer arithmetic operations.”
Performance of Image Recognition with Machine Vision: A Systematic Review
Lopez-Carreño, J., Calvo-Lavado, C., & Zarate-Perez, E. (2023) · LACCEI International Multi-Conference for Engineering, Education and Technology (LACCEI) · doi:10.18687/laccei2023.1.1.839
Flexible Convolver for Convolutional Neural Networks Deployment onto Hardware-Oriented Applications
Arredondo-Velázquez, M., Aguirre-Alvarez, P. A., Padilla-Medina, J. A., Calderón, A. E., Prado-Olivarez, J., & Díaz-Carmona, J. (2022) · Applied Sciences · doi:10.3390/app13010093
Metadata
- Authors
- Kim, J., Kang, J.-K., & Kim, Y.
- Affiliations
- Inha University (KR)
- Sangmyung University (KR)
- Venue
- IEEE Access
- Published
- 2021
- Volume
- 9
- Pages
- 104367-104381
- ISSN
- 2169-3536 (ISSN-L)
- OpenAlex
- W3186146740
- Semantic Scholar
- a22bddd6df37451f8c9882b21854d21696f264d1
- Cited by
- 50
- References
- 62
- Citations by year
- 2026: 5 · 2025: 9 · 2024: 11 · 2023: 14 · 2022: 10 · 2021: 1
- FWCI
- 3.23
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- IEEE Access (publishedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Hardware and Architecture › Embedded Systems Design Techniques
- Physical Sciences › Engineering › Electrical and Electronic Engineering › Embedded Systems and FPGA Applications
- Keywords
- facial emotion recognition, lightweight CNN architecture, embedded systems, real-time inference, shift operations, data caching
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-06, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-06 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
