

The DOI matches its Crossref record; 33 of the 33 references it cites were found in a registry or an index; none of the 13 sources its claims cite is checked for support yet.
Extreme Audio Time Stretching Using Neural Synthesis
Open accessAbstract
A deep neural network solution for time-scale modification (TSM) focused on large stretching factors is proposed, targeting environmental sounds. Traditional TSM artifacts such as transient smearing, loss of presence, and phasiness are heavily accentuated and cause poor audio quality when the TSM factor is four or larger. The weakness of established TSM methods, often based on a phase vocoder structure, lies in the poor description and scaling of the transient and noise components, or nuances, of a sound. Our novel solution combines a sines-transients-noise decomposition with an independent WaveNet synthesizer to provide a better description of the noise component and an improve sound quality for large stretching factors. Results of a subjective listening test against four other TSM algorithms are reported, showing the proposed method to be often superior. The proposed method is stereo compatible and has a wide range of applications related to the slow motion of media content.
Overview
CoChat Summary
TL;DR
The paper proposes a hybrid time-scale modification method for extreme stretching of environmental sounds, combining two-stage sines-transients-noise (STN) decomposition with a WaveNet synthesizer that resynthesizes the noise component. In a subjective listening test at TSM factors 4 and 8, the proposed method was often rated superior to four comparison algorithms.
Key findings
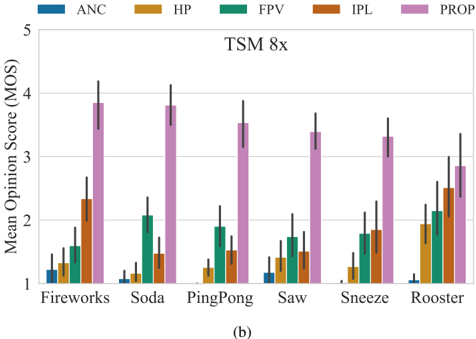
- The proposed method outperformed fuzzy phase vocoder (FPV), harmonic-percussive TSM (HP), identity phase locking (IPL), and WSOLA under both tested time-stretching conditions for all samples except “Rooster.”
- Among three local conditioning representations tested for the WaveNet noise synthesizer—spectrogram, mel-spectrogram, and Constant-Q Transform (CQT) spectrogram—the CQT spectrogram produced the highest quality results.
- The method is stereo compatible: STN decomposition is transparent with respect to the stereo field, and stereo balance and phase coherence between left and right channels are preserved when components are recomposed.
- Training used approximately 4 hours of audio, 1,900,000 iterations, and about 200 hours on a GPU; the CQT conditioning used a 256-sample hop at 44.1 kHz, 32.7 Hz minimum frequency, Nyquist maximum, and 48 bins per octave, giving 451 frequency bins.
Methods
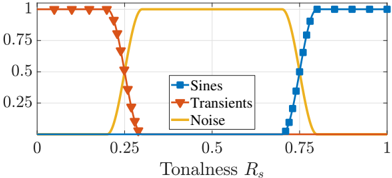
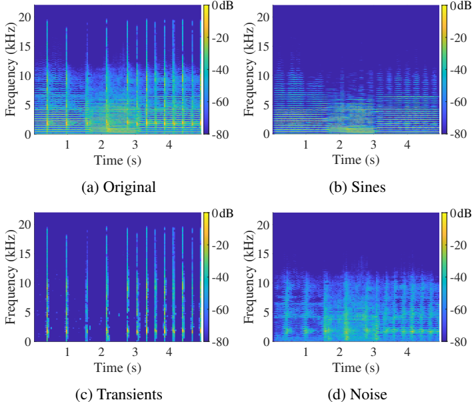
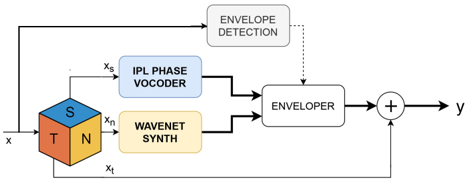
- The pipeline decomposes input audio into sines, transients, and noise using two-stage soft spectral masks. Sines are processed with a phase vocoder using identity phase locking, transients are preserved and relocated onto the new time axis, and noise is neurally resynthesized at the desired TSM factor.
- The WaveNet synthesizer is autoregressively trained at 44.1 kHz to generate raw 16-bit audio using a 10-component Mixture-of-Logistic distributions sampling method, with CQT spectrogram local conditioning and beam-search at inference to remove spurious impulse events.
- Evaluation was a formal blind listening test with 14 experienced listeners, six audio samples, TSM factors α = 4 and α = 8, 24 trials total, and 72 audio samples under investigation; ratings were collected on a 0–100 scale and analyzed as Mean Opinion Scores with 95% confidence intervals.
Limitations
- The paper does not include a dedicated limitations section. It states future work involves redesigning the neural synthesis for standard time-stretching factors and using a larger dataset of more relevant sounds.
- Evident from the text: the listening test used only 14 listeners and six short environmental samples (approximately 2 s each), and it evaluated only extreme factors of 4 and 8, not standard TSM factors.
- Evident from the text: the proposed method is designed and trained for environmental sounds, and the “Rooster” sample was an exception where the proposed method did not clearly outperform the others; participants commented that its noisy nature and lack of sharp transients made expectations for a stretched version difficult.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 1 Not valid · 8 Not checked · 13 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Three different time-frequency representations were tested as local conditioning signals for the network: spectrogram, melspectrogram, and Constant-Q Transform (CQT) spectrogram.Different models were trained using each of these representations, and it was found that using the CQT-spectrogram produced the highest quality results.”
§ EXTREME AUDIO TIME STRETCHING USING NEURAL SYNTHESIS > 3.2. WaveNet-based TSM
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A check of a cited source is scheduled, or we don’t hold its full text yet; the claim is checked once it runs.
In the paper
“The weakness of established TSM methods, often based on a phase vocoder structure, lies in the poor description and scaling of the transient and noise components, or nuances, of a sound.”
- Also stated in: § 1. INTRODUCTION · hedged
“It was also hinted that the potential weakness of the fuzzy phase vocoder [9], which received the highest overall score both on average and for the largest tested α in a recent comparison of audio TSM methods [10], lies in the poor description and scaling of the”
§ EXTREME AUDIO TIME STRETCHING USING NEURAL SYNTHESIS > Abstract
What the sources say
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1. INTRODUCTION · hedged
In the paper
“The WaveNet synthesizer can be used for TSM by adjusting the number of audio samples generated per frame of the local conditioning signal, similarly to how the hop size between consecutive frames is adjusted from analysis to synthesis in traditional DSP methods.”
- Also stated in: § 3.2. WaveNet-based TSM · plain
“Time stretching via WaveNet is achieved by adjusting the number of audio samples generated per frame of the local conditioning signal, according to α.”
§ EXTREME AUDIO TIME STRETCHING USING NEURAL SYNTHESIS > 1. INTRODUCTION
What the sources say
- Not checked yetcites [17] source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3.2. WaveNet-based TSM · plain
In the paper
“The proposed method is stereo compatible and has a wide range of applications related to the slow motion of media content.”
- Also stated in: § 4.3. Stereo compatibility · plain
“The process described so far can be individually applied to the two channels of a stereo sound, as STN decomposition is transparent with respect to the stereo field.”
- Also stated in: § 4.3. Stereo compatibility · plain
“When a sound is decomposed into its individual components and then recomposed, the stereo balance and phase coherence between the left and the right channel, computed according to [27] are preserved.”
§ EXTREME AUDIO TIME STRETCHING USING NEURAL SYNTHESIS > Abstract
What the sources say
- Not matchedcites [27] Ramires, The Freesound loop dataset and annotation tool
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
- Also stated in: § 4.3. Stereo compatibility · plain
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The STN decomposition enables the application of different TSM algorithms for each component.”
§ EXTREME AUDIO TIME STRETCHING USING NEURAL SYNTHESIS > 2. STN DECOMPOSITION
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
5 more claims
Create a free account to see all 22 claims and to verify the 12 references still open.
- Borderline: one of the tests for a substantial claim is unclear. 1
- It may state two separate claims as one. 7
- The quote only partly states this claim. 1
- Probably not a substantial claim. 7
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“A solution involving a Wavenet neural synthesizer for the noise component has also proved successful for extreme time stretching of environmental sounds [17].”
From Noise Morphing for Audio Time Stretching (2024) · cites this paper as [17]
In the citing paper
“Our test approach, a variation of the standard MUSHRA test [35], has been used earlier in TSM studies [4], [17], and employs a multiple-stimuli method with the original, unprocessed sound as the reference.”
From Noise Morphing for Audio Time Stretching (2024) · cites this paper as [17]
Citations
Cites
WaveNet: a generative model for raw audio
Oord, A. V. D., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., & Kavukcuoglu, K. (2016) · arXiv · doi:10.48550/arxiv.1609.03499 · Cited by 4,911
Piczak, K. J. (2015) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/2733373.2806390 · Cited by 1,572
Calculation of a constant Q spectral transform
Brown, J. T. (1991) · The Journal of the Acoustical Society of America · doi:10.1121/1.400476 · Cited by 925
Serra, X., & Smith, J. (1990) · Computer Music Journal · doi:10.2307/3680788 · Cited by 338
Non-parametric techniques for pitch-scale and time-scale modification of speech
Moulines, É., & Laroche, J. (1995) · Speech Communication · doi:10.1016/0167-6393(94)00054-e · Cited by 289
Improved phase vocoder time-scale modification of audio
Laroche, J., & Dolson, M. (1999) · IEEE Transactions on Speech and Audio Processing · doi:10.1109/89.759041 · Cited by 276
Parallel WaveNet: Fast High-Fidelity Speech SynthesisPreprint
van den Oord, A., Li, Y., Babuschkin, I., Simonyan, K., Vinyals, O., Kavukcuoglu, K., van den Driessche, G., Lockhart, E., Cobo, L. C., Stimberg, F., et al. (2017) · arXiv (Cornell University) · Cited by 262
Ito, K. A. (2024) · TIB Data Manager · doi:10.57702/yamk7ojd · Cited by 259
webMUSHRA — A Comprehensive Framework for Web-based Listening Tests
Schoeffler, M., Bartoschek, S., Stöter, F.-R., Roess, M., Westphal, S., Edler, B., & Herre, J. (2018) · Journal of Open Research Software · doi:10.5334/jors.187 · Cited by 236
Verhelst, W., & Roelands, M. (1993) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp.1993.319366 · Cited by 217
Huzaifah, M. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1706.07156 · Cited by 171
Nam, J., Choi, K., Lee, J., Chou, S.-Y., & Yang, Y. (2018) · IEEE Signal Processing Magazine · doi:10.1109/msp.2018.2874383 · Cited by 117
Hybrid representations for audiophonic signal encoding
Daudet, L., & Torrésani, B. (2002) · Signal Processing · doi:10.1016/s0165-1684(02)00304-3 · Cited by 94
A Review of Time-Scale Modification of Music Signals
Driedger, J., & Müller, M. (2016) · Applied Sciences · doi:10.3390/app6020057 · Cited by 71
Solving Audio Inverse Problems with a Diffusion Model
Moliner, E., Lehtinen, J., & Välimäki, V. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10095637 · Cited by 65
Self-citationImproving Time-Scale Modification of Music Signals Using Harmonic-Percussive Separation
Driedger, J., Muller, M., & Ewert, S. (2014) · IEEE Signal Processing Letters · doi:10.1109/lsp.2013.2294023 · Cited by 64
Extending spectral modeling synthesis with transient modeling synthesis
Verma, T. S., & Meng, T. H. Y. (2000) · Computer Music Journal · doi:10.1162/014892600559317 · Cited by 35
Audio Time Stretching Using Fuzzy Classification of Spectral Bins
Damskägg, E.-P., & Välimäki, V. (2017) · Applied Sciences · doi:10.3390/app7121293 · Cited by 34
Self-citationPhase-vocoder: about this phasiness business
Laroche, J., & Dolson, M. (2002) · Proceedings of 1997 Workshop on Applications of Signal Processing to Audio and Acoustics · doi:10.1109/aspaa.1997.625603 · Cited by 23
Speech-adaptive time-scale modification for computer assisted language-learning
Donnellan, O., Jung, E., & Coyle, E. (2004) · IEEE International Conference on Advanced Learning Technologies (ICALT) · doi:10.1109/icalt.2003.1215049 · Cited by 21
Speech Time-Scale Modification With GANs
Cohen, E., Kreuk, F., & Keshet, J. (2022) · IEEE Signal Processing Letters · doi:10.1109/lsp.2022.3164361 · Cited by 13
Dutilleux, P., Poli, G. D., Knesebeck, A. V. D., & Zölzer, U. (2011) · Wiley eBooks · doi:10.1002/9781119991298.ch6 · Cited by 10
The Freesound Loop Dataset and Annotation ToolPreprint
Ramires, A., Font, F., Bogdanov, D., Smith, J. B. L., Yang, Y., Ching, J., Chen, B., Wu, Y.-K., Wei-Han, H., & Serra, X. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2008.11507 · Cited by 10
Välimäki, V., Rämö, J., & Flores, F. E. (2018) · Aaltodoc (Aalto University) · Cited by 8
Self-citationHang the DJ Automatic sequencing and seamless mixing of dance-music tracks
Cliff, D., & Hewlett-Packard Laboratories, B. (. K. (2000) · Cited by 7
Enhanced Fuzzy Decomposition of Sound Into Sines, Transients, and Noise
Fierro, L., & Välimäki, V. (2023) · Journal of the Audio Engineering Society · doi:10.17743/jaes.2022.0077 · Cited by 4
Self-citationTimbral effects the Paulstretch audio time-stretching algorithm
Malloy, C. (2022) · The Journal of the Acoustical Society of America · doi:10.1121/10.0010964 · Cited by 3
Deep Learning-Based Single-Ended Quality Prediction for Time-Scale Modified Audio
Roberts, T., Nicolson, A., & Paliwal, K. K. (2021) · Journal of the Audio Engineering Society · doi:10.17743/jaes.2021.0031 · Cited by 2
Stereo Time-Scale Modification Using Sum and Difference Transformation
Roberts, T., & Paliwal, K. K. (2018) · 2018 12th International Conference on Signal Processing and Communication Systems (ICSPCS) · doi:10.1109/icspcs.2018.8631776 · Cited by 1
(2009) · Publikationsdatenbank der Fraunhofer-Gesellschaft (Fraunhofer-Gesellschaft)
(2010) · Arrow@dit (Dublin Institute of Technology)
(2014)
TimbreTron: A WaveNet(CycleGAN(CQT(Audio))) Pipeline for Musical Timbre Transfer
Huang, S., Li, Q., Anil, C., Bao, X., Oore, S., & Grosse, R. B. (2018) · arXiv · doi:10.48550/arxiv.1811.09620
Research works printed but not linked: 2
- Moinet, 2013, Slowdio: Audio Time-Scaling for Slow Motion Sports Videos
- 2015, Algorithms to measure audio programme loudness and true-peak audio level
Cited by
Yousefi, S., Najjar-Ghabel, S., & Owaid, Z. S. (2025) · IEEE Symposium on Computers & Informatics (ISCI) · doi:10.1109/isci65687.2025.11167791 · Cited by 3
Noise Morphing for Audio Time Stretching
Moliner, E., Fierro, L., Wright, A., Hämäläinen, M. S., & Välimäki, V. (2024) · IEEE Signal Processing Letters · doi:10.1109/lsp.2024.3386118 · Cited by 2
Self-citation
Metadata
- Authors
- Fierro, L., Wright, A., Välimäki, V., & Hämäläinen, M.
- Affiliations
- Aalto University (FI)
- Nokia (Finland) (FI)
- Venue
- ICASSP 2023 - 2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)
- Publisher
- IEEE
- Published
- 2023-06-04
- Pages
- 1-5
- ISSN
- 1520-6149 (ISSN-L)
- OpenAlex
- W4375869273
- Cited by
- 2
- References
- 33
- Citations by year
- 2025: 1 · 2024: 1
- FWCI
- 0.35
- Type
- conference paper
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- IEEE International Conference on Acoustics Speech and Signal Processing (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- Aaltodoc (Aalto University) (submittedVersion, other-oa)
- Edinburgh Research Explorer (University of Edinburgh) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- Nokia
- Topics
- Physical Sciences › Computer Science › Signal Processing › Music and Audio Processing
- Physical Sciences › Computer Science › Signal Processing › Speech and Audio Processing
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- time-scale modification, environmental sounds, WaveNet, neural audio synthesis, stereo audio
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
