

The DOI matches its Crossref record; 23 of the 23 references it cites were found in a registry or an index.
PromptMagician: Interactive Prompt Engineering for Text-to-Image Creation
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
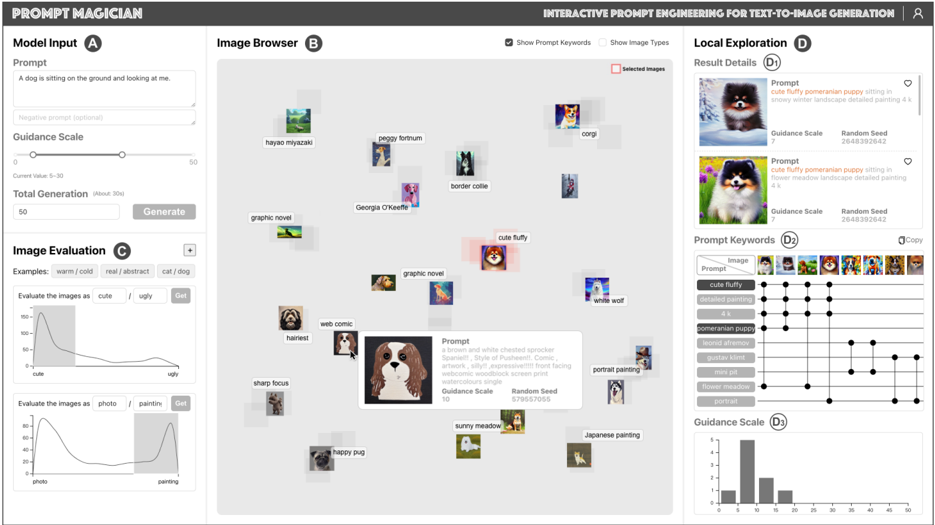
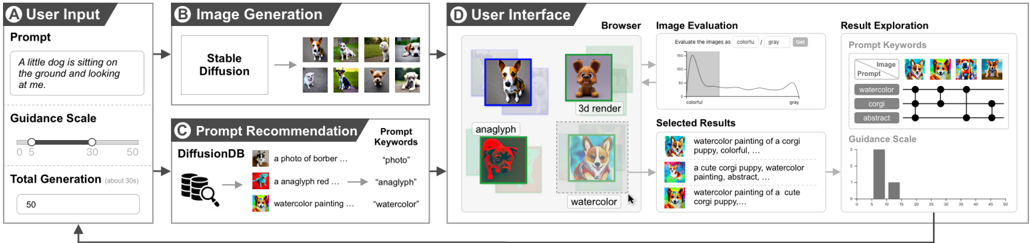
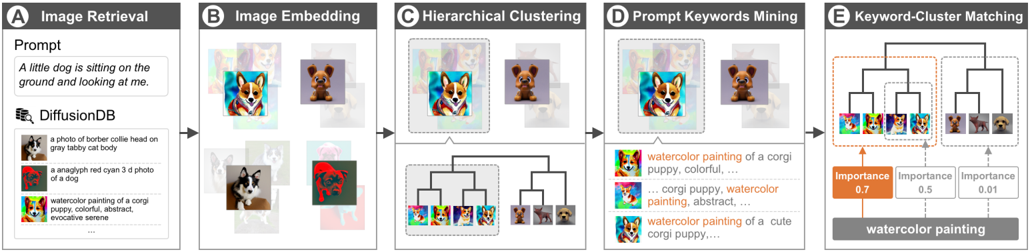
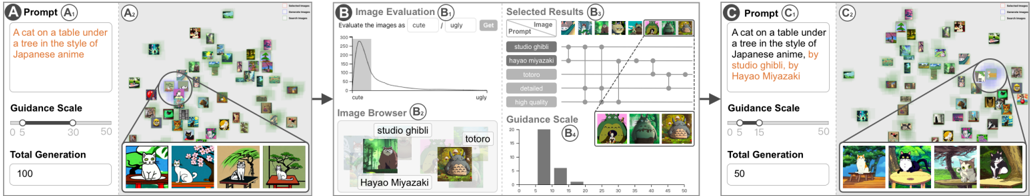
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“recent text-to-image generation systems that generate multiple images for exploration focus on helping users refine their prompts to find the image that fits their desired quality or characteristics [11, 26].”
From Luminate: Structured Generation and Exploration of Design Space with Large Language Models for Human-AI Co-Creation (2024) · cites this paper as [26]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
A Unified Approach to Interpreting Model Predictions
Lundberg, S., & Lee, S.-I. (2017) · arXiv · doi:10.48550/arxiv.1705.07874 · Cited by 23,707
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
High-Resolution Image Synthesis with Latent Diffusion Models
Rombach, R., Blattmann, A., Lorenz, D., Esser, P., & Ommer, B. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.01042 · Cited by 20,302
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Denoising Diffusion Probabilistic Models
Ho, J., Jain, A., & Abbeel, P. (2020) · arXiv · doi:10.48550/arxiv.2006.11239 · Cited by 8,712
Adding Conditional Control to Text-to-Image Diffusion Models
Zhang, L., Rao, A., & Agrawala, M. (2023) · 2023 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00355 · Cited by 4,547
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
The Power of Scale for Parameter-Efficient Prompt Tuning
Lester, B., Al-Rfou, R., & Constant, N. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.243 · Cited by 3,096
Research works printed but not linked: 60
- 10.1109/tvcg.2022.3209425 · DOI
- 10.1109/tvcg.2006.187 · DOI
- Chambon, 2022, Adapting pretrained vision-language foundational models to medical imaging domains, arXiv
- 10.1109/tvcg.2021.3138933 · DOI
- 10.1145/3491102.3517485 · DOI
- 10.1109/cvprw53098.2021.00054 · DOI
- 10.1007/s12650-021-00780-0 · DOI
- 10.1109/tvcg.2023.3240003 · DOI
- 10.1145/2807442.2807478 · DOI
- Hao, 2022, Optimizing prompts for text-to-image generation, arXiv
- 10.1109/TVCG.2023.3326586 · DOI
- Ho, 2022, Imagen video: High definition video generation with diffusion models, arXiv
- Liang, 2022, Multiviz: Towards visualizing and understanding multimodal models
- 10.1109/tvcg.2020.3030370 · DOI
- 10.1145/3526113.3545621 · DOI · Paper page
- 10.1186/1471-2105-13-275 · DOI
- 10.3115/1118108.1118117 · DOI
- Luca, 2019, Multi-level tree based approach for interactive graph visualization with semantic zoom, arXiv
- 10.1109/tvcg.2021.3114876 · DOI
- 10.1016/j.cviu.2016.12.009 · DOI
- MacQueen, Classification and analysis of multivariate observations, 281
- 10.1109/mra.2012.2192811 · DOI · Paper page
- Nichol, Glide: Towards photorealistic image generation and editing with text-guided diffusion models, 162, 16784
- 2023, GPT-4 technical report, arXiv, 2303
- Oppenlaender, 2022, Prompt engineering for text-based generative art, arXiv
- 10.1080/0144929x.2023.2286532 · DOI
- 10.1145/3588432.3591500 · DOI
- 10.1007/978-3-030-01216-8_36 · DOI
- 10.1145/166117.166125 · DOI
- 10.18653/v1/2021.naacl-main.208 · DOI · Paper page
- 10.18653/v1/2021.naacl-main.185 · DOI · Paper page
- 10.18653/v1/2020.emnlp-main.346 · DOI · Paper page
- Song, 2021, Denoising diffusion implicit models
- 10.1108/00220410410560573 · DOI
- 10.1109/mcg.2020.2986902 · DOI
- Van der Maaten, 2008, Visualizing data using t-sne, Journal of machine learning research, 9
- 10.1609/aaai.v37i2.25353 · DOI
- Wang, 2022, Interactive data analysis with next-step natural language query recommendation, arXiv
- 10.1109/tvcg.2021.3114794 · DOI
- 10.1007/s11704-023-2691-y · DOI
- 10.18653/v1/2023.acl-long.51 · DOI
- Weng, 2023, Towards an understanding and explanation for mixed-initiative artificial scientific text detection, arXiv
- 10.1109/tvcg.2023.3245609 · DOI
- 10.1145/3491101.3519729 · DOI · Paper page
- 10.1145/3491102.3517582 · DOI
- 10.1109/tvcg.2022.3209423 · DOI
- 10.1109/TVCG.2018.2835485 · DOI
- 10.1109/VAST.2006.261425 · DOI
- 10.1109/tvcg.2021.3128157 · DOI
- 10.1109/cvpr.2012.6247789 · DOI
- 10.1109/tvcg.2022.3169175 · DOI
- 10.1109/tvcg.2019.2934656 · DOI
- 10.1109/iccv.2017.629 · DOI · Paper page
- 10.1109/tip.2011.2109730 · DOI
- Zhang, 2023, Scrolltimes: Tracing the provenance of paintings as a window into history, arXiv
- 10.1109/tvcg.2022.3209483 · DOI
- Zhang, 2023, Computational approaches for traditional chinese painting: From the “six principles of painting” perspective, arXiv
- 10.1109/tvcg.2022.3209391 · DOI
- 10.1016/j.visinf.2021.06.002 · DOI
- 10.1109/cvpr.2019.00595 · DOI
Cited by
Sorted by citations
Suh, S., Chen, M., Min, B., Li, T. J.-J., & Xia, H. (2024) · Proceedings of the CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642400 · Cited by 148
PromptCharm: Text-to-Image Generation through Multi-modal Prompting and Refinement
Wang, Z., Huang, Y., Song, D., Ma, L., & Zhang, T. (2024) · Proceedings of the CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642803 · Cited by 115
Liu, M., Zhang, L. J., & Zhang, D. (2025) · Computers in Human Behavior · doi:10.1016/j.chb.2025.108569 · Cited by 43
Metadata
- Authors
- Feng, Y., Wang, X., Wong, K. K., Wang, S., Lu, Y., Zhu, M., Wang, B., & Chen, W.
- Affiliations
- State Key Lab of CAD&CG, Zhejiang University, China
- Hong Kong University of Science and Technology, Hong Kong
- Zhejiang University, China
- Venue
- IEEE Transactions on Visualization and Computer Graphics
- Published
- 2023
- Pages
- 1-11
- ISSN
- 1077-2626
- 1941-0506
- 2160-9306
- Cited by
- 124
- References
- 23
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: PromptMagician: Interactive Prompt Engineering for Text-to-Image Creation. https://app.cochat.ai/papers/10.1109/tvcg.2023.3327168
- The paper
- Feng, Y., Wang, X., Wong, K. K., Wang, S., Lu, Y., Zhu, M., Wang, B., & Chen, W. (2023). PromptMagician: Interactive Prompt Engineering for Text-to-Image Creation. IEEE Transactions on Visualization and Computer Graphics. https://doi.org/10.1109/tvcg.2023.3327168
