

DocTer: documentation-guided fuzzing for testing deep learning API functions
Open accessThe DOI matches its Crossref record; 53 of the 54 references it cites were found in a registry or an index.
Abstract
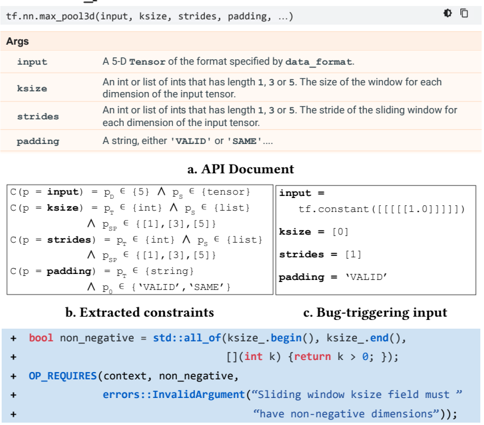
Input constraints are useful for many software development tasks. For example, input constraints of a function enable the generation of valid inputs, i.e., inputs that follow these constraints, to test the function deeper. API functions of deep learning (DL) libraries have DL-specific input constraints, which are described informally in the free-form API documentation. Existing constraint-extraction techniques are ineffective for extracting DL-specific input constraints.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“We include both PyTorch (v1.12) [57] and TensorFlow (v2.10) [66], since they are two of the most popular DL libraries and are widely studied in prior DL library testing work [70,72,77].”
From Large Language Models Are Zero-Shot Fuzzers: Fuzzing Deep-Learning Libraries via Large Language Models (2023) · cites this paper as [77]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Scikit-learn: Machine Learning in Python
Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Müller, A., Nothman, J., Louppe, G., et al. (2012) · arXiv · doi:10.48550/arxiv.1201.0490 · Cited by 71,016
PyTorch: An Imperative Style, High-Performance Deep Learning Library
Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., et al. (2019) · arXiv · doi:10.48550/arxiv.1912.01703 · Cited by 31,473 · cited 3×
“, TensorFlow [14] and PyTorch [39]) is crucial because these libraries are widely used and contain software bugs [26, 27, 42, 58, 59], which hurt not only the development but also the accuracy and speed of the DL models.”
BackgroundMethodTensorFlow: A system for large-scale machine learning
Abadi, M., Barham, P., Chen, J., Chen, Z., Davis, A., Dean, J., Devin, M., Ghemawat, S., Irving, G., Isard, M., et al. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1605.08695 · Cited by 11,822
Scikit-learn: Machine Learning in Python
(2011) · Journal of Machine Learning Research · doi:10.5555/1953048.2078195 · Cited by 8,539
The Stanford CoreNLP Natural Language Processing Toolkit
Manning, C., Surdeanu, M., Bauer, J., Finkel, J., Bethard, S., & McClosky, D. (2014) · Proceedings of 52nd Annual Meeting of the Association for Computational Linguistics: System Demonstrations · doi:10.3115/v1/p14-5010 · Cited by 7,037 · cited 2×
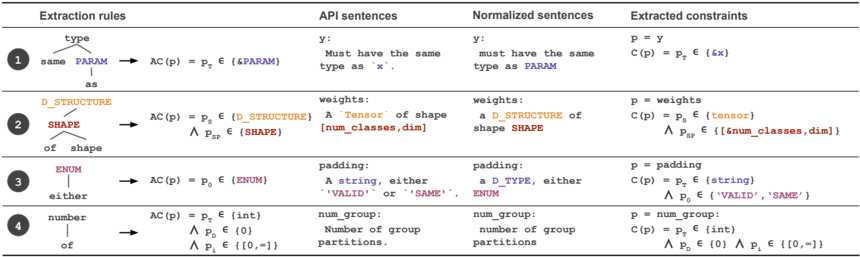
“Dependency tree parsing: Once the sentences are normalized, they are fed to the dependency tree parser [33], which conducts POSTagging and builds tree structure relationships (i.”
BackgroundMethodNatural language processing with Python
Bird, S., Klein, E., & Loper, E. (2009) · CERN Document Server (European Organization for Nuclear Research) · Cited by 3,955
MXNet: A Flexible and Efficient Machine Learning Library for Heterogeneous Distributed Systems
Chen, T., Li, M., Li, Y., Lin, M., Wang, N., Wang, M., Xiao, T., Xu, B., Zhang, C., & Zhang, Z. (2015) · arXiv · doi:10.48550/arxiv.1512.01274 · Cited by 1,819 · cited 1×
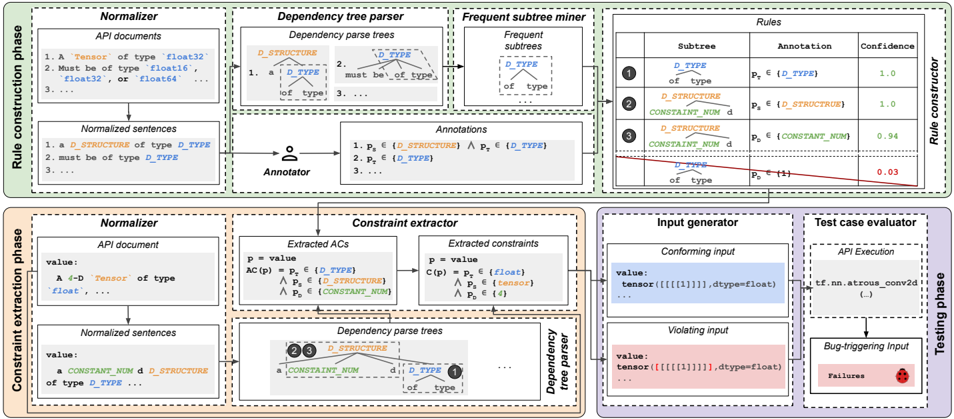
“• A document-analysis technique that extracts 16,035 constraints automatically from API documentation with the focus on four categories of input properties in DL APIs: structure, dtype, shape, and valid values for 2,415 API functions across the three widelyusedDL libraries, TensorFlow [14], PyTorch [39], andMXNet [17].”
MethodSelf-citationStatic Analysis of Shape in TensorFlow Programs
The Theano Development Team, Al‐Rfou, R., Alain, G., Almahairi, A., Angermueller, C., Bahdanau, D., Ballas, N., Bastien, F., Bayer, J., Belikov, A., et al. (2016) · arXiv (Cornell University) · doi:10.4230/lipics.ecoop.2020.15 · Cited by 1,589
Fraser, G., & Arcuri, A. (2013) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2012.14 · Cited by 586 · cited 1×
“Existing test-generation tools [3, 5, 9, 19, 37, 44] such as AFL [3] and libFuzzer [5] have no knowledge of such input constraints, thus are very limited in testing DL API functions.”
MethodRandoop: feedback-directed random testing for Java
Pacheco, C., & Ernst, M. D. (2007) · Companion to the 22nd ACM SIGPLAN conference on Object-oriented programming systems and applications companion · doi:10.1145/1297846.1297902 · Cited by 558
Cited by
Software Testing With Large Language Models: Survey, Landscape, and Vision
Wang, J., Huang, Y., Chen, C., Liu, Z., Wang, S., & Wang, Q. (2024) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2024.3368208 · Cited by 573
“Traditional techniques with API-level fuzzing [139], [140] or model-level fuzzing [141], [142] suffer from the following limitations: 1) lack of diverse API sequence thus cannot reveal bugs caused by chained API sequences; 2) cannot generate arbitrary code thus cannot explore the huge search space…”
Deng, Y., Xia, C. S., Peng, H., Yang, C., & Zhang, L. (2023) · Proceedings of the 32nd ACM SIGSOFT International Symposium on Software Testing and Analysis · doi:10.1145/3597926.3598067 · Cited by 326
“While it is not explicitly stated in the documentation, the developers commented on the issue report that because the CPU and GPU use different lower-level shifting operators, the output result when shifting with negative values will be dependent on the implementation.”
MethodInfluentialDeng, Y., Xia, C. S., Yang, C., Zhang, S. D., Yang, S., & Zhang, L. (2024) · Proceedings of the IEEE/ACM 46th International Conference on Software Engineering · doi:10.1145/3597503.3623343 · Cited by 115
Unifying the Perspectives of NLP and Software Engineering: A Survey on Language Models for Code
Zhang, Z., Chen, C., Liu, B., Liao, C., Gong, Z., Yu, H., Li, J., & Wang, R. (2024) · Transactions on machine learning research · doi:10.13140/rg.2.2.32710.69440/1 · Cited by 194
WhiteFox: White-Box Compiler Fuzzing Empowered by Large Language Models
Yang, C., Deng, Y., Lu, R., Yao, J., Liu, J., Jabbarvand, R., & Zhang, L. (2024) · Proceedings of the ACM on Programming Languages · doi:10.1145/3689736 · Cited by 82
Metadata
- Authors
- Xie, D., Li, Y., Kim, M., Pham, H. V., Tan, L., Zhang, X., & Godfrey, M. W.
- Affiliations
- Purdue University West Lafayette (US)
- University of Waterloo (CA)
- Ulsan National Institute of Science and Technology (KR)
- Venue
- Proceedings of the 31st ACM SIGSOFT International Symposium on Software Testing and Analysis
- Publisher
- ACM
- Published
- 2022-07-18
- Pages
- 176-188
- OpenAlex
- W4285490440
- Cited by
- 81
- References
- 54
- Citations by year
- 2026: 14 · 2025: 27 · 2024: 23 · 2023: 15 · 2022: 2
- FWCI
- 12.63
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- ACM SIGSOFT International Symposium on Software Testing and Analysis (ISSTA) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- Scholarworks@UNIST (Ulsan National Institute of Science and Technology) (submittedVersion)
- arXiv (Cornell University)
- Funders
- National Science Foundation (1901242)
- Topics
- Physical Sciences › Computer Science › Software › Software Testing and Debugging Techniques
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Physical Sciences › Computer Science › Information Systems › Software Engineering Techniques and Practices
- Keywords
- deep learning libraries, API testing, input constraints, constraint extraction, API documentation, software testing
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
