

The DOI matches its Crossref record; 46 of the 48 references it cites were found in a registry or an index.
Large Language Models for Test-Free Fault Localization
Open accessAbstract
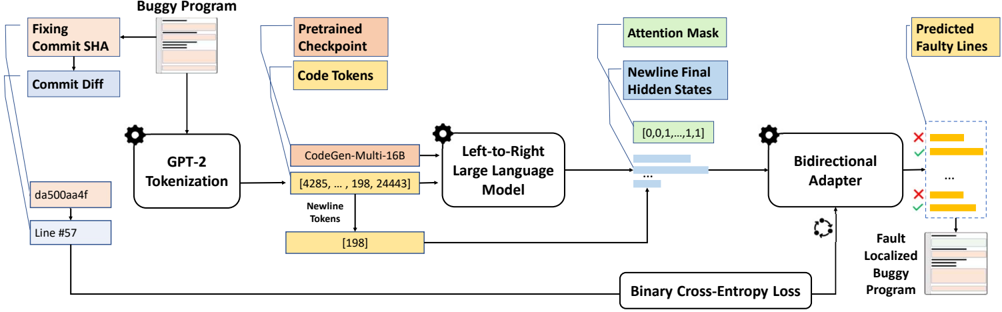
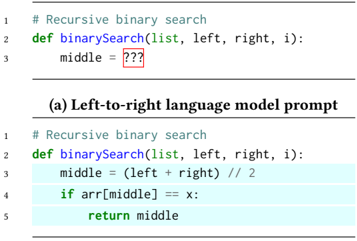
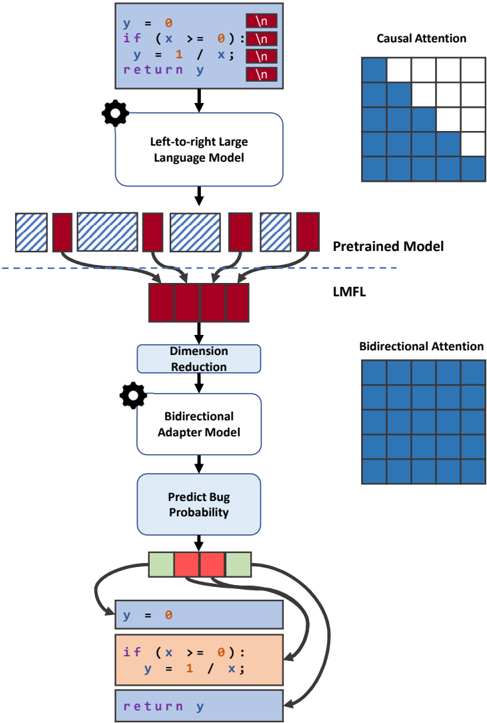
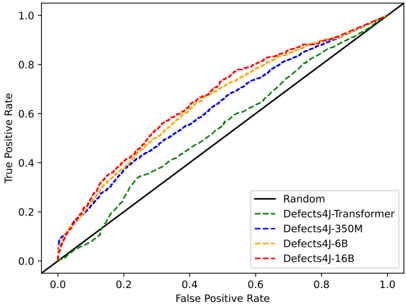
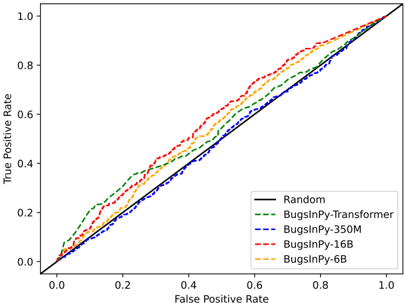
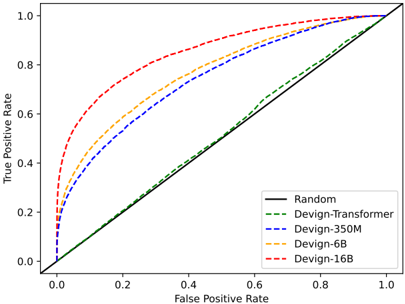
Fault Localization (FL) aims to automatically localize buggy lines of code, a key first step in many manual and automatic debugging tasks. Previous FL techniques assume the provision of input tests, and often require extensive program analysis, program instrumentation, or data preprocessing. Prior work on deep learning for APR struggles to learn from small datasets and produces limited results on real-world programs. Inspired by the ability of large language models (LLMs) of code to adapt to new tasks based on very few examples, we investigate the applicability of LLMs to line level fault localization. Specifically, we propose to overcome the left-to-right nature of LLMs by fine-tuning a small set of bidirectional adapter layers on top of the representations learned by LLMs to produce LLMAO, the first language model based fault localization approach that locates buggy lines of code without any test coverage information. We fine-tune LLMs with 350 million, 6 billion, and 16 billion parameters on small, manually curated corpora of buggy programs such as the Defects4J corpus. We observe that our technique achieves substantially more confidence in fault localization when built on the larger models, with bug localization performance scaling consistently with the LLM size. Our empirical evaluation shows that LLMAO improves the Top-1 results over the state-of-the-art machine learning fault localization (MLFL) baselines by 2.3%--54.4%, and Top-5 results by 14.4%-35.6%. LLMAO is also the first FL technique trained using a language model architecture that can detect security vulnerabilities down to the code line level.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Meanwhile, most such LLM-based techniques either cannot perform repository-level FL due to the limited context window of LLMs [98], or rely on complicated/costly agentic design to navigate through the codebase [48, 79].”
From Agentless: Demystifying LLM-based Software Engineering Agents (2024) · cites this paper as [98]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“We use SWE-bench because it unites many separate SE tasks, such as automated program repair [10, 40, 55], bug localization [4, 58], and testing [22, 46, 56] under a single task formulation that faithfully mirrors practical SE.”
From SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering (2024) · cites this paper as [58]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155
The graph neural network model
Scarselli, F., Gori, M., Tsoi, A. C., Hagenbuchner, M., & Monfardini, G. (2009) · IEEE Transactions on Neural Networks · doi:10.1109/tnn.2008.2005605 · Cited by 9,582
Scaling Laws for Neural Language Models
Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., & Amodei, D. (2020) · arXiv · doi:10.48550/arxiv.2001.08361 · Cited by 9,550 · cited 1×
“A key property of LLMs is that their performance improves consistently with the scale of their computational budget [16], which is itself a function of the model and training data size.”
BackgroundLearning long-term dependencies with gradient descent is difficult
Bengio, Y., Simard, P., & Frasconi, P. (1994) · IEEE Transactions on Neural Networks · doi:10.1109/72.279181 · Cited by 8,542
A Neural Probabilistic Language Model
Bengio, Y., Ducharme, R., Vincent, P., Jauvin, C., Jaz, K., Hofmann, T., Poggio, T., & Shawe-Taylor, J. S. (2000) · Cited by 3,451
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Bubeck, S., Chandrasekaran, V., Eldan, R., Gehrke, J., Horvitz, E., Kamar, E., Lee, P., Lee, Y. T., Li, Y., Lundberg, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.12712 · Cited by 1,526
Defects4J: a database of existing faults to enable controlled testing studies for Java programs
Just, R., Jalali, D., & Ernst, M. D. (2014) · Proceedings of the 2014 International Symposium on Software Testing and Analysis · doi:10.1145/2610384.2628055 · Cited by 1,447
Empirical evaluation of the tarantula automatic fault-localization technique
Jones, J. A., & Harrold, M. J. (2005) · IEEE/ACM International Conference on Automated Software Engineering (ASE) · doi:10.1145/1101908.1101949 · Cited by 1,274
Deep Learning Based Vulnerability Detection: Are We There Yet?
Chakraborty, S., Krishna, R., Ding, Y., & Ray, B. (2021) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2021.3087402 · Cited by 970
Research works printed but not linked: 5
- L. Tunstall, L. Von Werra, and T. Wolf, Natural language processing with transformers. O'Reilly Media, Inc., 2022.
- B. Ray, V. Hellendoorn, S. Godhane, Z. Tu, A. Bacchelli, and P. Devanbu, "On the" naturalness" of buggy code," in Proceedings of the 38th International Conference on Software Engineering, pp. 428--439, 2016.
- L. Gao, S. Biderman, S. Black, L. Golding, T. Hoppe, C. Foster, J. Phang, H. He, A. Thite, N. Nabeshima, et al., "The pile: An 800gb dataset of diverse text for language modeling," arXiv preprint arXiv:2101.00027, 2020. · arXiv
- P. S. Kochhar, X. Xia, D. Lo, and S. Li, "Practitioners' expectations on automated fault localization," in Proceedings of the 25th International Symposium on Software Testing and Analysis, pp. 165--176, 2016.
- H. Pearce, B. Ahmad, B. Tan, B. Dolan-Gavitt, and R. Karri, "An empirical cyber-security evaluation of github copilot's code contributions," ArXiv abs/2108.09293, 2021. · arXiv
Cited by
Sorted by citations
Large Language Models for Software Engineering: A Systematic Literature Review
Hou, X., Zhao, Y., Liu, Y., Yang, Z., Wang, K., Li, L., Luo, X., Lo, D., Grundy, J., & Wang, H. (2024) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3695988 · Cited by 1,029
Software Testing With Large Language Models: Survey, Landscape, and Vision
Wang, J., Huang, Y., Chen, C., Liu, Z., Wang, S., & Wang, Q. (2024) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2024.3368208 · Cited by 573
SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering
Yang, J., Jimenez, C., Wettig, A., Lieret, K., Yao, S., Narasimhan, K., & Press, O. (2024) · Advances in Neural Information Processing Systems 37 · doi:10.52202/079017-1601 · Cited by 264
When LLMs meet cybersecurity: a systematic literature review
Zhang, J., Bu, H., Wen, H., Liu, Y., Fei, H., Xi, R., Li, L., Yang, Y., Zhu, H., & Meng, D. (2025) · Cybersecurity · doi:10.1186/s42400-025-00361-w · Cited by 383
“Thereby, the model can understand and perform cybersecurity-related tasks, such as automated threat detection, vulnerability identification, and security policy recommendations.”
A Review on Edge Large Language Models: Design, Execution, and Applications
Zheng, Y., Chen, Y., Qian, B., Shi, X., Shu, Y., & Chen, J. (2025) · ACM Computing Surveys · doi:10.1145/3719664 · Cited by 169
Metadata
- Authors
- Yang, A. Z. H., Le Goues, C., Martins, R., & Hellendoorn, V.
- Affiliations
- Carnegie Mellon University (US)
- Carnegie Mellon University, Pittsburgh, Pennsylvania, USA
- Venue
- Proceedings of the IEEE/ACM 46th International Conference on Software Engineering
- Publisher
- ACM
- Published
- 2024-02-06
- Pages
- 1-12
- ISSN
- 0270-5257 (ISSN-L)
- OpenAlex
- W4391579639
- Cited by
- 144
- References
- 48
- Citations by year
- 2026: 53 · 2025: 64 · 2024: 27
- FWCI
- 39.31
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- ACM/IEEE International Conference on Software Engineering: Companion Proceedings (ICSE-Companion) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- NSF (National Science Foundation) (CCF-1750116)
- National Science Foundation (CCF-1762363)
- Topics
- Physical Sciences › Computer Science › Software › Software Testing and Debugging Techniques
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Physical Sciences › Computer Science › Computer Networks and Communications › Software System Performance and Reliability
- Keywords
- large language models, LLM fine-tuning, Defects4J, vulnerability detection, automated program repair
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
