

The DOI matches its Crossref record; 29 of the 30 references it cites were found in a registry or an index, and 1 are not checked yet.
Performance of an Open-Source Large Language Model in Extracting Information from Free-Text Radiology Reports
Open accessAbstract
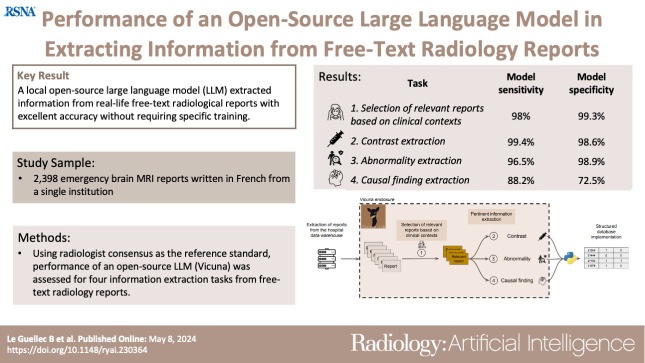
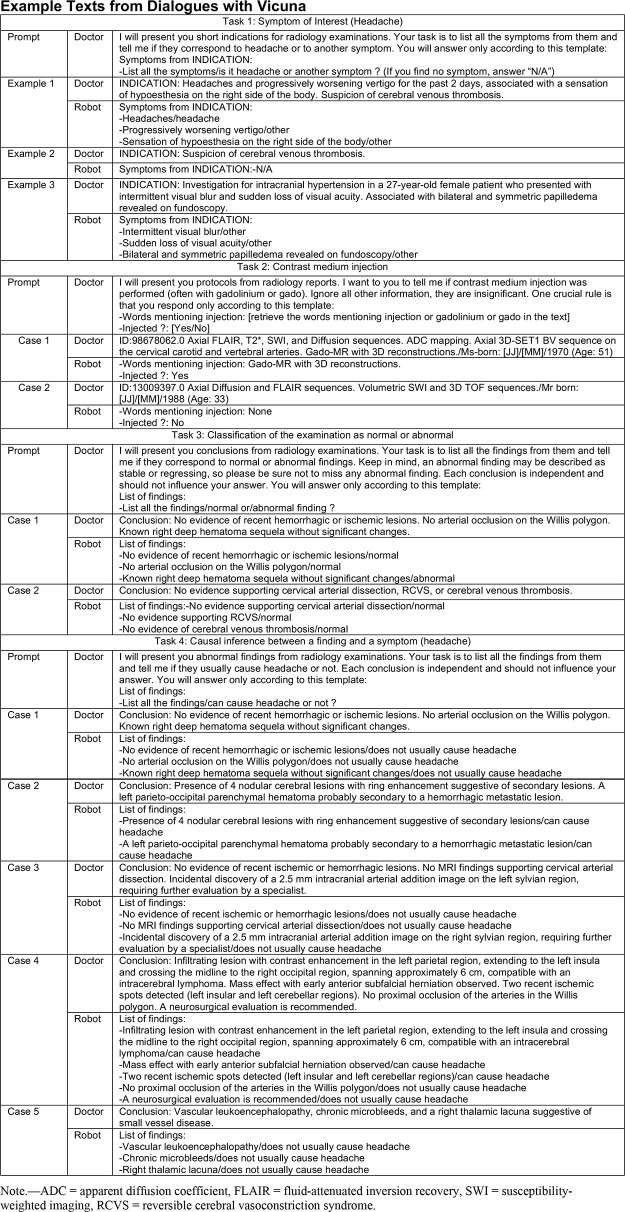
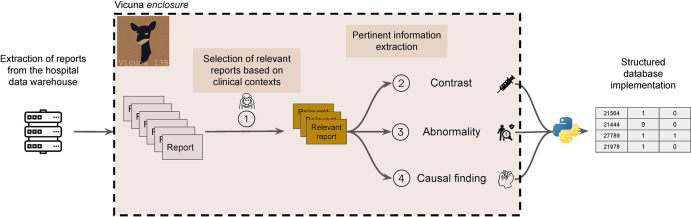
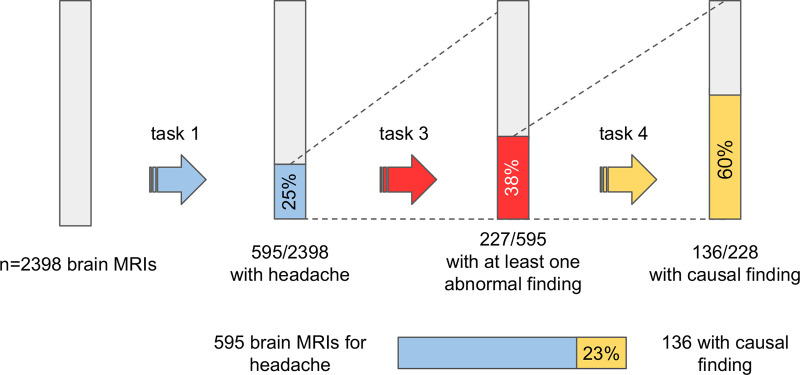
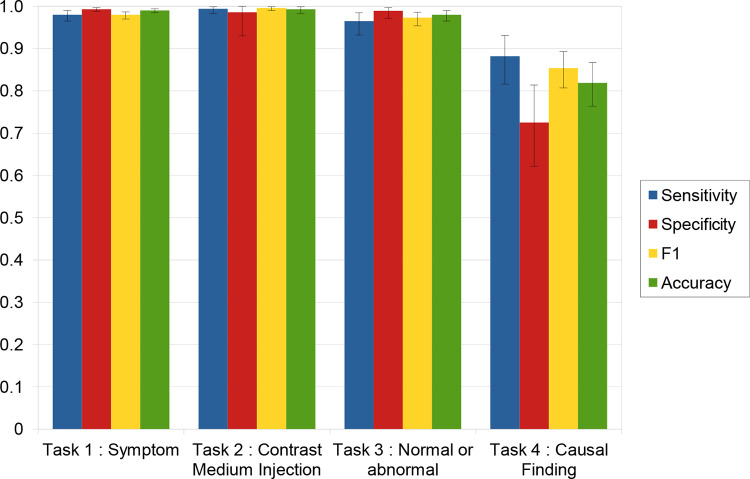
“Just Accepted” papers have undergone full peer review and have been accepted for publication in Radiology: Artificial Intelligence. This article will undergo copyediting, layout, and proof review before it is published in its final version. Please note that during production of the final copyedited article, errors may be discovered which could affect the content. Purpose To assess the performance of a local open-source large language model (LLM) on various information extraction tasks from real-life emergency brain MRI reports. Materials and Methods All consecutive emergency brain MRI reports written in 2022 from a French quaternary center were retrospectively reviewed. Two radiologists identified MRIs that were performed for headaches. Four radiologists scored reports' conclusions as normal or abnormal. Abnormalities were labeled as either headache-causing or incidental. Vicuna, an open-source LLM, performed the same tasks. Vicuna’s performance metrics were evaluated using the radiologists’ consensus as the reference standard. Results Among the 2398 reports during the study period, radiologists identified 595 that included headaches in their indication (median age of patients, 35 years [IQR, 26–51], 68% (403/595) female). A positive finding was reported in 227/595 (38%) cases, 136 of which could explain the headache. The LLM had a sensitivity/specificity (95%CI), respectively, of 98% (583/595)(97–99)/99% (1791/1803)(99–100) for detecting the presence of headache in the clinical context, 99% (514/517)(98–100)/99% (68/69)(92–100) for the use of contrast medium injection, 97% (219/227)(93–99)/99% (364/368)(97–100) for study categorization as normal or abnormal and 88% (120/136)(82– 93)/73% (66/91)(62–81) for causal inference between MRI findings and headache. Conclusion An open-source LLM was able to extract information from free-text radiology reports with excellent accuracy without requiring further training. ©RSNA, 2024
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Most studies applying LLM on clinical notes have been conducted in the US without individual consent, using de-identified data, with only one study from France utilising retrospective MRI reports without identifiable data [5, 6, 13, 14, 17–20].”
From A pilot feasibility study comparing large language models in extracting key information from ICU patient text records from an Irish population (2024) · cites this paper as [20]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Benefits, Limits, and Risks of GPT-4 as an AI Chatbot for Medicine
Lee, P., Bubeck, S., & Petro, J. (2023) · New England Journal of Medicine · doi:10.1056/nejmsr2214184 · Cited by 1,738
Buderer, N. M. F. (1996) · Academic Emergency Medicine · doi:10.1111/j.1553-2712.1996.tb03538.x · Cited by 912
Explainability for Large Language Models: A Survey
Zhao, H., Chen, H., Yang, F., Liu, N., Deng, H., Cai, H., Wang, S., Yin, D., & Du, M. (2024) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3639372 · Cited by 681
Natural language processing in radiology: a systematic review
Pons, E., Braun, L. M. M., Hunink, M. G. M., & Kors, J. A. (2016) · Radiology · doi:10.1148/radiol.16142770 · Cited by 573
Bhayana, R., Krishna, S., & Bleakney, R. R. (2023) · Radiology · doi:10.1148/radiol.230582 · Cited by 460
Emergent analogical reasoning in large language models
Webb, T., Holyoak, K. J., & Lu, H. (2023) · Nature Human Behaviour · doi:10.1038/s41562-023-01659-w · Cited by 404
Adams, L. C., Truhn, D., Busch, F., Kader, A., Niehues, S. M., Makowski, M. R., & Bressem, K. K. (2023) · Radiology · doi:10.1148/radiol.230725 · Cited by 339
Ethics of large language models in medicine and medical research
Li, H., Moon, J. T., Purkayastha, S., Celi, L. A., Trivedi, H., & Gichoya, J. W. (2023) · The Lancet Digital Health · doi:10.1016/s2589-7500(23)00083-3 · Cited by 286
Research works printed but not linked: 1
- Budweg J, 2016, Swiss Med Wkly, 146, w14349
Cited by
Sorted by citations
Large Language Models and Large Multimodal Models in Medical Imaging: A Primer for Physicians
Bradshaw, T., Tie, X., Warner, J., Hu, J., Li, Q., & Li, X. (2025) · Journal of Nuclear Medicine · doi:10.2967/jnumed.124.268072 · Cited by 60
Comprehensive testing of large language models for extraction of structured data in pathology
Grothey, B., Odenkirchen, J., Brkic, A., Schömig-Markiefka, B., Quaas, A., Büttner, R., & Tolkach, Y. (2025) · Communications Medicine · doi:10.1038/s43856-025-00808-8 · Cited by 54
Salam, B., Stüwe, C., Nowak, S., Sprinkart, A. M., Theis, M., Kravchenko, D., Mesropyan, N., Dell, T., Endler, C., Pieper, C. C., et al. (2025) · European Radiology · doi:10.1007/s00330-025-11438-y · Cited by 43
Benchmarking the diagnostic performance of open source LLMs in 1933 Eurorad case reports
Kim, S. H., Schramm, S., Adams, L. C., Braren, R., Bressem, K. K., Keicher, M., Platzek, P., Paprottka, K. J., Zimmer, C., Hedderich, D. M., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01488-3 · Cited by 44
Lee, J. E., Park, K. S., Kim, Y., Song, H.-C., Park, B., & Jeong, Y. J. (2024) · American Journal of Roentgenology · doi:10.2214/ajr.24.31696 · Cited by 41
Metadata
- Authors
- Le Guellec, B., Lefèvre, A., Geay, C., Shorten, L., Bruge, C., Hacein-Bey, L., Amouyel, P., Pruvo, J.-P., Kuchcinski, G., & Hamroun, A.
- Affiliations
- Inserm (FR)
- ORCID
- Venue
- Radiology: Artificial Intelligence
- Published
- 2024-07-01
- Volume
- 6
- Issue
- 4
- Pages
- e230364-e230364
- ISSN
- 2638-6100 (ISSN-L)
- PMC
- PMC11294959
- OpenAlex
- W4396722287
- Cited by
- 115
- References
- 28
- Citations by year
- 2026: 42 · 2025: 60 · 2024: 12
- FWCI
- 10.66
- Type
- journal article
- Language
- en
- Open access
- green
- www.ncbi.nlm.nih.gov
- Licence
- cc-by
- Locations
- Radiology Artificial Intelligence (publishedVersion)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- HAL (submittedVersion, cc-by)
- eScholarship (California Digital Library) (submittedVersion, cc-by)
- LillOA (Université de Lille (University Of Lille)) (submittedVersion)
- LillOA (Université de Lille (University Of Lille)) (submittedVersion, other-oa)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- open-source large language models, vicuña, headache, contrast medium injection, incidental finding, radiologist consensus, local LLM deployment, radiology education, radiology workforce shortage
- MeSH terms
- Adult, Brain, Emergency Service, Hospital, Female, Headache, Humans, Magnetic Resonance Imaging, Male, Middle Aged, Natural Language Processing, Retrospective Studies, Sensitivity and Specificity
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
