

Measuring Attribution in Natural Language Generation Models
Open accessThe DOI matches its Crossref record; 48 of the 48 references it cites were found in a registry or an index.
Abstract
Large neural models have brought a new challenge to natural language generation (NLG): It has become imperative to ensure the safety and reliability of the output of models that generate freely. To this end, we present an evaluation framework, Attributable to Identified Sources (AIS), stipulating that NLG output pertaining to the external world is to be verified against an independent, provided source. We define AIS and a two-stage annotation pipeline for allowing annotators to evaluate model output according to annotation guidelines. We successfully validate this approach on generation datasets spanning three tasks (two conversational QA datasets, a summarization dataset, and a table-to-text dataset). We provide full annotation guidelines in the appendices and publicly release the annotated data at https://github.com/google-research-datasets/AIS.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures

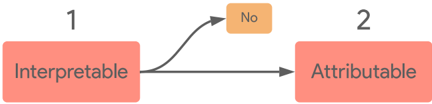


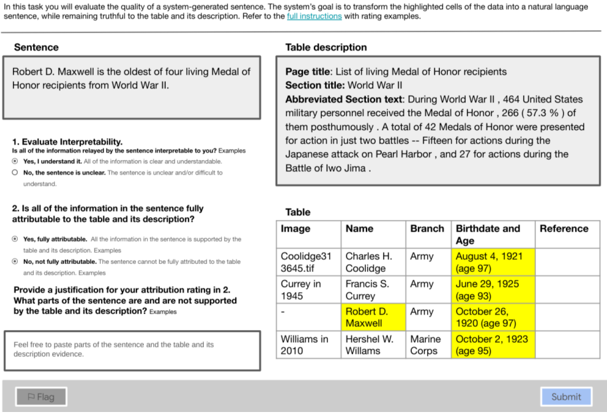
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Rashkin et al. propose23 and formalize a framework called Attributable to Identifiable Sources, which defines the AIS score of a given language model’s response”
From An automated framework for assessing how well LLMs cite relevant medical references (2025) · cites this paper as [23]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Citation-grade attribution requires locatable evidence: a reader must be able to retrieve and check the cited source (Rashkin et al., 2023;Bohnet et al., 2022).”
From The Attribution-Compression Frontier in Retrieval-Augmented Generation (2026) · cites this paper as Rashkin et al., 2023
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“The AIS framework evaluates whether statements are supported by identified sources (Rashkin et al., 2023).”
From The Attribution-Compression Frontier in Retrieval-Augmented Generation (2026) · cites this paper as Rashkin et al., 2023
In the citing paper
“Compliance with stringent legal standards within applicable jurisdictions, such as the General Data Protection Regulation (GDPR) and California Consumer Privacy Act (CCPA), is essential, necessitating purpose limitation and data minimization [230], [231], [232].”
From From Google Gemini to OpenAI Q* (Q-Star): A Survey on Reshaping the Generative Artificial Intelligence (AI) Research Landscape (2025) · cites this paper as [230]
In the citing paper
“Rashkin et al. (2023) define the”
From Enabling Large Language Models to Generate Text with Citations (2023) · cites this paper as Rashkin et al. (2023)
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Grice, H. P. (1975) · Speech Acts · doi:10.1163/9789004368811_003 · Cited by 23,221
Advances in neural information processing systems 7
(1996) · Computers & Mathematics with Applications · doi:10.1016/s0898-1221(96)90463-0 · Cited by 14,281
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929 · cited 2×
“…that paper, we also compared with three models that are seq2seq-style conversation models: the original answer generation system from Dinan et al. (2019), the Dodecadialogue multitask system from Shuster et al. (2020) and a T5-base model (Raffel et al., 2020) finetuned on Wizard of Wikipedia data.”
BackgroundGet To The Point: Summarization with Pointer-Generator Networks
See, A., Liu, P. J., & Manning, C. D. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1099 · Cited by 3,775 · cited 1×
“Lastly, we used Pointer-generator Networks from See et al. (2017) — a hybrid approach that is uses an abstractive seq2seq model but with an explicit copy mechanism that can extract information from the source document.”
MethodAbstractive Text Summarization using Sequence-to-sequence RNNs and Beyond
Nallapati, R., Zhou, B., dos Santos, C., Gulcehre, C., & Xiang, B. (2016) · Proceedings of The 20th SIGNLL Conference on Computational Natural Language Learning · doi:10.18653/v1/k16-1028 · Cited by 2,361 · cited 7×
“We observed that the reference summaries in CNN/DM may sometimes refer to external pieces of information that may have accompanied the article (a picture, a headline, etc.) or sometimes make assumptions about what the intended audience of the article might already know that can affect either the interpretability or AI…”
BackgroundMethodInfluentialNatural Questions: A benchmark for question answering research
Kwiatkowski, T., Palomaki, J., Redfield, O., Collins, M., Parikh, A., Alberti, C., Epstein, D., Polosukhin, I., Devlin, J., Lee, K., et al. (2019) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00276 · Cited by 2,069
Self-citationBig Bird: Transformers for Longer Sequences
Zaheer, M., Guruganesh, G., Dubey, A., Ainslie, J., Alberti, C., Ontanon, S., Pham, P., Ravula, A., Wang, Q., Yang, L., et al. (2020) · arXiv · doi:10.48550/arxiv.2007.14062 · Cited by 1,349 · cited 1×
“We also used an abstractive summarization system, BigBird (Zaheer et al., 2020).”
MethodFEVER: a Large-scale Dataset for Fact Extraction and VERification
Thorne, J., Vlachos, A., Christodoulopoulos, C., & Mittal, A. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1074 · Cited by 1,343 · cited 1×
“A related field of study has dealt with the topic of fact or claim verification (Thorne et al., 2018; Thorne and Vlachos, 2018; Thorne et al., 2021, inter alia).”
BackgroundOn Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185 · cited 4×
“Maynez et al. (2020) presented an extensive characterization of hallucinations, discussed behavior of models that generate content that are present in larger corpora beyond a given source and conducted a significant human study.”
BackgroundResultInfluential
Research works printed but not linked: 2
- Carston, 1988, Implicature, explicature, and truth-theoretic semantics, 155
- Wilson, 2004, Relevance theory, 607
Cited by
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
“…generated by large language models are coherent or factually correct, as underscored by the recent work evaluating the factuality of language model generations and explanations (Maynez et al., 2020; Rashkin et al., 2021; Ye and Durrett, 2022; Marasovi ´ c et al., 2022; Wiegreffe et al., 2022).”
HaluEval: A Large-Scale Hallucination Evaluation Benchmark for Large Language Models
Li, J., Cheng, X., Zhao, W. X., Nie, J.-Y., & Wen, J.-R. (2023) · arXiv · doi:10.48550/arxiv.2305.11747 · Cited by 340
“…the utterances generated by dialogue systems into three categories, i.e., fully attributable, not fully attributable, and generic; and the Attributable to Identified Sources (AIS) benchmark (Rashkin et al., 2021) assesses whether the source documents support the output of text generation models.”
BackgroundChain-of-Verification Reduces Hallucination in Large Language Models
Dhuliawala, S., Komeili, M., Xu, J., Raileanu, R., Li, X., Celikyilmaz, A., & Weston, J. (2024) · Findings of the Association for Computational Linguistics ACL 2024 · doi:10.18653/v1/2024.findings-acl.212 · Cited by 282
Huang, L., Yu, W., Ma, W., Zhong, W., Feng, Z., Wang, H., Chen, Q., Peng, W., Feng, X., Qin, B., et al. (2023) · arXiv · doi:10.48550/arxiv.2311.05232 · Cited by 2,516
Enabling Large Language Models to Generate Text with Citations
Gao, T., Yen, H., Yu, J., & Chen, D. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.398 · Cited by 216
Metadata
- Authors
- Rashkin, H., Nikolaev, V., Lamm, M., Aroyo, L., Collins, M., Das, D., Petrov, S., Tomar, G. S., Turc, I., & Reitter, D.
- Affiliations
- Google DeepMind (United Kingdom) (GB)
- Google (United States) (US)
- Storia AI. iulia@iuliaturc.com
- ORCID
- Venue
- Computational Linguistics
- Publisher
- MIT Press
- Published
- 2023
- Volume
- 49
- Issue
- 4
- Pages
- 777-840
- ISSN
- 0891-2017 (ISSN-L)
- 1530-9312
- OpenAlex
- W4381432831
- Cited by
- 71
- References
- 46
- Citations by year
- 2026: 37 · 2025: 20 · 2024: 8 · 2023: 6
- FWCI
- 6.69
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Licence
- Locations
- Computational Linguistics (publishedVersion, cc-by-nc-nd)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Explainable Artificial Intelligence (XAI)
- Keywords
- attribution, natural language generation, evaluation framework, annotation guidelines, annotation pipeline, conversational question answering, summarization, table-to-text generation, model safety
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Measuring Attribution in Natural Language Generation Models. https://app.cochat.ai/papers/10.1162/coli_a_00486
- The paper
- Rashkin, H., Nikolaev, V., Lamm, M., Aroyo, L., Collins, M., Das, D., Petrov, S., Tomar, G. S., Turc, I., & Reitter, D. (2023). Measuring Attribution in Natural Language Generation Models. Computational Linguistics. https://doi.org/10.1162/coli_a_00486
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
