

The DOI matches its Crossref record; 21 of the 21 references it cites were found in a registry or an index.
Evaluating the Ripple Effects of Knowledge Editing in Language Models
Abstract
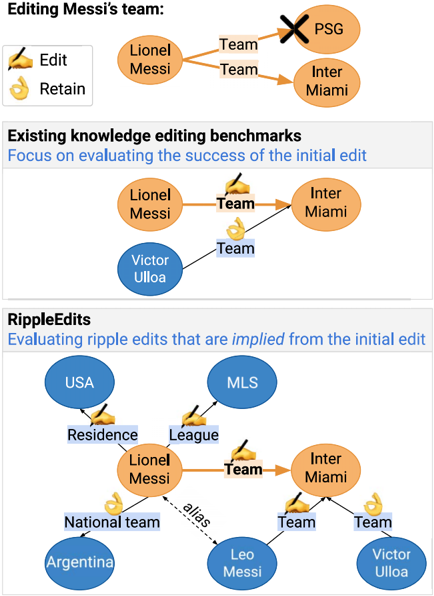
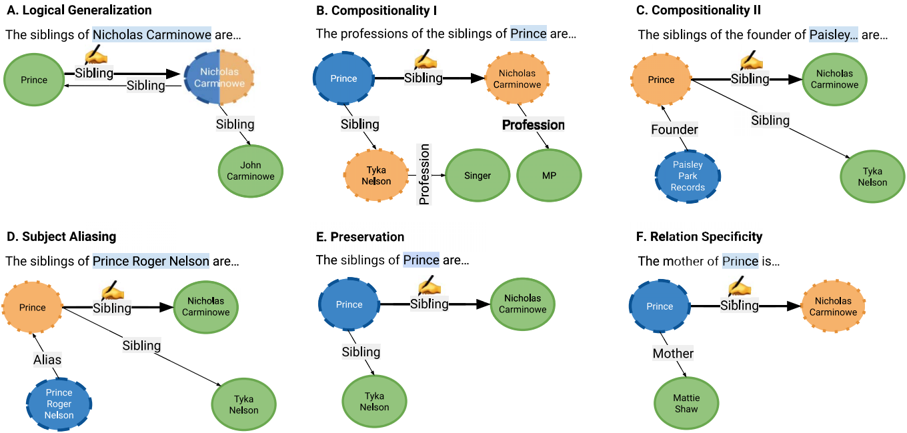
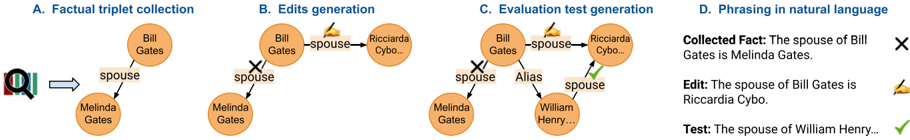
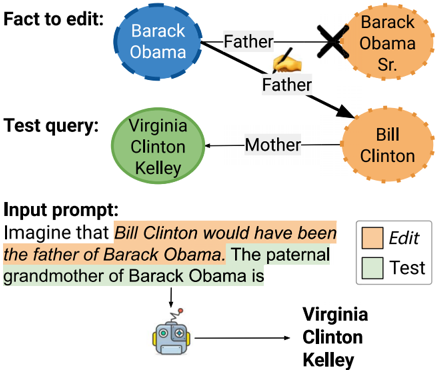
Modern language models capture a large body of factual knowledge. However, some facts can be incorrectly induced or become obsolete over time, resulting in factually incorrect generations. This has led to the development of various editing methods that allow updating facts encoded by the model. Evaluation of these methods has primarily focused on testing whether an individual fact has been successfully injected, and if similar predictions for other subjects have not changed. Here we argue that such evaluation is limited, since injecting one fact (e.g., “Jack Depp is the son of Johnny Depp”) introduces a “ripple effect” in the form of additional facts that the model needs to update (e.g., “Jack Depp is the sibling of Lily-Rose Depp”). To address this, we propose novel evaluation criteria that consider the implications of an edit on related facts. Using these criteria, we then construct RippleEdits, a diagnostic benchmark of 5K factual edits, capturing various types of ripple effects. We evaluate prominent editing methods on RippleEdits, showing that they fail to introduce consistent changes in the model’s knowledge. In addition, we find that a simple in-context editing baseline obtains the best scores on our benchmark, suggesting a promising research direction for model editing.1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Many memory editing benchmarks(Wang et al., 2023d; Cohen et al., 2024; Khandelwal et al., 2024) primarily focus on editing accuracy by constructing datasets designed to evaluate whether models can produce counterfactual responses when queried about specific factual knowledge.”
From The AI Hippocampus: How Far are We From Human Memory? (2026) · cites this paper as Cohen et al., 2024
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2023) · ACM Computing Surveys · doi:10.1145/3560815 · Cited by 4,361
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2021) · arXiv · doi:10.48550/arxiv.2107.13586 · Cited by 4,352
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
Evaluating Large Language Models Trained on Code
Chen, M., Tworek, J., Jun, H., Yuan, Q., Pinto, H. P. D. O., Kaplan, J., Edwards, H., Burda, Y., Joseph, N., Brockman, G., et al. (2021) · arXiv · doi:10.48550/arxiv.2107.03374 · Cited by 1,436
KEPLER: A Unified Model for Knowledge Embedding and Pre-trained Language Representation
Wang, X., Gao, T., Zhu, Z., Zhang, Z., Liu, Z., Li, J., & Tang, J. (2021) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00360 · Cited by 676
Knowledge Enhanced Contextual Word Representations
Peters, M. E., Neumann, M., Logan, R., Schwartz, R., Joshi, V., Singh, S., & Smith, N. A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1005 · Cited by 661
Zero-Shot Relation Extraction via Reading Comprehension
Levy, O., Seo, M., Choi, E., & Zettlemoyer, L. (2017) · arXiv · doi:10.48550/arxiv.1706.04115 · Cited by 482
Research works printed but not linked: 26
- Black, 2022, GPT-NeoX-20B: An open-source autoregressive language model, 95, 10.18653/v1/2022.bigscience-1.9 · DOI
- Cohen, 2023, Crawling the internal knowledge-base of language models, 1856, 10.18653/v1/2023.findings-eacl.139 · DOI
- Dhingra, 2022, Time-aware language models as temporal knowledge bases, Transactions of the Association for Computational Linguistics, 10, 257, 10.1162/tacl_a_00459 · DOI · Paper page
- Genin, 2022, Formal representations of belief
- Geva, 2021, Transformer feed-forward layers are key-value memories, 5484, 10.18653/v1/2021.emnlp-main.446 · DOI · Paper page
- Hase, 2023, Methods for measuring, updating, and visualizing factual beliefs in language models, 2714, 10.18653/v1/2023.eacl-main.199 · DOI
- Heinzerling, 2021, Language models as knowledge bases: On entity representations, storage capacity, and paraphrased queries, 1772, 10.18653/v1/2021.eacl-main.153 · DOI · Paper page
- Hernandez, 2023, Measuring and manipulating knowledge representations in language models, ArXiv preprint
- Hoelscher-Obermaier, 2023, Detecting edit failures in large language models: An improved specificity benchmark, 11548, 10.18653/v1/2023.findings-acl.733 · DOI
- Kassner, 2021, BeliefBank: Adding memory to a pre-trained language model for a systematic notion of belief, 8849, 10.18653/v1/2021.emnlp-main.697 · DOI
- Lewis, 2020, Retrieval- augmented generation for knowledge-intensive NLP tasks
- Meng, 2023, Mass-editing memory in a transformer
- Mitchell, 2022, Fast model editing at scale
- Onoe, 2023, Can LMs learn new entities from descriptions? Challenges in propagating injected knowledge, 5469, 10.18653/v1/2023.acl-long.300 · DOI
- Petroni, 2019, Language models as knowledge bases?, 2463, 10.18653/v1/D19-1250 · DOI · Paper page
- Radford, 2019, Language models are unsupervised multitask learners, OpenAI blog, 1, 9
- Roberts, 2020, How much knowledge can you pack into the parameters of a language model?, 5418, 10.18653/v1/2020.emnlp-main.437 · DOI · Paper page
- Shin, 2020, AutoPrompt: Eliciting knowledge from language models with automatically generated prompts, 4222, 10.18653/v1/2020.emnlp-main.346 · DOI · Paper page
- Si, 2023, Prompting GPT-3 to be reliable
- Wang, 2021, K-Adapter: Infusing knowledge into pre-trained models with adapters, 1405, 10.18653/v1/2021.findings-acl.121 · DOI
- Yao, 2022, Kformer: Knowledge injection in transformer feed-forward layers, 131, 10.1007/978-3-031-17120-8_11 · DOI
- Yao, 2023, Editing large language models: Problems, methods, and opportunities, 10.18653/v1/2023.emnlp-main.632 · DOI
- Zhang, 2021, Drop redundant, shrink irrelevant: Selective knowledge injection for language pretraining, 4007, 10.24963/ijcai.2021/552 · DOI
- Zhang, 2022, Greaselm: Graph reasoning enhanced language models
- Zhang, 2019, ERNIE: Enhanced language representation with informative entities, 1441, 10.18653/v1/P19-1139 · DOI · Paper page
- Zhong, 2023, Mquake: Assessing knowledge editing in language models via multi-hop questions, 10.18653/v1/2023.emnlp-main.971 · DOI
Cited by
Sorted by citations
Unifying Large Language Models and Knowledge Graphs: A Roadmap
Pan, S., Luo, L., Wang, Y., Chen, C., Wang, J., & Wu, X. (2024) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2024.3352100 · Cited by 1,376
From RAG to Memory: Non-Parametric Continual Learning for Large Language Models
Gutiérrez, B. J., Shu, Y., Qi, W., Zhou, S., & Su, Y. (2025) · arXiv · doi:10.48550/arxiv.2502.14802 · Cited by 2
“…memory capabilities have faced significant challenges in both fully absorbing new knowledge (Zhong et al., 2023; Hoelscher-Obermaier et al., 2023) and avoiding catastrophic forgetting (Cohen et al., 2024; Gu et al., 2024), due to the complex distributional nature of their parametric knowledge.”
The AI Hippocampus: How Far are We From Human Memory?
Jia, Z., Li, J., Kang, Y., Wang, Y., Wu, T., Wang, Q., Wang, X., Zhang, S., Shen, J., Li, Q., et al. (2026) · arXiv · doi:10.48550/arxiv.2601.09113
Reason-KE++: Aligning the Process, Not Just the Outcome, for Faithful LLM Knowledge Editing
Wu, Y., Ding, L., Shen, L., & Tao, D. (2025) · arXiv · doi:10.48550/arxiv.2511.12661
Metadata
- Authors
- Cohen, R., Biran, E., Yoran, O., Globerson, A., & Geva, M.
- Affiliations
- Blavatnik School of Computer Science, Tel Aviv University, Israel. roi1@mail.tau.ac.il
- Blavatnik School of Computer Science, Tel Aviv University, Israel. edenbiran@mail.tau.ac.il
- Blavatnik School of Computer Science, Tel Aviv University, Israel. oriy@mail.tau.ac.il
- Blavatnik School of Computer Science, Tel Aviv University, Israel. gamir@tauex.tau.ac.il
- Blavatnik School of Computer Science, Tel Aviv University, Israel. morgeva@tauex.tau.ac.il
- Venue
- Transactions of the Association for Computational Linguistics
- Publisher
- MIT Press
- Published
- 2024
- Volume
- 12
- Pages
- 283-298
- ISSN
- 2307-387X
- Cited by
- 42
- References
- 21
- Language
- en
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
