

The DOI matches its Crossref record; 16 of the 16 references it cites were found in a registry or an index.
Preserving Privacy Through Dememorization: An Unlearning Technique For Mitigating Memorization Risks In Language Models
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
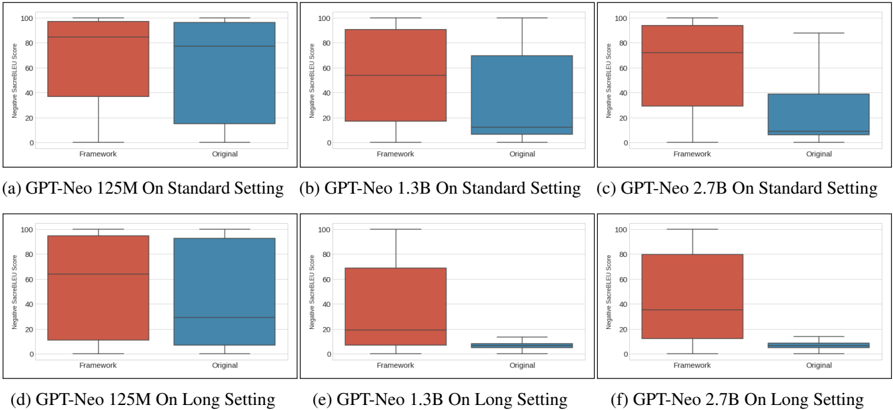
“To address this, Kassem, Mahmoud & Saad (2023) introduced the DeMemorization (DeMem) framework, a model alignment strategy specifically designed to reduce memorisation in LLMs.”
From Generative AI and intellectual property: a systematic literature review of possible issues and mitigations (2026) · cites this paper as Kassem, Mahmoud & Saad (2023)
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Proximal Policy Optimization Algorithms
Schulman, J., Wolski, F., Dhariwal, P., Radford, A., & Klimov, O. (2017) · arXiv · doi:10.48550/arxiv.1707.06347 · Cited by 10,625
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
A Call for Clarity in Reporting BLEU Scores
Post, M. (2018) · Proceedings of the Third Conference on Machine Translation: Research Papers · doi:10.18653/v1/w18-6319 · Cited by 2,112
HellaSwag: Can a Machine Really Finish Your Sentence?
Zellers, R., Holtzman, A., Bisk, Y., Farhadi, A., & Choi, Y. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1472 · Cited by 830
Extracting Training Data from Large Language Models
Carlini, N., Tramer, F., Wallace, E., Jagielski, M., Herbert-Voss, A., Lee, K., Roberts, A., Brown, T., Song, D., Erlingsson, U., et al. (2020) · arXiv · doi:10.48550/arxiv.2012.07805 · Cited by 727
WinoGrande: An Adversarial Winograd Schema Challenge at Scale
Sakaguchi, K., Le Bras, R., Bhagavatula, C., & Choi, Y. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i05.6399 · Cited by 579
Think you have Solved Question Answering? Try ARC, the AI2 Reasoning Challenge
Clark, P., Cowhey, I., Etzioni, O., Khot, T., Sabharwal, A., Schoenick, C., & Tafjord, O. (2018) · arXiv · doi:10.48550/arxiv.1803.05457 · Cited by 462
Research works printed but not linked: 28
- Martin Abadi, Andy Chu, Ian Goodfellow, H Bren- dan McMahan, Ilya Mironov, Kunal Talwar, and Li Zhang. 2016. Deep learning with differential pri- vacy. In Proceedings of the 2016 ACM SIGSAC con- ference on computer and communications security, pages 308-318.
- Aida Amini, Saadia Gabriel, Peter Lin, Rik Koncel- Kedziorski, Yejin Choi, and Hannaneh Hajishirzi. 2019. Mathqa: Towards interpretable math word problem solving with operation-based formalisms. arXiv preprint arXiv:1905.13319. · arXiv
- Priyam Basu, Tiasa Singha Roy, Rakshit Naidu, Zum- rut Muftuoglu, Sahib Singh, and Fatemehsadat Mireshghallah. 2021. Benchmarking differential pri- vacy and federated learning for bert models. arXiv preprint arXiv:2106.13973. · arXiv
- Stella Biderman, Hailey Schoelkopf, Quentin Anthony, Herbie Bradley, Kyle O'Brien, Eric Hallahan, Mo- hammad Aflah Khan, Shivanshu Purohit, USVSN Sai Prashanth, Edward Raff, et al. 2023. Pythia: A suite for analyzing large language models across training and scaling. arXiv preprint arXiv:2304.01373. · arXiv
- Yonatan Bisk, Rowan Zellers, Jianfeng Gao, Yejin Choi, et al. 2020. Piqa: Reasoning about physical com- monsense in natural language. In Proceedings of the AAAI conference on artificial intelligence, volume 34, pages 7432-7439.
- Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, et al. 2022. Gpt-neox-20b: An open-source autoregressive language model. arXiv preprint arXiv:2204.06745. · arXiv
- Hannah Brown, Katherine Lee, Fatemehsadat Mireshghallah, Reza Shokri, and Florian Tramèr. 2022. What does it mean for a language model to preserve privacy? arXiv preprint arXiv:2202.05520. · arXiv
- Aakanksha Chowdhery, Sharan Narang, Jacob Devlin, Maarten Bosma, Gaurav Mishra, Adam Roberts, Paul Barham, Hyung Won Chung, Charles Sutton, Sebastian Gehrmann, et al. 2022. Palm: Scaling language modeling with pathways. arXiv preprint arXiv:2204.02311. · arXiv
- Leo Gao, Stella Biderman, Sid Black, Laurence Gold- ing, Travis Hoppe, Charles Foster, Jason Phang, Ho- race He, Anish Thite, Noa Nabeshima, et al. 2020. The pile: An 800gb dataset of diverse text for lan- guage modeling. arXiv preprint arXiv:2101.00027. · arXiv
- Ari Holtzman, Jan Buys, Maxwell Forbes, Antoine Bosselut, David Golub, and Yejin Choi. 2018. Learn- ing to write with cooperative discriminators. arXiv preprint arXiv:1805.06087. · arXiv
- Daphne Ippolito, Florian Tramèr, Milad Nasr, Chiyuan Zhang, Matthew Jagielski, Katherine Lee, Christo- pher A Choquette-Choo, and Nicholas Carlini. 2022. Preventing verbatim memorization in language mod- els gives a false sense of privacy. arXiv preprint arXiv:2210.17546. · arXiv
- Joel Jang, Dongkeun Yoon, Sohee Yang, Sungmin Cha, Moontae Lee, Lajanugen Logeswaran, and Minjoon Seo. 2022. Knowledge unlearning for mitigating privacy risks in language models. arXiv preprint arXiv:2210.01504. · arXiv
- Qiao Jin, Bhuwan Dhingra, Zhengping Liu, William W Cohen, and Xinghua Lu. 2019. Pubmedqa: A dataset for biomedical research question answering. arXiv preprint arXiv:1909.06146. · arXiv
- Nikhil Kandpal, Eric Wallace, and Colin Raffel. 2022. Deduplicating training data mitigates privacy risks in language models. arXiv preprint arXiv:2202.06539. · arXiv
- Xuechen Li, Florian Tramer, Percy Liang, and Tatsunori Hashimoto. 2021. Large language models can be strong differentially private learners. arXiv preprint arXiv:2110.05679. · arXiv
- Stephen Merity, Caiming Xiong, James Bradbury, and Richard Socher. 2016. Pointer sentinel mixture mod- els. arXiv preprint arXiv:1609.07843. · arXiv
- Denis Paperno, Germán Kruszewski, Angeliki Lazari- dou, Quan Ngoc Pham, Raffaella Bernardi, Sandro Pezzelle, Marco Baroni, Gemma Boleda, and Raquel Fernández. 2016. The lambada dataset: Word pre- diction requiring a broad discourse context. arXiv preprint arXiv:1606.06031. · arXiv
- Guilherme Penedo, Quentin Malartic, Daniel Hesslow, Ruxandra Cojocaru, Alessandro Cappelli, Hamza Alobeidli, Baptiste Pannier, Ebtesam Almazrouei, and Julien Launay. 2023. The refinedweb dataset for falcon llm: Outperforming curated corpora with web data, and web data only. arXiv preprint arXiv:2306.01116. · arXiv
- Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, Ilya Sutskever, et al. 2019. Language models are unsupervised multitask learners. OpenAI blog, 1(8):9.
- Rajkumar Ramamurthy, Prithviraj Ammanabrolu, Kianté Brantley, Jack Hessel, Rafet Sifa, Christian Bauckhage, Hannaneh Hajishirzi, and Yejin Choi. 2022. Is reinforcement learning (not) for natural language processing?: Benchmarks, baselines, and building blocks for natural language policy optimiza- tion. arXiv preprint arXiv:2210.01241. · arXiv
- Jeff Rasley, Samyam Rajbhandari, Olatunji Ruwase, and Yuxiong He. 2020. Deepspeed: System optimiza- tions enable training deep learning models with over 100 billion parameters. In Proceedings of the 26th ACM SIGKDD International Conference on Knowl- edge Discovery & Data Mining, pages 3505-3506.
- Melissa Roemmele, Cosmin Adrian Bejan, and An- drew S Gordon. 2011. Choice of plausible alter- natives: An evaluation of commonsense causal rea- soning. In AAAI spring symposium: logical formal- izations of commonsense reasoning, pages 90-95.
- Teven Le Scao, Angela Fan, Christopher Akiki, El- lie Pavlick, Suzana Ilić, Daniel Hesslow, Roman Castagné, Alexandra Sasha Luccioni, François Yvon, Matthias Gallé, et al. 2022. Bloom: A 176b- parameter open-access multilingual language model. arXiv preprint arXiv:2211.05100. · arXiv
- Ross Taylor, Marcin Kardas, Guillem Cucurull, Thomas Scialom, Anthony Hartshorn, Elvis Saravia, Andrew Poulton, Viktor Kerkez, and Robert Stojnic. 2022. Galactica: A large language model for science. arXiv preprint arXiv:2211.09085. · arXiv
- Florian Tramèr, Gautam Kamath, and Nicholas Car- lini. 2022. Considerations for differentially private learning with large-scale public pretraining. arXiv preprint arXiv:2212.06470. · arXiv
- Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pier- ric Cistac, Tim Rault, Rémi Louf, Morgan Funtowicz, et al. 2019. Huggingface's transformers: State-of- the-art natural language processing. arXiv preprint arXiv:1910.03771. · arXiv
- Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen, Christopher De- wan, Mona Diab, Xian Li, Xi Victoria Lin, et al. 2022. Opt: Open pre-trained transformer language models. arXiv preprint arXiv:2205.01068. · arXiv
- Tianyi Zhang, Varsha Kishore, Felix Wu, Kilian Q Weinberger, and Yoav Artzi. 2019. Bertscore: Eval- uating text generation with bert. arXiv preprint arXiv:1904.09675. · arXiv
Cited by
A Survey of Machine Unlearning
Nguyen, T. T., Huynh, T. T., Ren, Z., Nguyen, P. L., Liew, A. W.-C., Yin, H., & Nguyen, Q. V. H. (2022) · arXiv · doi:10.48550/arxiv.2209.02299 · Cited by 193
Arnaudo, A., Coppola, R., Morisio, M., Vetrò, A., Borghi, M., Raso, R., & Khan, B. (2026) · PeerJ Computer Science · doi:10.7717/peerj-cs.3928 · Cited by 2
Metadata
- Authors
- Kassem, A., Mahmoud, O., & Saad, S.
- Venue
- Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing
- Published
- 2023
- Pages
- 4360-4379
- Cited by
- 12
- References
- 16
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
