

The DOI matches its Crossref record; 21 of the 21 references it cites were found in a registry or an index.
Benchmarking Retrieval-Augmented Generation for Medicine
Open accessAbstract
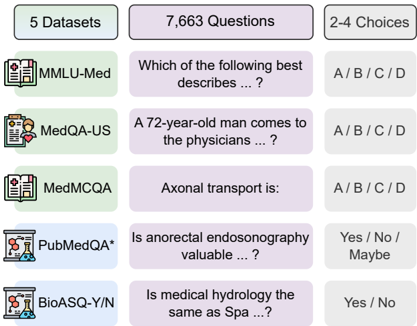
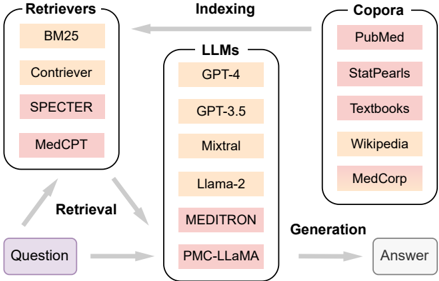
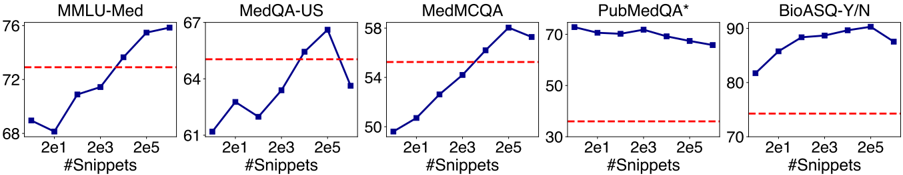
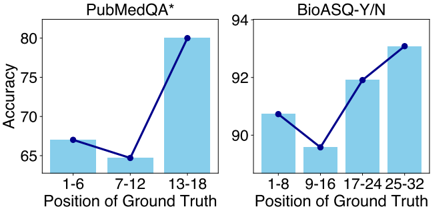
While large language models (LLMs) have achieved state-of-the-art performance on a wide range of medical question answering (QA) tasks, they still face challenges with hallucinations and outdated knowledge.Retrievalaugmented generation (RAG) is a promising solution and has been widely adopted.However, a RAG system can involve multiple flexible components, and there is a lack of best practices regarding the optimal RAG setting for various medical purposes.To systematically evaluate such systems, we propose the Medical Information Retrieval-Augmented Generation Evaluation (MIRAGE), a first-of-its-kind benchmark including 7,663 questions from five medical QA datasets.Using MIRAGE, we conducted large-scale experiments with over 1.8 trillion prompt tokens on 41 combinations of different corpora, retrievers, and backbone LLMs through the MEDRAG toolkit introduced in this work.Overall, MEDRAG improves the accuracy of six different LLMs by up to 18% over chain-of-thought prompting, elevating the performance of GPT-3.5 and Mixtral to GPT-4level.Our results show that the combination of various medical corpora and retrievers achieves the best performance.In addition, we discovered a log-linear scaling property and the "lostin-the-middle" effects in medical RAG.We believe our comprehensive evaluations can serve as practical guidelines for implementing RAG systems for medicine 1 .
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“Recently, LLMs have shown the ability to encode clinical knowledge7,8, retrieve relevant medical texts9, and perform accurate single-turn medical question-answering3,10–12.”
From AgentClinic: a multimodal benchmark for tool-using clinical AI agents (2026) · cites this paper as [9]
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“All analyses were performed on publicly available, de-identified benchmark datasets—MIRAGE [23], PubMedQA [24], and the medical licensing examination questions of Katz et al. [25]—used in accordance with their respective licenses and terms of use.”
From The economics of accuracy for medical reasoning with large language models (2026) · cites this paper as [23]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Similarly, without context on the MIRAGE datset, MedGemma 27B with extended reasoning (PCCR-1024) reached 80.1% which is higher than the 73.4% accuracy reported for GPT-4 without context and matched the performance of GPT-4 with access to extensive context [23].”
From The economics of accuracy for medical reasoning with large language models (2026) · cites this paper as [23]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“This pattern appeared in approximately 40% of cases, underscoring retrieval challenges in medical RAG systems where the complexity of clinical terminology limits the effectiveness of standard mechanisms [57,58].”
From Enhancing Medical Question Answering with LLMs via a Hybrid Retrieval-Augmented Generation Framework (2026) · cites this paper as [57]
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Such errors appeared in approximately 30% of cases, underscoring integration challenges in RAG systems where connecting retrieved facts to query-specific conclusions remain a persistent limitation [57].”
From Enhancing Medical Question Answering with LLMs via a Hybrid Retrieval-Augmented Generation Framework (2026) · cites this paper as [57]
Experimental — accuracy not yet measured
In the citing paper
“The quality of RAG completion also depends on the retrieval results, such as the density or positions of query-relevant information14,22,24–26.”
From Leveraging long context in retrieval augmented language models for medical question answering (2025) · cites this paper as [26]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 45
- Asma Ben Abacha, Chaitanya Shivade, and Dina Demner-Fushman. 2019. Overview of the mediqa 2019 shared task on textual inference, question en- tailment and question answering. In Proceedings of the 18th BioNLP Workshop and Shared Task, pages 370-379.
- Waleed Ammar, Dirk Groeneveld, Chandra Bhagavat- ula, Iz Beltagy, Miles Crawford, Doug Downey, Ja- son Dunkelberger, Ahmed Elgohary, Sergey Feld- man, Vu Ha, et al. 2018. Construction of the liter- ature graph in semantic scholar. In Proceedings of the 2018 Conference of the North American Chap- ter of the Association for Computational Linguistics: Human Language Technologies, Volume 3 (Industry Papers), pages 84-91.
- Sofia J Athenikos and Hyoil Han. 2010. Biomedical question answering: A survey. Computer methods and programs in biomedicine, 99(1):1-24.
- Asma Ben Abacha and Dina Demner-Fushman. 2019. A question-entailment approach to question answering. BMC bioinformatics, 20(1):1-23.
- Sebastian Borgeaud, Arthur Mensch, Jordan Hoff- mann, Trevor Cai, Eliza Rutherford, Katie Milli- can, George Bm Van Den Driessche, Jean-Baptiste Lespiau, Bogdan Damoc, Aidan Clark, et al. 2022. Improving language models by retrieving from tril- lions of tokens. In International conference on ma- chine learning, pages 2206-2240. PMLR.
- Qingyu Chen, Jingcheng Du, Yan Hu, Vipina Kuttichi Keloth, Xueqing Peng, Kalpana Raja, Rui Zhang, Zhiyong Lu, and Hua Xu. 2023a. Large language models in biomedical natural language processing: benchmarks, baselines, and recommendations. arXiv preprint arXiv:2305.16326. · arXiv
- Arman Cohan, Sergey Feldman, Iz Beltagy, Doug Downey, and Daniel S Weld. 2020. Specter: Document-level representation learning using citation-informed transformers. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 2270-2282.
- Gordon V Cormack, Charles LA Clarke, and Stefan Buettcher. 2009. Reciprocal rank fusion outperforms condorcet and individual rank learning methods. In Proceedings of the 32nd international ACM SIGIR conference on Research and development in informa- tion retrieval, pages 758-759.
- Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. BERT: Pre-training of deep bidirectional transformers for language under- standing. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Tech- nologies, Volume 1 (Long and Short Papers), pages 4171-4186, Minneapolis, Minnesota. Association for Computational Linguistics.
- Alexander R Fabbri, Wojciech Kryściński, Bryan Mc- Cann, Caiming Xiong, Richard Socher, and Dragomir Radev. 2021. Summeval: Re-evaluating summariza- tion evaluation. Transactions of the Association for Computational Linguistics, 9:391-409.
- Nicolas Fiorini, Robert Leaman, David J Lipman, and Zhiyong Lu. 2018. How user intelligence is improv- ing pubmed. Nature biotechnology, 36(10):937-945.
- Giacomo Frisoni, Miki Mizutani, Gianluca Moro, and Lorenzo Valgimigli. 2022. Bioreader: a retrieval- enhanced text-to-text transformer for biomedical lit- erature. In Proceedings of the 2022 conference on empirical methods in natural language processing, pages 5770-5793.
- Yu Gu, Robert Tinn, Hao Cheng, Michael Lucas, Naoto Usuyama, Xiaodong Liu, Tristan Naumann, Jianfeng Gao, and Hoifung Poon. 2021. Domain-specific lan- guage model pretraining for biomedical natural lan- guage processing. ACM Transactions on Computing for Healthcare (HEALTH), 3(1):1-23.
- Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. 2020. Measuring massive multitask language under- standing. In International Conference on Learning Representations.
- William Hersh. 2024. Search still matters: informa- tion retrieval in the era of generative ai. Journal of the American Medical Informatics Association, page ocae014.
- Gautier Izacard, Mathilde Caron, Lucas Hosseini, Sebas- tian Riedel, Piotr Bojanowski, Armand Joulin, and Edouard Grave. 2022. Unsupervised dense informa- tion retrieval with contrastive learning. Transactions on Machine Learning Research.
- Ziwei Ji, Nayeon Lee, Rita Frieske, Tiezheng Yu, Dan Su, Yan Xu, Etsuko Ishii, Ye Jin Bang, Andrea Madotto, and Pascale Fung. 2023. Survey of halluci- nation in natural language generation. ACM Comput- ing Surveys, 55(12):1-38.
- Di Jin, Eileen Pan, Nassim Oufattole, Wei-Hung Weng, Hanyi Fang, and Peter Szolovits. 2021. What disease does this patient have? a large-scale open domain question answering dataset from medical exams. Ap- plied Sciences, 11(14):6421.
- Qiao Jin, Bhuwan Dhingra, Zhengping Liu, William Cohen, and Xinghua Lu. 2019. Pubmedqa: A dataset for biomedical research question answering. In Pro- ceedings of the 2019 Conference on Empirical Meth- ods in Natural Language Processing and the 9th In- ternational Joint Conference on Natural Language Processing (EMNLP-IJCNLP), pages 2567-2577.
- Qiao Jin, Robert Leaman, and Zhiyong Lu. 2023b. Re- trieve, summarize, and verify: How will chatgpt im- pact information seeking from the medical literature? Journal of the American Society of Nephrology, pages 10-1681.
- Qiao Jin, Zheng Yuan, Guangzhi Xiong, Qianlan Yu, Huaiyuan Ying, Chuanqi Tan, Mosha Chen, Song- fang Huang, Xiaozhong Liu, and Sheng Yu. 2022. Biomedical question answering: a survey of ap- proaches and challenges. ACM Computing Surveys (CSUR), 55(2):1-36.
- Vladimir Karpukhin, Barlas Oguz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih. 2020. Dense passage retrieval for open- domain question answering. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 6769-6781.
- Anastasia Krithara, Anastasios Nentidis, Konstantinos Bougiatiotis, and Georgios Paliouras. 2023. Bioasq- qa: A manually curated corpus for biomedical ques- tion answering. Scientific Data, 10(1):170.
- Jinhyuk Lee, Wonjin Yoon, Sungdong Kim, Donghyeon Kim, Sunkyu Kim, Chan Ho So, and Jaewoo Kang. 2020. Biobert: a pre-trained biomedical language representation model for biomedical text mining. Bioinformatics, 36(4):1234-1240.
- Jimmy Lin, Xueguang Ma, Sheng-Chieh Lin, Jheng- Hong Yang, Ronak Pradeep, and Rodrigo Nogueira. 2021. Pyserini: A python toolkit for reproducible information retrieval research with sparse and dense representations. In Proceedings of the 44th Inter- national ACM SIGIR Conference on Research and Development in Information Retrieval, pages 2356- 2362.
- Aakanksha Naik, Sravanthi Parasa, Sergey Feldman, Lucy Wang, and Tom Hope. 2022. Literature- augmented clinical outcome prediction. In Findings of the Association for Computational Linguistics: NAACL 2022, pages 438-453.
- OpenAI, :, Josh Achiam, Steven Adler, Sandhini Agar- wal, Lama Ahmad, Ilge Akkaya, Florencia Leoni Ale- man, Diogo Almeida, Janko Altenschmidt, Sam Alt- man, Shyamal Anadkat, Red Avila, Igor Babuschkin, Suchir Balaji, Valerie Balcom, Paul Baltescu, Haim- ing Bao, Mo Bavarian, Jeff Belgum, Irwan Bello, Jake Berdine, Gabriel Bernadett-Shapiro, Christo- pher Berner, Lenny Bogdonoff, Oleg Boiko, Made- laine Boyd, Anna-Luisa Brakman, Greg Brockman, Tim Brooks, Miles Brundage, Kevin Button, Trevor Cai, Rosie Campbell, Andrew Cann, Brittany Carey, Chelsea Carlson, Rory Carmichael, Brooke Chan, Che Chang, Fotis Chantzis, Derek Chen, Sully Chen, Ruby Chen, Jason Chen, Mark Chen, Ben Chess, Chester Cho, Casey Chu, Hyung Won Chung, Dave Cummings, Jeremiah Currier, Yunxing Dai, Cory Decareaux, Thomas Degry, Noah Deutsch, Damien Deville, Arka Dhar, David Dohan, Steve Dowl- ing, Sheila Dunning, Adrien Ecoffet, Atty Eleti, Tyna Eloundou, David Farhi, Liam Fedus, Niko Felix, Simón Posada Fishman, Juston Forte, Is- abella Fulford, Leo Gao, Elie Georges, Christian Malte Ostendorff, Nils Rethmeier, Isabelle Augenstein, Bela Gipp, and Georg Rehm. 2022. Neighborhood contrastive learning for scientific document represen- tations with citation embeddings. In Proceedings of the 2022 Conference on Empirical Methods in Natu- ral Language Processing, pages 11670-11688.
- Ankit Pal, Logesh Kumar Umapathi, and Malaikan- nan Sankarasubbu. 2022. Medmcqa: A large-scale multi-subject multi-choice dataset for medical do- main question answering. In Conference on Health, Inference, and Learning, pages 248-260.
- PMLR.
- François Remy, Kris Demuynck, and Thomas De- meester. 2022. Biolord: Learning ontological repre- sentations from definitions for biomedical concepts and their textual descriptions. In Findings of the As- sociation for Computational Linguistics: EMNLP 2022, pages 1454-1465.
- Stephen Robertson, Hugo Zaragoza, et al. 2009. The probabilistic relevance framework: Bm25 and be- yond. Foundations and Trends® in Information Re- trieval, 3(4):333-389.
- Karan Singhal, Shekoofeh Azizi, Tao Tu, S Sara Mah- davi, Jason Wei, Hyung Won Chung, Nathan Scales, Ajay Tanwani, Heather Cole-Lewis, Stephen Pfohl, et al. 2023a. Large language models encode clinical knowledge. Nature, 620(7972):172-180.
- Sarvesh Soni and Kirk Roberts. 2020. Evaluation of dataset selection for pre-training and fine-tuning transformer language models for clinical question answering. In Proceedings of the Twelfth Language Resources and Evaluation Conference, pages 5532- 5538.
- Nandan Thakur, Nils Reimers, Andreas Rücklé, Ab- hishek Srivastava, and Iryna Gurevych. 2021. BEIR: A heterogeneous benchmark for zero-shot evaluation of information retrieval models. In Thirty-fifth Con- ference on Neural Information Processing Systems Datasets and Benchmarks Track (Round 2).
- Hugo Touvron, Louis Martin, Kevin Stone, Peter Al- bert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, Soumya Batra, Prajjwal Bhargava, Shruti Bhosale, et al. 2023b. Llama 2: Open founda- tion and fine-tuned chat models. arXiv preprint arXiv:2307.09288. · arXiv
- Daniel Truhn, Jorge S Reis-Filho, and Jakob Nikolas Kather. 2023. Large language models should be used as scientific reasoning engines, not knowledge databases. Nature medicine, 29(12):2983-2984.
- George Tsatsaronis, Georgios Balikas, Prodromos Malakasiotis, Ioannis Partalas, Matthias Zschunke, Michael R Alvers, Dirk Weissenborn, Anastasia Krithara, Sergios Petridis, Dimitris Polychronopou- los, et al. 2015. An overview of the bioasq large-scale biomedical semantic indexing and question answer- ing competition. BMC bioinformatics, 16(1):1-28.
- David Wadden, Shanchuan Lin, Kyle Lo, Lucy Lu Wang, Madeleine van Zuylen, Arman Cohan, and Hannaneh Hajishirzi. 2020. Fact or fiction: Verifying scientific claims. In Proceedings of the 2020 Con- ference on Empirical Methods in Natural Language Processing (EMNLP), pages 7534-7550.
- Lucy Lu Wang, Julia Otmakhova, Jay DeYoung, Thinh Hung Truong, Bailey Kuehl, Erin Bransom, and Byron C Wallace. 2023a. Automated metrics for medical multi-document summarization disagree with human evaluations. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 9871- 9889.
- Jason Wei, Xuezhi Wang, Dale Schuurmans, Maarten Bosma, Fei Xia, Ed Chi, Quoc V Le, Denny Zhou, et al. 2022. Chain-of-thought prompting elicits rea- soning in large language models. Advances in Neural Information Processing Systems, 35:24824-24837.
- Guillaume Wenzek, Marie-Anne Lachaux, Alexis Con- neau, Vishrav Chaudhary, Francisco Guzmán, Ar- mand Joulin, and Édouard Grave. 2020. Ccnet: Ex- tracting high quality monolingual datasets from web crawl data. In Proceedings of the Twelfth Language Resources and Evaluation Conference, pages 4003- 4012.
- Chaoyi Wu, Xiaoman Zhang, Ya Zhang, Yanfeng Wang, and Weidi Xie. 2023. Pmc-llama: Further fine- tuning llama on medical papers. arXiv preprint arXiv:2304.14454. · arXiv
- Lee Xiong, Chenyan Xiong, Ye Li, Kwok-Fung Tang, Jialin Liu, Paul N Bennett, Junaid Ahmed, and Arnold Overwijk. 2020. Approximate nearest neigh- bor negative contrastive learning for dense text re- trieval. In International Conference on Learning Representations.
- Michihiro Yasunaga, Antoine Bosselut, Hongyu Ren, Xikun Zhang, Christopher D Manning, Percy S Liang, and Jure Leskovec. 2022. Deep bidirectional language-knowledge graph pretraining. Advances in Neural Information Processing Systems, 35:37309- 37323.
- Pierre Zweigenbaum. 2003. Question answering in biomedicine. In Proceedings Workshop on Natural Language Processing for Question Answering, EACL, volume 2005, pages 1-4. Citeseer.
Cited by
Sorted by citations
Items 201–300 of 314
Kong, W., Ye, J., Zhao, C., Ma, Y., Chen, Y., & Lv, W. (2025) · IEEE International Conference on Parallel and Distributed Systems (ICPADS) · doi:10.1109/icpads67057.2025.11322977
RAG System Application for Supporting Drug Discovery and Docking Molecular Processes
Arévalo, J. D. F., Rodriguez-Lopez, A., & Orjuela-Cañón, A. D. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-14706-6_5
Peng, L., Xie, W., Gao, D., TIan, H., Yang, Z., Xian, N., Li, K., Liu, L., Zhao, Y., & Liu, Y. (2026) · doi:10.2196/preprints.91173
Chimera-3X: A Hybrid Cognitive Engine for Retrieval-Augmented Biomedical Consulting
Dhifallah, M., & Liu, Y. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11356117
Jin, X., Wang, Z., Yang, H., Li, M., & Du, Y. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11356717
Nikolić, M., Stanimirović, A., & Stoimenov, L. V. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-04890-5_32
VetChain-RAG: A PureChain-Enhanced RAG Framework for Veterinary Diagnosis
Khafagy, R. A., Angelo, O. P., Lee, J. M., & Kim, D. (2025) · International Conference on Information and Communication Technology Convergence (ICTC) · doi:10.1109/ictc66702.2025.11389066
Exploring RAGs Applications in Healthcare
Almohsen, K., & Hewahi, N. (2025) · International Conference on Foundation and Large Language Models (FLLM) · doi:10.1109/fllm67465.2025.11391150
MeDRNet: A Knowledge-Augmented Multi-model Framework for Robust Medical Language Understanding
Long, X., Zhao, Y., & Liu, J. (2026) · Lecture notes in computer science · doi:10.1007/978-981-95-7081-2_22
Liu, T., Zhu, M., & Zhai, S. (2026) · IEEE Annual Computing and Communication Workshop and Conference (CCWC) · doi:10.1109/ccwc67433.2026.11393764
RAG Technology for Reliable Medical Retrieval and Hallucination Mitigation
Wu, M. (2025) · International Conference on Computer Communication, Networks and Information Science (CCNIS) · doi:10.1109/ccnis69465.2025.00009
StagRAG: Explaining Where RAG Systems Go Wrong in Medical Reasoning
Wang, Y., Chowdhury, M. A.-M., Sristy, M. A., & Kabir, M. F. (2025) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata66926.2025.11402407
Wang, L., Duanmu, C., Zhang, X., & Huang, Z. (2025) · International Conference on Advanced Computer Theory and Engineering · doi:10.1109/icacte66284.2025.11412210
Shen, L., Shi, D., & Cheng, J. (2025) · International Conference on Advanced Computer Theory and Engineering · doi:10.1109/icacte66284.2025.11411964
Improving Causal Gene Identification Using Large Language ModelsPreprint
Ofer, D., & Kaufman, H. (2026) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.64898/2026.03.08.710344
CancerRAGent: Evidence-Linked and Safety-Guided Oncology Question Answering
Vo, T., Trieu, A., Tran, V., Matsumoto, Y., & Nguyen, L.-M. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-21321-1_20
Design of a RAG framework for cardiology EHR analysis
Defilippo, A., Canino, G., Procopio, N., Trapuzzano, M. D. A., Sorrentino, S., Indolfi, M. D. C., Vizza, P., Veltri, P., & Guzzi, P. H. (2026) · Discover Artificial Intelligence · doi:10.1007/s44163-026-01128-z
Chowdhury, D., Abdullah, S., Hossain, R., Arefin, M. S., & Hussain, M. M. M. (2026) · International Conference on Sentiment Analysis and Deep Learning (ICSADL) · doi:10.1109/icsadl67539.2026.11452021
A critical evaluation of generative query expansion on biomedical literature retrieval
Fang, Y., Zhang, G., Chen, F., Peng, Y., & Weng, C. (2026) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocag037
SpecMedRAG: A Multi-Granularity Graph RAG for Specialty Medicine
Duan, Z. Y., Song, Y., Chen, J., & Zhao, S. (2025) · International Conference on Cyberworlds (CW) · doi:10.1109/cw68232.2025.00061
Comparative Evaluation of Large Language Models in Clinical Diagnostics for Real-World Medical Cases
Młodawski, M., Deniziak, S. R., Płaza, M., Kwiatkowska, A., Jaszczyk, D., Gajda, A., & Twardowski, K. (2026) · Applied Sciences · doi:10.3390/app16073499 · Cited by 1
Medical Question Answering System Based on Retrieval-augmented Generation
Cao, C. (2026) · ITM Web of Conferences · doi:10.1051/itmconf/20268401001
BLUEmed: Retrieval-Augmented Multi-Agent Debate for Clinical Error Detection
You, S. T., Tran, N. A. K., Marizane, W. K., Rao, H., Zhang, Q., & Huang, X. (2026) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi69079.2026.00112 · Cited by 2
Xu, Z. (2026) · International Symposium on Computer Applications and Information Systems (ISCAIS) · doi:10.1109/iscait69154.2026.11477466
RAG-Enhanced LLMs for Interactive Explainability in Clinical Decision Support Systems
Mannocci, L., Naretto, F., Passaro, L., & Monreale, A. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-16708-8_4
Sharma, K., Srivastava, S., -, S. S., & Singhal, A. (2026) · IEEE International Conference on AI Engineering and Innovations (AIEI) · doi:10.1109/aiei69164.2026.11497629
EchoAgent: guideline-centric reasoning agent for echocardiography measurement and interpretation
Daghyani, M., Wang, L., Hashemi, N., Medhat, B., Abdelsamad, B., Velez, E. R., Li, X., Tsang, M. Y. C., Luong, C. L., Abolmaesumi, P., et al. (2026) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-026-03694-0
M3E: A Unified Framework for Large-Scale Multimodal Embedding via Multi-Task Mixture-of-ExpertsPreprint
Zhang, L., Cheng, J., Wang, M., Xie, Q., & Wang, X. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6795463
M3E: A Unified Framework for Large-Scale Multimodal Embedding via Multi-Task Mixture-of-ExpertsPreprint
Zhang, L., Cheng, J., Wang, M., Xie, Q., & Wang, X. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6795462
He, X., Camacho, D., Moukheiber, L., Iyer, M. R., Zhao, B., Ye, C., Nursal, B., Guo, X., Lee, A. J. B., & Mitchell, C. S. (2026) · Big Data and Cognitive Computing · doi:10.3390/bdcc10060171
田, 行. (2026) · Modeling and Simulation · doi:10.12677/mos.2026.155082
Iterative Dynamic Routing Framework for Medical Question Answering
Wang, C., Yang, X., Zhu, Y., Sun, M., Li, M., & Zhang, W. (2026) · Communications in computer and information science · doi:10.1007/978-981-95-7299-1_2
Retrieval-Augmented Generation for Pharmaceutical Regulatory Intelligence: A Narrative Review
Bianchi, L., Rossi, M., & Romano, G. (2026) · Pharmacophore · doi:10.51847/sma6gzncaq
MedAgent: Trustworthy Personalized Consumer Health Search via Multi-Agent Retrieval and Verification
Trikha, K., Madrzyk, B., Castelino, A., & Bahrini, A. (2026) · Systems and Information Engineering Design Symposium · doi:10.1109/sieds69358.2026.11540322
Ragupathy, V. (2026) · IEEE International Conference on Computing and Machine Intelligence (ICMI) · doi:10.1109/icmi68585.2026.11539784
Chen, C., & Han, Z. (2026) · International Conference on Intelligent Computing and Signal Processing (ICSP) · doi:10.1109/icsp69961.2026.11540949
Guideline-grounded Retrieval-augmented Generation for Ophthalmic Clinical Decision Support
Chen, S., Cui, S., & Cao, Z. (2026) · doi:10.1145/3811238.3811871
Chokkalingam, S. P., & Ganesh, M. (2026) · International Conference on Intelligent Communication Technologies and Virtual Mobile Networks (ICICV) · doi:10.1109/icicv68925.2026.11554638
MTDW-RAG: A Tree-Structured Medical Q&A Approach Combining Deep Progression and Wide Exploration
Chen, R. (2026) · Lecture notes in electrical engineering · doi:10.1007/978-981-95-4897-2_12
Risk-Aware Medical Question Answering as a Reliability-Critical Decision Process
Luo, Y., & Li, Y. (2026) · International Conference on Multimedia Retrieval · doi:10.1145/3805622.3810784
Suta, P., & Mongkolnam, P. (2026) · International Conference on Advances in Information Technology · doi:10.1145/3816713.3819510
EC-RAG: Evidence-Centric Retrieval-Augmented Generation for Medical Visual Question Answering
Li, S., & Long, J. (2026) · International Conference on Multimedia Retrieval · doi:10.1145/3805622.3810670
AI-CURA, an automated LLM workflow for high-accuracy genetic variant classification
Ma, W., Fong, G., Lai, J., Wu, H., Hue, S. P. Y., Ying, D., Chen, L., Tang, W., Preusch, C. B., Chu, A. T. W., et al. (2026) · Science Translational Medicine · doi:10.1126/scitranslmed.adz4172 · Cited by 1
Mahalakshmi, B. S., Khairnar, S., Gite, S., Lengure, A., Loharkar, A., Mahadik, S., & Mahajan, S. (2026) · Research Square · doi:10.21203/rs.3.rs-9787855/v1 · Cited by 1
Optimizing White Noise for Stability and Strategic Performance Enhancement of LLM-RAG Systems
Kim, D., & Ko, Y.-M. (2026) · Journal of Korean Institute of Industrial Engineers · doi:10.7232/jkiie.2026.52.3.193
Wan, S., Zhang, J., Zhao, Z., & Ren, S. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37654-1_29
Artificial intelligence in healthcare: concepts and applications
Das, S., Chanda, P. B., & Maity, D. (2026) · Elsevier eBooks · doi:10.1016/b978-0-443-45875-0.00008-9
Nguyen, T. N.-B., & Phan, T. H. V. (2026) · Lecture notes of the Institute for Computer Sciences, Social Informatics and Telecommunications Engineering · doi:10.1007/978-3-032-24399-7_10
A Dual-source Fusion Enhancement method for Question Answering on Acute Mountain Sickness
Sui, M., Bi, X., Yu, G., Zhang, L. H., Xu, H., & Zhao, K. (2026) · International Conference on Computer Supported Cooperative Work in Design (CSCWD) · doi:10.1109/cscwd68734.2026.11582261
STRAGMED: Standardizing Retrieval-Augmented Generation Pipelines in Medical Domains
Sanna, L., Yildiz, E. E., & Dragoni, M. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30710-1_15
Comparative Evaluation of LLM Systems in Psychiatry: The MedicLLM Study
Mahadik, P. V., Saud, K. S. I., & Dongardive, J. (2026) · Procedia Computer Science · doi:10.1016/j.procs.2026.06.550
Language Bias in Multilingual RAG: A Case Study in the Japanese Medical Domain
Huang, J., Cheng, F., Jiang, J., Kobayashi, K., & Aizawa, A. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-20897-2_9
QAlign-RAG: Causal-Aware Pseudo-Question Generation and Debate-Driven Verification for Medical RAG
Liu, M., Yang, Q., & Wang, H. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-2852-2_13
Ayalew, A. M., Seppänen, T., & Oussalah, M. (2026) · ACM SIGIR International Conference on Theory of Information Retrieval (ICTIR) · doi:10.1145/3805713.3820416
Zhou, Z., Xue, C., & Zhuang, N. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-3495-0_25
Interactive Retrieval-Governed LLM Tutoring for Surgical Site Infection Prevention Education
Stylianou, F., Vakanas, K., Papageorgiou, P., Charalambous, A., Nicolaidou, I. A., Michail, K. A., Loizou, C. P., Kyriacou, E. C., & Tsitsi, T. (2026) · IFIP advances in information and communication technology · doi:10.1007/978-3-032-30805-4_6
He, C., Li, Y., Yang, J., & Zhao, S. (2026) · Applied Sciences · doi:10.3390/app16147213
Abbas, S., Amin, W., Alshammari, T., Aoun, M., Mazhar, T., & Hamam, H. (2026) · Expert Systems with Applications · doi:10.1016/j.eswa.2026.133708
Toward Trustworthy Large Language Model Agents in Healthcare
Hasan, H., Salman, S., Dargham, A. T. A., Mohanna, A., & Chehab, A. (2026) · International Conference on Computer Networks, Big Data and IoT (ICCBI) · doi:10.1109/iccbi68589.2026.11619647 · Cited by 1
Nguyen, T. N.-B., & Phan, T. H. V. (2026) · Journal of Intelligent & Fuzzy Systems · doi:10.1177/18758967261468810
Souza, M. L. H., Barcelos, J., da Costa, C. A., Piovesan, L. D., Abe, J. M., & Leite, M. V. (2026) · Advances in sustainability science and technology · doi:10.1007/978-3-032-25267-8_4
Sulaiman, M. A., Oyeyemi, B. F., & Sarafadeen, H. (2026) · medRxiv · doi:10.64898/2026.07.31.26359439
Retrieval-augmented generation for medical question answering: a multi-metric performance evaluation
Kökver, Y. (2026) · PeerJ Computer Science · doi:10.7717/peerj-cs.4053
Jeon, K., Ko, Y., Jung, W., & Kim, H. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3818040
Wang, H., Xu, X., Huang, B., & Shu, K. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3817665
Huang, Y.-H., Han, Z., Chang, K., Jiao, T., & Liu, J. (2026) · Knowledge Discovery and Data Mining · doi:10.1145/3770855.3817461
Ashinze, E. C. (2026) · SPE Nigeria Annual International Conference and Exhibition · doi:10.2118/234917-ms
Yan, F., Zheng, D., Yu, F., & Kang, J. (2026) · Applied Sciences · doi:10.3390/app16167956
Ribeiro, A., Garrido, R., Ramos, V., Teixeira, S., & Георгиева, П. (2026) · doi:10.1109/icarai70085.2026.11635662
Multi-source Knowledge Graph RAG for LLM-Based Medical Diagnosis
Kespechara, K., & Mingkhwan, A. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-35387-0_31
Benchmarking large language models for question answering on German clinical practice guidelines
Schwietering, J., & Lichtner, G. (2026) · BMJ Health & Care Informatics · doi:10.1136/bmjhci-2026-102207
Jabbar, S., Bougzime, O., Cruz, C., & Bertolim, M. A. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-35387-0_36
Improving Cost Efficiency in Medical Retrieval-Augmented Generation via Adaptive Query Routing
Chang, K., & Alireza Shafiey., M. (2026) · IEEE International Conference on Consumer Electronics - Taiwan (ICCE-Taiwan) · doi:10.1109/icce-taiwan71481.2026.11652397
OnkoRAG: Modelling Cross-Lingual German-Arabic Medical Question Answering
Jennings, N. G., Petukhova, V. V., & Klakow, D. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37249-9_54
Yıldırım, S., Çevik, M., & Basar, A. (2026) · SN Computer Science · doi:10.1007/s42979-026-05302-z
Local large language model‐guided optimization for prostate radiotherapy planning
Nusrat, H., Luo, B., Bagher‐Ebadian, H., Hall, R., Kim, J., Doemer, A., Adil, K., Elsheikh, M., Feldman, A. M., Movsas, B., et al. (2026) · Medical Physics · doi:10.1002/mp.70654 · Cited by 1
Nhan, T. P. T., Phu, H. N., Truong, T. Q., & Thin, D. V. (2026) · International Conference on Multimedia Analysis and Pattern Recognition (MAPR) · doi:10.1109/mapr72750.2026.11685790
Comparative Evaluation of Advanced RAG Architectures for Medical Question Answering
Haneela, A. L. S., Sujith, R., Ganesh, A., Kudalkar, V. P., & O, P. C. (2026) · International Conference on Emerging Technologies in Computing and Communication (ETCC) · doi:10.1109/etcc69750.2026.11681946
Embeddings Enrichment for Arabic Retrieval-Augmented Generation (RAG) Systems
Degheidy, F. E., Ebrashi, R. E., Abdelghaffar, H., & Abu-Elkheir, M. (2026) · International Conference on Machine Learning Technologies (ICMLT) · doi:10.1109/icmlt69916.2026.11688831
Hazra, M., & Anandaram, H. (2026) · Frontiers in Pharmacology · doi:10.3389/fphar.2026.1915973
Xu, Z., Dai, X., Wang, B., & Tian, T. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-38059-3_29
Long, H., Duan, T., & Hu, G. (2026) · IEEE Access · doi:10.1109/access.2026.3735448
Integration of a large language model as an agent of the ChronobioticsDB pharmacological database
Solovev, I. A., Gaiduchik, B. R., Golubev, D., Yagovkina, A. I., & Kotelina, N. O. (2026) · Medical Technologies Assessment and Choice · doi:10.17116/medtech20264803129
Feng, Y., Gao, Y., Li, H., & Gao, X. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-38189-7_26
Zhang, R., Dong, J., Xin, J., Ballard, J., Beeche, C., Sharma, R., Zhao, X., Konz, N., Long, Q., Witschey, W. R., et al. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-38079-1_16
REM-CaR: Retrieval-Augmented Generation Enhanced Medical Case-Based Reasoner
Li, Z., Jin, B., Chen, Y., Gong, T., & Fu, Y. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-5699-0_35
Szewczyk, M., Pluciński, T., Maksim, K., Bartanowicz, S., & Jassem, K. (2026) · Annals of Computer Science and Information Systems · doi:10.15439/2026f9874
Analysis of Generalist and Domain-Specific Large Language Models for Medical Assessment
Maheswara, I. G. A., Yudistira, F. S., Prasetyo, A., & Majiid, M. R. N. (2026) · International Conference on Information Management and Technology (ICIMTech) · doi:10.1109/icimtech202671078.2026.11699040
Bold, C., Faizan, R., Hua, C.-H., Kang, S. M., Lee, S., & Kim, S. T. (2026) · International Conference on Advanced Network Technologies and Applications (APAN) · doi:10.1109/apan70967.2026.11709588
J, J. T., Rajagopalan, N., & Gopal, S. (2026) · International Conference on Smart Communication and Sustainable Technologies (ICSCST) · doi:10.1109/icscst70031.2026.11709521
Lorensia, A., Vincent, D., Febrianto, D. R., Jabar, B. A., & Halim, R. (2026) · International Conference on ICT for Smart Society (ICISS) · doi:10.1109/iciss71466.2026.11715110
Kulkarni, S., Aman Chandra, H., Saadhvi, S., Nithin, S., & S, S. M. J. (2026) · International Conference on Emerging Techniques in Computational Intelligence (ICETCI) · doi:10.1109/icetci71772.2026.11710573
Hatim, S. M., Nizam, A. A. K., Shamsudin, N., Zamani, N. A. M., & Ahmad, Z. (2026) · International Conference on Artificial Intelligence and Data Sciences (AiDAS) · doi:10.1109/aidas71914.2026.11712729
PROTEUS: Privacy-Preserving On-Premise RAG for Biomedical Text Understanding
Antar, S. S., & Ador, S. S. (2026) · International Conference on Technology Innovation and Its Applications (ICTIIA) · doi:10.1109/ictiia70925.2026.11717316
Ardiyansah, S., & Yugopuspito, P. (2026) · International Conference on Technology Innovation and Its Applications (ICTIIA) · doi:10.1109/ictiia70925.2026.11717347
Wu, C., Zuo, M., & Xie, L. (2026) · doi:10.1109/cvprf71909.2026.00528
Ensemble multi-retrieval methodologies with reasoning model decision in multi-step biomedical QA
Jung, J., Hwang, H., Park, Y., Minju, S., Yun, J., Hwang, H., Lee, S., Sohn, J., & Kang, J. (2026) · Database · doi:10.1093/database/baag061
Reliable extraction of clinical-trial evidence with provenance, verification, and targeted reviewPreprint
Najpande, G., Titiya, P., Khan, M. A., Khakwani, K. Z. R., Sonbol, M. B., Riaz, I. B., & Gupta, V. (2026) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.64898/2026.10.01.756091
Metadata
- Authors
- Xiong, G., Jin, Q., Lu, Z., & Zhang, A.
- Affiliations
- National Institutes of Health (US)
- Venue
- Findings of the Association for Computational Linguistics ACL 2024
- Published
- 2024
- Pages
- 6233-6251
- OpenAlex
- W4402670290
- Cited by
- 310
- References
- 0
- Citations by year
- 2026: 142 · 2025: 144 · 2024: 24
- FWCI
- 91.48
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: ACL (Findings of ACL) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- National Science Foundation (2333740)
- National Institutes of Health (1R01LM014012)
- U.S. National Library of Medicine
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Keywords
- retrieval-augmented generation, medical question answering, benchmark, hallucinations, large language models, medical corpora, Retriever, chain-of-thought prompting
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
