

The DOI matches its Crossref record; 24 of the 25 references it cites were found in a registry or an index; none of the 28 sources its claims cite is checked for support yet.
Ai2 Scholar QA: Organized Literature Synthesis with Attribution
Open accessAbstract
Amanpreet Singh, Joseph Chee Chang, Dany Haddad, Aakanksha Naik, Jena D. Hwang, Rodney Kinney, Daniel S Weld, Doug Downey, Sergey Feldman. Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 3: System Demonstrations). 2025.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
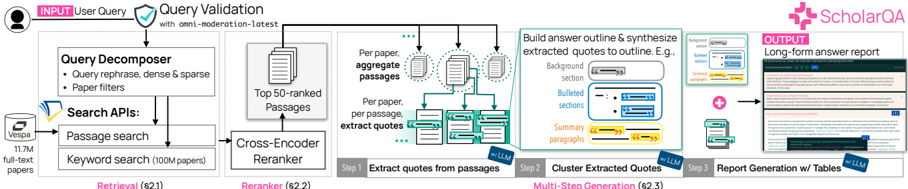
Ai2 Scholar QA is a free, open-source scientific question-answering system that retrieves from Semantic Scholar abstracts and a new 11.7M-paper full-text index, re-ranks passages, and uses multi-step LLM generation to produce cited, organized reports. It reports state-of-the-art results on the ScholarQA-CS benchmark and positive real-world usage feedback.
Key findings
Ai2 Scholar QA outperforms competing systems on ScholarQA-CS, with its Claude 3.7 Sonnet variant scoring 2.4 points higher than STORM overall; it also beats popular LLMs and reasoning models overall, though reasoning models score better on rubrics. The system’s attribution quality, measured with ALCE-style citation precision/recall, is far ahead of other QA systems. In 9 weeks of public deployment, it received 30.2k questions from 8,219 unique visitors; responses averaged about 2.4k words and cost $0.50 to produce, and 85% of 2,433 thumbs feedback was positive. Average full report generation took 2.5 minutes (N=500, σ=70s), with the first section available in 50 seconds (N=500, σ=24s).
Methods
The pipeline has three main components: retrieval from Semantic Scholar keyword search over abstracts and a new `/snippet/search` endpoint over 11.7M full-text papers and 285.6M passages; cross-encoder re-ranking retaining the top 50 passages; and multi-step LLM generation that extracts quotes, builds a thematic outline, clusters quotes, and synthesizes sections with citations and comparison tables. Retrieval tuning used 500 synthetic queries and top 1000 passages per query, with GPT-4o relevance labels that agreed with human annotators 80% of the time on a sample of 100 queries; re-ranker evaluation used 2,426 queries and 225,618 passages. Generation was evaluated on ScholarQA-CS, consisting of expert-annotated rubrics for 100 Computer Science research questions, using GPT-4o as judge and comparing against LLM prompting and RAG QA baselines.
Limitations
The paper states that production uses a proprietary, closed-source LLM backbone, and that open-source models lag behind proprietary models in their evaluation; they are experimenting with open-source replacements. The paper also states that evaluation is limited to Computer Science questions and relies completely on an LLM evaluator, with ongoing work on broader-domain, human-preference benchmarks. User feedback analysis of 383 neutral/negative freeform instances identified categories including incorrect or missing references (126), off-topic or misunderstood query (113), requests for more detail or specificity (289), general quality feedback (149), and language or format issues (78).
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
21 Own result · 18 Sources not found · 13 Own method · 10 Own interpretation · 4 No basis given · 1 Check pending · 1 Not checked yet
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in Table 2, open source models lag behind the proprietary models in our evaluation.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, in cases where the retrieved passages were not relevant enough, the system failed to answer the question in favor of just discussing the information in the quotes.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
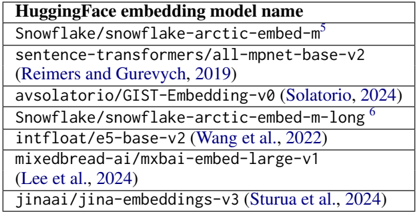
“The mxbai-embed-large-v1 (Lee et al., 2024) embeddings performed best over our dev set.”
§ Organized Literature Synthesis with Attribution > 3 Scholar QA: Interface and Source Code
What the sources say
- Not matchedcites Lee et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Even with a report spanning multiple sections where all the sentences might not be cited, Scholar QA comes out far ahead of the other QA systems.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“We compare Scholar QA's answers against several baselines, demonstrating that it achieves state-of-the-art performance on the ScholarQA-CS benchmark (Asai et al., 2024).”
§ Organized Literature Synthesis with Attribution > 1 Introduction
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We observed 1,075 monthly repeated users who had issued queries on two distinct days over the course of a 30 day window.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
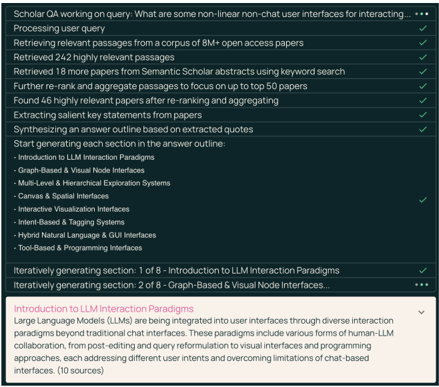
“On average, Scholar QA produces a full report in 2.5 minutes (N=500, σ=70s), which is comparable to modern LLMbased research tools.”
§ Organized Literature Synthesis with Attribution > 3 Scholar QA: Interface and Source Code
plainn = 500- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“As shown in Table 2, our system outperforms popular LLMs: Llama 3.1 (Dubey et al., 2024), GPT 4.1 and Claude Sonnet 3.7 (Anthropic, 2024).”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
What the sources say
- Not matchedcites Dubey et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Anthropic, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Presenting each section as soon as it is generated, so users can begin browsing the first section in 50 seconds (N=500, σ=24s) post issuing a query (Appendix H).”
§ Organized Literature Synthesis with Attribution > 3 Scholar QA: Interface and Source Code
plainn = 500- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Out of 18 comparisons, Claude 3.7 Sonnet was the overwhelming favorite with 17 wins”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 19
- Probably not a substantial claim. 29
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“An interesting discovery from our analysis was that with an updated version of GPT-4o (i.e.gpt-4o-2024-11-20) as the judge, the scores are inflated compared to using gpt-4o-2024-08-06, even though the relative rankings are consistent (See Appendix J).”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We release key components as open source code and public APIs, and report experiments analyzing design decisions and demonstrate state-of-the-art results.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
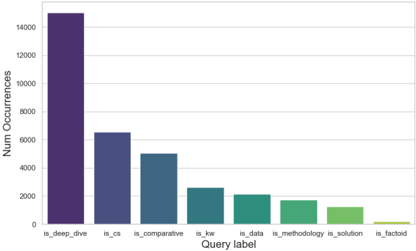
“Other themes such as factoid QA or specific methods, datasets accounted for fewer queries.”
§ Organized Literature Synthesis with Attribution > Additional information
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Further, our code is open-sourced and can easily be used with potentially any available LLM api provider supported by litellm.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
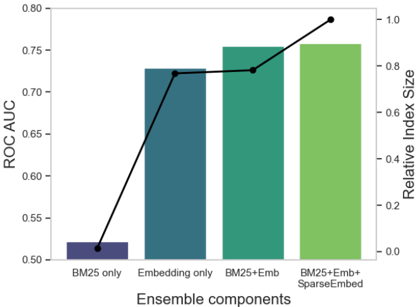
“SparseEmbed introduces an overhead with minimal performance gains, so we picked an ensemble of embedding similarity and BM25 as our final ranking metric.”
§ Organized Literature Synthesis with Attribution > E Retrieval Ensemble Experiments
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We present Ai2 Scholar QA, a freely-available longform literature synthesis system that generates reports for complex scientific questions.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
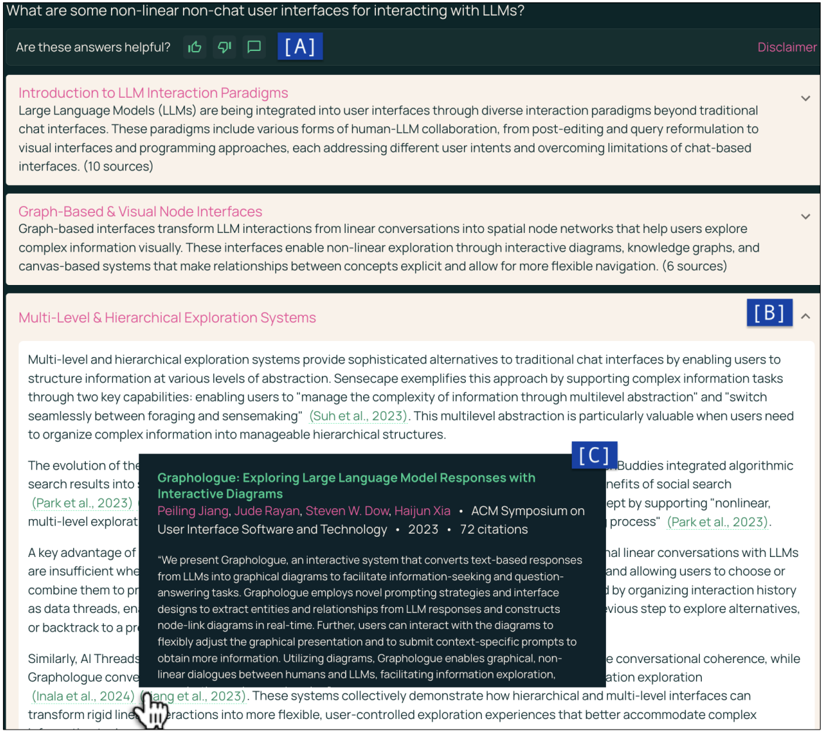
“A total of 2,433 thumbs feedback were submitted (Figure 2 [A]) and 85% were positive.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We analyze the user query types and the most prominent themes were deep-dive into specific research topics (15k) and comparative analysis of specific prior work (5k) (detailed distribution in Appendix I).”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We have publicly deployed Scholar QA for 9 weeks, and received 30.2k questions from 8,219 unique visitors.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Our production system has a few additional features like downloadable reports, login and links to other Ai2 systems.”
§ Organized Literature Synthesis with Attribution > F Prompt for Evaluating Attribution
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The most prominent types were comprehensive deep-dive into a specific research topic (15k) and comparative analysis of prior work (5k).”
§ Organized Literature Synthesis with Attribution > Additional information
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Excluding SparseEmbed reduces the index size by 20% without a significant drop in ranking performance.”
§ Organized Literature Synthesis with Attribution > E Retrieval Ensemble Experiments
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On average, each response is about 2.4k words and costs $0.50 to produce.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“Scholar QA obtains the best scores both on rubrics and overall, with the variant using Claude 3.7 Sonnet as the backbone scoring 2.4 points higher than STORM.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
What the sources say
- Not checked yetcites Shao et al., 2024a source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Our results are not identical toAsai et al. (2024) due to variance across LLM-as-a-judge runs.”
§ Organized Literature Synthesis with Attribution > F Prompt for Evaluating Attribution
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This citation following method allows the LLM to condition on and cite foundational sources which are not uncovered in retrieval.”
§ Organized Literature Synthesis with Attribution > Report Generation.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Their code was not available at the time of our evaluation.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“Other general-purpose tools also support scientific inquiries: Perplexity (Perplexity, 2024), You.com (You.com, 2024), OpenAI Deep Research (Ope-nAI, 2024a) and Gemini Deep Research (Deep-Mind, 2024).”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
What the sources say
- Not matchedcites Perplexity, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites You.com, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites OpenAI, 2024a
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
In the paper
“Passages from the retrieval stage can be lengthy and may contain extraneous information not useful for answering the user query (Asai et al., 2023).”
§ Organized Literature Synthesis with Attribution > Quote extraction.
What the sources say
- Not matchedcites Asai et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
In the paper
“STORM (Shao et al., 2024b) synthesizes comprehensive, Wikipedia-like articles, a distinct task from long-form scientific question answering.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
What the sources say
- Not matchedcites Shao et al., 2024b
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
“Their reported total score for OS-GPT-4o is 57.7.”
§ Organized Literature Synthesis with Attribution > F Prompt for Evaluating Attribution
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Even though the answer rubrics are collected via human annotation, the evaluation is only limited to questions in the Computer Science domain and further relies completely on an LLM as the evaluator.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Together, these resources can be combined with any generative LLM API to power a complete long-form scientific QA application.”
§ Organized Literature Synthesis with Attribution > 1 Introduction
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Scholar QA extends its capabilities by leveraging the latest state-of-the-art LLMs and an open source generation pipeline that filters literature into precise quotes and produces thematically organized and detailed answers.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Recently, OpenScholar (Asai et al., 2024) introduced a retrieval-augmented model designed explicitly for scientific literature synthesis with citation-supported responses with significant improvement in accuracy and reduced citation hallucination.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
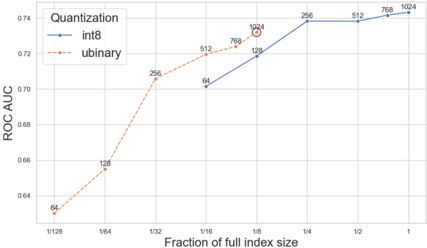
“We optimized several aspects of retrieval over this dev set: embedding model selection and quantization method for it, the components and weights in the final ensemble, and (when relevant) the target Matryoshka dimension for the embeddings (Kusupati et al., 2024).”
§ Organized Literature Synthesis with Attribution > 3 Scholar QA: Interface and Source Code
What the sources say
- Not matchedcites Kusupati et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
“For these QA systems, we also evaluate the attribution quality based on ALCE (Gao et al., 2023), which proposes entailment between claims and evidence to compute citation precision and recall.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
What the sources say
- Not matchedcites Gao et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
In the paper
“Zhou et al. (2025) present a survey categorizing AI-driven research support systems across various stages of the scientific process, including literature synthesis.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
What the sources say
- Not matchedcites Zhou et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, due to the additional reasoning tokens, these models are more expensive and also significantly increase latency.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“For insight into the failure modes, we manually examined the 383 instances of neutral/negative freeform feedback.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Again, we use GPT-4o as a judge to predict entailment (See Appendix F for the prompt) and treat each sentence in a response as a claim.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“To finalize the backbone LLM for the production web application we conducted an anonymized pair- wise comparison among the authors of this work.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“We use GPT-4o (Hurst et al., 2024) as a judge with the utility provided by Asai et al. (2024) for automatic evaluation and compare against several baselines.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
What the sources say
- Not matchedcites Hurst et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“Commercial RAG tools have emerged to facilitate research specifically tailored for scientific literature, such as Consensus (Consensus, 2024), which synthesizes findings from research papers, Scite (Scite, 2024), which evaluates claims by analyzing citation contexts, and Elicit (Elicit, 2024), which supports structured scientific literature reviews.”
§ Organized Literature Synthesis with Attribution > 4.4 Real-world Usage and User Feedback
What the sources say
- Not matchedcites Consensus, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Scite, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Elicit, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The results reported here are obtained post these changes.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Due to a lack of retrieval, this evaluation was not conducted when the LLMs are simply prompted to generate a response from memory.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“We tuned our retrieval setup by optimizing ranking over a dev set of 500 synthetic queries (see Appendix C) and the top 1000 passages for each based on GIST embedding distance (Solatorio, 2024).”
§ Organized Literature Synthesis with Attribution > 3 Scholar QA: Interface and Source Code
What the sources say
- Not matchedcites Solatorio, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This aggregation helps create a richer context conducive to extracting relevant quotes.”
§ Organized Literature Synthesis with Attribution > Quote extraction.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“For parity with Asai et al. (2023), we report the rubrics and citation scores with the older and newer model as the judge, respectively.”
§ Organized Literature Synthesis with Attribution > 4.3 Generation
What the sources say
- Not matchedcites Asai et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
The paper relies on this without support.
Most state-of-the-art scientific QA systems are expensive to use and closed source, relying on models, workflows, and retrieval solutions not shared publicly.
“Most of these systems are expensive to use and closed source, relying on models, workflows, and retrieval solutions not shared publicly.”
The paper relies on this without support.
Effective organization of reference materials is essential for the overall coherence of a comprehensive research report.
“For generating a comprehensive research report, the effective organization of reference materials is essential for its overall coherence.”
The paper relies on this without support.
Paragraphs convey nuanced summaries from multiple papers, while bulleted lists enumerate related papers.
“Paragraphs convey nuanced summaries from multiple papers, while bulleted lists enumerate related papers (e.g., models, datasets, or interactive systems).”
The paper relies on this without support.
The ScholarQA-CS benchmark rewards attribution and supporting evidence as a measure of trust in the system.
“The benchmark rewards attribution and supporting evidence as a measure of trust in the system”
The paper relies on this without support.
Commercial platforms can be too expensive for widespread academic use and typically lack transparency regarding their pipelines.
“Although these platforms leverage advanced retrieval and generation capabilities to facilitate literature reviews and deliver rapid insights, they can be too expensive for widespread academic use and typically lack transparency regarding their pipelines.”
Citations
Cites
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Reimers, N., & Gurevych, I. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1410 · Cited by 12,778
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Lewis, P., Perez, E., Piktus, A., Petroni, F., Karpukhin, V., Goyal, N., Küttler, H., Lewis, M., Yih, W.-T., Rocktäschel, T., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.11401 · Cited by 3,101
Enhancing the explanatory power of usability heuristics
Nielsen, J. (1994) · Proceedings of the SIGCHI Conference on Human Factors in Computing Systems · doi:10.1145/191666.191729 · Cited by 1,439
Chen, J., Xiao, S., Zhang, P., Luo, K., Lian, D., & Liu, Z. (2024) · Findings of the Association for Computational Linguistics ACL 2024 · doi:10.18653/v1/2024.findings-acl.137 · Cited by 757
MTEB: Massive Text Embedding Benchmark
Muennighoff, N., Tazi, N., Magne, L., & Reimers, N. (2023) · Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.148 · Cited by 548
Grattafiori, A., Dubey, A., Jauhri, A., Pandey, A., Kadian, A., Al-Dahle, A., Letman, A., Mathur, A., Schelten, A., Vaughan, A., et al. (2024) · arXiv · doi:10.48550/arxiv.2407.21783 · Cited by 505
Self-citationjina-embeddings-v3: Multilingual Embeddings With Task LoRAPreprint
Sturua, S., Mohr, I., Akram, M. K., Günther, M., Wang, B., Krimmel, M., Wang, F., Mastrapas, G., Koukounas, A., Wang, N., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.10173 · Cited by 267
Enabling Large Language Models to Generate Text with Citations
Gao, T., Yen, H., Yu, J., & Chen, D. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.398 · Cited by 216
OpenAI, :, Hurst, A., Lerer, A., Goucher, A. P., Perelman, A., Ramesh, A., Clark, A., Ostrow, A., Welihinda, A., et al. (2024) · arXiv · Cited by 180
Text Embeddings by Weakly-Supervised Contrastive Pre-training
Wang, L., Yang, N., Huang, X., Jiao, B., Yang, L., Jiang, D., Majumder, R., & Wei, F. (2022) · arXiv · doi:10.48550/arxiv.2212.03533 · Cited by 135
Asai, A., Wu, Z., Wang, Y., Sil, A., & Hajishirzi, H. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.11511 · Cited by 101
Matryoshka Representation Learning
Kusupati, A., Bhatt, G., Rege, A., Wallingford, M., Sinha, A., Ramanujan, V., Howard-Snyder, W., Chen, K., Kakade, S., Jain, P., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2192 · Cited by 90
GISTEmbed: Guided In-sample Selection of Training Negatives for Text Embedding Fine-tuningPreprint
Solatorio, A. V. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.16829 · Cited by 85
Chen, J., Xiao, S., Zhang, P., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.03216 · Cited by 65
The Semantic Scholar Open Data Platform
Kinney, R., Anastasiades, C., Authur, R., Beltagy, I., Bragg, J., Buraczynski, A., Cachola, I., Candra, S., Chandrasekhar, Y., Cohan, A., et al. (2023) · arXiv · doi:10.48550/arxiv.2301.10140 · Cited by 64
Self-citationLanguage agents achieve superhuman synthesis of scientific knowledge
Skarlinski, M. D., Cox, S., Laurent, J. M., Braza, J. D., Hinks, M., Hammerling, M. J., Ponnapati, M., Rodriques, S. G., & White, A. D. (2024) · arXiv · doi:10.48550/arxiv.2409.13740 · Cited by 49
Assisting in Writing Wikipedia-like Articles From Scratch with Large Language Models
Shao, Y., Jiang, Y., Kanell, T., Xu, P., Khattab, O., & Lam, M. (2024) · Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2024.naacl-long.347 · Cited by 41
Yan, X., Feng, S., Yuan, J., Xia, R., Wang, B., Bai, L., & Zhang, B. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.609 · Cited by 41
ArxivDIGESTables: Synthesizing Scientific Literature into Tables using Language Models
Newman, B., Lee, Y., Naik, A., Siangliulue, P., Fok, R., Kim, J., Weld, D. S., Chang, J. C., & Lo, K. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.538 · Cited by 19
Self-citationAttribute First, then Generate: Locally-attributable Grounded Text Generation
Slobodkin, A., Hirsch, E., Cattan, A., Schuster, T., & Dagan, I. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.182 · Cited by 17
SparseEmbed: Learning Sparse Lexical Representations with Contextual Embeddings for Retrieval
Kong, W., Dudek, J. M., Li, C., Zhang, M., & Bendersky, M. (2023) · Proceedings of the 46th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3539618.3592065 · Cited by 14
Assisting in Writing Wikipedia-like Articles From Scratch with Large Language Models
Shao, Y., Jiang, Y., Kanell, T. A., Xu, P., Khattab, O., & Lam, M. S. (2024) · arXiv · doi:10.48550/arxiv.2402.14207 · Cited by 10
From Hypothesis to Publication: A Comprehensive Survey of AI-Driven Research Support Systems
Zhou, Z., Feng, X., Huang, L., Feng, X., Song, Z., Chen, R., Zhao, L., Ma, W., Gu, Y., Wang, B., et al. (2025) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2025.findings-emnlp.631 · Cited by 8
OpenScholar: Synthesizing Scientific Literature with Retrieval-augmented LMs
Asai, A., He, J., Shao, R., Shi, W., Singh, A., Chang, J. C., Lo, K., Soldaini, L., Feldman, S., D'arcy, M., et al. (2024) · arXiv · Cited by 7
Self-citationMatryoshka Representation Learning
Kusupati, A., Bhatt, G., Rege, A., Wallingford, M., Sinha, A., Ramanujan, V., Howard-Snyder, W., Chen, K., Kakade, S., Jain, P., et al. (2022) · arXiv · doi:10.48550/arxiv.2205.13147
Research works printed but not linked: 1
- Shubham Agarwal, Gaurav Sahu, Abhay Puri, Is- sam Hadj Laradji, Krishnamurthy Dj Dvijotham, Ja- son Stanley, Laurent Charlin, and Christopher Pal. 2024. Litllms, llms for literature review: Are we there yet? Anthropic. 2024. The claude 3 model family: Opus, sonnet, haiku. Anthropic. 2025. Claude 3.7 sonnet system card.
Cited by
Sorted by citations
DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep ResearchPreprint
Shao, R., Asai, A., Shen, S. Z., Ivison, H., Kishore, V., Zhuo, J., Zhao, X., Park, M., Finlayson, S. G., Sontag, D. A., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2511.19399 · Cited by 129
Yifei, L. S., Chang, A., Malaviya, C., & Yatskar, M. (2026) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl.a.732 · Cited by 43
A Survey of Model Architectures in Information RetrievalPreprint
Xu, Z., Mo, F., Huang, Z., Zhang, C., Yu, P., Wang, B., Lin, J., & Srikumar, V. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.14822 · Cited by 40
AI-Assisted Tools for Scientific Review Writing: Opportunities and Cautions
da Silva, J. J. G., Gouveia, R. P., Zielinski, K., de Oliveira, M. C. F., Amancio, D. R., Bruno, O. M., & Oliveira, O. N. (2025) · ACS Applied Materials & Interfaces · doi:10.1021/acsami.5c08837 · Cited by 30
AI4Research: a survey of artificial intelligence for scientific research
Chen, Q., Yang, M., Qin, L., Liu, J., Yan, Z., Guan, J., Peng, D., Ji, Y., Li, H., Hu, M., et al. (2026) · Science China Information Sciences · doi:10.1007/s11432-025-5000-y · Cited by 4
Metadata
- Authors
- Singh, A., Chang, J. C., Haddad, D., Naik, A., Hwang, J. D., Kinney, R., Weld, D. S., Downey, D., & Feldman, S.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- ORCID
- Venue
- Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 3: System Demonstrations)
- Published
- 2025
- Pages
- 513-523
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W4412886885
- Semantic Scholar
- 563c61639fb1a5a0d68ee429687f9b51d6c40654
- Cited by
- 19
- References
- 5
- Citations by year
- 2026: 13 · 2025: 6
- FWCI
- 6.99
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Health Sciences › Medicine › Health Informatics › Biomedical Text Mining and Ontologies
- Keywords
- question answering, literature synthesis, attribution, AI-assisted research, scientific information retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
