

The DOI matches its Crossref record; 2 of the 2 references it cites were found in a registry or an index.
The Partial Information Decomposition of Generative Neural Network Models
Abstract
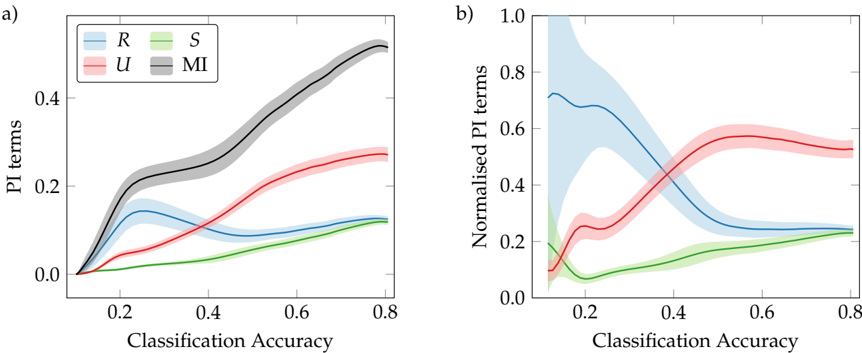
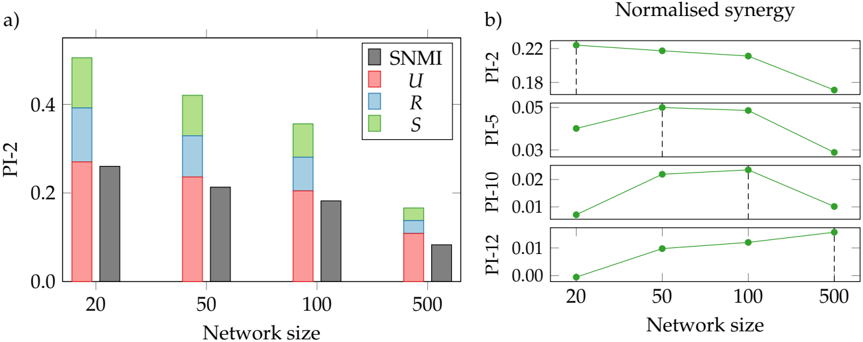
In this work we study the distributed representations learnt by generative neural network models. In particular, we investigate the properties of redundant and synergistic information that groups of hidden neurons contain about the target variable. To this end, we use an emerging branch of information theory called partial information decomposition (PID) and track the informational properties of the neurons through training. We find two differentiated phases during the training process: a first short phase in which the neurons learn redundant information about the target, and a second phase in which neurons start specialising and each of them learns unique information about the target. We also find that in smaller networks individual neurons learn more specific information about certain features of the input, suggesting that learning pressure can encourage disentangled representations.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“our work could be readily applied more widely, as PID using the discrete or Gaussian estimators studied here are often employed in real-data analyses in non-neuroscience fields”
From Sampling bias corrections for discrete and Gaussian partial information decompositions (2026) · cites this paper as [102]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Building machines that learn and think like people
Lake, B. M., Ullman, T. D., Tenenbaum, J. B., & Gershman, S. J. (2017) · Behavioral and Brain Sciences · doi:10.1017/s0140525x16001837 · Cited by 2,550
Keeping the neural networks simple by minimizing the description length of the weights
Hinton, G. E., & van Camp, D. (1993) · Proceedings of the sixth annual conference on Computational learning theory - COLT '93 · doi:10.1145/168304.168306 · Cited by 994
Research works printed but not linked: 35
- Srivastava, 2014, Dropout: A Simple Way to Prevent Neural Networks from Overfitting, J. Mach. Learn. Res., 15, 1929
- Gal, Y., and Ghahramani, Z. (2015). Dropout as a Bayesian Approximation: Representing Model Uncertainty in Deep Learning. arXiv.
- Bengio, Y., Courville, A., and Vincent, P. (2012). Representation Learning: A Review and New Perspectives. arXiv.
- Higgins, I., Matthey, L., Glorot, X., Pal, A., Uria, B., Blundell, C., Mohamed, S., and Lerchner, A. (2016). Early Visual Concept Learning with Unsupervised Deep Learning. arXiv.
- Mathieu, M., Zhao, J., Sprechmann, P., Ramesh, A., and LeCun, Y. (2016). Disentangling Factors of Variation in Deep Representations Using Adversarial Training. arXiv.
- Siddharth, N., Paige, B., Van de Meent, J.W., Desmaison, A., Wood, F., Goodman, N.D., Kohli, P., and Torr, P.H.S. (2017). Learning Disentangled Representations with Semi-Supervised Deep Generative Models. arXiv.
- Garnelo, M., Arulkumaran, K., and Shanahan, M. (2016). Towards Deep Symbolic Reinforcement Learning. arXiv.
- Williams, P.L., and Beer, R.D. (2010). Nonnegative Decomposition of Multivariate Information. arXiv.
- Rieke, F., Bialek, W., Warland, D., and de Ruyter van Steveninck, R. (1997). Spikes: Exploring the Neural Code, MIT Press.
- Le, Q.V., Ranzato, M., Monga, R., Devin, M., Chen, K., Corrado, G.S., Dean, J., and Ng, A.Y. (2011). Building High-Level Features Using Large Scale Unsupervised Learning. arXiv.
- Zeiler, M.D., and Fergus, R. (2014, January 6–12). Visualizing and Understanding Convolutional Networks. Proceedings of the European Conference on Computer Vision, Zurich, Switzerland. · DOI · Paper page
- Choromanska, A., Henaff, M., Mathieu, M., Arous, G.B., and LeCun, Y. (2014). The Loss Surfaces of Multilayer Networks. arXiv.
- Kawaguchi, K. (2016). Deep Learning Without Poor Local Minima. arXiv.
- Sørngård, B. (2014). Information Theory for Analyzing Neural Networks. [Master’s Thesis, Norwegian University of Science and Technology].
- Schwartz-Ziv, R., and Tishby, N. (2017). Opening the Black Box of Deep Neural Networks via Information. arXiv.
- Achille, A., and Soatto, S. (2017). On the Emergence of Invariance and Disentangling in Deep Representations. arXiv. · DOI
- Tishby, N., and Zaslavsky, N. (2015). Deep Learning and the Information Bottleneck Principle. arXiv. · DOI
- Berglund, 2015, Measuring the Usefulness of Hidden Units in Boltzmann Machines with Mutual Information, Neural Netw., 64, 12, 10.1016/j.neunet.2014.09.004 · DOI
- Balduzzi, D., Frean, M., Leary, L., Lewis, J., Ma, K.W.D., and McWilliams, B. (2017). The Shattered Gradients Problem: If Resnets are the Answer, Then What is the Question?. arXiv.
- Smolensky, P. (1986). Information Processing in Dynamical Systems: Foundations of Harmony Theory, MIT Press. Technical Report, DTIC Document.
- Larochelle, H., and Bengio, Y. (2008, January 5–9). Classification Using Discriminative Restricted Boltzmann Machines. Proceedings of the 25th International Conference on Machine Learning, Helsinki, Finland. · DOI
- Hinton, 2006, A Fast Learning Algorithm for Deep Belief Nets, Neural Comput., 18, 1527, 10.1162/neco.2006.18.7.1527 · DOI · Paper page
- Tieleman, T. (2008, January 5–9). Training Restricted Boltzmann Machines Using Approximations to the Likelihood Gradient. Proceedings of the 25th International Conference on Machine Learning, Helsinki, Finland. · DOI
- Cover, T.M., and Thomas, J.A. (2006). Elements of Information Theory, Wiley. · DOI · Paper page
- DeWeese, 1999, How to Measure the Information Gained from one Symbol, Netw. Comput. Neural Syst., 12, 325, 10.1088/0954-898X_10_4_303 · DOI
- Ince, R.A.A. (2017). Measuring Multivariate Redundant Information with Pointwise Common Change in Surprisal. Entropy, 19. · DOI
- Griffith, 2015, Quantifying Redundant Information in Predicting a Target Random Variable, Entropy, 17, 4644, 10.3390/e17074644 · DOI
- Harder, M., Salge, C., and Polani, D. (2013). Bivariate Measure of Redundant Information. Phys. Rev. E, 87. · DOI
- Gilbert, T., Kirkilionis, M., and Nicolis, G. Shared Information—New Insights and Problems in Decomposing Information in Complex Systems. Proceedings of the European Conference on Complex Systems 2012.
- Williams, P.L. (2011). Information Dynamics: Its Theory and Application to EmbodiedCognitive Systems. [Ph.D. Thesis, Indiana University].
- Lizier, J.T. (2010). The Local Information Dynamics of Distributed Computation in Complex Systems, Springer.
- Timme, 2014, Synergy, Redundancy, and Multivariate Information Measures: An Experimentalist’s Perspective, J. Comput. Neurosci., 36, 119, 10.1007/s10827-013-0458-4 · DOI
- Bertschinger, 2014, Quantifying Unique Information, Entropy, 16, 2161, 10.3390/e16042161 · DOI · Paper page
- Ay, 2015, Geometry and Expressive Power of Conditional Restricted Boltzmann Machines, J. Mach. Learn. Res., 16, 2405
- Kingma, D.P., and Welling, M. (2013). Auto-Encoding Variational Bayes. arXiv.
Cited by
Sorted by citations
Sampling bias corrections for discrete and Gaussian partial information decompositions
Lorenz, G. M., Engel, N. M., Koçillari, L., Celotto, M., Orsenigo, D., Curreli, S., Malerba, S. B., Engel, A. K., Kayser, C., Fellin, T., et al. (2026) · Patterns · doi:10.1016/j.patter.2026.101619 · Cited by 9
Metadata
- Authors
- Tax, T., Mediano, P., & Shanahan, M.
- Affiliations
- Corti, Nørrebrogade 45E 2, 2200 Copenhagen N, Denmark
- Department of Computing, Imperial College London, London SW7 2RH, UK
- Venue
- Entropy
- Publisher
- MDPI AG
- Published
- 2017-09-06
- Volume
- 19
- Issue
- 9
- Pages
- 474
- ISSN
- 1099-4300
- Cited by
- 55
- References
- 2
- Language
- en
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
