

Feature Importance in Gradient Boosting Trees with Cross-Validation Feature Selection
Open accessThe DOI matches its Crossref record; 37 of the 39 references it cites were found in a registry or an index.
Abstract
Gradient Boosting Machines (GBM) are among the go-to algorithms on tabular data, which produce state-of-the-art results in many prediction tasks. Despite its popularity, the GBM framework suffers from a fundamental flaw in its base learners. Specifically, most implementations utilize decision trees that are typically biased towards categorical variables with large cardinalities. The effect of this bias was extensively studied over the years, mostly in terms of predictive performance. In this work, we extend the scope and study the effect of biased base learners on GBM feature importance (FI) measures. We demonstrate that although these implementation demonstrate highly competitive predictive performance, they still, surprisingly, suffer from bias in FI. By utilizing cross-validated (CV) unbiased base learners, we fix this flaw at a relatively low computational cost. We demonstrate the suggested framework in a variety of synthetic and real-world setups, showing a significant improvement in all GBM FI measures while maintaining relatively the same level of prediction accuracy.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
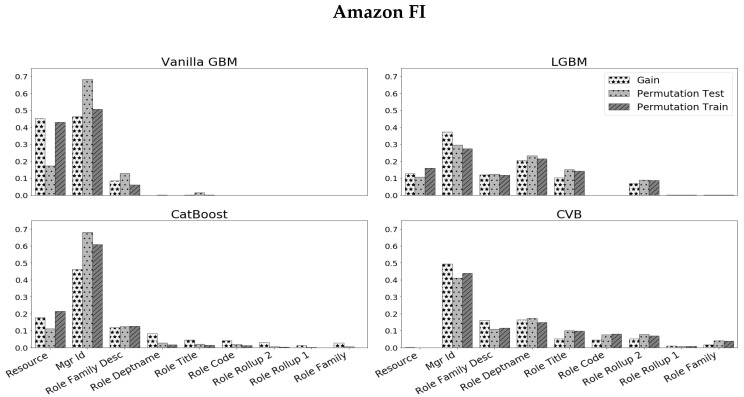
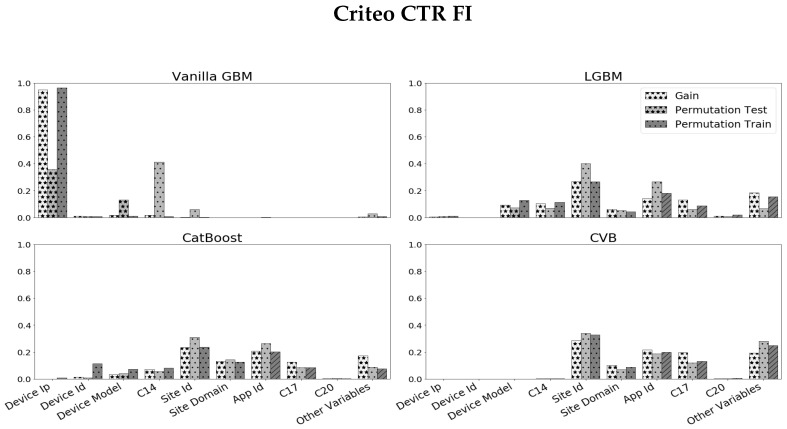
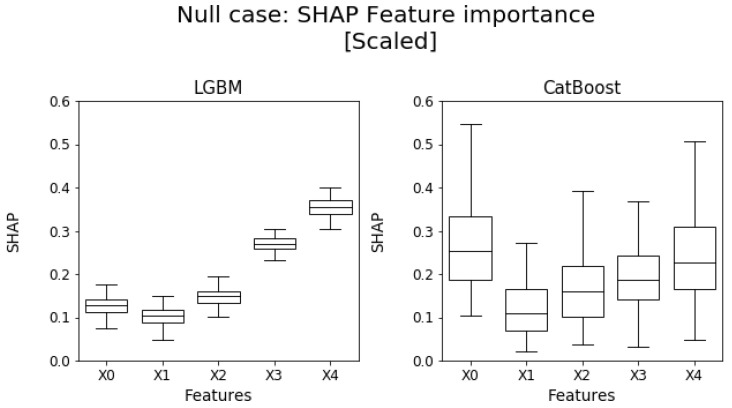
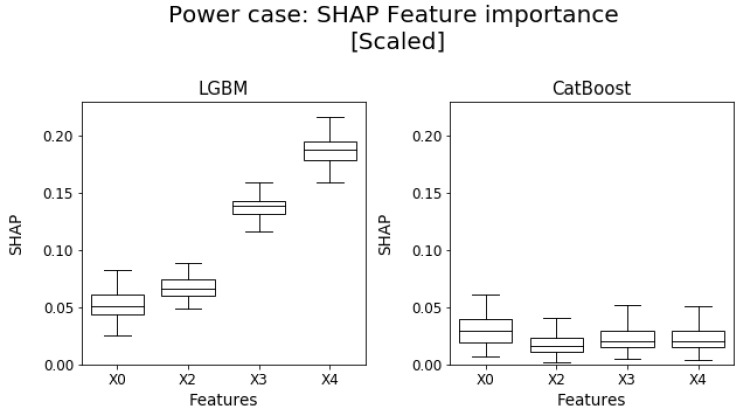
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“We also kept the top 3 edges for each downstream gene to reduce any gene specific bias caused by feature importance.81”
From SCING: Inference of robust, interpretable gene regulatory networks from single cell and spatial transcriptomics (2023) · cites this paper as [81]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Breiman, L. (2001) · Machine Learning · doi:10.1023/a:1010933404324 · Cited by 133,538
XGBoost: A Scalable Tree Boosting System
Chen, T., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939785 · Cited by 54,569
Greedy function approximation: A gradient boosting machine
Friedman, J. H. (2001) · The Annals of Statistics · doi:10.1214/aos/1013203451 · Cited by 30,731 · cited 4×
“GBM (Friedman, 2001) is an ensemble of base (weak) learners.”
BackgroundInfluentialA Unified Approach to Interpreting Model Predictions
Lundberg, S., & Lee, S.-I. (2017) · arXiv · doi:10.48550/arxiv.1705.07874 · Cited by 23,707
Quinlan, J. R. (1986) · Machine Learning · doi:10.1007/bf00116251 · Cited by 21,439
"Why Should I Trust You?": Explaining the Predictions of Any Classifier
Ribeiro, M. T., Singh, S., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939778 · Cited by 17,555
Breiman, L. (1996) · Machine Learning · doi:10.1007/bf00058655 · Cited by 16,325
Gauriat, C.-M., Pencolé, Y., Ribot, P., & Brouillet, G. (2024) · HAL (Le Centre pour la Communication Scientifique Directe) · doi:10.4230/oasics.dx.2024.27 · Cited by 12,586
LightGBM: A Highly Efficient Gradient Boosting Decision Tree
(2017) · HAL · Cited by 10,512
He, H., & Garcia, E. A. (2009) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2008.239 · Cited by 10,359 · cited 2×
“We randomly sample 30,000 observations, such that half of them have a positive label and the others are negative (following [37]).”
BackgroundMethod
Research works printed but not linked: 1
- Loh, 2002, Regression tress with unbiased variable selection and interaction detection, Stat. Sin., 12, 361
Cited by
Chiu, C., Wu, C.-M., Chien, T.-N., Kao, L., Li, C., & Chu, C.-M. (2023) · International Journal of Environmental Research and Public Health · doi:10.3390/ijerph20054340 · Cited by 57
Efficient permutation testing of variable importance measures by the example of random forests
Hapfelmeier, A., Hornung, R., & Haller, B. (2023) · Computational Statistics & Data Analysis · doi:10.1016/j.csda.2022.107689 · Cited by 47
Yin, H., Wang, K., Yang, R., Tan, Y., Li, Q., Zhu, W., & Sung, S. (2024) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2023.108005 · Cited by 40
Machine Learning-Based Crop Stress Detection in Greenhouses
Elvanidi, A., & Katsoulas, N. (2022) · Plants · doi:10.3390/plants12010052 · Cited by 39
Debiasing SHAP scores in random forests
Loecher, M. (2023) · AStA Advances in Statistical Analysis · doi:10.1007/s10182-023-00479-7 · Cited by 40
Metadata
- Authors
- Adler, A. I., & Painsky, A.
- Affiliations
- Tel Aviv University (IL)
- Corresponding author
- Painsky, Amichai
- ORCID
- Painsky, Amichai
- Venue
- Entropy
- Publisher
- MDPI AG
- Published
- 2022-05-13
- Volume
- 24
- Issue
- 5
- Pages
- 687
- ISSN
- 1099-4300 (ISSN-L)
- PMC
- PMC9140774
- OpenAlex
- W3200824799
- Cited by
- 149
- References
- 39
- Citations by year
- 2026: 35 · 2025: 59 · 2024: 32 · 2023: 18 · 2022: 5
- FWCI
- 9.38
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Entropy (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Explainable Artificial Intelligence (XAI)
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Data Classification
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods and Inference
- Keywords
- gradient boosting, feature importance, categorical variables, decision tree, tabular data
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Feature Importance in Gradient Boosting Trees with Cross-Validation Feature Selection. https://app.cochat.ai/papers/10.3390/e24050687
- The paper
- Adler, A. I., & Painsky, A. (2022). Feature Importance in Gradient Boosting Trees with Cross-Validation Feature Selection. Entropy. https://doi.org/10.3390/e24050687
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
