

The DOI matches its Crossref record; 73 of the 74 references it cites were found in a registry or an index; none of the 2 sources its claims cite is checked for support yet.
Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance
Open accessAbstract
This paper summarizes in depth the state of the art of aerial swarms, covering both classical and new reinforcement-learning-based approaches for their management. Then, it proposes a hybrid AI system, integrating deep reinforcement learning in a multi-agent centralized swarm architecture. The proposed system is tailored to perform surveillance of a specific area, searching and tracking ground targets, for security and law enforcement applications. The swarm is governed by a central swarm controller responsible for distributing different search and tracking tasks among the cooperating UAVs. Each UAV agent is then controlled by a collection of cooperative sub-agents, whose behaviors have been trained using different deep reinforcement learning models, tailored for the different task types proposed by the swarm controller. More specifically, proximal policy optimization (PPO) algorithms were used to train the agents’ behavior. In addition, several metrics to assess the performance of the swarm in this application were defined. The results obtained through simulation show that our system searches the operation area effectively, acquires the targets in a reasonable time, and is capable of tracking them continuously and consistently.
Overview
CoChat Summary
TL;DR
The paper proposes a hybrid AI system for UAV swarm ground surveillance, combining a centralized rule-based swarm controller with deep reinforcement learning sub-agents for search, tracking, and obstacle avoidance. Simulation results show effective area search, reasonable target acquisition, and consistent tracking, with performance adapting to changing numbers of targets and UAVs.
Key findings
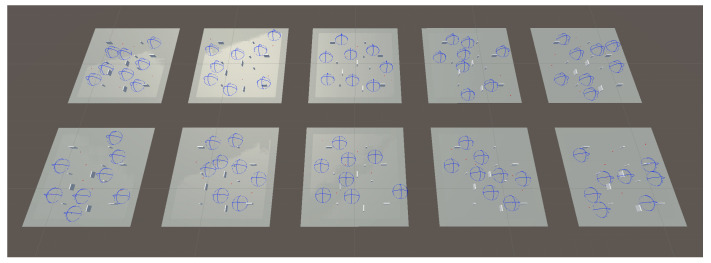
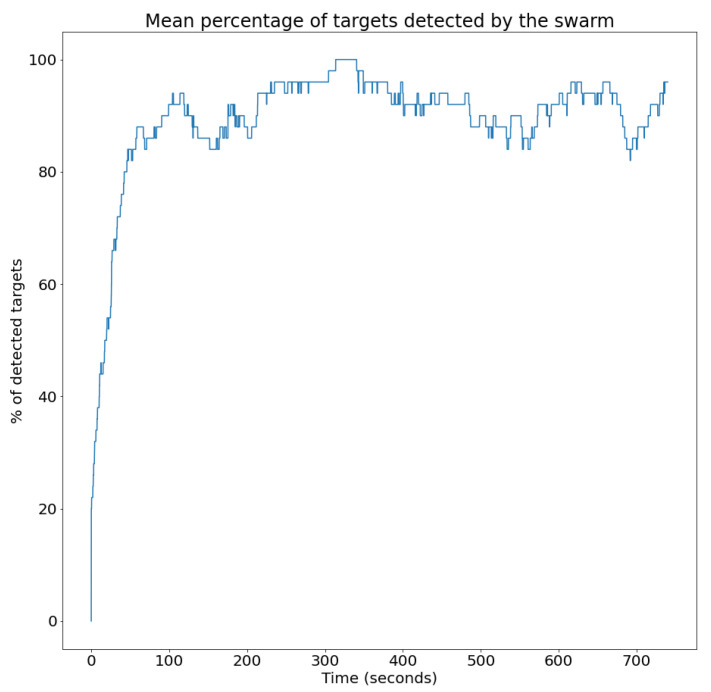
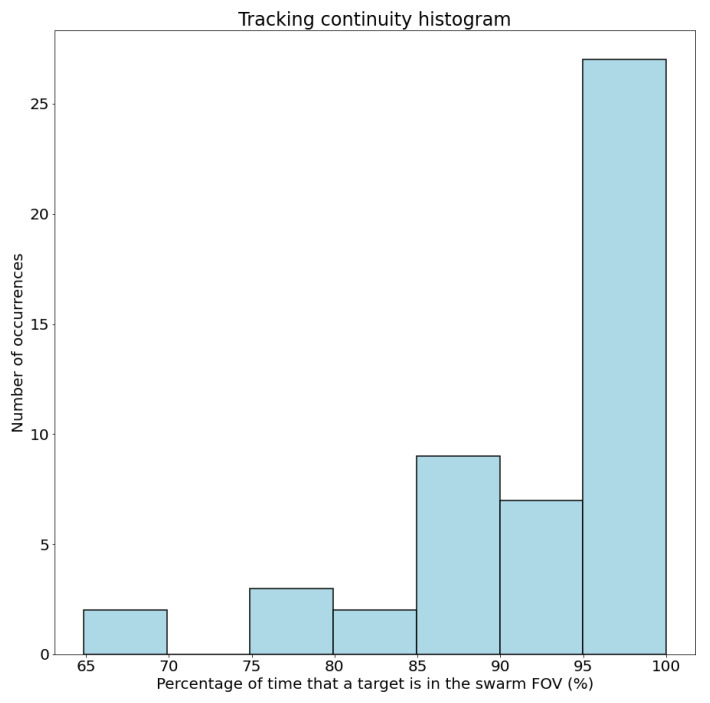
- In a baseline simulation with 8 fixed-wing UAVs tracking 5 targets over a 6 km × 6 km area, run 10 times, most targets were kept in the swarm’s field of view for over 95% of the time since first identification, though some losses occurred mainly due to occlusions behind obstacles.
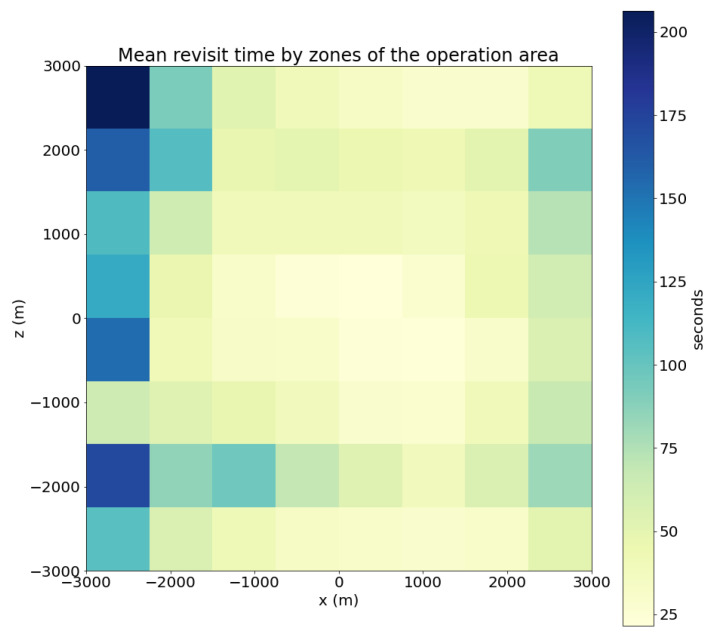
- Across 10 simulations totaling 50 targets, the swarm searched the operation area effectively, but border cells had higher revisit periods, indicating more difficulty exploring edges.
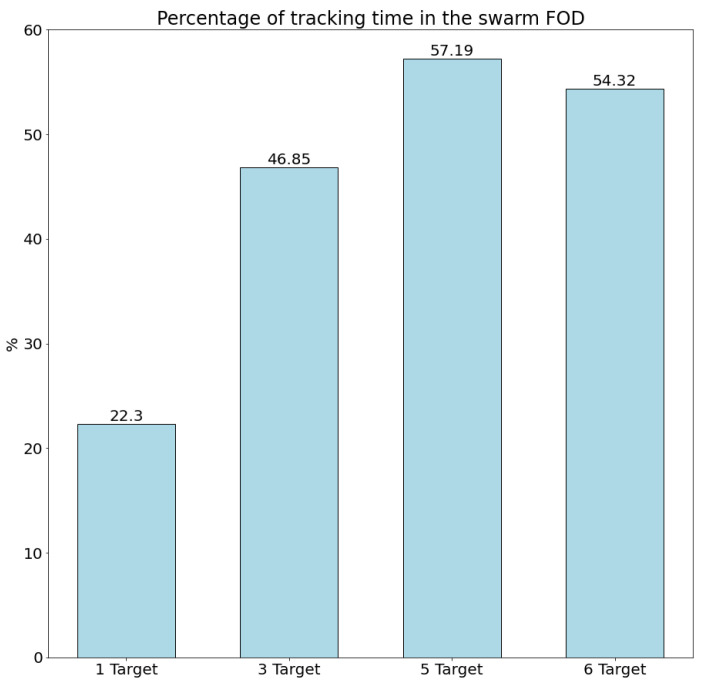
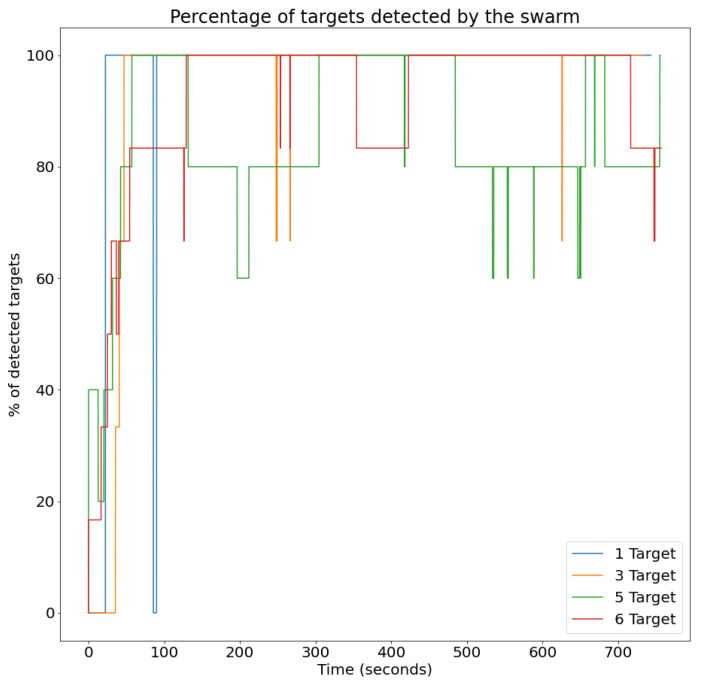
- With UAVs fixed at 8 and targets varied as 1, 3, 5, and 6, total search time generally increased with more targets, while the percentage of detected targets showed fewer differences because tracking is assigned to a single agent once a target is first detected.
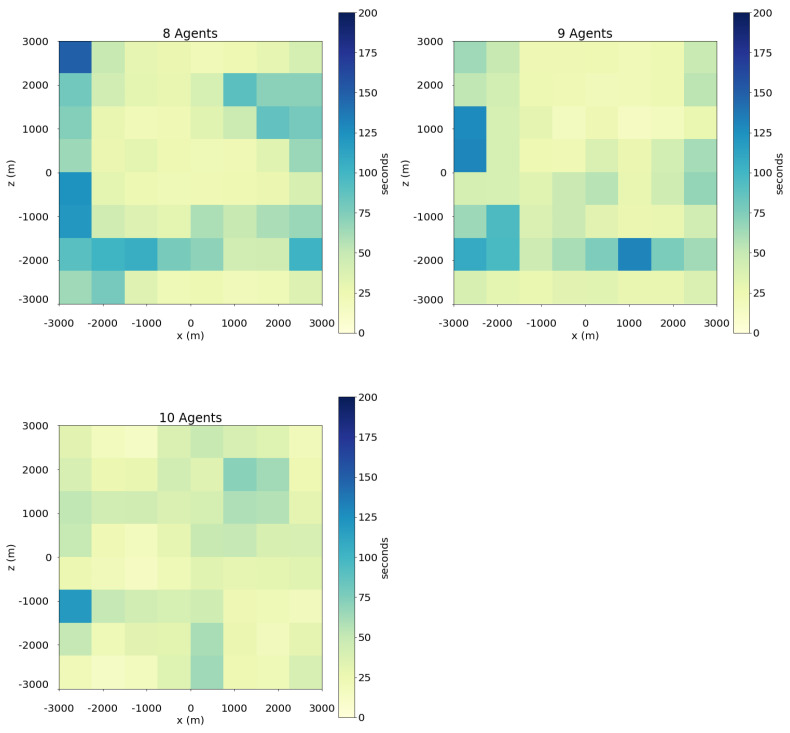
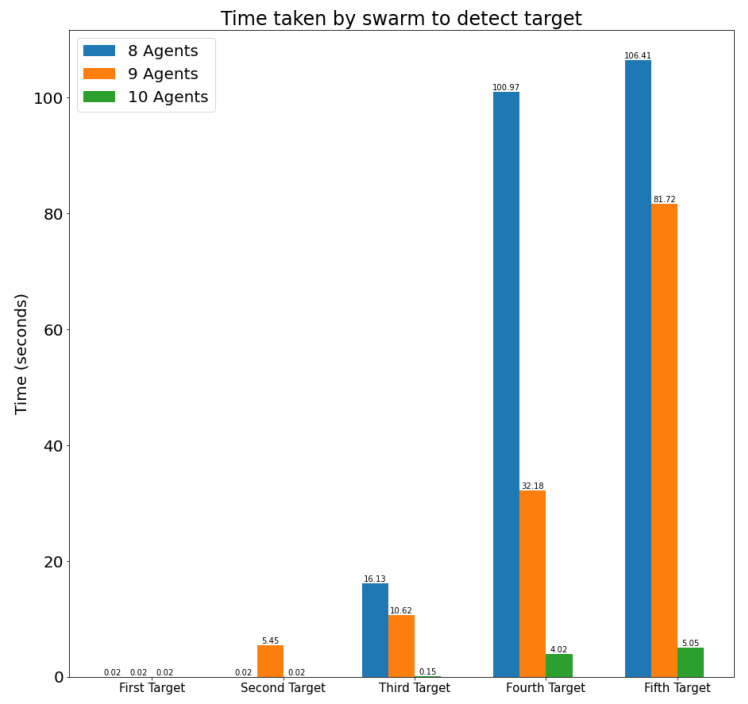
- With targets fixed at 5 and UAVs varied as 8, 9, and 10, increasing the number of UAVs significantly improved revisit time and reduced ordered target acquisition time.
Methods
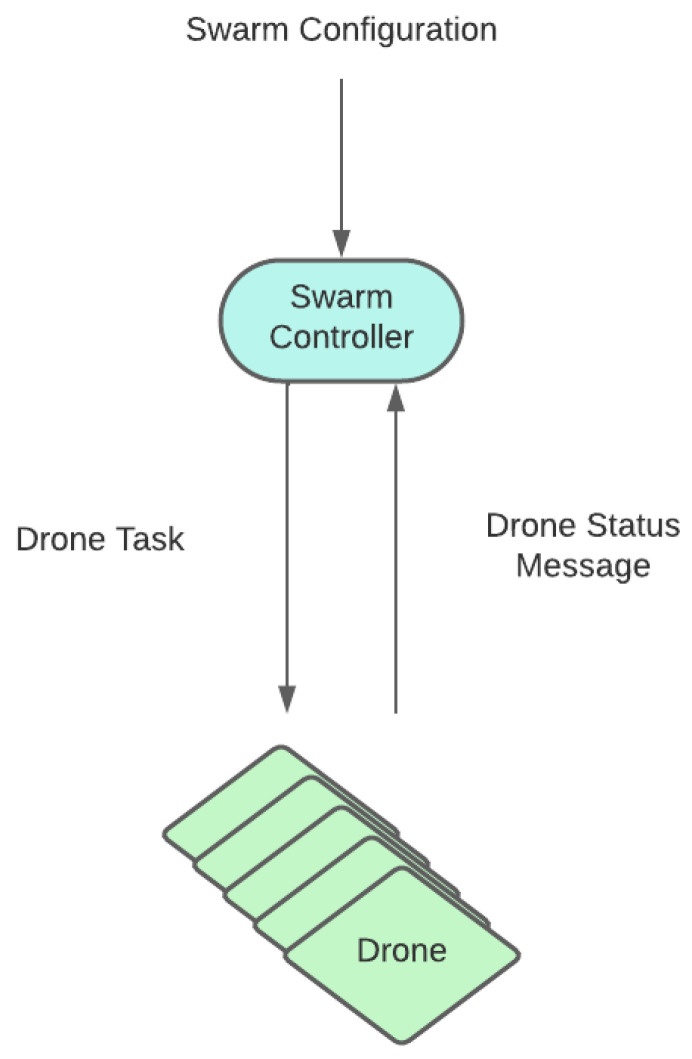
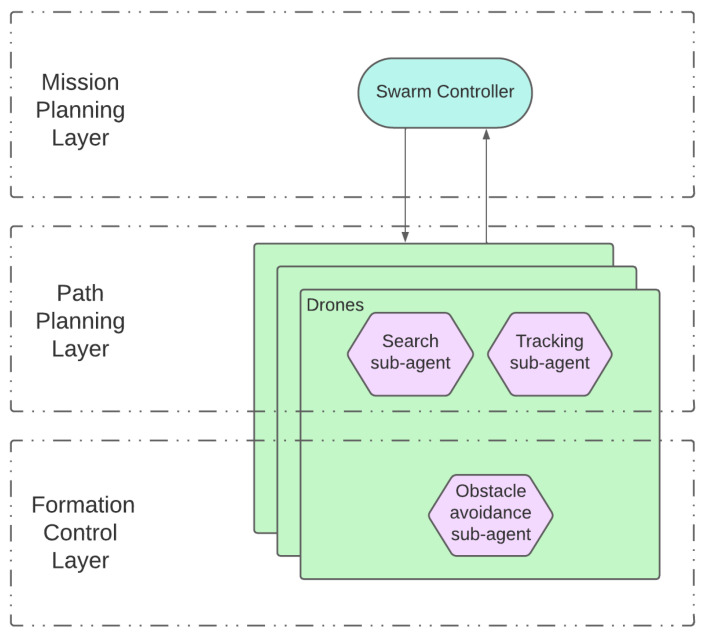
- The system uses a two-layer centralized architecture: a deterministic rule-based swarm controller assigns search and tracking tasks, while each UAV agent executes tasks through three cooperative DRL sub-agents for search, tracking, and obstacle avoidance.
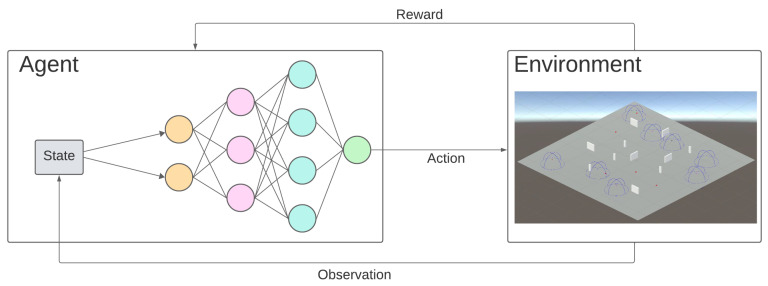
- The sub-agents were trained independently using proximal policy optimization (PPO) in Unity ML-Agents, with an artificial neural network having an input layer, two fully connected hidden layers of 128 neurons each, and an output layer.
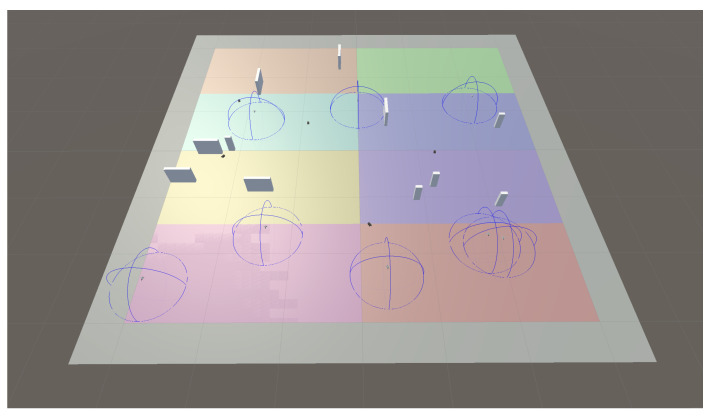
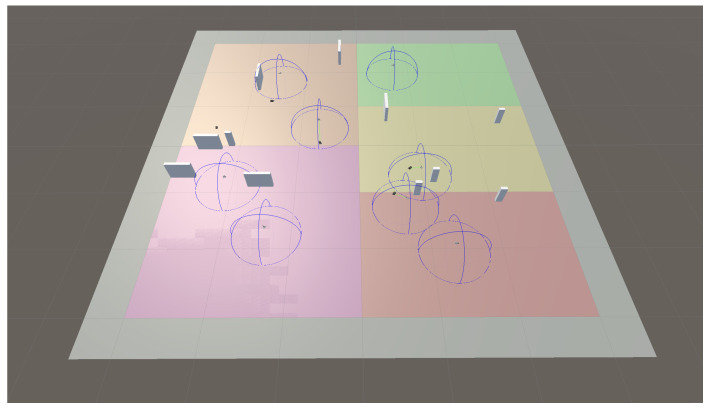
- Evaluation used simulation scenarios with a 6 km square operation area, fixed-wing UAVs at constant altitude, ground targets moving at 20 m/s, static obstacles, and metrics including revisit period, search time, percentage of detected targets, tracking continuity, and target acquisition time.
Limitations
- The paper states that RL-based approaches are expensive in computation, development time, and resources, and that training a swarm control system for an imminent mission with a specific or new scenario could be difficult.
- The paper states that performance strongly depends on the fidelity of training scenarios, that reward function design requires expert knowledge and many design iterations, and that there is no clear method for determining reward functions.
- Evident from the text: the study assumes perfect sensors, negligible navigation error, benign weather, fixed UAV altitude, and simulation-only validation; targets in the tracking training initially move at constant speed in straight lines, and the evaluation uses constant-speed targets.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
61 Own interpretation · 13 Own result · 2 No basis given · 1 No full text of the sources · 1 Not checked yet · 1 Own method
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The results obtained through simulation show that our system searches the operation area effectively, acquires the targets in a reasonable time, and is capable of tracking them continuously and consistently.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The results obtained through simulation show that our system searches the operation area effectively, acquires the targets in a reasonable time, and is capable of tracking them continuously and consistently.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The results obtained through simulation show that our system searches the operation area effectively, acquires the targets in a reasonable time, and is capable of tracking them continuously and consistently.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As for the percentage of detected targets, there are not so many differences between the four simulations since the tracking task is assigned to a single agent once the target is first detected.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > 4. Experiments and Results > 4.2. Simulation Scenarios and Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In conclusion, the metric that is most affected is the search time, which make logical sense given that the number of agents is fixed and the number of targets is modified.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > 4. Experiments and Results > 4.2. Simulation Scenarios and Results
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
24 more claims
Create a free account to see all 79 claims and to verify the 1 reference still open.
- The quote only partly states this claim. 1
- It may state two separate claims as one. 20
- Probably not a substantial claim. 41
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > 2. State of the Art > 2.2. Mission-Planning Layer
“In [15], simulated annealing (SA) is included in the inner loop of PSO to improve the local search and still preserve the fast convergence of PSO.”
§ Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance > 2. State of the Art > 2.2. Mission-Planning Layer
“Ref. [15] uses SA as the external part of a particle swarm optimization (PSO).”
Citations
Cites
Kennedy, J., & Eberhart, R. (2002) · Proceedings of ICNN'95 - International Conference on Neural Networks · doi:10.1109/icnn.1995.488968 · Cited by 58,192
Optimization by Simulated Annealing
Kirkpatrick, S., Gelatt, C. D., & Vecchi, M. P. (1983) · Science · doi:10.1126/science.220.4598.671 · Cited by 45,134
Rapidly-exploring random trees : a new tool for path planning
LaValle, S. M. (1998) · Cited by 3,704
Roberge, V., Tarbouchi, M., & Labonté, G. (2012) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2012.2198665 · Cited by 1,070
Path Planning with Modified a Star Algorithm for a Mobile Robot
Duchoň, F., Babinec, A., Kajan, M., Beňo, P., Florek, M., Fico, T., & Jurišica, L. (2014) · Procedia Engineering · doi:10.1016/j.proeng.2014.12.098 · Cited by 901
Deep Reinforcement Learning: An Overview
Li, Y. (2017) · arXiv · doi:10.48550/arxiv.1701.07274 · Cited by 762
UAV path planning using artificial potential field method updated by optimal control theory
Chen, Y., Luo, G., Mei, Y., Yu, J., & Su, X. (2014) · International Journal of Systems Science · doi:10.1080/00207721.2014.929191 · Cited by 456
Pareto Optimality, Game Theory And Equilibria
Chinchuluun, A., Migdalas, A., Pardalos, P. M., & Pitsoulis, L. (2008) · Springer optimization and its applications · doi:10.1007/978-0-387-77247-9 · Cited by 437
Pan, Z., Zhang, C., Xia, Y., Xiong, H., & Shao, X. (2021) · IEEE Transactions on Circuits & Systems II Express Briefs · doi:10.1109/tcsii.2021.3112787 · Cited by 430
UAV Swarm Intelligence: Recent Advances and Future Trends
Zhou, Y., Rao, B., & Wang, W. (2020) · IEEE Access · doi:10.1109/access.2020.3028865 · Cited by 373
Research works printed but not linked: 2
- Schulman, J., Wolski, F., Dhariwal, P., Radford, A., and Klimov, O. (2017). Proximal policy optimization algorithms. arXiv.
- Haarnoja, T., Zhou, A., Hartikainen, K., Tucker, G., Ha, S., Tan, J., and Levine, S. (2018). Soft actor-critic algorithms and applications. arXiv.
Cited by
Mustafa, R., Sarkar, N. I., Mohaghegh, M., & Pervez, S. (2025) · Drones · doi:10.3390/drones9040263 · Cited by 108
Almansor, M. J., Din, N. M., Baharuddin, M. Z., Ma, M., Alsayednoor, H. M., Al-Shareeda, . A., & Al-asadi, A. J. (2024) · Alexandria Engineering Journal · doi:10.1016/j.aej.2024.09.032 · Cited by 67
Computational offloading into UAV swarm networks: a systematic literature review
Baktayan, A. A., Zahary, A. T., Sikora, A., & Welte, D. (2024) · EURASIP Journal on Wireless Communications and Networking · doi:10.1186/s13638-024-02401-4 · Cited by 36
The Rise of UAV-Based Smart Surveillance: A Systematic Review of Trends and Technologies
Kumar, S., Tiwari, A., Ahirwar, Y., Kumar, G., & Arafat, M. Y. (2025) · IEEE Access · doi:10.1109/access.2025.3621736 · Cited by 30
Ye, Y., Min, X., Liu, X., Chen, X., Cao, K., Howlader, S. M. R. K., & Chen, X. (2025) · Sensors · doi:10.3390/s25216751 · Cited by 22
Metadata
- Authors
- Arranz, R., Carramiñana, D., Miguel, G. D., Besada, J. A., & Bernardos, A. M.
- Affiliations
- Information Processing and Telecommunications Center (ES)
- Information Processing and Telecommunications Center, Universidad Politécnica de Madrid, ETSI Telecomunicación, Av. Complutense 30, 28040 Madrid, Spain
- Corresponding author
- Bernardos, Ana M.
- Venue
- Sensors
- Publisher
- MDPI AG
- Published
- 2023-10-27
- Volume
- 23
- Issue
- 21
- Pages
- 8766
- ISSN
- 1424-8220 (ISSN-L)
- PMC
- PMC10648592
- OpenAlex
- W4387977146
- Semantic Scholar
- cfdeb972d25cf0eeba9bf73b4bea951d8b7dca6c
- Cited by
- 58
- References
- 72
- Citations by year
- 2026: 24 · 2025: 25 · 2024: 9
- FWCI
- 4.13
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Sensors (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Hispana (acceptedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by-nc-nd)
- Archivo Digital UPM (Universidad Politécnica de Madrid) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Funders
- MCIN/AEI/10.13039/501100011033 (PID2020-118249RB-C21, 101021797)
- European Union’s Horizon 2020 Research and Innovation Programme (PID2020-118249RB-C21, 101021797)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Reinforcement Learning in Robotics
- Physical Sciences › Engineering › Control and Systems Engineering › Distributed Control Multi-Agent Systems
- Physical Sciences › Engineering › Aerospace Engineering › UAV Applications and Optimization
- Keywords
- UAV swarms, aerial swarms, deep reinforcement learning, ground surveillance, proximal policy optimization, law enforcement, security applications
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance. https://app.cochat.ai/papers/10.3390/s23218766
- The paper
- Arranz, R., Carramiñana, D., Miguel, G. D., Besada, J. A., & Bernardos, A. M. (2023). Application of Deep Reinforcement Learning to UAV Swarming for Ground Surveillance. Sensors. https://doi.org/10.3390/s23218766
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
