

The DOI matches its DataCite record; 7 of the 7 references it cites were found in a registry or an index.
Sequence Modeling of Temporal Credit Assignment for Episodic Reinforcement Learning
Abstract
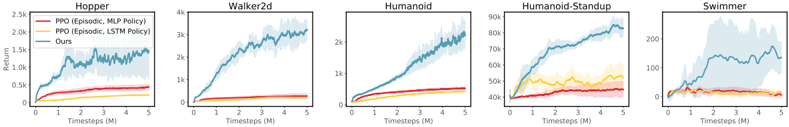
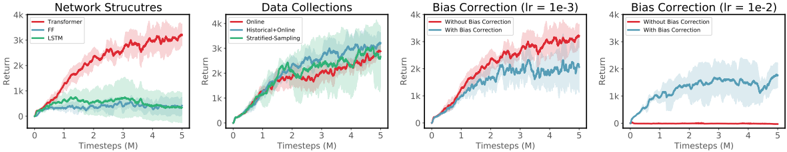
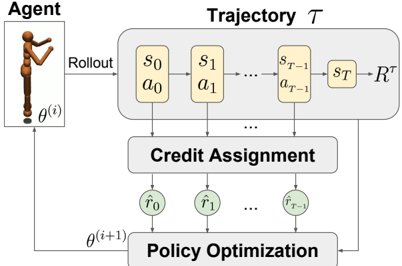
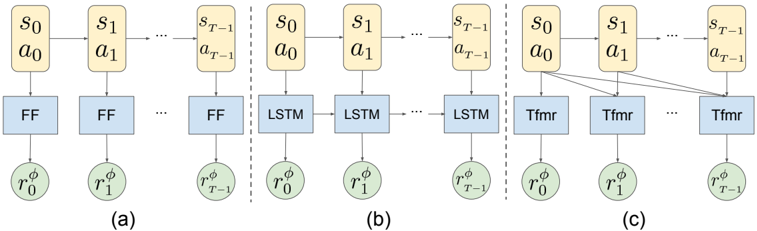
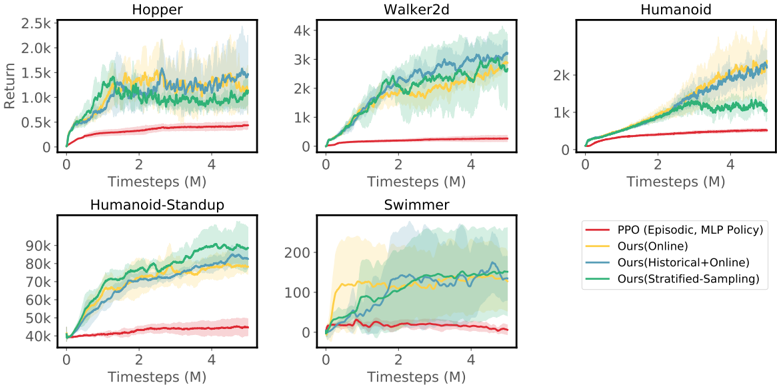
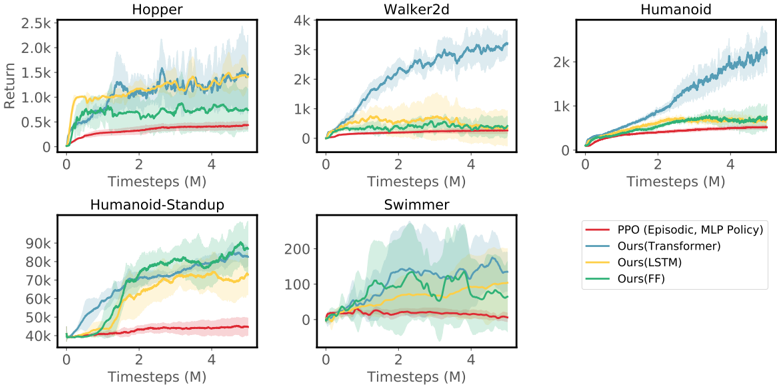
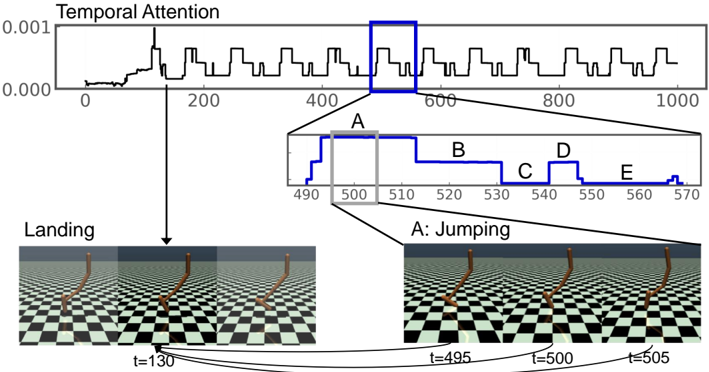
Recent advances in deep reinforcement learning algorithms have shown great potential and success for solving many challenging real-world problems, including Go game and robotic applications. Usually, these algorithms need a carefully designed reward function to guide training in each time step. However, in real world, it is non-trivial to design such a reward function, and the only signal available is usually obtained at the end of a trajectory, also known as the episodic reward or return. In this work, we introduce a new algorithm for temporal credit assignment, which learns to decompose the episodic return back to each time-step in the trajectory using deep neural networks. With this learned reward signal, the learning efficiency can be substantially improved for episodic reinforcement learning. In particular, we find that expressive language models such as the Transformer can be adopted for learning the importance and the dependency of states in the trajectory, therefore providing high-quality and interpretable learned reward signals. We have performed extensive experiments on a set of MuJoCo continuous locomotive control tasks with only episodic returns and demonstrated the effectiveness of our algorithm.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The terminal reward is the sum of the original Markov dense rewards.”
From When Do Transformers Shine in RL? Decoupling Memory from Credit Assignment (2023) · cites this paper as Liu et al., 2019
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Hochreiter, S., & Schmidhuber, J. (1997) · Neural Computation · doi:10.1162/neco.1997.9.8.1735 · Cited by 102,318
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Mastering the game of Go with deep neural networks and tree search
Silver, D., Huang, A., Maddison, C. J., Guez, A., Sifre, L., van den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M., et al. (2016) · Nature · doi:10.1038/nature16961 · Cited by 15,612
Proximal Policy Optimization Algorithms
Schulman, J., Wolski, F., Dhariwal, P., Radford, A., & Klimov, O. (2017) · arXiv · doi:10.48550/arxiv.1707.06347 · Cited by 10,625
A Structured Self-attentive Sentence Embedding
Lin, Z., Feng, M., Santos, C. N. D., Yu, M., Xiang, B., Zhou, B., & Bengio, Y. (2017) · arXiv · doi:10.48550/arxiv.1703.03130 · Cited by 1,743 · cited 1×
“The second part is a self-attention layer [22], which generates a set of summation weight vectors for the encoder outputs.”
BackgroundResource Management with Deep Reinforcement Learning
Mao, H., Alizadeh, M., Menache, I., & Kandula, S. (2016) · Proceedings of the 15th ACM Workshop on Hot Topics in Networks · doi:10.1145/3005745.3005750 · Cited by 1,353 · cited 1×
“…the well-known policy gradient algorithms [24, 31, 32] and deep Q-networks [25], have shown superior performance and great potential in many difficult real-world problems, such as the Go game [33, 34], locomotive continuous control problems [21], resource management [23], and robotics [20].”
Background
Research works printed but not linked: 36
- Pieter Abbeel and Andrew Y Ng. Apprenticeship learning via inverse reinforcement learning. In Proceedings of the twenty-first international conference on Machine learning, page 1. ACM, 2004.
- Marcin Andrychowicz, Filip Wolski, Alex Ray, Jonas Schneider, Rachel Fong, Peter Welinder, Bob McGrew, Josh Tobin, OpenAI Pieter Abbeel, and Wojciech Zaremba. Hindsight experience replay. In Advances in Neural Information Processing Systems, pages 5048-5058, 2017.
- Jose A Arjona-Medina, Michael Gillhofer, Michael Widrich, Thomas Unterthiner, and Sepp Hochreiter. Rudder: Return decomposition for delayed rewards. arXiv preprint arXiv:1806.07857, 2018. · arXiv
- Marc Bellemare, Sriram Srinivasan, Georg Ostrovski, Tom Schaul, David Saxton, and Remi Munos. Unifying count-based exploration and intrinsic motivation. In Advances in Neural Information Processing Systems, pages 1471-1479, 2016.
- Yoshua Bengio, Réjean Ducharme, Pascal Vincent, and Christian Jauvin. A neural probabilistic language model. Journal of machine learning research, 3(Feb):1137-1155, 2003.
- Greg Brockman, Vicki Cheung, Ludwig Pettersson, Jonas Schneider, John Schulman, Jie Tang, and Wojciech Zaremba. Openai gym. arXiv preprint arXiv:1606.01540, 2016. · arXiv
- Tanmay Gangwani, Qiang Liu, and Jian Peng. Learning self-imitating diverse policies. Pro- ceedings of the International Conference on Learning Representations (ICLR), 2019.
- Yijie Guo, Junhyuk Oh, Satinder Singh, and Honglak Lee. Generative adversarial self-imitation learning. arXiv preprint arXiv:1812.00950, 2018. · arXiv
- Dylan Hadfield-Menell, Smitha Milli, Pieter Abbeel, Stuart J Russell, and Anca Dragan. Inverse reward design. In Advances in Neural Information Processing Systems, pages 6765-6774, 2017.
- Nikolaus Hansen and Andreas Ostermeier. Completely derandomized self-adaptation in evolu- tion strategies. Evolutionary computation, 9(2):159-195, 2001.
- Nicolas Heess, Srinivasan Sriram, Jay Lemmon, Josh Merel, Greg Wayne, Yuval Tassa, Tom Erez, Ziyu Wang, Ali Eslami, Martin Riedmiller, et al. Emergence of locomotion behaviours in rich environments. arXiv preprint arXiv:1707.02286, 2017. · arXiv
- Rein Houthooft, Richard Y Chen, Phillip Isola, Bradly C Stadie, Filip Wolski, Jonathan Ho, and Pieter Abbeel. Evolved policy gradients. arXiv preprint arXiv:1802.04821, 2018. · arXiv
- Rein Houthooft, Xi Chen, Yan Duan, John Schulman, Filip De Turck, and Pieter Abbeel. Vime: Variational information maximizing exploration. In Advances in Neural Information Processing Systems, pages 1109-1117, 2016.
- Chia-Chun Hung, Timothy Lillicrap, Josh Abramson, Yan Wu, Mehdi Mirza, Federico Carnevale, Arun Ahuja, and Greg Wayne. Optimizing agent behavior over long time scales by transporting value. arXiv preprint arXiv:1810.06721, 2018. · arXiv
- Max Jaderberg, Volodymyr Mnih, Wojciech Czarnecki, Tom Schaul, Joel Z. Leibo, David Silver, and Koray Kavukcuoglu. Reinforcement learning with unsupervised auxiliary tasks. CoRR, abs/1611.05397, 2017. · arXiv
- Daniel Jurafsky and James H. Martin. Speech and Language Processing (2Nd Edition). Prentice- Hall, Inc., Upper Saddle River, NJ, USA, 2009.
- Nan Rosemary Ke, Anirudh Goyal, Olexa Bilaniuk, Jonathan Binas, Michael C. Mozer, Chris Pal, and Yoshua Bengio. Sparse attentive backtracking: Temporal credit assignment through reminding. In Proceedings of the 32Nd International Conference on Neural Information Processing Systems, NIPS'18, pages 7651-7662, USA, 2018.
- Sergey Levine, Chelsea Finn, Trevor Darrell, and Pieter Abbeel. End-to-end training of deep visuomotor policies. The Journal of Machine Learning Research, 17(1):1334-1373, 2016.
- Timothy P Lillicrap, Jonathan J Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yuval Tassa, David Silver, and Daan Wierstra. Continuous control with deep reinforcement learning. ICLR, 2016.
- Volodymyr Mnih, Adria Puigdomenech Badia, Mehdi Mirza, Alex Graves, Timothy Lilli- crap, Tim Harley, David Silver, and Koray Kavukcuoglu. Asynchronous methods for deep reinforcement learning. In International conference on machine learning, pages 1928-1937, 2016.
- Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Andrei A Rusu, Joel Veness, Marc G Bellemare, Alex Graves, Martin Riedmiller, Andreas K Fidjeland, Georg Ostrovski, et al. Human-level control through deep reinforcement learning. Nature, 518(7540):529, 2015.
- Andrew Y Ng, Daishi Harada, and Stuart Russell. Policy invariance under reward transfor- mations: Theory and application to reward shaping. In ICML, volume 99, pages 278-287, 1999.
- Marcus Olivecrona, Thomas Blaschke, Ola Engkvist, and Hongming Chen. Molecular de-novo design through deep reinforcement learning. Journal of cheminformatics, 9(1):48, 2017.
- Deepak Pathak, Pulkit Agrawal, Alexei A Efros, and Trevor Darrell. Curiosity-driven exploration by self-supervised prediction. In International Conference on Machine Learning (ICML), volume 2017, 2017.
- Reuven Rubinstein. The cross-entropy method for combinatorial and continuous optimization. Methodology and computing in applied probability, 1(2):127-190, 1999.
- Tim Salimans, Jonathan Ho, Xi Chen, Szymon Sidor, and Ilya Sutskever. Evolution strategies as a scalable alternative to reinforcement learning. arXiv preprint arXiv:1703.03864, 2017. · arXiv
- John Schulman, Philipp Moritz, Sergey Levine, Michael Jordan, and Pieter Abbeel. High- dimensional continuous control using generalized advantage estimation. Proceedings of the International Conference on Learning Representations (ICLR), 2016.
- David Silver, Julian Schrittwieser, Karen Simonyan, Ioannis Antonoglou, Aja Huang, Arthur Guez, Thomas Hubert, Lucas Baker, Matthew Lai, Adrian Bolton, et al. Mastering the game of go without human knowledge. Nature, 550(7676):354, 2017.
- Satinder Singh, Richard L Lewis, and Andrew G Barto. Where do rewards come from. In Proceedings of the annual conference of the cognitive science society, pages 2601-2606, 2009.
- Jonathan Sorg, Richard L Lewis, and Satinder P Singh. Reward design via online gradient ascent. In Advances in Neural Information Processing Systems, pages 2190-2198, 2010.
- Bradly C Stadie, Sergey Levine, and Pieter Abbeel. Incentivizing exploration in reinforcement learning with deep predictive models. arXiv preprint arXiv:1507.00814, 2015. · arXiv
- Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction. MIT press, 2018.
- Richard Stuart Sutton. Temporal Credit Assignment in Reinforcement Learning. PhD thesis, University of Massachusetts Amherst, 1984. AAI8410337.
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in Neural Informa- tion Processing Systems, pages 5998-6008, 2017.
- Ronald J Williams. Simple statistical gradient-following algorithms for connectionist reinforce- ment learning. Machine learning, 8(3-4):229-256, 1992.
- Zeyu Zheng, Junhyuk Oh, and Satinder Singh. On learning intrinsic rewards for policy gradient methods. In Advances in Neural Information Processing Systems, pages 4649-4659, 2018.
Cited by
When Do Transformers Shine in RL? Decoupling Memory from Credit Assignment
Ni, T., Ma, M., Eysenbach, B., & Bacon, P.-L. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-2194 · Cited by 7
Metadata
- Authors
- Liu, Y., Luo, Y., Zhong, Y., Chen, X., Liu, Q., & Peng, J.
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2019
- arXiv
- 1905.13420
- References
- 7
- Type
- Preprint
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
