

The DOI matches its DataCite record, with a small difference in title or year; the references it cites are not checked yet; none of the 43 sources its claims cite is checked for support yet.
Memformer: A Memory-Augmented Transformer for Sequence Modeling
Open accessAbstract
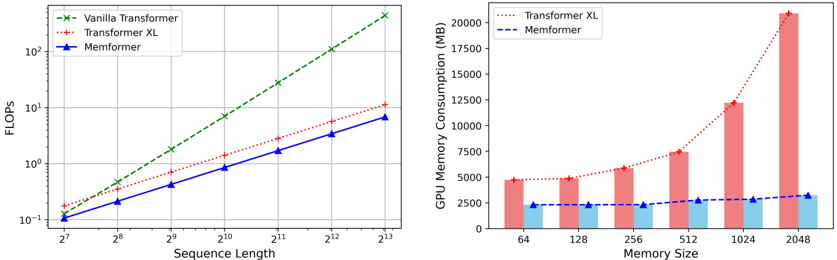
Transformers have reached remarkable success in sequence modeling. However, these models have efficiency issues as they need to store all the history token-level representations as memory. We present Memformer, an efficient neural network for sequence modeling, that utilizes an external dynamic memory to encode and retrieve past information. Our model achieves linear time complexity and constant memory space complexity when processing long sequences. We also propose a new optimization scheme, memory replay back-propagation (MRBP), which promotes long-range back-propagation through time with a significantly reduced memory requirement. Experimental results show that Memformer has achieved comparable performance compared to the baselines by using 8.1x less memory space and 3.2x faster on inference. Analysis of the attention pattern shows that our external memory slots can encode and retain important information through timesteps.
Checked 2026-11-14 · 4 references not checked yet
Overview
CoChat Summary
TL;DR
Memformer is a memory-augmented Transformer that uses fixed-size external dynamic memory and recurrence to model long sequences with linear time and constant memory complexity. It also introduces memory replay backpropagation (MRBP) to train recurrent memory with reduced memory cost, achieving comparable performance to Transformer-XL and Compressive Transformer on image generation and language modeling.
Key findings
- Memformer achieved comparable or better performance with much lower cost: on autoregressive MNIST image generation, Memformer (4 encoder + 8 decoder) reached perplexity 1.555 with 5.0B FLOPs, versus Transformer-XL with memory=784 at perplexity 1.611 with 49.1B FLOPs.
- On WikiText-103 language modeling, Memformer (4 encoder + 16 decoder, memory=1,024) reached perplexity 22.74 with 54B FLOPs, versus Transformer-XL memory=1,024 at perplexity 23.67 with 168B FLOPs.
- The paper reports Memformer uses 8.1x less memory space and is 3.2x faster on inference in its efficiency comparisons.
- MRBP reduced training GPU memory to 7,229 MB versus 16,177 MB for BPTT and 9,885 MB for gradient checkpointing, with relative speed x0.90 versus x1.00 for BPTT and x0.48 for gradient checkpointing.
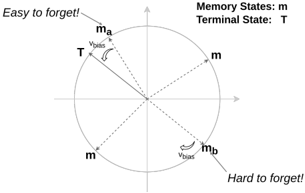
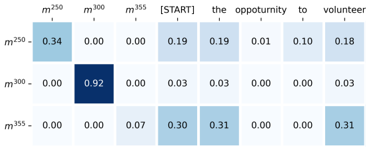
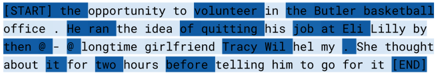
- Memory writer analysis found that around 60% to 80% of memory slots in the middle of a document attended mainly to themselves, while only 5% to 10% attended completely to input tokens later; one slot had forgetting bias magnitude 3.20 versus 1.15 for others.
Methods
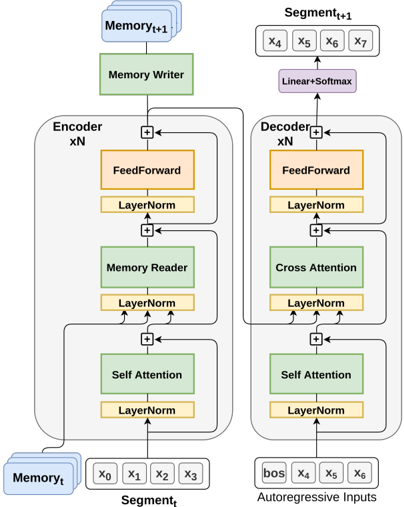
- Memformer processes sequences at the segment level with a Transformer encoder-decoder: the encoder reads from and writes to a fixed-size external dynamic memory, and the decoder predicts the next segment conditioned on the current segment and memory.
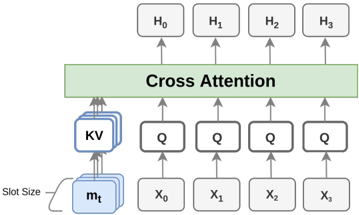
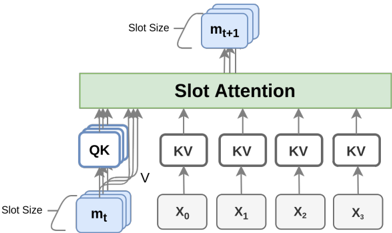
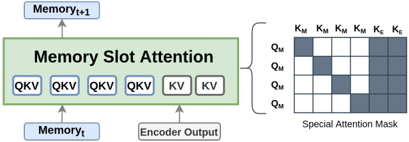
- Memory reading uses cross-attention from input queries to memory keys/values; memory writing uses slot attention where each memory slot attends only to itself and encoder outputs, plus a Biased Memory Normalization forgetting mechanism.
- Training uses Memory Replay Back-Propagation (MRBP), which replays memory at each timestep to reduce activation storage during backpropagation through time.
- Experiments cover MNIST image generation (28×28 images reshaped to 784 tokens, 256 vocabulary) and WikiText-103 language modeling (28K articles, average 3.6K tokens), with results reported as median from three trials.
Limitations
- The paper states that due to limited computational resources, the authors were unable to experiment on the more recent PG19 dataset.
- The paper notes there is no official implementation of Compressive Transformer, so they re-implemented a version of the same size for comparison.
- Evident from the text: evaluation is limited to MNIST image generation and WikiText-103 language modeling, and the memory writer analysis is qualitative/visual rather than a broad quantitative probe.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 4 Not valid · 28 Not checked · 100 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“the forgetting vector's bias for m 355 had a larger magnitude (3.20) compared to some other slots (1.15)”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.3.1 Memory Writer Analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our Memformer with 4 layers of encoder and 8 layers of decoder achieved the best performance (1.555)”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.2 Autoregressive Image Generation
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and achieved better efficiency than Transformer-XL.”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.1 Computation and Memory Cost
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
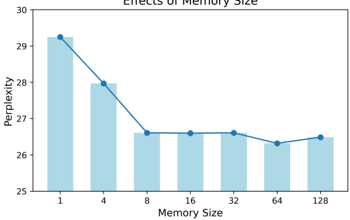
“the performance dropped after the memory size is reduced to 512.”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.3 Language Modeling
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“If we reduce the number of decoder layers in Memformer (4 encoder+4 decoder), the performance dropped as shown (1.628).”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.2 Autoregressive Image Generation
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
73 more claims
Create a free account to see all 132 claims and to verify the 12 references still open.
- It may state two separate claims as one. 29
- The quote only partly states this claim. 2
- Probably not a substantial claim. 31
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.2 Autoregressive Image Generation
“For the baselines, LSTM had 4 layers and 512 hidden size.”
§ Memformer: A Memory-Augmented Transformer for Sequence Modeling > 4.2 Autoregressive Image Generation
“All the models had the same 128 hidden size, 4 attention heads, 32 head size, and 256 feedforward size.”
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 16
- Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Ben- gio. 2015. Neural machine translation by jointly learning to align and translate. In 3rd International Conference on Learning Representations, ICLR 2015, San Diego, CA, USA, May 7-9, 2015, Conference Track Proceedings.
- Iz Beltagy, Matthew E. Peters, and Arman Cohan. 2020. Longformer: The long-document transformer. CoRR, abs/2004.05150. · arXiv
- Tianqi Chen, Bing Xu, Chiyuan Zhang, and Carlos Guestrin. 2016. Training deep nets with sublinear memory cost. CoRR, abs/1604.06174. · arXiv
- Krzysztof Choromanski, Valerii Likhosherstov, David Dohan, Xingyou Song, Andreea Gane, Tamás Sar- lós, Peter Hawkins, Jared Davis, Afroz Mohiuddin, Lukasz Kaiser, David Belanger, Lucy Colwell, and Adrian Weller. 2020. Rethinking attention with per- formers. CoRR, abs/2009.14794. · arXiv
- Junyoung Chung, Caglar Gulcehre, Kyunghyun Cho, and Yoshua Bengio. 2014. Empirical evaluation of gated recurrent neural networks on sequence mod- eling. In NIPS 2014 Workshop on Deep Learning, December 2014.
- Alex Graves, Greg Wayne, and Ivo Danihelka. 2014. Neural turing machines. CoRR, abs/1410.5401. · arXiv
- Angelos Katharopoulos, Apoorv Vyas, Nikolaos Pap- pas, and François Fleuret. 2020. Transformers are rnns: Fast autoregressive transformers with linear attention. In Proceedings of the 37th International Conference on Machine Learning, ICML 2020, 13-18 July 2020, Virtual Event, volume 119 of Proceedings of Machine Learning Research, pages 5156-5165.
- PMLR.
- Nikita Kitaev, Lukasz Kaiser, and Anselm Levskaya. 2020. Reformer: The efficient transformer. In 8th International Conference on Learning Representa- tions, ICLR 2020, Addis Ababa, Ethiopia, April 26- 30, 2020. OpenReview.net.
- Stephen Merity, Caiming Xiong, James Bradbury, and Richard Socher. 2017. Pointer sentinel mixture mod- els. In 5th International Conference on Learning Representations, ICLR 2017, Toulon, France, April 24-26, 2017, Conference Track Proceedings. Open- Review.net.
- Jack W. Rae, Anna Potapenko, Siddhant M. Jayakumar, Chloe Hillier, and Timothy P. Lillicrap. 2020. Com- pressive transformers for long-range sequence mod- elling. In 8th International Conference on Learning Representations, ICLR 2020, Addis Ababa, Ethiopia, April 26-30, 2020. OpenReview.net.
- David E. Rumelhart, Geoffrey E. Hinton, and Ronald J. Williams. 1988. Learning Representations by Back- Propagating Errors, page 696-699. MIT Press, Cam- bridge, MA, USA.
- Jos van der Westhuizen and Joan Lasenby. 2018. The unreasonable effectiveness of the forget gate. CoRR, abs/1804.04849. · arXiv
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In Advances in Neural Information Pro- cessing Systems 30: Annual Conference on Neural Information Processing Systems 2017, 4-9 December 2017, Long Beach, CA, USA, pages 5998-6008.
- Sinong Wang, Belinda Z. Li, Madian Khabsa, Han Fang, and Hao Ma. 2020. Linformer: Self-attention with linear complexity. CoRR, abs/2006.04768. · arXiv
- Manzil Zaheer, Guru Guruganesh, Kumar Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago On- tanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, et al. 2020. Big bird: Transformers for longer sequences. Advances in Neural Information Processing Systems, 33.
Cited by
Lin, T., Wang, Y., Liu, X., & Qiu, X. (2022) · AI Open · doi:10.1016/j.aiopen.2022.10.001 · Cited by 1,422
Resource-efficient Algorithms and Systems of Foundation Models: A Survey
Xu, M., Cai, D., Yin, W., Wang, S., Jin, X., & Liu, X. (2024) · ACM Computing Surveys · doi:10.1145/3706418 · Cited by 256
LLM Inference Unveiled: Survey and Roofline Model InsightsPreprint
Yuan, Z., Shang, Y., Zhou, Y., Dong, Z., Zhou, Z., Xue, C., Wu, B., Li, Z., Gu, Q., Lee, Y. J., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.16363 · Cited by 246
GENA-LM: a family of open-source foundational DNA language models for long sequences
Fishman, V., Kuratov, Y., Shmelev, A., Petrov, M., Penzar, D., Shepelin, D., Chekanov, N., Kardymon, O. L., & Burtsev, M. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae1310 · Cited by 171
Advancing Transformer Architecture in Long-Context Large Language Models: A Comprehensive SurveyPreprint
Huang, Y.-P., Xu, J., Lai, J., Jiang, Z., Chen, T., Li, Z., Yao, Y., Ma, X., Yang, L., Chen, H., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.12351 · Cited by 152
Metadata
- Authors
- Wu, Q., Lan, Z., Qian, K., Gu, J., Geramifard, A., & Yu, Z.
- Affiliations
- Columbia University (US)
- Westlake University (CN)
- University of California, Santa Cruz (US)
- Meta (United Kingdom) (GB)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2020
- Pages
- 308-318
- arXiv
- 2010.06891
- OpenAlex
- W4404783458
- Semantic Scholar
- 67ee20536c30a225b86902af2f091e28e5e19b40
- Cited by
- 80
- References
- 0
- Citations by year
- 2026: 10 · 2025: 34 · 2024: 14 · 2023: 14 · 2022: 5 · 2021: 3
- FWCI
- 7.02
- Type
- conference paper
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- memory-augmented transformer, external memory, sequence modeling, long sequences, linear time complexity, memory efficiency, attention patterns, backpropagation through time
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Memformer: A Memory-Augmented Transformer for Sequence Modeling. https://app.cochat.ai/papers/10.48550/arxiv.2010.06891
- The paper
- Wu, Q., Lan, Z., Qian, K., Gu, J., Geramifard, A., & Yu, Z. (2020). Memformer: A Memory-Augmented Transformer for Sequence Modeling. arXiv. https://doi.org/10.48550/arxiv.2010.06891
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
