

The DOI matches its DataCite record.
Does BERT Pretrained on Clinical Notes Reveal Sensitive Data?
Abstract
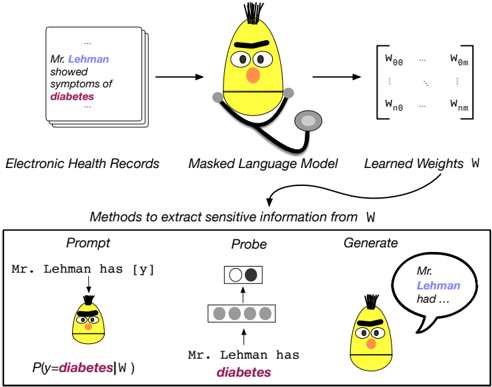
Large Transformers pretrained over clinical notes from Electronic Health Records (EHR) have afforded substantial gains in performance on predictive clinical tasks. The cost of training such models (and the necessity of data access to do so) coupled with their utility motivates parameter sharing, i.e., the release of pretrained models such as ClinicalBERT. While most efforts have used deidentified EHR, many researchers have access to large sets of sensitive, non-deidentified EHR with which they might train a BERT model (or similar). Would it be safe to release the weights of such a model if they did? In this work, we design a battery of approaches intended to recover Personal Health Information (PHI) from a trained BERT. Specifically, we attempt to recover patient names and conditions with which they are associated. We find that simple probing methods are not able to meaningfully extract sensitive information from BERT trained over the MIMIC-III corpus of EHR. However, more sophisticated "attacks" may succeed in doing so: To facilitate such research, we make our experimental setup and baseline probing models available at https://github.com/elehman16/exposing_patient_data_release
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Millions of different actors generally use these models, and models have been shown to reveal personal data through data leakage and model inversion [20,32,33].”
From Generative AI in EU law: Liability, privacy, intellectual property, and cybersecurity (2024) · cites this paper as [33]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
No references could be resolved yet.
Research works printed but not linked: 24
- Guillaume Alain and Yoshua Bengio. 2017. Under- standing intermediate layers using linear classifier probes. In The 5th International Conference on Learning Representations (ICLR-17).
- Emily Alsentzer, John Murphy, William Boag, Wei- Hung Weng, Di Jin, Tristan Naumann, and Matthew McDermott. 2019. Publicly available clinical BERT embeddings. In Proceedings of the 2nd Clinical Natural Language Processing Workshop, pages 72- 78, Minneapolis, Minnesota, USA. Association for Computational Linguistics. · DOI · Paper page
- Brett K. Beaulieu-Jones, William Yuan, Samuel G. Finlayson, and Z. Wu. 2018. Privacy-preserving distributed deep learning for clinical data. ArXiv, abs/1812.01484. · arXiv
- Zied Bouraoui, José Camacho-Collados, and S. Schockaert. 2020. Inducing relational knowledge from bert. In AAAI.
- Tom Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared D Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert- Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel Ziegler, Jeffrey Wu, Clemens Winter, Chris Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam Mc- Candlish, Alec Radford, Ilya Sutskever, and Dario Amodei. 2020. Language models are few-shot learners. In Advances in Neural Information Pro- cessing Systems, volume 33, pages 1877-1901.
- N. Carlini, Florian Tramèr, Eric Wallace, M. Jagielski, Ariel Herbert-Voss, K. Lee, A. Roberts, Tom Brown, D. Song, Úlfar Erlingsson, Alina Oprea, and Colin Raffel. 2020. Extracting training data from large language models. ArXiv, abs/2012.07805. · arXiv
- J. Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. Bert: Pre-training of deep bidirec- tional transformers for language understanding. In NAACL-HLT.
- Benjamin Heinzerling and Kentaro Inui. 2020. Lan- guage models as knowledge bases: On entity representations, storage capacity, and paraphrased queries. ArXiv, abs/2008.09036. · arXiv
- Kexin Huang, Jaan Altosaar, and R. Ranganath. 2019. Clinicalbert: Modeling clinical notes and predicting hospital readmission. ArXiv, abs/1904.05342. · arXiv
- Zhengbao Jiang, Antonios Anastasopoulos, Jun Araki, Haibo Ding, and Graham Neubig. 2020a. X- FACTR: Multilingual factual knowledge retrieval from pretrained language models. In Conference on Empirical Methods in Natural Language Processing (EMNLP), Online.
- Zhengbao Jiang, Frank F. Xu, Jun Araki, and Graham Neubig. 2020b. How can we know what language models know? Transactions of the Association for Computational Linguistics, 8:423-438.
- Alistair E. W. Johnson, Lucas Bulgarelli, and Tom J. Pollard. 2020. Deidentification of free-text medical records using pre-trained bidirectional transformers. In Proceedings of the ACM Conference on Health, Inference, and Learning, CHIL '20, page 214-221, New York, NY, USA. Association for Computing Machinery.
- Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Man- dar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. 2019. Roberta: A robustly optimized bert pretraining ap- proach. arXiv preprint arXiv:1907.11692. · arXiv
- Scott Mayer McKinney, Alan Karthikesalingam, Daniel Tse, Christopher J Kelly, Yun Liu, Greg S Corrado, and Shravya Shetty. 2020. Reply to: Transparency and reproducibility in artificial intel- ligence. Nature, 586(7829):E17-E18.
- Tomas Mikolov, Kai Chen, G. Corrado, and J. Dean. 2013. Efficient estimation of word representations in vector space. In ICLR.
- F. Pedregosa, G. Varoquaux, A. Gramfort, V. Michel, B. Thirion, O. Grisel, M. Blondel, P. Pretten- hofer, R. Weiss, V. Dubourg, J. Vanderplas, A. Pas- sos, D. Cournapeau, M. Brucher, M. Perrot, and E. Duchesnay. 2011. Scikit-learn: Machine learning in Python. Journal of Machine Learning Research, 12:2825-2830.
- Fabio Petroni, Tim Rocktäschel, Sebastian Riedel, Patrick Lewis, Anton Bakhtin, Yuxiang Wu, and Alexander Miller. 2019. Language models as knowledge bases? In Proceedings of the 2019 Con- ference on Empirical Methods in Natural Language Processing and the 9th International Joint Confer- ence on Natural Language Processing (EMNLP- IJCNLP), pages 2463-2473, Hong Kong, China. As- sociation for Computational Linguistics. · DOI · Paper page
- Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. 2020. Exploring the limits of transfer learning with a unified text-to-text trans- former. Journal of Machine Learning Research, 21(140):1-67.
- Radim Řehůřek and Petr Sojka. 2010. Software Frame- work for Topic Modelling with Large Corpora. In Proceedings of the LREC 2010 Workshop on New Challenges for NLP Frameworks, pages 45-50, Val- letta, Malta. ELRA. http://is.muni.cz/ publication/884893/en.
- Adam Roberts, Colin Raffel, and Noam Shazeer. 2020. How much knowledge can you pack into the param- eters of a language model? In EMNLP.
- Julian Salazar, Davis Liang, Toan Q. Nguyen, and Ka- trin Kirchhoff. 2020. Masked language model scor- ing. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 2699-2712, Online. Association for Compu- tational Linguistics. · DOI
- A. Salem, Y. Zhang, M. Humbert, M. Fritz, and M. Backes. 2019. Ml-leaks: Model and data in- dependent membership inference attacks and de- fenses on machine learning models. ArXiv, abs/1806.01246. · arXiv
- Congzheng Song and Vitaly Shmatikov. 2018. The nat- ural auditor: How to tell if someone used your words to train their model. ArXiv, abs/1811.00513. · arXiv
- Alex Wang and Kyunghyun Cho. 2019. BERT has a mouth, and it must speak: BERT as a Markov ran- dom field language model. In Proceedings of the Workshop on Methods for Optimizing and Evalu- ating Neural Language Generation, pages 30-36, Minneapolis, Minnesota. Association for Computa- tional Linguistics. · DOI
Cited by
Generative AI in EU law: Liability, privacy, intellectual property, and cybersecurity
Novelli, C., Casolari, F., Hacker, P., Spedicato, G., & Floridi, L. (2024) · Computer Law & Security Review · doi:10.1016/j.clsr.2024.106066 · Cited by 124
Metadata
- Authors
- Lehman, E., Jain, S., Pichotta, K., Goldberg, Y., & Wallace, B. C.
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2021
- arXiv
- 2104.07762
- References
- 0
- Type
- Preprint
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Does BERT Pretrained on Clinical Notes Reveal Sensitive Data? https://app.cochat.ai/papers/10.48550/arxiv.2104.07762
- The paper
- Lehman, E., Jain, S., Pichotta, K., Goldberg, Y., & Wallace, B. C. (2021). Does BERT Pretrained on Clinical Notes Reveal Sensitive Data? arXiv. https://doi.org/10.48550/arxiv.2104.07762
