

The DOI matches its DataCite record.
CiteBench: A benchmark for Scientific Citation Text Generation
Abstract
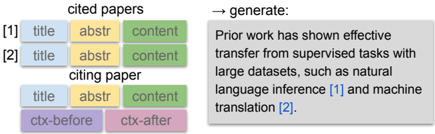
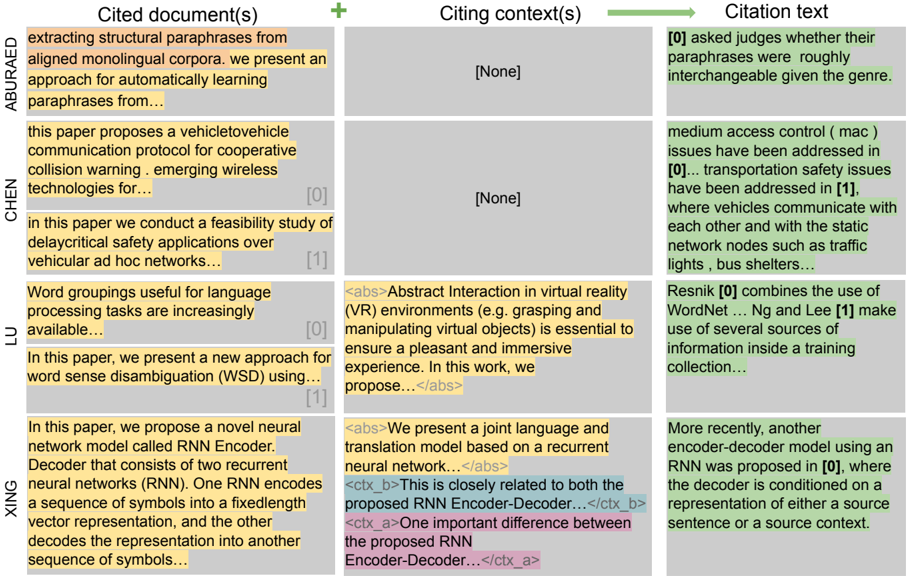
Science progresses by building upon the prior body of knowledge documented in scientific publications. The acceleration of research makes it hard to stay up-to-date with the recent developments and to summarize the ever-growing body of prior work. To address this, the task of citation text generation aims to produce accurate textual summaries given a set of papers-to-cite and the citing paper context. Due to otherwise rare explicit anchoring of cited documents in the citing paper, citation text generation provides an excellent opportunity to study how humans aggregate and synthesize textual knowledge from sources. Yet, existing studies are based upon widely diverging task definitions, which makes it hard to study this task systematically. To address this challenge, we propose CiteBench: a benchmark for citation text generation that unifies multiple diverse datasets and enables standardized evaluation of citation text generation models across task designs and domains. Using the new benchmark, we investigate the performance of multiple strong baselines, test their transferability between the datasets, and deliver new insights into the task definition and evaluation to guide future research in citation text generation. We make the code for CiteBench publicly available at https://github.com/UKPLab/citebench.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Scientific citation text generation (Funkquist et al., 2022) is a related task to ALCE where the model is provided the papers-to-cite and context and is required to recover the citing text.It is different from ALCE as all citations are provided and the model only needs to perform the summarization.”
From Enabling Large Language Models to Generate Text with Citations (2023) · cites this paper as Funkquist et al., 2022
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
No references could be resolved yet.
Research works printed but not linked: 26
- Ahmed AbuRa'ed, Horacio Saggion, Alexander Shvets, and Àlex Bravo. 2020. Automatic related work sec- 13 https://creativecommons.org/licenses/by-nc/4. 0/ 14 https://github.com/XingXinyu96/citation_ generation 15 https://github.com/AhmedAbuRaed/SPSeq2Seq 16 https://intertext.ukp-lab.de Evaluation, and Metrics (GEM 2021), pages 96-120, Online. Association for Computational Linguistics. · DOI
- Sebastian Gehrmann, Abhik Bhattacharjee, Abinaya Mahendiran, Alex Wang, Alexandros Papangelis, Aman Madaan, Angelina Mcmillan-major, Anna Shvets, Ashish Upadhyay, and Bernd Bohnet. 2022. GEMv2: Multilingual NLG benchmarking in a single line of code. In Proceedings of the 2022 Conference on Empirical Methods in Natural Language Process- ing: System Demonstrations, pages 266-281, Abu Dhabi, UAE. Association for Computational Linguis- tics.
- Cong Duy Vu Hoang and Min-Yen Kan. 2010. Towards automated related work summarization. In Inter- national Conference on Computational Linguistics (COLING) 2010: Posters, pages 427-435, Beijing, China. Coling 2010 Organizing Committee.
- Yue Hu and Xiaojun Wan. 2014. Automatic gener- ation of related work sections in scientific papers: An optimization approach. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 1624-1633, Doha, Qatar. Association for Computational Linguis- tics. · DOI
- David Jurgens, Srijan Kumar, Raine Hoover, Dan Mc- Farland, and Dan Jurafsky. 2018. Measuring the evolution of a scientific field through citation frames. Transactions of the Association for Computational Linguistics, 6:391-406. · DOI · Paper page
- Douwe Kiela, Max Bartolo, Yixin Nie, Divyansh Kaushik, Atticus Geiger, Zhengxuan Wu, Bertie Vid- gen, Grusha Prasad, Amanpreet Singh, Pratik Ring- shia, Zhiyi Ma, Tristan Thrush, Sebastian Riedel, Zeerak Waseem, Pontus Stenetorp, Robin Jia, Mohit Bansal, Christopher Potts, and Adina Williams. 2021. Dynabench: Rethinking benchmarking in NLP. In Proceedings of the 2021 Conference of the North American Chapter of the Association for Computa- tional Linguistics: Human Language Technologies, pages 4110-4124, Online. Association for Computa- tional Linguistics. · DOI · Paper page
- Anne Lauscher, Brandon Ko, Bailey Kuehl, Sophie Johnson, Arman Cohan, David Jurgens, and Kyle Lo. 2022. MultiCite: Modeling realistic citations requires moving beyond the single-sentence single- label setting. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Tech- nologies, pages 1875-1889, Seattle, United States. Association for Computational Linguistics. · DOI
- Xiangci Li, Biswadip Mandal, and Jessica Ouyang. 2022. CORWA: A citation-oriented related work annotation dataset. In Proceedings of the 2022 Con- ference of the North American Chapter of the As- sociation for Computational Linguistics: Human Language Technologies, pages 5426-5440, Seattle, United States. Association for Computational Lin- guistics. · DOI
- Xiangci Li and Jessica Ouyang. 2022. Automatic related work generation: A meta study. ArXiv, abs/2201.01880. · arXiv
- Chin-Yew Lin. 2004. ROUGE: A package for auto- matic evaluation of summaries. In Text Summariza- tion Branches Out, pages 74-81, Barcelona, Spain. Association for Computational Linguistics.
- Yao Lu, Yue Dong, and Laurent Charlin. 2020. Multi- XScience: A large-scale dataset for extreme multi- document summarization of scientific articles. In Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 8068-8074, Online. Association for Computa- tional Linguistics. · DOI
- Junyu Luo, Junxian Lin, Chi Lin, Cao Xiao, Xinning Gui, and Fenglong Ma. 2022. Benchmarking au- tomated clinical language simplification: Dataset, algorithm, and evaluation. In Proceedings of the 29th International Conference on Computational Lin- guistics, pages 3550-3562, Gyeongju, Republic of Korea. International Committee on Computational Linguistics.
- Kelvin Luu, Xinyi Wu, Rik Koncel-Kedziorski, Kyle Lo, Isabel Cachola, and Noah A. Smith. 2021. Ex- plaining relationships between scientific documents. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Lan- guage Processing (Volume 1: Long Papers), pages 2130-2144, Online. Association for Computational Linguistics. · DOI
- Yuning Mao, Ming Zhong, and Jiawei Han. 2022. Cite- Sum: Citation text-guided scientific extreme sum- marization and domain adaptation with limited su- pervision. In Proceedings of the 2022 Conference on Empirical Methods in Natural Language Process- ing, pages 10922-10935, Abu Dhabi, United Arab Emirates. Association for Computational Linguistics. · DOI
- Rada Mihalcea and Paul Tarau. 2004. TextRank: Bring- ing order into text. In Proceedings of the 2004 Con- ference on Empirical Methods in Natural Language Processing, pages 404-411, Barcelona, Spain. Asso- ciation for Computational Linguistics.
- Nafise Moosavi, Andreas Rücklé, Dan Roth, and Iryna Gurevych. 2021. Scigen: a dataset for reasoning- aware text generation from scientific tables. In Pro- ceedings of the Neural Information Processing Sys- tems Track on Datasets and Benchmarks, volume 1, Online.
- Fabio Petroni, Aleksandra Piktus, Angela Fan, Patrick Lewis, Majid Yazdani, Nicola De Cao, James Thorne, Yacine Jernite, Vladimir Karpukhin, Jean Maillard, Vassilis Plachouras, Tim Rocktäschel, and Sebastian Riedel. 2021. KILT: a benchmark for knowledge intensive language tasks. In Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 2523-2544, Online. Association for Computational Linguistics. · DOI · Paper page
- Vahed Qazvinian and Dragomir R. Radev. 2008. Sci- entific paper summarization using citation summary networks. In Proceedings of the 22nd International Conference on Computational Linguistics (Coling 2008), pages 689-696, Manchester, UK. Coling 2008 Organizing Committee.
- Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev, and Percy Liang. 2016. SQuAD: 100,000+ questions for machine comprehension of text. In Proceedings of the 2016 Conference on Empirical Methods in Natu- ral Language Processing, pages 2383-2392, Austin, Texas. Association for Computational Linguistics. · DOI · Paper page
- Darsh J. Shah and Regina Barzilay. 2021. Generating related work. ArXiv, abs/2104.08668. · arXiv
- Edward Sun, Yufang Hou, Dakuo Wang, Yunfeng Zhang, and Nancy X. R. Wang. 2021. D2S: Document-to-slide generation via query-based text summarization. In Proceedings of the 2021 Confer- ence of the North American Chapter of the Associ- ation for Computational Linguistics: Human Lan- guage Technologies, pages 1405-1418, Online. As- sociation for Computational Linguistics. · DOI
- Simeng Sun, Ori Shapira, Ido Dagan, and Ani Nenkova. 2019. How to compare summarizers without target length? pitfalls, solutions and re-examination of the neural summarization literature. In Proceedings of the Workshop on Methods for Optimizing and Eval- uating Neural Language Generation, pages 21-29, Minneapolis, Minnesota. Association for Computa- tional Linguistics. · DOI
- Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. 2018. GLUE: A multi-task benchmark and analysis platform for nat- ural language understanding. In Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP, pages 353-355, Brussels, Belgium. Association for Com- putational Linguistics. · DOI · Paper page
- Yifan Wang, Yiping Song, Shuai Li, Chaoran Cheng, Wei Ju, Ming Zhang, and Sheng Wang. 2022. Dis- encite: Graph-based disentangled representation learning for context-specific citation generation. In Proceedings of the AAAI Conference on Artificial In- telligence, volume 36, pages 11449-11458, Online. · DOI
- Xinyu Xing, Xiaosheng Fan, and Xiaojun Wan. 2020. Automatic generation of citation texts in scholarly papers: A pilot study. In Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics, pages 6181-6190, Online. Association for Computational Linguistics. · DOI
- Tianyi Zhang, Varsha Kishore, Felix Wu, Kilian Q. Weinberger, and Yoav Artzi. 2020. BERTScore: Evaluating Text Generation with BERT. In Inter- national Conference on Learning Representations, Online. 16.69 / 2.22 / 11.32 19.75 / 2.23 / 11.48 18.64 / 2.32 / 11.34 22.99 / 3.40 / 13.34 14.98 / 2.22 / 10.55 TextRank 13.59 / 1.54 / 9.35 27.39/3.77/14.04 23.09/3.48/12.82 23.05 / 3.98 / 12.75 8.51 / 1.14 / 6.61 LexRank 15.90 / 2.00 / 10.80 23.79 / 3.12 / 12.93 22.35 / 3.10 / 12.85 25.53 / 4.18 / 14.24 14.47 / 1.98 / 10.06 led-base 11.06 / 1.72 / 9.06 7.16 / 0.74 / 5.55 6.68 / 0.75 / 5.41 9.73 / 1.35 / 7.36 12.36 / 1.66 / 10.07 led-large 10.39 / 1.36 / 8.30 7.85 / 0.96 / 6.22 7.56 / 0.99 / 6.22 8.84 / 1.25/6.89 11.61/1.29/9.35 led-large-arxiv 15.55 / 1.89 / 10.22 25.78 / 3.35 / 13.37 23.45 / 3.20 / 12.89 26.27 / 4.44 / 14.41 14.57 / 2.04 / 10.23 *led-base 19.65 / 2.12 / 13.44 30.66 / 5.51 / 15.93 26.58 / 5.82 / 15.94 28.76 / 5.03 / 15.95 18.88 / 2.04 / 13.58 (0.018) / (0.006) /(0.025) (0.004) / -/ (0.002) (0.003) / (0.003) / - (0.007) / (0.002) / (0.003) (0.009) / -/ (0.006) *led-large-arxiv 21.56 / 2.96 / 14.90 31.65 / 6.01 / 16.27 26.70 / 6.07 / 15.92 30.54 / 5.63 / 16.53 17.90 / 1.52/ 12.42 (0.003) / (0.005) / (0.011) (0.007) / (0.002) / (0.003) (0.007) / (0.001) / (0.002) (0.010) / (0.004) / (0.002) (0.012) / (0.009) / (0.008) *led-base-aburaed 19.65 / 1.95 / 13.95 15.32 / 1.96 / 9.96 15.96 / 2.18 / 10.66 17.84 / 2.54 / 11.63 18.68 / 1.46 / 12.63 *led-base-chen 17.66 / 2.41 / 11.48 30.82 / 5.58 / 16.04 27.28 / 5.89 / 16.21 28.92 / 4.80 / 15.40 14.51 / 1.89 / 10.14 *led-base-lu 17.78 / 2.32 / 12.19 26.97 / 3.97 / 14.58 25.90 / 3.72 / 14.59 28.94 / 5.00 / 16.25 17.50 / 1.92 / 11.56 *led-base-xing 16.56 / 1.32 / 11.97 16.01 / 1.87 / 9.54 16.09 / 1.89 / 10.01 14.87 / 1.81 / 9.88 19.77 / 2.80 / 14.06
Cited by
Enabling Large Language Models to Generate Text with Citations
Gao, T., Yen, H., Yu, J., & Chen, D. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.398 · Cited by 216
Metadata
- Authors
- Funkquist, M., Kuznetsov, I., Hou, Y., & Gurevych, I.
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2022
- arXiv
- 2212.09577
- References
- 0
- Type
- Preprint
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: CiteBench: A benchmark for Scientific Citation Text Generation. https://app.cochat.ai/papers/10.48550/arxiv.2212.09577
- The paper
- Funkquist, M., Kuznetsov, I., Hou, Y., & Gurevych, I. (2022). CiteBench: A benchmark for Scientific Citation Text Generation. arXiv. https://doi.org/10.48550/arxiv.2212.09577
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
