

The DOI matches its DataCite record; 2 of the 36 references it cites were found in a registry or an index, and 34 are not checked yet.
Detection of Machine-Generated Text: Literature Survey
Open accessAbstract
Since language models produce fake text quickly and easily, there is an oversupply of such content in the public domain. The degree of sophistication and writing style has reached a point where differentiating between human authored and machine-generated content is nearly impossible. As a result, works generated by language models rather than human authors have gained significant media attention and stirred controversy.Concerns regarding the possible influence of advanced language models on society have also arisen, needing a fuller knowledge of these processes. Natural language generation (NLG) and generative pre-trained transformer (GPT) models have revolutionized a variety of sectors: the scope not only permeated throughout journalism and customer service but also reached academia. To mitigate the hazardous implications that may arise from the use of these models, preventative measures must be implemented, such as providing human agents with the capacity to distinguish between artificially made and human composed texts utilizing automated systems and possibly reverse-engineered language models. Furthermore, to ensure a balanced and responsible approach, it is critical to have a full grasp of the socio-technological ramifications of these breakthroughs. This literature survey aims to compile and synthesize accomplishments and developments in the aforementioned work, while also identifying future prospects. It also gives an overview of machine-generated text trends and explores the larger societal implications. Ultimately, this survey intends to contribute to the development of robust and effective approaches for resolving the issues connected with the usage and detection of machine-generated text by exploring the interplay between the capabilities of language models and their possible implications.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
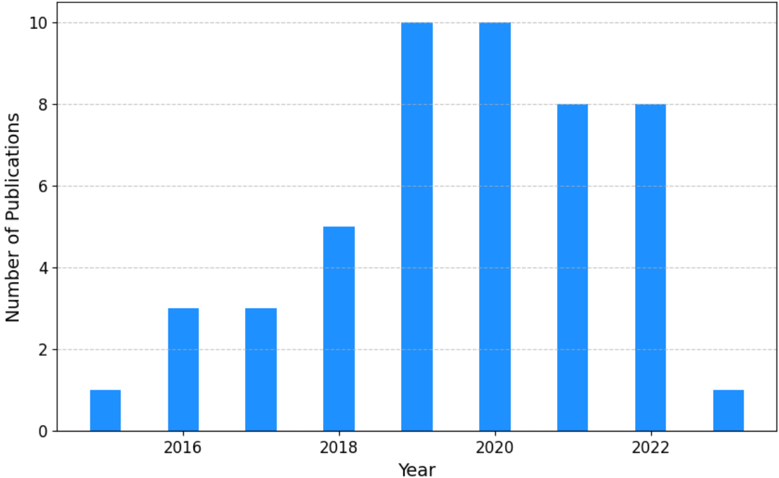
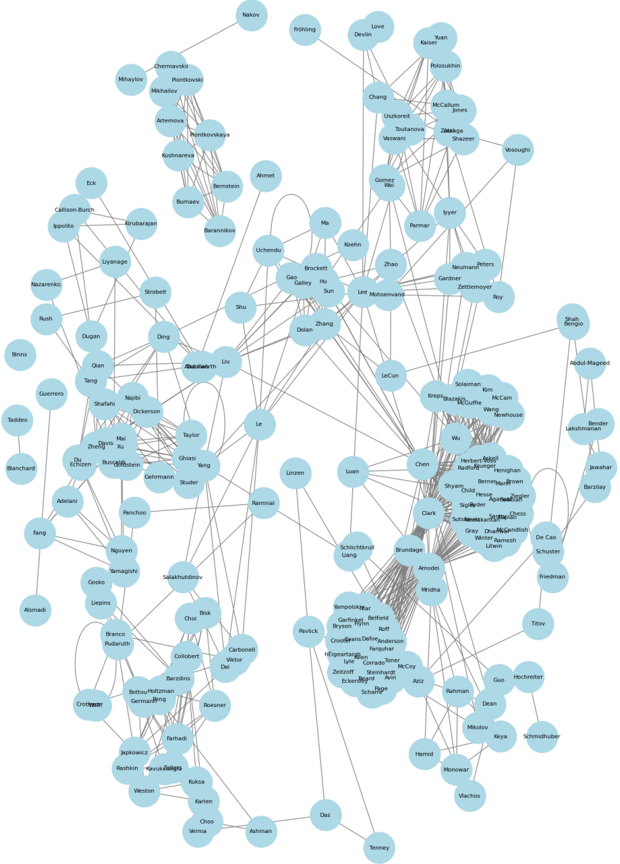
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“However, to date, no comprehensive review has systematically compiled this body of research.”
From Enhancing the Robustness of AI-Generated Text Detectors: A Survey (2025) · cites this paper as [31]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The publisher hasn’t deposited this paper’s reference list.
Research works printed but not linked: 12
- Reuben Binns. 2017. Fairness in Machine Learning: Lessons from Political Philosophy. Re- trieved April 24, 2023 from https://papers.ssrn.com/abstract=3086546
- Tom Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared D Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert- Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel Ziegler, Jeffrey Wu, Clemens Winter, Chris Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam McCandlish, Alec Radford, Ilya Sutskever, and Dario Amodei. 2020. Language Models are Few-Shot Learners. In Advances in Neural Information Processing Systems, Curran Associates, Inc., 1877-1901. Retrieved April 23, 2023 from https://papers.nips.cc/p aper/2020/hash/1457c0d6bfcb4967418bfb8ac142f64a-Abstract.html
- Ulrich Germann, Renārs Liepins, Didzis Gosko, and Guntis Barzdins. 2018. Integrating Multiple NLP Technologies into an Open-source Platform for Multilingual Media Monitoring. In Proceedings of Workshop for NLP Open Source Software (NLP-OSS), Association for Computational Linguistics, Melbourne, Australia, 47-51. DOI:https://doi.org/10.18653/v1/W18-2508 · DOI
- Jesus Guerrero and Izzat Alsmadi. 2022. Synthetic Text Detection: Systemic Literature Review. arXiv.org. DOI:https://doi.org/10.48550/arXiv.2210.06336 · DOI
- Daphne Ippolito, Daniel Duckworth, Chris Callison-Burch, and D. Eck. 2019. Human and Automatic Detection of Generated Text. ArXiv (November 2019). Retrieved April 24, 2023 from https://www.semanticscholar.org/paper/Human-and-Automatic-Detection-of-Generated-T ext-Ippolito-Duckworth/dee33aa8d7f8ff4458a65379ebce8bd8860d0100
- Yann LeCun and Yoshua Bengio. 1998. Convolutional networks for images, speech, and time series. In The handbook of brain theory and neural networks. MIT Press, Cambridge, MA, USA, 255-258.
- Tomas Mikolov, Kai Chen, Greg S. Corrado, and Jeffrey Dean. 2013. Efficient Estimation of Word Representations in Vector Space. Retrieved April 23, 2023 from http://arxiv.org/abs/1301.3781 · arXiv
- Ali Shafahi, Mahyar Najibi, Mohammad Amin Ghiasi, Zheng Xu, John Dickerson, Christoph Studer, Larry S Davis, Gavin Taylor, and Tom Goldstein. 2019. Adversarial training for free! In Advances in Neural Information Processing Systems, Curran Associates, Inc. Retrieved April 24, 2023 from https://papers.nips.cc/paper_files/paper/2019/hash/7503cfacd12053d309b6bed5c89de212- Abstract.html
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. Attention is All you Need. In Advances in Neural Infor- mation Processing Systems, Curran Associates, Inc. Retrieved April 23, 2023 from https://papers.ni ps.cc/paper_files/paper/2017/hash/3f5ee243547dee91fbd053c1c4a845aa-Abstract.html
- Zhilin Yang, Zihang Dai, Yiming Yang, Jaime Carbonell, Russ R Salakhutdinov, and Quoc V Le. 2019. XLNet: Generalized Autoregressive Pretraining for Language Understanding. In Advances in Neural Information Processing Systems, Curran Associates, Inc. Retrieved April 25, 2023 from https ://papers.nips.cc/paper_files/paper/2019/hash/dc6a7e655d7e5840e66733e9ee67cc69-Abstract.html
- Rowan Zellers, Ari Holtzman, Hannah Rashkin, Yonatan Bisk, Ali Farhadi, Franziska Roesner, and Yejin Choi. 2019. Defending Against Neural Fake News. In Advances in Neural Information Processing Systems, Curran Associates, Inc. Retrieved April 23, 2023 from https://proceedings.neur ips.cc/paper_files/paper/2019/hash/3e9f0fc9b2f89e043bc6233994dfcf76-Abstract.html
- Xiang Zhang, Junbo Zhao, and Yann LeCun. 2015. Character-level Convolutional Networks for Text Classification. In Advances in Neural Information Processing Systems, Curran Associates, Inc. Retrieved April 24, 2023 from https://papers.nips.cc/paper_files/paper/2015/hash/250cf8b51c77 3f3f8dc8b4be867a9a02-Abstract.html
Cited by
Sorted by citations
Fake News Detection: It’s All in the Data!
Kuntur, S., Wróblewska, A., Ganzha, M., Paprzycki, M., & Sachdeva, S. (2026) · Applied Sciences · doi:10.3390/app16031585 · Cited by 37
A Practical Synthesis of Detecting AI-Generated Textual, Visual, and Audio Content
Cao, L. (2025) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw69685.2025.00170 · Cited by 22
Watermarking for AI Content Detection: A Review on Text, Visual, and Audio ModalitiesPreprint
Cao, L. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.03765 · Cited by 13
Enhancing the Robustness of AI-Generated Text Detectors: A Survey
Liu, X., Li, Y., & Li, K. (2025) · Mathematics · doi:10.3390/math13132145 · Cited by 10
Humanizing the Machine: Proxy Attacks to Mislead LLM DetectorsPreprint
Wang, T., Chen, Y., Liu, Z., Chen, Z., Chen, H., Zhang, X., & Cheng, W. X. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.19230 · Cited by 7
Metadata
- Authors
- Valiaiev, D.
- Affiliations
- University of Arkansas at Little Rock (US)
- Corresponding author
- Valiaiev, Dmytro
- ORCID
- Valiaiev, Dmytro
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2024
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2402.01642
- OpenAlex
- W4391591595
- Cited by
- 5
- References
- 0
- Citations by year
- 2026: 1 · 2025: 1 · 2024: 3
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Authorship Attribution and Profiling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Digital Media Forensic Detection
- Keywords
- AI-generated text detection, AI-generated text, large language models, GPT models, natural language generation, societal impact of AI, AI-generated content
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Detection of Machine-Generated Text: Literature Survey. https://app.cochat.ai/papers/10.48550/arxiv.2402.01642
- The paper
- Valiaiev, D. (2024). Detection of Machine-Generated Text: Literature Survey. arXiv. https://doi.org/10.48550/arxiv.2402.01642
