

The DOI matches its DataCite record; 1 of the 1 references it cites were found in a registry or an index.
Benchmark Inflation: Revealing LLM Performance Gaps Using Retro-Holdouts
Open accessAbstract
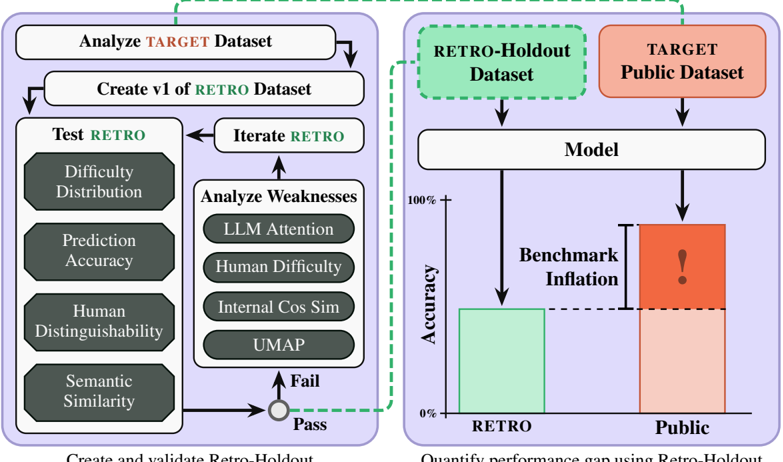
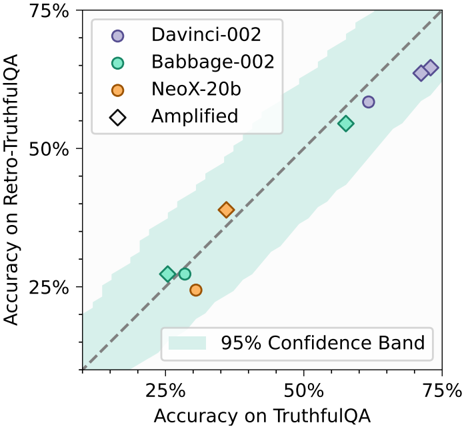
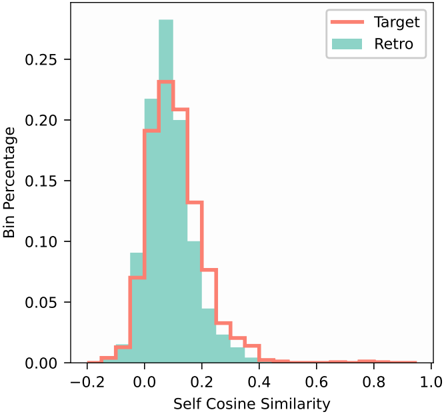
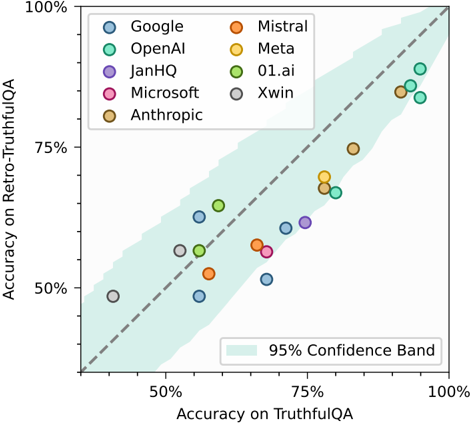
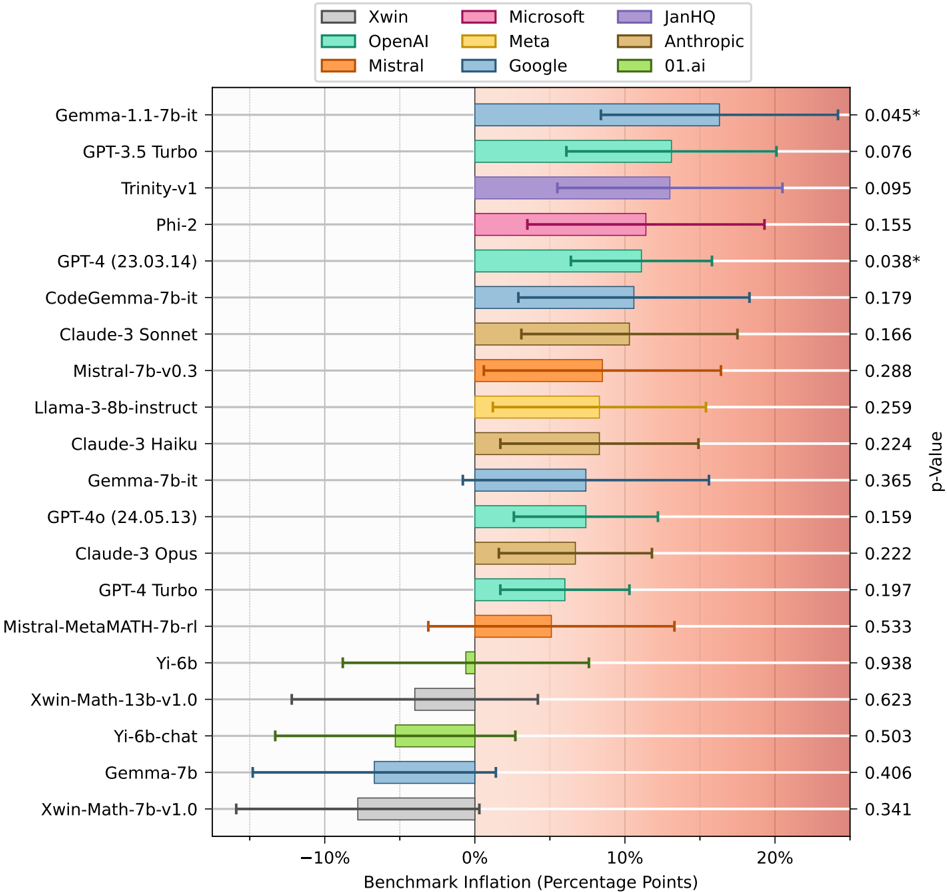
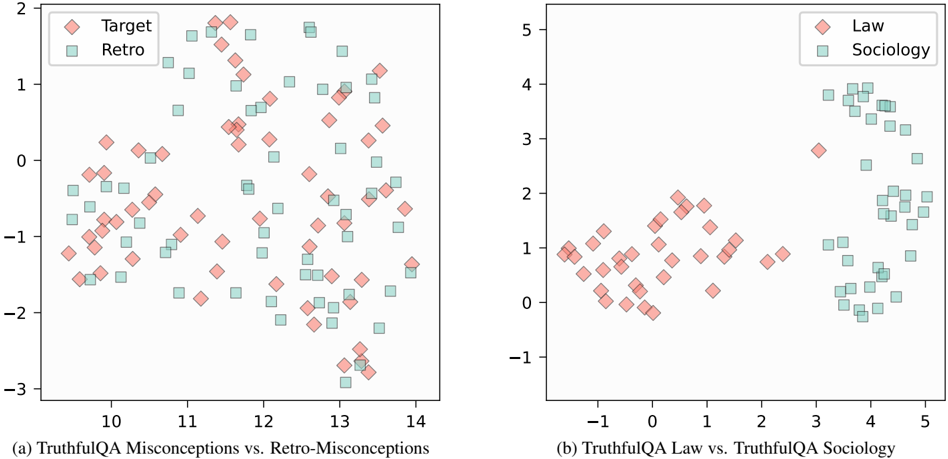
The training data for many Large Language Models (LLMs) is contaminated with test data. This means that public benchmarks used to assess LLMs are compromised, suggesting a performance gap between benchmark scores and actual capabilities. Ideally, a private holdout set could be used to accurately verify scores. Unfortunately, such datasets do not exist for most benchmarks, and post-hoc construction of sufficiently similar datasets is non-trivial. To address these issues, we introduce a systematic methodology for (i) retrospectively constructing a holdout dataset for a target dataset, (ii) demonstrating the statistical indistinguishability of this retro-holdout dataset, and (iii) comparing LLMs on the two datasets to quantify the performance gap due to the dataset's public availability. Applying these methods to TruthfulQA, we construct and release Retro-Misconceptions, on which we evaluate twenty LLMs and find that some have inflated scores by as much as 16 percentage points. Our results demonstrate that public benchmark scores do not always accurately assess model properties, and underscore the importance of improved data practices in the field.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Consistent with emerging understanding of AI benchmarking and leaderboards, we reserve a random sample of 50% of the dataset to guard against potential model memorization and ensure that a proper test set remains available for future evaluation (Haimes et al. 2024; Li and Flanigan 2024)”
From Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools (2025) · cites this paper as Haimes et al. 2024
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Research works printed but not linked: 33
- N. Alzahrani, H. A. Alyahya, Y. Alnumay, S. Alrashed, S. Alsubaie, Y. Almushaykeh, F. Mirza, N. Alotaibi, N. Alt- wairesh, A. Alowisheq, M. S. Bari, and H. Khan. When Benchmarks are Targets: Revealing the Sensitivity of Large Language Model Leaderboards, Feb. 2024. URL http: //arxiv.org/abs/2402.01781. arXiv:2402.01781 [cs]. · arXiv
- J. Bai, S. Bai, Y. Chu, Z. Cui, K. Dang, X. Deng, Y. Fan, W. Ge, Y. Han, F. Huang, B. Hui, L. Ji, M. Li, J. Lin, R. Lin, D. Liu, G. Liu, C. Lu, K. Lu, J. Ma, R. Men, X. Ren, X. Ren, C. Tan, S. Tan, J. Tu, P. Wang, S. Wang, W. Wang, S. Wu, B. Xu, J. Xu, A. Yang, H. Yang, J. Yang, S. Yang, Y. Yao, B. Yu, H. Yuan, Z. Yuan, J. Zhang, X. Zhang, Y. Zhang, Z. Zhang, C. Zhou, J. Zhou, X. Zhou, and T. Zhu. Qwen tech- nical report, 2023. URL https://arxiv.org/abs/ 2309.16609.
- R. Bommasani, K. Klyman, S. Longpre, S. Kapoor, N. Maslej, B. Xiong, D. Zhang, and P. Liang. The foundation model transparency index. arXiv preprint arXiv:2310.12941, 2023. · arXiv
- T. B. Brown, B. Mann, N. Ryder, M. Subbiah, J. Kaplan, P. Dhariwal, A. Neelakantan, P. Shyam, G. Sastry, A. Askell, S. Agarwal, A. Herbert-Voss, G. Krueger, T. Henighan, R. Child, A. Ramesh, D. M. Ziegler, J. Wu, C. Win- ter, C. Hesse, M. Chen, E. Sigler, M. Litwin, S. Gray, B. Chess, J. Clark, C. Berner, S. McCandlish, A. Radford, I. Sutskever, and D. Amodei. Language models are few- shot learners, 2020. URL https://arxiv.org/abs/ 2005.14165.
- Y. Chang, X. Wang, J. Wang, Y. Wu, L. Yang, K. Zhu, H. Chen, X. Yi, C. Wang, Y. Wang, et al. A survey on evaluation of large language models. ACM Transactions on Intelligent Systems and Technology, 15(3):1-45, 2024.
- K. Cobbe, V. Kosaraju, M. Bavarian, M. Chen, H. Jun, L. Kaiser, M. Plappert, J. Tworek, J. Hilton, R. Nakano, C. Hesse, and J. Schulman. Training Verifiers to Solve Math Word Problems, Nov. 2021. URL http://arxiv.org/ abs/2110.14168. · arXiv
- G. Cui, L. Yuan, N. Ding, G. Yao, B. He, W. Zhu, Y. Ni, G. Xie, R. Xie, Y. Lin, Z. Liu, and M. Sun. Ultrafeedback: Boosting language models with scaled ai feedback, 2024. URL https://arxiv.org/abs/2310.01377. · arXiv
- F. K. Dankar and M. Ibrahim. Fake It Till You Make It: Guidelines for Effective Synthetic Data Generation. Ap- plied Sciences, 11(5):2158, Jan. 2021. ISSN 2076-3417. doi: 10.3390/app11052158. URL https://www.mdpi. com/2076-3417/11/5/2158. Number: 5 Publisher: Multidisciplinary Digital Publishing Institute. · DOI
- C. Deng, Y. Zhao, X. Tang, M. Gerstein, and A. Cohan. Investigating Data Contamination in Modern Benchmarks for Large Language Models, Apr. 2024. URL http://arxiv. org/abs/2311.09783. arXiv:2311.09783 [cs]. · arXiv
- M. Dwass. Modified Randomization Tests for Nonparametric Hypotheses. The Annals of Mathematical Statistics, 28(1): 181 -187, 1957. doi: 10.1214/aoms/1177707045. URL https://doi.org/10.1214/aoms/1177707045. · DOI
- S. Golchin and M. Surdeanu. Time travel in llms: Tracing data contamination in large language models. arXiv preprint arXiv:2308.08493, 2023. · arXiv
- C. A. Goodhart. Problems of monetary management: the UK experience. Springer, 1984.
- J. Hemerik. On the Term "Randomization Test". The American Statistician, pages 1-8, Mar. 2024. ISSN 0003-1305, 1537-2731. doi: 10.1080/00031305.2024. 2319182. URL https://www.tandfonline.com/ doi/full/10.1080/00031305.2024.2319182. · DOI
- G. James, D. Witten, T. Hastie, R. Tibshirani, and J. Taylor. An Introduction to Statistical Learning: with Applications in Python. Springer Texts in Statistics. Springer International Publishing, Cham, 2023. ISBN 978-3-031-38746-3 978-3-031-38747-0. doi: 10.1007/ 978-3-031-38747-0. URL https://link.springer. com/10.1007/978-3-031-38747-0. · DOI
- M. Jiang, K. Z. Liu, M. Zhong, R. Schaeffer, S. Ouyang, J. Han, and S. Koyejo. Investigating Data Contamination for Pre-training Language Models, Jan. 2024. URL http: //arxiv.org/abs/2401.06059. arXiv:2401.06059 [cs]. · arXiv
- J. Karwowski, O. Hayman, X. Bai, K. Kiendlhofer, C. Griffin, and J. Skalse. Goodhart's law in reinforcement learning. arXiv preprint arXiv:2310.09144, 2023. · arXiv
- Y. Li, F. Guerin, and C. Lin. Latesteval: Addressing data con- tamination in language model evaluation through dynamic and time-sensitive test construction. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 18600-18607, 2024.
- S. Lin, J. Hilton, and O. Evans. TruthfulQA: Measuring How Models Mimic Human Falsehoods, May 2022. URL http: //arxiv.org/abs/2109.07958. arXiv:2109.07958 [cs]. · arXiv
- L. McInnes, J. Healy, and J. Melville. UMAP: Uniform Manifold Approximation and Projection for Dimension Re- duction, Feb. 2018. URL https://arxiv.org/abs/ 1802.03426v3.
- H. Naveed, A. U. Khan, S. Qiu, M. Saqib, S. Anwar, M. Us- man, N. Akhtar, N. Barnes, and A. Mian. A compre- hensive overview of large language models, 2024. URL https://arxiv.org/abs/2307.06435. · arXiv
- Y. Oren, N. Meister, N. Chatterji, F. Ladhak, and T. B. Hashimoto. Proving Test Set Contamination in Black Box Language Models, Nov. 2023. URL http://arxiv. org/abs/2310.17623. arXiv:2310.17623 [cs]. · arXiv
- N. Reimers and I. Gurevych. Sentence-bert: Sentence em- beddings using siamese bert-networks. In Proceedings of the 2019 Conference on Empirical Methods in Natural Lan- guage Processing. Association for Computational Linguis- tics, 11 2019. URL https://arxiv.org/abs/1908. 10084.
- O. Sainz, J. A. Campos, I. García-Ferrero, J. Etxaniz, O. L. de Lacalle, and E. Agirre. Nlp evaluation in trouble: On the need to measure llm data contamination for each benchmark. arXiv preprint arXiv:2310.18018, 2023. · arXiv
- O. Sainz, I. García-Ferrero, J. Ander, Y. Elazar, and E. Agirre. CONDA 2024 | The 1st Workshop on Data Contamination, 2024. URL https://conda-workshop.github. io/.
- N. Sambasivan, S. Kapania, H. Highfill, D. Akrong, P. Par- itosh, and L. M. Aroyo. "everyone wants to do the model work, not the data work": Data cascades in high-stakes ai. In proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, pages 1-15, 2021.
- R. Schaeffer. Pretraining on the Test Set Is All You Need, Sept. 2023. URL https://arxiv.org/abs/2309. 08632v1.
- S. Shalev-Shwartz and S. Ben-David. Understanding Ma- chine Learning -From Theory to Algorithms. Cambridge University Press, 2014. ISBN 978-1-10-705713-5.
- W. Shi, A. Ajith, M. Xia, Y. Huang, D. Liu, T. Blevins, D. Chen, and L. Zettlemoyer. Detecting Pretraining Data from Large Language Models, Nov. 2023. URL http: //arxiv.org/abs/2310.16789. arXiv:2310.16789 [cs]. · arXiv
- M. Strathern. 'improving ratings': audit in the british univer- sity system. European review, 5(3):305-321, 1997.
- R. Thomas and D. Uminsky. The problem with met- rics is a fundamental problem for ai. arXiv preprint arXiv:2002.08512, 2020. · arXiv
- H. Zhang, J. Da, D. Lee, V. Robinson, C. Wu, W. Song, T. Zhao, P. Raja, D. Slack, Q. Lyu, S. Hendryx, R. Ka- plan, M. Lunati, and S. Yue. A Careful Examination of Large Language Model Performance on Grade School Arith- metic, May 2024. URL https://arxiv.org/abs/ 2405.00332v3.
- W. X. Zhao, K. Zhou, J. Li, T. Tang, X. Wang, Y. Hou, Y. Min, B. Zhang, J. Zhang, Z. Dong, Y. Du, C. Yang, Y. Chen, Z. Chen, J. Jiang, R. Ren, Y. Li, X. Tang, Z. Liu, P. Liu, J.-Y. Nie, and J.-R. Wen. A survey of large language models, 2023. URL https://arxiv.org/abs/2303.18223. · arXiv
- C. Zheng, H. Zhou, F. Meng, J. Zhou, and M. Huang. Large Language Models Are Not Robust Multiple Choice Selec- tors, Feb. 2024. URL http://arxiv.org/abs/2309. 03882. arXiv:2309.03882 [cs]. · arXiv
Cited by
Sorted by citations
Hallucination‐Free? Assessing the Reliability of Leading AI Legal Research Tools
Magesh, V., Surani, F., Dahl, M., Suzgun, M., Manning, C. D., & Ho, D. E. (2025) · Journal of Empirical Legal Studies · doi:10.1111/jels.12413 · Cited by 182
The bewitching AI: The Illusion of Communication with Large Language Models
Bottazzi Grifoni, E., & Ferrario, R. (2025) · Philosophy & Technology · doi:10.1007/s13347-025-00893-6 · Cited by 15
Sun, Y., Wang, H., Li, D., Wang, G., & Zhang, H. (2025) · arXiv · doi:10.48550/arxiv.2503.16402
“Some methods modify evaluation samples while preserving their semantics (Zhu et al., 2024b;a; 2023b; Li et al., 2024c; Wang et al., 2021; Xia et al., 2024; Haimes et al., 2024; Zheng et al., 2024).”
Metadata
- Authors
- Haimes, J., Wenner, C., Thaman, K., Tashev, V., Neo, C., Kran, E., & Schreiber, J.
- ORCID
- Kran, Esben
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2024
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2410.09247
- OpenAlex
- W4403564508
- Cited by
- 3
- References
- 1
- Citations by year
- 2026: 1 · 2025: 2
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion, cc-by-sa)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- large language models, training data contamination, benchmark validity, TruthfulQA, statistical indistinguishability, LLM evaluation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Benchmark Inflation: Revealing LLM Performance Gaps Using Retro-Holdouts. https://app.cochat.ai/papers/10.48550/arxiv.2410.09247
- The paper
- Haimes, J., Wenner, C., Thaman, K., Tashev, V., Neo, C., Kran, E., & Schreiber, J. (2024). Benchmark Inflation: Revealing LLM Performance Gaps Using Retro-Holdouts. arXiv. https://doi.org/10.48550/arxiv.2410.09247
