

The DOI matches its DataCite record; 45 of the 45 references it cites were found in a registry or an index; 4 of the 50 sources its claims cite were checked for support.
AstaBench: Rigorous Benchmarking of AI Agents with a Scientific Research Suite
Open accessAbstract
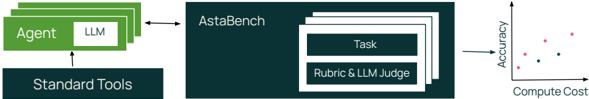
AI agents hold the potential to revolutionize scientific productivity by automating literature reviews, replicating experiments, analyzing data, and even proposing new directions of inquiry; indeed, there are now many such agents, ranging from general-purpose "deep research" systems to specialized science-specific agents, such as AI Scientist and AIGS. Rigorous evaluation of these agents is critical for progress. Yet existing benchmarks fall short on several fronts: they often (1) lack reproducible agent tools necessary for a controlled comparison of core agentic capabilities; (2) do not account for confounding variables such as model cost and tool access; (3) do not provide standardized interfaces for quick agent prototyping and evaluation; (4) fail to provide holistic, product-informed measures of real-world use cases such as science research; and (5) lack comprehensive baseline agents necessary to identify true advances. In response, we define principles and tooling for more rigorously benchmarking agents. Using these, we present AstaBench, a suite that provides a holistic measure of agentic ability to perform scientific research, comprising 2400+ problems spanning the entire scientific discovery process and multiple scientific domains, and including many problems inspired by actual user requests to deployed Asta agents. Our suite comes with the first scientific research environment with production-grade search tools that enable controlled, reproducible evaluation, better accounting for confounders. Alongside, we provide a comprehensive suite of nine science-optimized classes of Asta agents and numerous baselines. Our extensive evaluation of 57 agents across 22 agent classes reveals several interesting findings, most importantly that despite meaningful progress on certain individual aspects, AI remains far from solving the challenge of science research assistance.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
AstaBench is a new holistic benchmark suite for evaluating AI agents on scientific research assistance, comprising 2,400+ problems across 11 benchmarks, a controlled environment with production-grade literature search tools, and a cost-aware leaderboard. Evaluating 57 agents across 22 agent classes, the authors find that while literature understanding is reasonably strong, coding, experiment execution, data analysis, and end-to-end discovery remain largely unsolved.
Key findings
- The best overall agent, Asta v0 (a mixture of models), scores 53.0% overall versus 44.0% for ReAct with gpt-5; the best open-source agent with open-weight LLMs scores only 11.1% (Smolagents Coder with Llama-4-Scout-17B-16E-Instruct).
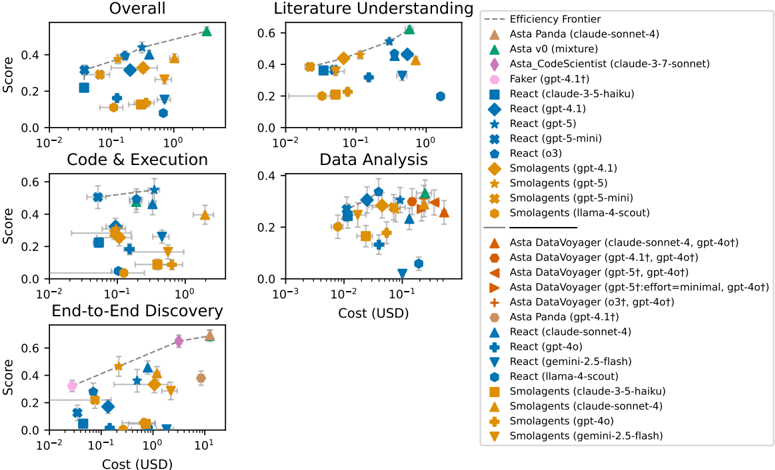
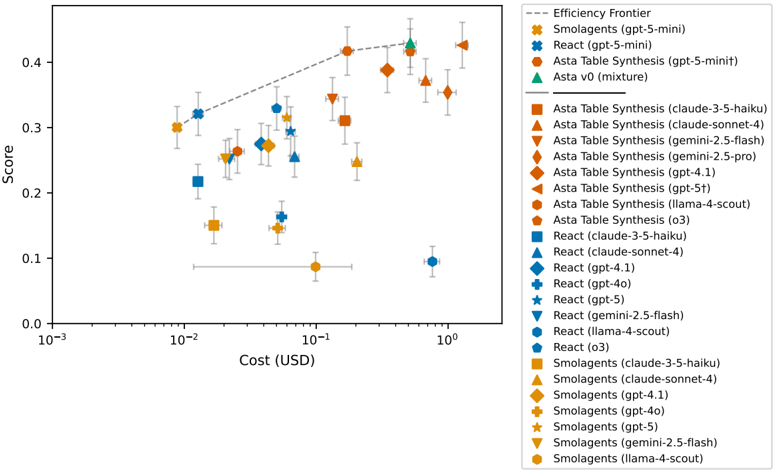
- Cost matters: ReAct with gpt-5-mini scores 32% overall at $0.04 per problem, "within 21% (absolute) of the best performing models" while costing over an order of magnitude less.
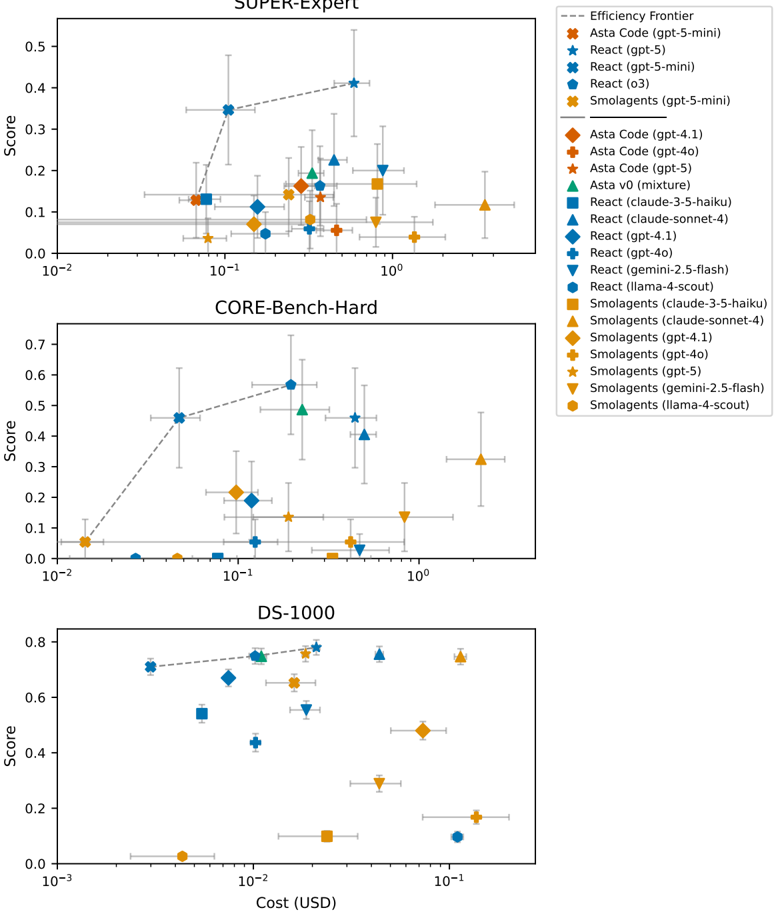
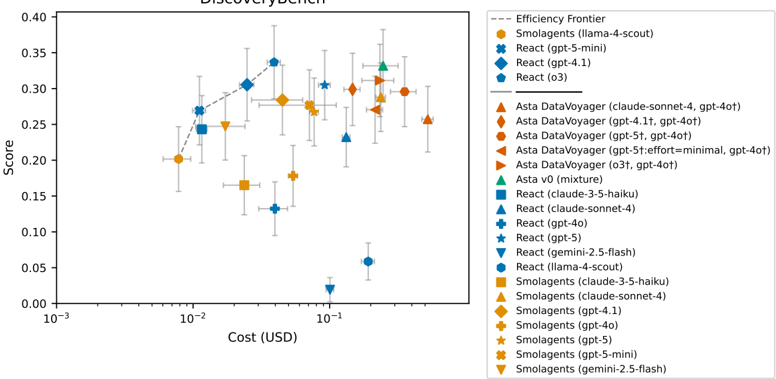
- Coding and execution are far from solved: all but two agents scored below 25% on SUPER-Expert (ReAct with gpt-5 scored 41%, gpt-5-mini 37%). Data analysis maxed out at 34% on DiscoveryBench.
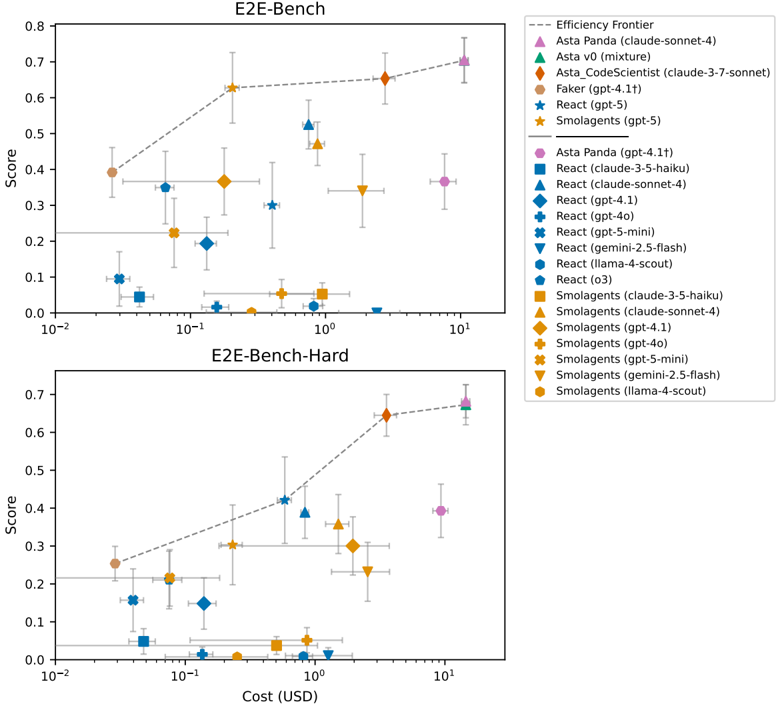
- End-to-end discovery is near-zero: although individual research-step completion reaches ~70%, the probability of completing all (~10–15) steps is ≈0.7^10 ≈ 3%, with actual numbers reaching a maximum of 5%.
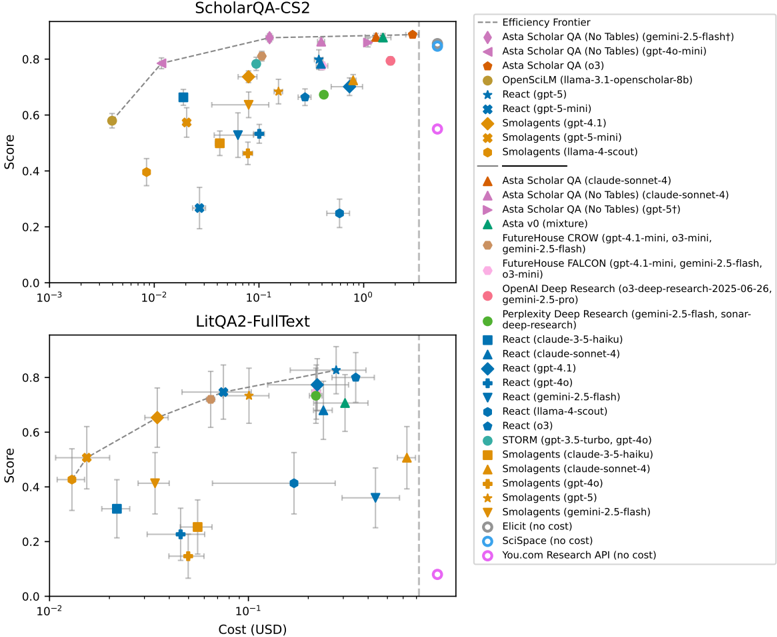
- Literature understanding is comparatively strong: best models score around 80% on QA, with Asta Scholar QA, Elicit, and SciSpace Deep Review all at ~85% or higher on ScholarQA-CS2; literature review table generation remains weak, with recall scores around 43%.
- gpt-5's effect is unpredictable: it boosts ReAct substantially (+13.4% on ScholarQA-CS2, +24.8% on SUPER-Expert, +25.3% on LitQA2-FullText-Search, +21.1% on E2E-Bench-Hard) but hurts several specialized agents (Asta Scholar QA, Asta DataVoyager, Asta Code).
Methods
- Design: 11 benchmarks spanning four categories — Literature Understanding (PaperFindingBench, LitQA2-FullText, LitQA2-FullText-Search, ScholarQA-CS2, ArxivDIGESTables-Clean), Code & Execution (SUPER-Expert, CORE-Bench-Hard-, DS-1000), Data Analysis (DiscoveryBench), and End-to-End Discovery (E2E-Bench, E2E-Bench-Hard) — totaling 2,400+ problems, many inspired by real user requests to deployed Asta agents.
- Infrastructure: the Asta Environment provides standardized, decoupled tools (Asta Scientific Corpus with date-restricted search, a computational notebook sandbox), and the agent-eval toolkit built on Inspect provides time-invariant cost accounting and leaderboards.
- Evaluation: 57 agents across 22 agent classes were run over several months; scoring uses LLM-as-judge against rubrics for some benchmarks (PaperFindingBench, ScholarQA-CS2, ArxivDIGESTables-Clean, DiscoveryBench, E2E-Bench, E2E-Bench-Hard) and programmatic evaluation for others (LitQA2-FullText, LitQA2-FullText-Search, SUPER-Expert, CORE-Bench-Hard-, DS-1000); 95% CIs are reported (±1.96 × SE).
Limitations
- Stated: E2E-Bench problems are specified in considerable detail, so they "only weakly test the ideation and planning steps"; rubric ingredients for ScholarQA-CS2 are sourced from evaluated systems, and hold-out experiments showed significant drops for three systems (average 2.5 points, p ≤ 0.01); semantic-query recall in PaperFindingBench uses an estimated set size rather than a definitive gold set; category-level standard errors are propagated assuming independence between tasks, "which could slightly underestimate uncertainty."
- Stated: Asta v0 was not evaluated with gpt-5 (experiments began before its release), and Asta Code was selected based on early experiments with older models despite ReAct with o3 performing better on SUPER-Expert.
- Evident from the text: several agents (Elicit, SciSpace, OpenAI Deep Research, OpenSciLM, Asta Panda, Asta CodeScientist) were graded from cached results rather than live runs, and some commercial agents could not be evaluated on all benchmarks (e.g., no API access for LitQA2-FullText), limiting comparability.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
49 No basis given · 47 Own result · 37 Own interpretation · 28 Sources not found · 28 Own method · 3 Check pending · 2 Supported · 2 Partly supported · 2 Not checked yet · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“They are based on the LitQA2 dataset (Skarlinski et al., 2024), which contains 199 multiple-choice questions, each associated with a target paper whose full-text can potentially answer the question.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > D FULL EXPERIMENTAL RESULTS
What the sources say
- Partly supportedcites Skarlinski et al., 2024 sourceExperimental — accuracy not yet measured
Section 2, “Answering scientific questions” (page not provided), describes LitQA2 as multiple-choice questions linked to an assigned source DOI, with answers designed to appear in a paper’s main body. But it states that the dataset contains 248 questions, not 199, and notes that some questions are intended to be unanswerable. (LLM, conf=0.90)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Here we report results also on the original LitQA2 dataset of Skarlinski et al. (2024), in which 114 out of the 199 queries have only their abstracts, and not full text, represented in our search index.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > G.2 EVALUATION ON FULL SET OF LITQA2 DATASET
What the sources say
- Supportedcites Skarlinski et al., 2024 source
Section 2, “Answering scientific questions,” identifies Skarlinski et al. as the creators of LitQA2, so the citation supports the identification of the dataset. The statement that 114 of 199 queries have only abstracts in “our search index” describes the citing authors’ own index, not a finding attributed to Skarlinski et al.; the source describes LitQA2 as 248 questions in total. (LLM, conf=0.88)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“As LitQA2 was designed as a full-text search benchmark, our main results are on the LitQA2-FullText-Search subset, for which our corpus contains full-text to all papers.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > G.2 EVALUATION ON FULL SET OF LITQA2 DATASET
What the sources say
- Supportedcites Skarlinski et al., 2024 source
Section 2, “Answering scientific questions,” describes LitQA2 as a benchmark for retrieval from scientific literature and says its questions were designed so answers appear in a paper’s main body, not its abstract. That supports the characterization of LitQA2 as a full-text search benchmark; the citing authors’ statement about their own corpus is not attributed to this source. (LLM, conf=0.91)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“AstaBench includes more classes of agents than prior benchmarking efforts.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“We also introduce the agent-eval Agents Evaluation Toolkitfoot_2 (Section 4.2), which enables defining a benchmark suite and leaderboard with time-invariant cost accounting using model usages logged by Inspect (UK AI Security Institute, 2024)”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
What the sources say
- Not matchedcites UK AI Security Institute, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The agent-eval toolkit computes normalized dollar costs based on model usages logged through Inspect.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 4.2 A G E N T-E V A L EVALUATION TOOLKIT & ASTABENCH LEADERBOARD
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We introduce AstaBench Leaderboard 4 built using this Toolkit.It's the first agent leaderboard to properly account for confounding variables such as the tools used by the agent and inference cost.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“we provide a comprehensive suite of nine science-optimized classes of Asta agents and numerous baselines.”
- Also stated in: § 1 INTRODUCTION · plain
“we present the agent-baselines Agents Suitefoot_4 (Section 4.3), the most comprehensive standardized agents suite, comprised of nine Asta agent classes that have been optimized for scientific research tasks, as well as numerous baselines.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“AstaBench comprises the following 11 benchmarks”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 3 ASTABENCH: A HOLISTIC SCIENTIFIC RESEARCH BENCHMARK SUITE
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our extensive evaluation of 57 agents across 22 agent classes reveals several interesting findings”
- Also stated in: § 1 INTRODUCTION · plain
“We report on an extensive set of experiments on AstaBench using our agents suite with 57 agents spanning 22 classes of agent architectures”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · plain
- It may state two separate claims as one. 66
- Probably not a substantial claim. 81
- The quote only partly states this claim. 2
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“They focus on purely semantic criteria, not covering metadata or navigational queries, and they are missing a methodological process to cover the different within-semantic challenging types.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.2 PA P E RFI N D I N GBE N C H
What the sources say
- Not matchedcites Ajith et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites He et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Partly supportedcites Skarlinski et al., 2024 sourceExperimental — accuracy not yet measured
Section 2, “Answering scientific questions” (page unavailable), describes LitQA2 questions about findings in papers’ main bodies, supporting the characterization of this benchmark as focused on content-based queries. Section 8.2.1 describes a question-construction methodology, but our copy does not establish that paper-finding benchmarks generally exclude metadata or navigational queries, or assess whether they systematically cover different types of semantic challenge. (LLM, conf=0.76)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“we present AstaBenchfoot_0 (Section 3), a more rigorous agent benchmark suite that is a holistic measure of scientific research, which exercises a broad spectrum of skillsincluding literature understanding, data understanding, planning, tool use, coding, and search”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Asta Scientific Corpus: A toolset for accessing the scientific literature, which represents the first production-grade, reproducible search tools for agents.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 4.1 STANDARD TOOLS FOR AGENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“we provide the agent-baselines Agents Suite, 12 which consists of a large set of agents from 16 agent classesfoot_12 with a standard Inspect-compatible interface.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 4.3 A G E N T-B A S E L I N E S AGENTS SUITE
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“They are cleanly decoupled from agents and provide easy integration via MCP.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 4.1 STANDARD TOOLS FOR AGENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Asta Environment is, to our knowledge, the first realistic, reproducible scientific research environment for agents.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 4 ASTA ENVIRONMENT
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“we present AstaBench, a suite that provides a holistic measure of agentic ability to perform scientific research, comprising 2400+ problems spanning the entire scientific discovery process and multiple scientific domains, and including many problems inspired by actual user requests to deployed Asta agents.”
- Also stated in: § 1 INTRODUCTION · plain
“comprises over 2400 problems spanning the full scientific discovery process and multiple scientific domains, including many problems based on real user requests from Asta”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The Asta user requests used to inspire benchmark problems are representative of real-world scientific research use cases.
- Also stated in: § 1 INTRODUCTION · plain
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“It is easy to integrate new general agents with AstaBench, which provides a standardized task interface.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We present AstaBench, the first benchmark suite for holistic evaluation of agents' ability to perform scientific research.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 3 ASTABENCH: A HOLISTIC SCIENTIFIC RESEARCH BENCHMARK SUITE
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Asta Table Synthesis, backed by gpt-5, wins on this task, beating the best general agents.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The other external/commercial agents are not far behind, but also do not do significantly better than the best ReAct baseline.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Though the per-token cost is 3 to 25 times lower for gemini-flash and llama-scout compared to o3 or sonnet, the weaker models often take more steps or get stuck in loops, causing a ReAct agent to end up being twice as expensive in addition to lower-performing.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Coding and execution is far from solved-all agents score low on these tasks, e.g., all but two scored below 25% on SUPER-Expert”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The best economical model is ReAct with gpt-5-mini, scoring 32%-within 21% (absolute) of the best performing models-while costing over an order of magnitude less at $0.04 per problem.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Asta Scholar QA, Elicit, and SciSpace Deep Review are the best tools on these tests (all score about 85% or higher on ScholarQA-CS2, Table 6).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“As noted above, agents powered by closed weight LLMs currently far exceed the reach of those powered by open weight LLMs.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“(ReAct with gpt-5 scored 41% and gpt-5-mini scored 37%; Tables 8 and 15)”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Although the average research step completion scores appear reasonable (scores up to ∼70%, Table 10), the likelihood of completing all experiment steps remains near zero.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Analysis:
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, this comes with the trade-off of significantly higher development (engineering) cost, and (for some tasks, specifically in end-to-end-discovery) higher inference cost.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, Asta Table Synthesis backed by gpt-5-mini also shows competitive performance, at just 13% of the cost.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
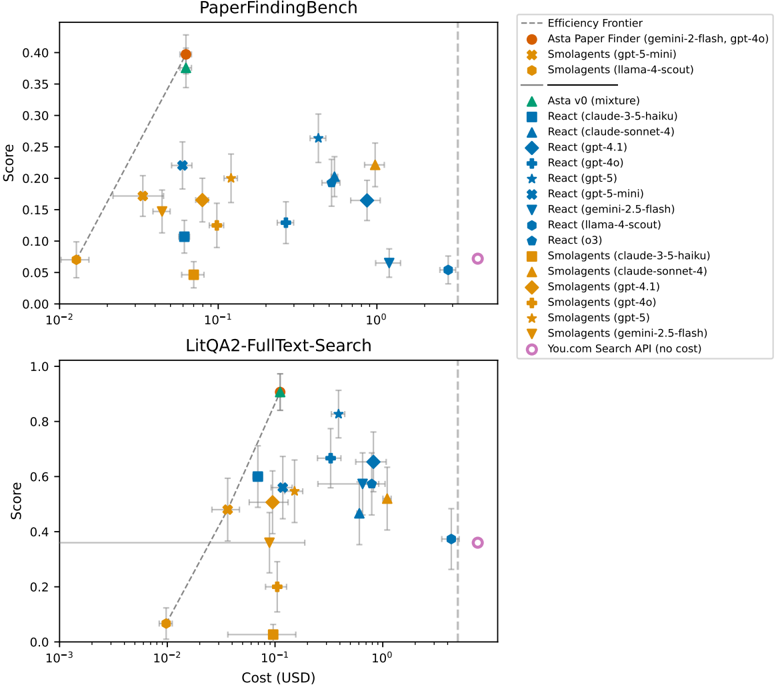
“However, gpt-5 provides a huge boost in 4 benchmarks: +13.4% absolute on ScholarQA-CS2 (Table 6), + 24.8% on SUPER-Expert (Table 8), +25.3% on LitQA2-FullText-Search (Table 5), and +21.1% on E2E-Bench-Hard (Table 10).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“PaperFindingBench includes 48 navigational queries, 43 metadata queries, and 242 semantic queries.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.2 PA P E RFI N D I N GBE N C H
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“the Asta Environment, the first scientific research environment for agents with realistic, controlled search tools.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 6 CONCLUSION AND FUTURE WORK
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“AstaBench is the first major agent benchmark suite to come with standard environment and tools that enable controlled comparison of agents”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 6 CONCLUSION AND FUTURE WORK
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Some of the metadata queries contain (easy) navigational queries as part of their criteria, but there is currently a strict separation between metadata and semantic queries (metadata queries do not involve a semantic component and vice-versa), which may change in future versions.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.2 PA P E RFI N D I N GBE N C H
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While the best API-based agent (FutureHouse Falcon) and closed agent (OpenAI Deep Research) score well on a single benchmark (Table 6), they are stymied by the full range of tasks.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“we present the agentbaselines Agents Suite, a large suite of standardized agents”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 6 CONCLUSION AND FUTURE WORK
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For example, given ∼10 steps per experiment, and a success rate of 70% per step, the success rate to complete all steps in the experiment will be ≈ 0.7 10 ≈ 3% (see Table 20 for actual numbers, reaching a maximum of 5%).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Analysis:
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The success rate per step is independent across steps in the end-to-end discovery calculation.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Surprisingly, most of our specialized agents (Asta Scholar QA (Table 6), Asta DataVoyager (Table 4), Asta Code (Table 8)) perform worse with gpt-5 than with previous models, while ReAct performs much better.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We see agents struggle with this benchmark, with the maximum score being only 34% (Table 4)”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Analysis:
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“While individual step completion accuracy is reasonable (up to ∼70%, Table 10), the likelihood of completing all (typically 10-15) steps remains near zero due to compounding.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Domain Percentage
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This approach sometimes confuses highly similar tasks that have the same answer format (e.g.PaperFindingBench and LitQA2-FullText-Search)”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Additional information
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We do not claim this is the optimal way of structuring such a component, but we found it to be effective and have lower latency compared to a longer prompt that extracts all of the information pieces.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.3.1 QUERY ANALYSIS
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Although this internal set is not an established benchmark it has been proven useful to monitor retrieval quality and detect any regressions in recall or ranking performance.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To guard against runaway loops, we also cap the agent at a maximum of 100 steps per task; in practice agents submit well before this limit (most models average under 12 steps).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.2 BASELINE AGENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“| PaperFinder (ours) | LitQA2-FullText- | 100% | 80 | 80 |”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The field of study distribution in the test set is 14 Social Sciences problems (37.8%), 12 Medical Sciences (32.4%), and 11 CS (29.7%).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.6 CORE-BE N C H-HA R D -
plainn = 37- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Finally, while we found it may be possible to prompt Perplexity Sonar Deep Research to extract quotes in each of its cited sources, the API does not explicitly return these snippets; thus, we evaluate the model as if it only cites the title and URL of each page.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These are based on metadata requests that appear frequently enough in our logs, but for which we do not currently have metadata support in the APIs and indices.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.3.1 QUERY ANALYSIS
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found the manual-coding approach to be more efficient (in terms of number of LLM calls, number of tokens, and in terms of the ability to parallelize) and more reliable than a more dynamic process that grants more autonomy to the LLM, allowing it to write code and significantly influence the computation flow and search process.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We remove instances that would require a GPU to run, to keep the resource requirements in line with the rest of the tasks.This reduces the dataset to 37 samples instead of the original 45.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.6 CORE-BE N C H-HA R D -
plaindirectn = 37- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“There are also some agents that proport to have structured output capabilities but whose output quality drops dramatically when it is enabled.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“| PaperFinder (ours) | LitQA2-FullText- | 100% | 93.3 | 90.7 |”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“To enable accurate assessment of citation recall and citation precision, we leverage a feature of many evaluated systems: they provide quotes from each cited article intended to support the associated claim.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.3 SC H O L A RQA-CS2
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For some queries, a non-negligible number of matching snippets refer to other papers (”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Initial-search.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“| PaperFinder (ours) | full (199) | <50% | 70.3 | 64.3 |”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“| PaperQA2 (Skarlinski et al. (2024)) full (199) | 100% | 69.9 | 62.8 | |”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
What the sources say
- Not checked yetcites Skarlinski et al. (2024) source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, at the time of running the system (August 3rd-7th, 2025), this disabled web search entirely, so we did not set this parameter.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Rests on an assumption: The Perplexity API provides a 'search_mode' parameter that can be set to 'academic' to only retrieve academic sources.
In the paper
“The results in Table 23 show that PaperFinder agent obtains very similar results to the agent of Skarlinski et al. (2024) despite having access to only abstracts for over half the papers, and scores significantly higher on the subsets where full text is available.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > G.2 EVALUATION ON FULL SET OF LITQA2 DATASET
What the sources say
- Not checked yetcites Skarlinski et al., 2024 source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This three-facet approach adds substantial robustness to scoring, in particular helping avoid false positives (FP), e.g., the report states an experiment was run, but the code shows otherwise, and recover from false negatives (FN), e.g., paper doesn't mention a criterion, but code shows it was indeed implemented, see Table 21.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.9 VALIDATION OF END-TO-END DISCOVERY AGENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“At the system level, we find moderate human-model agreement (Kendall τ = 0.467), which rises substantially to 0.800 when excluding Elicit outputs for which experts show systematic dispreference.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Collection
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“the relatively poor performance of GPT-5 on many specialized solvers”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Additional information
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The results show that the effect of being held out varies across systems, with three (Asta Scholar QA (w/ Tables), Elicit, and SciSpace Deep Review) experiencing significant drops in performance in the held-out condition (average 2.5 point drop; p <= 0.01) and two (OpenAI Deep Research and Perplexity Sonar Deep Research) with insignificant drops (< 1 point drop; p > 0.16).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Collection
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Finally, benchmark suites lack comprehensive agent baselines for proper comparison.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“As a result, most published evaluations only compare to a small number of other agents or ablations, making it difficult to assess whether claimed improvements represent genuine advances.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“AI agents hold the potential to revolutionize scientific productivity by automating literature reviews, replicating experiments, analyzing data, and even proposing new directions of inquiry”
- Also stated in: § 1 INTRODUCTION · hedged
“In particular, they hold the promise to revolutionize scientific productivity by automating reviews of the literature, replicating complex experiments, analyzing high volumes of data, and even proposing new avenues to explore.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Abstract
What the sources say
- Not matchedcites Lu et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Yamada et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Liu et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Also stated in: § 1 INTRODUCTION · hedged
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“most importantly that despite meaningful progress on certain individual aspects, AI remains far from solving the challenge of science research assistance.”
- Also stated in: § 1 INTRODUCTION · plain
“We find that while meaningful progress has been made on many fronts, science research assistance remains far from solved.”
- Also stated in: § 6 CONCLUSION AND FUTURE WORK · plain
“most importantly that despite meaningful progress on certain individual aspects, agentic AI remains far from solving the challenge of scientific research assistance.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § 1 INTRODUCTION · plain
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“for example, no large-scale, controlled document retrieval tools exist, making it unclear whether a 'winning' agent has superior AI capabilities or merely access to a more relevant information source.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Fourth, they often lack tasks that are informed by authentic product usage data (typically guarded by technology companies), raising concerns that higher scores may not lead to meaningful real-world benefit.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
- Rests on an assumption: Real-world product usage data is typically guarded by product companies and unavailable to academic benchmark creators.
In the paper
“The capsules in CORE-Bench-Hardare chosen to be highly reproducible and span a variety of domains, including computer science, social science, and medicine, and use Python and R programming languages.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > CORE-Bench-Hard -
What the sources say
- Not matchedcites Siegel et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
“The SUPER-Expert benchmark (Bogin et al., 2024) (Setting UP and Executing tasks from Research repositories) tests the ability of code agents to set up and execute Python machine learning experiments reported in ML and NLP papers.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > SUPER-Expert
What the sources say
- Not matchedcites Bogin et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Rests on an assumption: Setting up and running code from sparsely documented repositories accompanying published papers is a common, non-trivial, and time-consuming task.
- Not matched
In the paper
“Asai et al. (2024) introduced ScholarQABench, which consists of multiple datasets to evaluate scientific QA systems over several dimensions.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.3 SC H O L A RQA-CS2
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
“We release a new benchmark that builds on ArxivDIGESTables, the first high-quality dataset for literature review table generation created by Newman et al. (2024) by extracting review tables from ArXiv papers.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ScholarQA-CS2
What the sources say
- Not matchedcites Newman et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
In the paper
“ScholarQA-CS2 is a new benchmark that builds upon the recent ScholarQA-CS (Asai et al., 2024) by incorporating real scientific queries and introducing four facets for coverage and precision evaluation of both answers and their attributions, using LLMas-judge.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ScholarQA-CS2
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
In the paper
“The CORE-Bench-Hard -benchmark (Siegel et al., 2025) tests an agent's ability to reproduce experiments and analyses from papers.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > CORE-Bench-Hard -
What the sources say
- Not matchedcites Siegel et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The framework logs and reports specific repository commits, including for data.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > REPRODUCIBILITY STATEMENT
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We also report the standard deviation of our measurements.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the semantic queries, which are based on LLM judgement, we can compute precision, but not recall.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Dataset Creation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Most existing benchmark suites lack standard tools, leading agent developers to use disparate environments and tools that obscure whether performance differences are due to superior AI capabilities or other enhancements.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > A PRINCIPLES FOR BENCHMARKING AGENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In general, today's agents are reasonably good at literature understanding.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“This benchmark contains 1000 problems involving 7 Python libraries that were originally collected from StackOverflow and perturbed to avoid training leakage.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > DS-1000
What the sources say
- Not matchedcites Lai et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, despite some recent progress, coding, experiment execution, data analysis, and data-driven discovery still remain major, unsolved problems for science assistance agents.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
In the paper
“The DS-1000 benchmark (Lai et al., 2023) tests the ability of code models on routine data science tasks encountered in everyday research.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > DS-1000
What the sources say
- Not matchedcites Lai et al., 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“PaperFindingBench is designed to be challenging (including things that our system currently does not perform well on) and realistic (based to the extent possible on real-world queries and information needs).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.2 PA P E RFI N D I N GBE N C H
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Coding and execution thus remain major bottlenecks for assisting with and automating science.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For numerous queries, assessing the relevance of the paper cannot be done solely based on title and abstract, but requires evidence from the paper's full text.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Dataset Creation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Note that in extreme cases, this may result in a recall number larger than 1.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Dataset Creation
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“It fills a gap in the current research landscape where there are many such agents, e.g., AI Scientist (Lu et al., 2024), AgentLab (Schmidgall et al., 2025), and CodeScientist (Jansen et al., 2025), but no systematic way to compare them.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E2E-Bench
What the sources say
- Not matchedcites Lu et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Schmidgall et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Jansen et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This task is similar to E2E-Bench, except the problems are generally harder.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E2E-Bench-Hard
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“For the semantic queries, the full-coverage gold-set does not exist, and we resort to a combination of partial annotation and LLMbased judgement.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Dataset Creation
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“AstaBench comes with open source code for all included benchmarks, agents, and core infrastructure-as well as logs of all reported experiment.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > REPRODUCIBILITY STATEMENT
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“The DiscoveryBench (Majumder et al., 2025) benchmark aims to test whether the agent can automatically find and verify hypotheses from given dataset(s), performing data-driven analysis.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > DiscoveryBench
What the sources say
- Not matchedcites Majumder et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“For a fifth of the queries, the relevance criteria were manually verified and corrected or tweaked.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Dataset Creation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Controlling for tool usage is also essential to separate gains due to model or agent architecture advancements from benefits due to privileged access to specialized information sources.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > A PRINCIPLES FOR BENCHMARKING AGENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Despite this, it is clear that the paper-finding task is far from 'solved,' requiring further work to achieve truly comprehensive results.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The final evaluation metric is an average of per-query scores.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In our new dataset, we instead collect a diverse set of key ingredients from a variety of candidate system responses, and also develop new LLM-as-judge approaches for answer relevance and improved citation evaluation.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.3 SC H O L A RQA-CS2
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Generic columns are trivially easy to generate (over-optimistic performance estimates), while unrecoverable columns are impossible to generate (under-optimistic estimates).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.4 AR X I VDIGESTA B L E S-CL E A N
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“The OpenSciLM paper evaluated multiple variants of its RAG pipeline, here we evaluate the publicly available demo system which uses an open 8B-parameter Llama-3.1 backbone fine-tuned on synthetic data.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Smolagents Coder is the reference
What the sources say
- Not matchedcites Asai et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“All reports sourced were obtained before the cutoff date of June 24, 2025.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The rubrics were checked manually (and updated where needed) by human annotators.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.9 VALIDATION OF END-TO-END DISCOVERY AGENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“Agent counts for Table1were derived from live leaderboards and repositories accessed August 2025, in addition to the canonical benchmark references (Microsoft, 2024; ServiceNow, 2025; SAgE Team, Princeton University, 2025; ArcadiaImpact / UK Government BEIS Team, 2025; All-Hands-AI, 2025a;b; The Terminal-Bench Team, 2025b).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
What the sources say
- Not matchedcites Microsoft, 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites ServiceNow, 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites SAgE Team, Princeton University, 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Our Asta v0 experiments were started prior to the release of gpt-5”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Additional information
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“(OpenAI Deep Research) score well on literature understanding, but are unable to perform the full spectrum of science research assistance.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The AstaBench tasks are a valid measure of science research assistance.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“navigational and metadata queries are evaluated in terms of F1 over the result set”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This agreement is higher than the agreement with individual metrics (38.7%-63.5%),which suggests that the metrics may be working in concert to more accurately capture human judgment-complementing one another in ways that counterbalance their individual weaknesses and collectively achieving more than any single metric can on its own.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Data Collection
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“AstaBench includes two of the original splits from Bogin et al. (2024): the Expert split containing 45 end-to-end problems as our test set and the Auto split containing 50 auto-generated problems (generated based on the README file of respositories that pass a certain filter) as our development set.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.5 SUPER-EX P E R T
What the sources say
- Not matchedcites Bogin et al. (2024)
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Since the Asta Panda source code26 has not yet been integrated, we grade the cached results.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“The TABEVAL protocol first represents a generated table's semantics by breaking it down into a list of natural language atomic statements, a process referred to as table unrolling.Then, it compares these statements against ground truth statements produced from a reference table using entailment-based measures.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.4 AR X I VDIGESTA B L E S-CL E A N
What the sources say
- Not matchedcites Ramu et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Benchmarks are fully reproducible when paired with the Asta Environment tools listed in the 'Tools' column, which come standard with each benchmark”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, this decomposed evaluation has two disadvantages.First, it requires agents evaluated on this task to expose the same set of components (column generation and cell value generation), instead of allowing flexibility in agent design.Second, cell value evaluation is conducted by providing agents with the set of”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.4 AR X I VDIGESTA B L E S-CL E A N
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“Newman et al. (2024) originally proposed a reference-based automated evaluation procedure for the task of literature review table generation.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.4 AR X I VDIGESTA B L E S-CL E A N
What the sources say
- Not matchedcites Newman et al. (2024)
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
In the paper
“Previous work has found that code-based tool calling can outperform other formats in practice (Wang et al., 2024), and it has the theoretical advantages of being able to manipulate values by reference and represent logic structures such as loops in a single step, as opposed to the LLM having to simulate these structures over a long sequence of calls.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Smolagents Coder is the reference
What the sources say
- Not matchedcites Wang et al., 2024
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Asta Panda performs research via a LLM-based plan-and-act (hence “Panda”) cycle.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Reported values are macro averages over benchmark statistics; confidence intervals are omitted.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Given a research task, it first generates a natural language plan, then systematically performs each plan step in turn, then writes a report on the outcome.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The rubric scores were validated using spot-check sampling and verification by a human (judged 92% correct on a dev set sample of 50 rubric items).”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.9 VALIDATION OF END-TO-END DISCOVERY AGENTS
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The creation of tables leads to more LLM calls resulting in higher costs as well.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.1 ASTA AGENTS
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We did not do any task-specific modifications or tuning of PaperFinder for this task.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > G.2 EVALUATION ON FULL SET OF LITQA2 DATASET
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Slightly less than the 22 we evaluate because some are closed source and thus not usable on new inputs; however, we provide ways to reproducing those results based on cached answers obtained for our experiments.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“If there are too many failures the system replans from the failed step.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Each plan step is performed using a ReAct/CodeAct-style loop of (a) write Python code (b) execute it (c) reflect, and either recode (if step failed/incomplete) or move to the next plan step depending on the outcome.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Agents without an API could not be evaluated on LitQA2-FT.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“For ArxivDIGESTables-Clean, corpus tools are restricted to snippet search with specific paper IDs for each problem.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“semantic queries use the harmonic mean of estimated recall and nDCG”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Specifically, we source from the eight”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The quote only partly states this claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Importantly, this formalization allows for systematic, reproducible evaluation over a wide variety of real-world problems, by leveraging these facets.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.7 DS-1000
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We also note that Asta Code was chosen based on very early experiments with relatively old models”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Additional information
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Original datasets were filtered to ensure questions are answerable with the environment.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“AstaBench benchmarks, spanning four task categories: Literature Understanding, Code & Execution, Data Analysis, and End-to-End Discovery.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Note that these citation metrics do not verify that citations refer to real papers or that quoted snippets actually appear in the cited sources.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.3 SC H O L A RQA-CS2
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Their procedure consists of two components: evaluating the schema (columns) and values (cells) for a generated table.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.4 AR X I VDIGESTA B L E S-CL E A N
What the sources say
- Not matchedcites Newman et al. (2024)
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Intuitively, these are relevant results which are at the boundaries of the current search queries.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > Initial-search.
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Science research assistance is still far from solved, as evidenced by the generally low overall scores for the full gamut of agents, from fully open to fully closed.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The AstaBench tasks are a valid measure of science research assistance.
- Rests on an assumption: The set of agents evaluated is representative of the full gamut of agents, from fully open to fully closed.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For sanity, we look at the difference between the average accuracy result reported for PaperQA2 (66.0) and FutureHouse Crow (72.0) and conclude that evaluating on fewer questions and with better SOTA models explains it.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
- Rests on an assumption: At the time, PaperQA2 used gpt-4-turbo as the backbone LLM, while FutureHouse Crow, which is based on PaperQA2, uses gpt-4.1-mini.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Answering this question is hard, as data-driven discovery in the wild (real-world) is diverse across domains and subject areas, which in turn makes it difficult to build a robust evaluation framework to measure progress.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.7 DS-1000
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The increasing adoption among users serves as additional corroboration of both the effectiveness of the agent and the correctness of our internal evaluation methodology.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > F.6 SM O L A G E N T S CO D E R PROMPT
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
- Rests on an assumption: Asta Paper Finder is actively used by a growing number of users.
In the paper
“DiscoveryBench (Majumder et al., 2025) is a novel benchmark for discovering data-driven hypotheses.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > E.7 DS-1000
What the sources say
- Not matchedcites Majumder et al., 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
The paper relies on this without support.
Real-world product usage data is typically guarded by product companies and unavailable to academic benchmark creators.
“Real-world product usage provides an informative basis for determining appropriate tasks, but unfortunately such data is typically guarded by product companies (who use it to create private evaluations) and unavailable to academic benchmark creators.”
The paper relies on this without support.
Large-scale, optimized search indexes are costly to create.
“yet large-scale, optimized search indexes are costly to create and public search tools are not reproducible”
The paper relies on this without support.
Public search tools are not reproducible.
“yet large-scale, optimized search indexes are costly to create and public search tools are not reproducible”
The paper relies on this without support.
The Asta user requests used to inspire benchmark problems are representative of real-world scientific research use cases.
“including many problems inspired by actual user requests to deployed Asta agents”
The paper relies on this without support.
The success rate per step is independent across steps in the end-to-end discovery calculation.
“given ∼10 steps per experiment, and a success rate of 70% per step, the success rate to complete all steps in the experiment will be ≈ 0.7 10 ≈ 3%”
The paper relies on this without support.
Most previous benchmark suites require general agent developers to adapt agents for individual tasks, introducing developer bias and hindering development.
“Unfortunately, most previous benchmark suites require general agent developers to adapt agents for individual tasks, introducing developer bias and hindering development.”
The paper relies on this without support.
A large integrated suite of agent baselines is lacking from current agent suites, resulting in most evaluations comparing only to a small number of other agents or ablations on the evaluator's own agent.
“A large integrated suite of agent baselines must be available to identify which agents are truly state-of-the-art agents and to provide high-quality starting points for future development, yet is lacking from current agent suites resulting in most evaluations comparing only to a small number of other agents or ablations on the evaluator's own agent.”
The authors state this as an assumption.
The propagation of standard errors assumes independence between tasks, which could slightly underestimate uncertainty.
“This propagation assumes independence between tasks, which could slightly underestimate uncertainty.”
The authors state this as an assumption.
The set contains a mix of queries for which there are many relevant results, and queries for which only a handful of results exist.
“The set contains a mix of queries for which we assume there are many relevant results, and queries for which we assume only a handful of results exist.”
The paper relies on this without support.
Setting up and running code from sparsely documented repositories accompanying published papers is a common, non-trivial, and time-consuming task.
“It targets the common yet often non-trivial and time-consuming task of setting up and running code from sparsely documented repositories accompanying published papers.”
The authors state this as an assumption.
The published workflows used as gold trajectories in DiscoveryBench are scientifically valid.
“As most of the papers are highly cited, peer-reviewed, and from top venues in the domains, it is reasonable to assume the published workflows are scientifically valid.”
The paper relies on this without support.
Data-driven research is the cornerstone of scientific progress in the six selected domains: sociology, biology, humanities, economics, engineering, and meta-science.
“We focus on six scientific domains where data-driven research is the cornerstone of scientific progress: sociology, biology, humanities, economics, engineering, and meta-science.”
The paper relies on this without support.
Papers in academic scientific-literature retrieval benchmarks focus almost exclusively on semantic criteria.
“Papers in academic scientific-literature retrieval benchmarks focus almost exclusively on this criteria.”
The paper relies on this without support.
Real-world queries may include additional details such as metadata constraints or other properties.
“However, real-world queries may include additional details such as metadata constraints or other properties, as discussed below.”
The paper relies on this without support.
The order in which we go over the results matters for efficiency.
“The order in which we go over the results matters for efficiency.”
The paper relies on this without support.
Asta Paper Finder is actively used by a growing number of users.
“For Asta Paper Finder, an expanded and continuously developed version of the agent-including a user interface and additional infrastructure-is actively used by a growing number of users.”
The paper relies on this without support.
At the time, PaperQA2 used gpt-4-turbo as the backbone LLM, while FutureHouse Crow, which is based on PaperQA2, uses gpt-4.1-mini.
“Further, at the time, PaperQA2 used gpt-4-turbo as the backbone LLM, while FutureHouse Crow, which is based on PaperQA2 uses gpt-4.1-mini.”
The paper relies on this without support.
The Perplexity API provides a 'search_mode' parameter that can be set to 'academic' to only retrieve academic sources.
“The Perplexity API also provides a”
The paper relies on this without support.
The AstaBench tasks are a valid measure of science research assistance.
“Science research assistance is still far from solved, as evidenced by the generally low overall scores for the full gamut of agents, from fully open to fully closed.”
The paper relies on this without support.
The set of agents evaluated is representative of the full gamut of agents, from fully open to fully closed.
“the full gamut of agents, from fully open to fully closed”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
“AutoGen-Bench × No science × × × × Coupled to agent framework 7 11”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 1 INTRODUCTION
“The table's final column, titled 'Cls.',indicates the number of agent classes (e.g., ReAct) that are used to instantiate (e.g., with specific LLMs) the total number of agents listed in preceding column;”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
“As a case in point, one of the newest LLMs, gpt-5, provides only a modest boost over an earlier "reasoning LLM", o3, except on three benchmarks.”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
“However, gpt-5 provides a huge boost in 4 benchmarks: +13.4% absolute on ScholarQA-CS2 (Table 6), + 24.8% on SUPER-Expert (Table 8), +25.3% on LitQA2-FullText-Search (Table 5), and +21.1% on E2E-Bench-Hard (Table 10).”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > 5 EXPERIMENTS
“ReAct with gpt-5 scored 41% and gpt-5-mini scored 37%; Tables 8 and 15”
§ ASTABENCH: RIGOROUS BENCHMARKING OF AI AGENTS WITH A SCIENTIFIC RESEARCH SUITE > ↩→
“∼ ✓ ReAct | gpt-5-mini 34.6 ± 13.2 0.105 ± 0.046 45.9 ± 16.3 0.047 ± 0.014 71.0 ± 3.0 0.003 ± 0.0001”
Citations
Cites
Agent Laboratory: Using LLM Agents as Research AssistantsPreprint
Schmidgall, S., Su, Y., Wang, Z., Sun, X., Wu, J., Yu, X., Liu, J., Moor, M., Liu, Z., & Barsoum, E. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2501.04227 · Cited by 387
PaperBench: Evaluating AI's Ability to Replicate AI Research
Starace, G., Jaffe, O., Sherburn, D., Aung, J., Chan, J. S., Maksin, L., Dias, R., Mays, E., Kinsella, B., Thompson, W., et al. (2025) · arXiv · doi:10.48550/arxiv.2504.01848 · Cited by 310
Show Your Work: Improved Reporting of Experimental Results
Dodge, J., Gururangan, S., Card, D., Schwartz, R., & Smith, N. A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1224 · Cited by 233
AI-Researcher: Autonomous Scientific Innovation
Tang, J., Xia, L., Li, Z., & Huang, C. (2025) · neural information processing systems · doi:10.52202/085713-0320 · Cited by 144
BixBench: a Comprehensive Benchmark for LLM-based Agents in Computational BiologyPreprint
Mitchener, L., Laurent, J. M., Andonian, A., Tenmann, B., Narayanan, S., Wellawatte, G. P., White, A., Sani, L., & Rodriques, S. G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.00096 · Cited by 133
The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery
Lu, C., Lu, C., Lange, R. T., Foerster, J., Clune, J., & Ha, D. (2024) · arXiv · doi:10.48550/arxiv.2408.06292 · Cited by 118
AI-Researcher: Autonomous Scientific Innovation
Tang, J., Xia, L., Li, Z., & Huang, C. (2025) · Neural Information Processing Systems · doi:10.48550/arxiv.2505.18705 · Cited by 116
OLMES: A Standard for Language Model Evaluations
Gu, Y., Tafjord, O., Kuehl, B., et al. (2024) · North American Chapter of the Association for Computational Linguistics · doi:10.48550/arxiv.2406.08446 · Cited by 115
Overview of the TREC 2020 Deep Learning Track
Craswell, N., Mitra, B., Yilmaz, E., & Campos, D. (2021) · arXiv · doi:10.48550/arxiv.2102.07662 · Cited by 107
MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research
Chen, H., Xiong, M., Lu, Y.-J., Han, W., Deng, A., He, Y.-F., Wu, J.-Y., Li, Y.-B., Liu, Y., & Hooi, B. (2025) · Neural Information Processing Systems · doi:10.48550/arxiv.2505.19955 · Cited by 74
Research works printed but not linked: 14
- Jun Shern Chan, Neil Chowdhury, Oliver Jaffe, James Aung, Dane Sherburn, Evan Mays, Giulio Starace, Kevin Liu, Leon Maksin, Tejal Patwardhan, Lilian Weng, and Aleksander Mádry. MLE- bench: Evaluating machine learning agents on machine learning engineering. In ICLR, 2025. URL https://openreview.net/forum?id=6s5uXNWGIh.
- Ziru Chen, Shijie Chen, Yuting Ning, Qianheng Zhang, Boshi Wang, Botao Yu, Yifei Li, Zeyi Liao, Chen Wei, Zitong Lu, Vishal Dey, Mingyi Xue, Frazier N. Baker, Benjamin Burns, Daniel Adu-Ampratwum, Xuhui Huang, Xia Ning, Song Gao, Yu Su, and Huan Sun. ScienceAgentBench: Toward rigorous assessment of language agents for data-driven scientific discovery. In ICLR, 2025b. URL https://openreview.net/forum?id=6z4YKr0GK6.
- Yichen He, Guanhua Huang, Peiyuan Feng, Yuan Lin, Yuchen Zhang, Hang Li, and Weinan E. PaSa: An LLM agent for comprehensive academic paper search. In ACL, 2025. URL https: //aclanthology.org/2025.acl-long.572/.
- Yuhang Lai, Chengxi Li, Yiming Wang, Tianyi Zhang, Ruiqi Zhong, Luke Zettlemoyer, Wen-tau Yih, Daniel Fried, Sida Wang, and Tao Yu. DS-1000: A natural and reliable benchmark for data science code generation. In ICML, 2023.
- Thibault Le Sellier De Chezelles, Maxime Gasse, Alexandre Drouin, Massimo Caccia, Léo Boisvert, Megh Thakkar, Tom Marty, Rim Assouel, Sahar Omidi Shayegan, Lawrence Keunho Jang, Xing Han Lù, Ori Yoran, Dehan Kong, Frank F. Xu, Siva Reddy, Quentin Cappart, Graham Neubig, Ruslan Salakhutdinov, Nicolas Chapados, and Alexandre Lacoste. The BrowserGym ecosystem for web agent research. TMLR, 2025. URL https://openreview.net/forum ?id=5298fKGmv3.
- Bodhisattwa Prasad Majumder, Harshit Surana, Dhruv Agarwal, Sanchaita Hazra, Ashish Sabharwal, and Peter Clark. Data-driven discovery with large generative models. ICML, 2024.
- Bodhisattwa Prasad Majumder, Harshit Surana, Dhruv Agarwal, Bhavana Dalvi Mishra, Abhi- jeetsingh Meena, Aryan Prakhar, Tirth Vora, Tushar Khot, Ashish Sabharwal, and Peter Clark. DiscoveryBench: Towards data-driven discovery with large language models. In ICLR, 2025. URL https://openreview.net/pdf?id=vyflgpwfJW.
- Benjamin Newman, Yoonjoo Lee, Aakanksha Naik, Pao Siangliulue, Raymond Fok, Juho Kim, Daniel S Weld, Joseph Chee Chang, and Kyle Lo. ArxivDIGESTables: Synthesizing scientific literature into tables using language models. In EMNLP, 2024. URL https://aclantholo gy.org/2024.emnlp-main.538/.
- Pritika Ramu, Aparna Garimella, and Sambaran Bandyopadhyay. Is this a bad table? a closer look at the evaluation of table generation from text. In EMNLP, 2024. URL https://aclantholo gy.org/2024.emnlp-main.1239/.
- Zachary S. Siegel, Sayash Kapoor, Nitya Nadgir, Benedikt Stroebl, and Arvind Narayanan. CORE- Bench: Fostering the credibility of published research through a computational reproducibility agent benchmark. TMLR, 2025-January:1-31, 2025. URL https://tmlr.org/papers/v2 025/01-2025paper.pdf.
- Hanchen Wang, Tianfan Fu, Yuanqi Du, Wenhao Gao, Kexin Huang, Ziming Liu, Payal Chandak, Shengchao Liu, Peter Van Katwyk, Andreea Deac, et al. Scientific discovery in the age of artificial intelligence. Nature, 620(7972):47-60, 2023.
- Xingyao Wang, Yangyi Chen, Lifan Yuan, Yizhe Zhang, Yunzhu Li, Hao Peng, and Heng Ji. Executable code actions elicit better llm agents. In ICML, 2024.
- Xingyao Wang, Boxuan Li, Yufan Song, Frank F. Xu, Xiangru Tang, Mingchen Zhuge, Jiayi Pan, Yueqi Song, Bowen Li, Jaskirat Singh, Hoang H. Tran, Fuqiang Li, Ren Ma, Mingzhang Zheng, Bill Qian, Yanjun Shao, Niklas Muennighoff, Yizhe Zhang, Binyuan Hui, Junyang Lin, Robert Brennan, Hao Peng, Heng Ji, and Graham Neubig. OpenHands: An open platform for AI software developers as generalist agents. In ICLR, 2025. URL https://openreview.net/forum ?id=OJd3ayDDoF.
- Yanzheng Xiang, Hanqi Yan, Shuyin Ouyang, Lin Gui, and Yulan He. Scireplicate-bench: Bench- marking llms in agent-driven algorithmic reproduction from research papers. Proceedings of COLM, 2025.
Cited by
Sorted by citations
Olmo 3Preprint
Team OLMo, :, Ettinger, A., Bertsch, A., Kuehl, B., Graham, D., Heineman, D., Groeneveld, D., Brahman, F., Timbers, F., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2512.13961 · Cited by 576
Self-citationAI scientists produce results without reasoning scientificallyPreprint
Ríos-García, M., Alampara, N., Gupta, C., Mandal, I., Mannan, S., Aghajani, A. A., Krishnan, N. M. A., & Jablonka, K. M. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2604.18805 · Cited by 35
Evolving Roles of LLMs in Scientific Innovation: Assistant, Collaborator, Scientist, and EvaluatorPreprint
Zhang, H., Li, R., Zhang, Y., Xiao, T., Chen, J., Ding, J., & Chen, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.11810 · Cited by 33
Agentic AI and the rise of in silico team science in biomedical research
Li, B., Saini, A. K., Hernandez, J. G., & Moore, J. H. (2026) · Nature Biotechnology · doi:10.1038/s41587-026-03035-1 · Cited by 29
Artificial Intelligence Index Report 2026Preprint
Sajadieh, S., Fattorini, L., Perrault, R., Gil, Y., Parli, V., Santarlasci, L., Pava, J., Maslej, N., Altman, R. B., Brynjolfsson, E., et al. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2606.15708 · Cited by 20
Self-citation
Metadata
- Authors
- Bragg, J., D'Arcy, M., Balepur, N., Bareket, D., Dalvi, B., Feldman, S., Haddad, D., Hwang, J. D., Jansen, P., Kishore, V., Majumder, B. P., Naik, A., Rahamimov, S., Richardson, K., Singh, A., Surana, H., Tiktinsky, A., Vasu, R., Wiener, G., Anastasiades, C., Candra, S., Dunkelberger, J., Emery, D., Evans, R., Hamada, M., Huff, R., Kinney, R., Latzke, M., Lochner, J., Lozano-Aguilera, R., Nguyen, C., Rao, S., Tanaka, A., Vlahos, B., Clark, P., Downey, D., Goldberg, Y., Sabharwal, A., & Weld, D. S.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- University of Maryland, College Park (US)
- University of Arizona (US)
- University of Washington (US)
- University of Zurich (CH)
- Bar-Ilan University (IL)
- ORCID
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2025
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2510.21652
- OpenAlex
- W7101416451
- Cited by
- 63
- References
- 23
- Citations by year
- 2026: 57 · 2025: 6
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Artificial Intelligence Applications
- Social Sciences › Decision Sciences › Information Systems and Management › Scientific Computing and Data Management
- Physical Sciences › Computer Science › Artificial Intelligence › AI-based Problem Solving and Planning
- Keywords
- AI agents, benchmarking, artificial intelligence in science, agent evaluation, reproducibility, search tools, baselines, AI scientists, literature review automation, experimental replication
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: AstaBench: Rigorous Benchmarking of AI Agents with a Scientific Research Suite. https://app.cochat.ai/papers/10.48550/arxiv.2510.21652
- The paper
- Bragg, J., D'Arcy, M., Balepur, N., Bareket, D., Dalvi, B., Feldman, S., Haddad, D., Hwang, J. D., Jansen, P., Kishore, V., Majumder, B. P., Naik, A., Rahamimov, S., Richardson, K., Singh, A., Surana, H., Tiktinsky, A., Vasu, R., Wiener, G., . . . Weld, D. S. (2025). AstaBench: Rigorous Benchmarking of AI Agents with a Scientific Research Suite. arXiv. https://doi.org/10.48550/arxiv.2510.21652
