

The DOI matches its DataCite record; 30 of the 30 references it cites were found in a registry or an index; none of the 28 sources its claims cite is checked for support yet.
The Fast and Spurious: Developer Productivity with GenAI
Open accessAbstract
Generative AI (GenAI) tools are increasingly being adopted in software development as productivity aids, since there is evidence that GenAI tools can improve individual aspects of productivity. However, productivity is multidimensional; accelerating one aspect of work may simply shift effort to another. In this paper, we investigate how GenAI adoption affects different dimensions of developer productivity. We surveyed 415 software practitioners to understand how they perceive productivity changes associated with AI adoption, using the SPACE framework (Satisfaction and well-being, Performance, Activity, Communication and collaboration, and Efficiency and flow). Our results reveal systematic redistribution of effort across SPACE dimensions. While frequent GenAI users reported faster task completion and higher output volume, these gains were offset by increased code review burden, persistent cognitive load from output verification, and unchanged collaboration patterns. We further provide an empirical mapping between the challenges perceived by developers and potential strategies to mitigate them. Overall, our findings suggest that, at the current stage of GenAI adoption, perceived productivity gains may be spurious -- surface-level acceleration, often accompanied by redistributed effort and hidden costs.
Overview
CoChat Summary
TL;DR
A survey of 415 software practitioners using the SPACE framework finds that GenAI adoption produces modest perceived gains in efficiency and activity, but these are offset by increased review burden, persistent cognitive load from verification, and unchanged collaboration. The authors argue that current productivity gains may be “spurious”—surface-level acceleration accompanied by redistributed effort and hidden costs.
Key findings
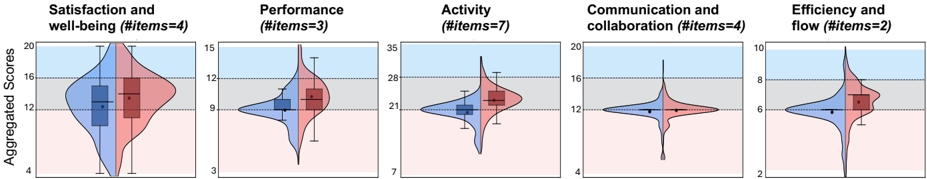
- Frequent GenAI users reported higher coding throughput (P1: 72.7% More/Much more) and more commits (48.3% vs. 7.9%), test cases (56.5% vs. 24.8%), and closed work items (55.9% vs. 9.1%) than non-frequent users.
- These activity gains did not extend uniformly to performance: 67.4% of frequent users reported no change or decline in test pass rates (P2), and 58.6% reported no change or decline in learning velocity (P3).
- Review effort increased: frequent users were more likely to conduct more code reviews (25.1% vs. 9.8%), and 84.3% reported that GenAI did not reduce time spent on code reviews.
- Communication and collaboration remained largely unchanged: over 70% of frequent users reported “No Change” across all four items, with meeting frequency at 93.1% vs. 90.8% and work-related emails at 93.6% vs. 91.3% for non-frequent vs. frequent users.
Methods
- Survey-based study grounded in the SPACE framework, with items adapted from prior validated questionnaires and an open-ended question on AI’s impact.
- Received 688 responses; after removing invalid entries, analyzed 415 software practitioners recruited from 56 OSS communities; most worked in full-stack (36.9%), backend (16.9%), or data/ML (15.4%) roles, 90.6% identified as men, 57.8% worked at large/extra-large organizations, and 82.2% had more than five years of experience.
- RQ1 compared frequent (Often/Always) vs. non-frequent (Never/Rarely/Sometimes) GenAI users using Likert distributions, stacked bar charts, and violin plots; RQ2 qualitatively coded 206 open-ended responses using SPACE dimensions, with two authors independently coding 20% and achieving 90% agreement via Jaccard index.
Limitations
- The paper states that self-reported survey data capture perceptions and may not reflect objective productivity outcomes; future work should complement findings with repository mining or longitudinal behavioral measures.
- The paper states that adoption frequency is a practical but incomplete proxy for GenAI engagement, as it may not capture task types, depth of workflow integration, or reliance on specific features.
- The paper acknowledges that no single sample fully represents the global software workforce, though it argues the 415 practitioners from 56 organizations are comparable in scale and diversity to prior studies; evident from the text, the sample is heavily male (90.6%) and experienced (82.2% with >5 years), and the cross-sectional design limits causal inference.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 0 Not valid · 17 Not checked · 79 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and frequent users were more likely than non-frequent users to report conducting more code reviews ( 𝐴 6: 25.1% vs. 9.8%).”
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The majority of frequent users (84.3%) reported that GenAI did not reduce the time spent on code reviews ( 𝐴 7)”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Nevertheless, all values remain within the neutral (or 'no-change') range , as indicated by the gray-shaded area.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Beyond measurable review time, developers also described a less visible cost- the mental effort required to continuously evaluate AI suggestions.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, these improvements are partial; more than half of respondents still reported feeling exhausted ( 𝑆 2: 65.2% vs. 62.8%).”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
43 more claims
Create a free account to see all 96 claims and to verify the 28 references still open.
- It may state two separate claims as one. 38
- Probably not a substantial claim. 22
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Performance (P) · p. 5
“In most activity-related items, frequent AI users reported higher levels of activity than non-frequent users, except code review ( 𝐴 6 and 𝐴 7).”
§ Performance (P) · p. 5
“frequent users were more likely than non-frequent users to report conducting more code reviews ( 𝐴 6: 25.1% vs. 9.8%).”
Citations
Cites
Brooks, F. P. (1975) · ACM SIGPLAN Notices · doi:10.1145/390016.808439 · Cited by 3,224
Two case studies of open source software development: Apache and Mozilla
Mockus, A., Fielding, R. T., & Herbsleb, J. D. (2002) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/567793.567795 · Cited by 1,685
Vaithilingam, P., Zhang, T., & Glassman, E. L. (2022) · CHI Conference on Human Factors in Computing Systems Extended Abstracts · doi:10.1145/3491101.3519665 · Cited by 660
Quality and productivity outcomes relating to continuous integration in GitHub
Vasilescu, B., Yu, Y., Wang, H., Devanbu, P., & Filkov, V. (2015) · Proceedings of the 2015 10th Joint Meeting on Foundations of Software Engineering · doi:10.1145/2786805.2786850 · Cited by 406
The Impact of AI on Developer Productivity: Evidence from GitHub Copilot
Peng, S., Kalliamvakou, E., Cihon, P., & Demirer, M. (2023) · arXiv · doi:10.48550/arxiv.2302.06590 · Cited by 287
Software developers' perceptions of productivity
Meyer, A. N., Fritz, T., Murphy, G. C., & Zimmermann, T. (2014) · Proceedings of the 22nd ACM SIGSOFT International Symposium on Foundations of Software Engineering · doi:10.1145/2635868.2635892 · Cited by 224 · cited 6×
“We adapted four statements from Meyer et al. [16]: (1) number of meetings attended, (2) time spent in meetings, (3) number of work-related emails written, and (4) time spent responding to emails.”
InfluentialThe SPACE of Developer Productivity: There's more to it than you think.
Forsgren, N., Storey, M.-A., Maddila, C., Zimmermann, T., Houck, B., & Butler, J. (2021) · Queue · doi:10.1145/3454122.3454124 · Cited by 164
Empirical findings on team size and productivity in software development
Rodríguez, D., Sicilia, M., García, E., & Harrison, R. (2011) · Journal of Systems and Software · doi:10.1016/j.jss.2011.09.009 · Cited by 138
Zhou, M., & Mockus, A. (2010) · ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) · doi:10.1145/1882291.1882313 · Cited by 107
Kuhail, M. A., Mathew, S. S., Khalil, A., Berengueres, J., & Shah, S. J. H. (2024) · Science of Computer Programming · doi:10.1016/j.scico.2024.103111 · Cited by 68
Generative Artificial Intelligence for Software Engineering—A Research Agenda
Nguyen‐Duc, A., Cabrero‐Daniel, B., Przybylek, A., Arora, C., Khanna, D., Herda, T., Rafiq, U., Melegati, J., Guerra, E., Kemell, K., et al. (2025) · Software: Practice and Experience · doi:10.1002/spe.70005 · Cited by 60
Code and commit metrics of developer productivity: a study on team leaders perceptions
de Oliveira, E. C. C., Fernandes, E., Steinmacher, I., de Cristo, M. A. P., Conte, T. U., & Garcia, A. (2020) · Empirical Software Engineering · doi:10.1007/s10664-020-09820-z · Cited by 56
Self-citationFrom Today’s Code to Tomorrow’s Symphony: The AI Transformation of Developer’s Routine by 2030
Qiu, K., Puccinelli, N., Ciniselli, M., & Grazia, L. D. (2024) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3709353 · Cited by 44
DevEx: What Actually Drives Productivity
Noda, A., Storey, M., Forsgren, N., & Greiler, M. (2023) · Queue · doi:10.1145/3595878 · Cited by 41
Shifting Work Patterns with Generative AI
Dillon, E., Jaffe, S., Immorlica, N., & Stanton, C. (2025) · doi:10.3386/w33795 · Cited by 31
Do I Belong? Modeling Sense of Virtual Community Among Linux Kernel Contributors
Trinkenreich, B., Stol, K.-J., Sarma, A., German, D. M., Gerosa, M. A., & Steinmacher, I. (2023) · 2023 IEEE/ACM 45th International Conference on Software Engineering (ICSE) · doi:10.1109/icse48619.2023.00038 · Cited by 25
Self-citationA case study of implicit mentoring, its prevalence, and impact in Apache
Feng, Z., Chatterjee, A., Sarma, A., & Ahmed, I. (2022) · Proceedings of the 30th ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering · doi:10.1145/3540250.3549167 · Cited by 19
Self-citationThe Evolution of Technical Debt from DevOps to Generative AI: A multivocal literature review
Moreschini, S., Arvanitou, E.-M., Kanidou, E.-P., Nikolaidis, N., Su, R., Ampatzoglou, A., Chatzigeorgiou, A., & Lenarduzzi, V. (2026) · Journal of Systems and Software · doi:10.1016/j.jss.2025.112599 · Cited by 19
Trinkenreich, B., Santos, F., & Stol, K.-J. (2024) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3691629 · Cited by 17
Self-citationParadigm shift on Coding Productivity Using GenAI
Yu, L. (2025) · International Conference on Evaluation and Assessment in Software Engineering (EASE) · doi:10.1145/3756681.3757081 · Cited by 17
Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
Becker, J., Rush, N., Barnes, E., & Rein, D. (2025) · arXiv · doi:10.48550/arxiv.2507.09089 · Cited by 16
"Maybe We Need Some More Examples:" Individual and Team Drivers of Developer GenAI Tool Use
Miller, C., Choudhuri, R., Ulloa, M., Haniyur, S., DeLine, R. A., Storey, M.-A., Murphy-Hill, E. R., Bird, C., & Butler, J. (2026) · ACM/IEEE International Conference on Software Engineering: Companion Proceedings (ICSE-Companion) · doi:10.1145/3744916.3773155 · Cited by 15
Generative AI and collaboration: opportunities for cultivating collective intelligence
Woolley, A. W. (2025) · Journal of Organization Design · doi:10.1007/s41469-025-00199-z · Cited by 13
Dohmke, T., Iansiti, M., & Richards, G. (2023) · arXiv · doi:10.48550/arxiv.2306.15033 · Cited by 10
Feng, Z., Milewicz, R. M., Murphy-Hill, E. R., Menezes, T., Serebrenik, A., Steinmacher, I., & Sarma, A. (2026) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3789210 · Cited by 7
Self-citationFrom Gains to Strains: Modeling Developer Burnout with GenAI Adoption
Feng, Z., Afroz, S., & Sarma, A. (2026) · Proceedings of the IEEE/ACM 48th International Conference on Software Engineering · doi:10.1145/3786581.3786934 · Cited by 6
Self-citationTobisch, F., & Matthes, F. (2025) · Lecture notes in business information processing · doi:10.1007/978-3-031-94544-1_6 · Cited by 5
AI in Software Engineering: Perceived Roles and Their Impact on Adoption
Zakharov, I., Koshchenko, E., & Sergeyuk, A. (2025) · ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) · doi:10.1145/3696630.3730563 · Cited by 4
When Domains Collide: An Activity Theory Exploration of Cross-Disciplinary Collaboration
Feng, Z., Zimmermann, T., Pisani, L., Gooley, C., Wander, J., & Sarma, A. (2025) · 2025 ACM/IEEE International Symposium on Empirical Software Engineering and Measurement (ESEM) · doi:10.1109/esem64174.2025.00017 · Cited by 4
Self-citationDeveloper Productivity with GenAI
Anonym (2025) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.17459830 · Cited by 1
Research works printed but not linked: 6
- [9][9] Zixuan Feng, Reed Milewicz, Emerson Murphy-Hill, Tyler Menezes, Alexander Serebrenik, Igor Steinmacher, and Anita Sarma. 2025. Charting Uncertain Waters: A Socio-Technical Framework for Navigating GenAI's Impact on Open Source Communities. arXiv preprint arXiv:2508.04921 (2025). - · arXiv
- [10][10] Zixuan Feng, Igor Steinmacher, Marco Gerosa, Tyler Menezes, Alexander Serebrenik, Reed Milewicz, and Anita Sarma. 2025. The multifaceted nature of mentoring in oss: strategies, qualities, and ideal outcomes. In CHASE . IEEE, 203-214. -
- [13][13] Ranim Khojah, Mazen Mohamad, Philipp Leitner, and Francisco de Oliveira Neto. 2024. Beyond code generation: An observational study 14. of chatgpt usage in software engineering practice. FSE 1 (2024), 18191840. -
- [24][24] Elise Paradis, Kate Grey, Quinn Madison, et al. 2025. How much does AI impact development speed? An enterprise RCT. In Proc. ICSE-SEIP . 618-629. -
- [33][33] Margaret-Anne Storey, Thomas Zimmermann, Christian Bird, Jacek Czerwonka, Brendan Murphy, and Eirini Kalliamvakou. 2019. Towards a theory of software developer job satisfaction and perceived productivity. TSE 47, 10 (2019). -
- [41][41] Brennan Wilkes, Alessandra Maciel Paz Milani, and Margaret-Anne Storey. 2023. A framework for automating the measurement of devops research and assessment (dora) metrics. In ICSME . IEEE, 62-72. -
Cited by
Tabarsi, B. T., Reichert, H., Gilson, S., Limke, A., Kuttal, S. K., & Barnes, T. M. (2026) · Empirical Software Engineering · doi:10.1007/s10664-026-10917-0 · Cited by 31
To Copilot and Beyond: 22 AI Systems Developers Want Built
Choudhuri, R., Bird, C., Badea, C., & Sarma, A. (2026) · IEEE International Conference on Software Maintenance (ICSM) · doi:10.48550/arxiv.2604.07830 · Cited by 9
Self-citationFeng, Z., Milewicz, R. M., Murphy-Hill, E. R., Menezes, T., Serebrenik, A., Steinmacher, I., & Sarma, A. (2026) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3789210 · Cited by 7
Self-citationMurphy-Hill, E. R., Butler, J., & Savelieva, A. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2607.01418 · Cited by 6
Afroz, S., Miller, C., Menezes, T., Gilmour, E., Sarma, A., & Feng, Z. (2026) · arXiv · doi:10.48550/arxiv.2607.04003 · Cited by 1
Self-citation
Metadata
- Authors
- Afroz, S., Feng, Z., Menezes, T., Kimura, K., Trinkenreich, B., Steinmacher, I., & Sarma, A.
- Affiliations
- Oregon State University (US)
- CodeDay (US)
- Colorado State University (US)
- Northern Arizona University (US)
- ORCID
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2025
- Pages
- 1832-1841
- arXiv
- 2510.24265
- OpenAlex
- W7169591074
- Cited by
- 11
- References
- 30
- Citations by year
- 2026: 10 · 2025: 1
- FWCI
- 18.18
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- National Science Foundation (2303043)
- Topics
- Physical Sciences › Computer Science › Information Systems › Software Engineering Techniques and Practices
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Physical Sciences › Computer Science › Artificial Intelligence › Artificial Intelligence Applications
- Keywords
- generative AI, developer productivity, software development, SPACE framework, cognitive load, output verification, developer well-being, collaboration patterns, AI adoption barriers
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
