

The DOI matches its Crossref record; 3 of the 3 references it cites were found in a registry or an index.
Ada-KV: Optimizing KV Cache Eviction by Adaptive Budget Allocation for Efficient LLM Inference
Open accessAbstract
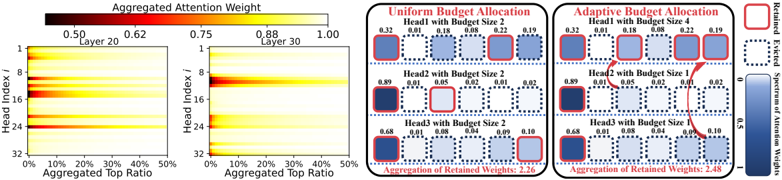
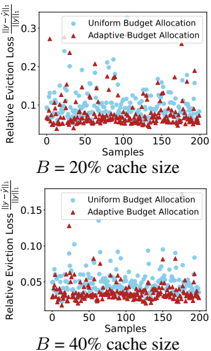
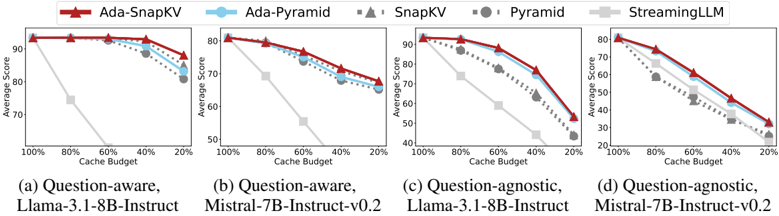
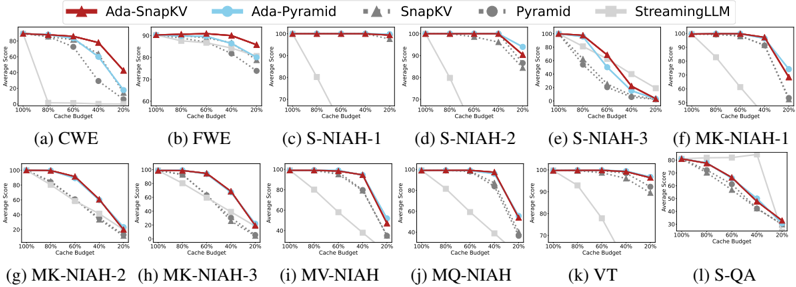
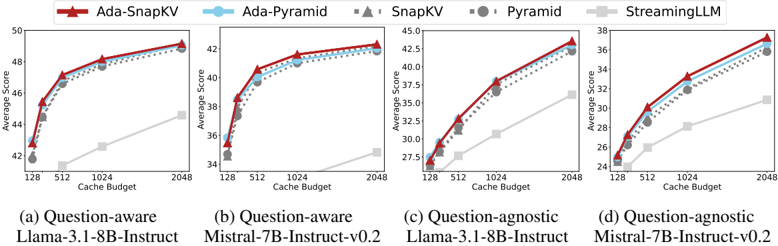
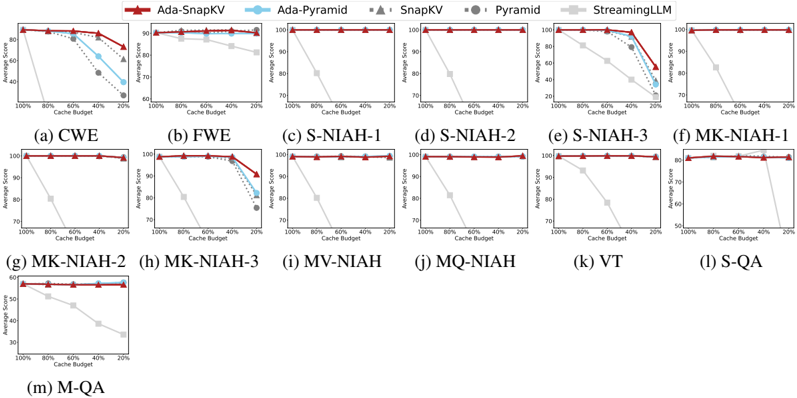
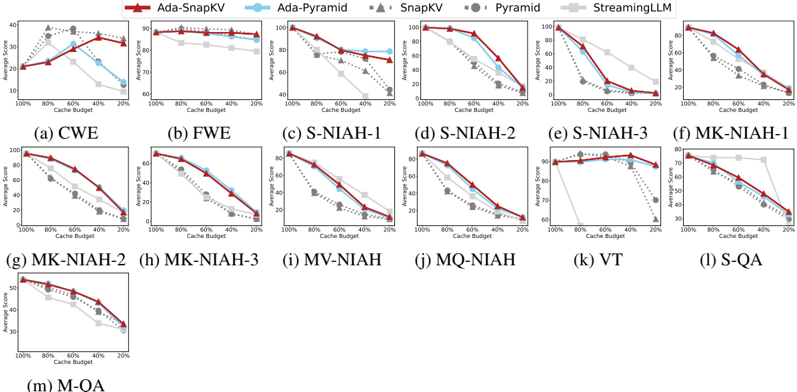
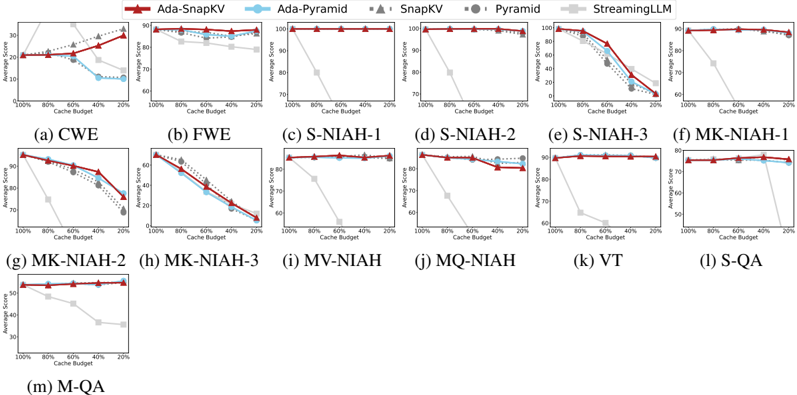
Large Language Models have excelled in various domains but face efficiency challenges due to the growing Key-Value (KV) cache required for long-sequence inference. Recent efforts aim to reduce KV cache size by evicting vast non-critical cache elements during runtime while preserving generation quality. However, these methods typically allocate compression budgets uniformly across all attention heads, ignoring the unique attention patterns of each head. In this paper, we establish a theoretical loss upper bound between pre- and post-eviction attention output, explaining the optimization target of prior cache eviction methods, while guiding the optimization of adaptive budget allocation. Base on this, we propose {\it Ada-KV}, the first head-wise adaptive budget allocation strategy. It offers plug-and-play benefits, enabling seamless integration with prior cache eviction methods. Extensive evaluations on 13 datasets from Ruler and 16 datasets from LongBench, all conducted under both question-aware and question-agnostic scenarios, demonstrate substantial quality improvements over existing methods. Our code is available at https://github.com/FFY0/AdaKV.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“AdaKV (Feng et al., 2025) reallocates a SnapKVstyle budget per-head”
From How Query Visibility Changes KV-Cache Compression Rankings: A Matched-Budget Audit (2026) · cites this paper as Feng et al., 2025
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Multi-News: A Large-Scale Multi-Document Summarization Dataset and Abstractive Hierarchical Model
Fabbri, A., Li, I., She, T., Li, S., & Radev, D. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1102 · Cited by 449
LongBench: A Bilingual, Multitask Benchmark for Long Context Understanding
Bai, Y., Lv, X., Zhang, J., Lyu, H., Tang, J., Huang, Z., Du, Z., Liu, X., Zeng, A., Hou, L., et al. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.172 · Cited by 400
Jiang, A. Q., Sablayrolles, A., Mensch, A., Bamford, C., Chaplot, D. S., Casas, D. D. L., Bressand, F., Lengyel, G., Lample, G., Saulnier, L., et al. (2023) · arXiv · doi:10.48550/arxiv.2310.06825 · Cited by 340
Research works printed but not linked: 54
- Zihao Yi, Jiarui Ouyang, Yuwen Liu, Tianhao Liao, Zhe Xu, and Ying Shen. A survey on recent advances in llm-based multi-turn dialogue systems. arXiv preprint arXiv:2402.18013, 2024. · arXiv
- Philippe Laban, Wojciech Kryściński, Divyansh Agarwal, Alexander Richard Fabbri, Caiming Xiong, Shafiq Joty, and Chien-Sheng Wu. Summedits: measuring llm ability at factual reasoning through the lens of summarization. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, pages 9662-9676, 2023.
- Qiuhan Gu. Llm-based code generation method for golang compiler testing. In Proceedings of the 31st ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering, pages 2201-2203, 2023.
- Josh Achiam, Steven Adler, Sandhini Agarwal, Lama Ahmad, Ilge Akkaya, Florencia Leoni Aleman, Diogo Almeida, Janko Altenschmidt, Sam Altman, Shyamal Anadkat, et al. Gpt-4 technical report. arXiv preprint arXiv:2303.08774, 2023. · arXiv
- Machel Reid, Nikolay Savinov, Denis Teplyashin, Dmitry Lepikhin, Timothy Lillicrap, Jean- baptiste Alayrac, Radu Soricut, Angeliki Lazaridou, Orhan Firat, Julian Schrittwieser, et al. Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context. arXiv preprint arXiv:2403.05530, 2024. · arXiv
- Suyu Ge, Yunan Zhang, Liyuan Liu, Minjia Zhang, Jiawei Han, and Jianfeng Gao. Model tells you what to discard: Adaptive kv cache compression for llms. arXiv preprint arXiv:2310.01801, 2023. · arXiv
- Zhenyu Zhang, Ying Sheng, Tianyi Zhou, Tianlong Chen, Lianmin Zheng, Ruisi Cai, Zhao Song, Yuandong Tian, Christopher Ré, Clark Barrett, et al. H2o: Heavy-hitter oracle for efficient generative inference of large language models. Advances in Neural Information Processing Systems, 36, 2024.
- Dongjie Yang, Xiaodong Han, Yan Gao, Yao Hu, Shilin Zhang, and Hai Zhao. PyramidInfer: Pyramid KV cache compression for high-throughput LLM inference. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors, Findings of the Association for Computational Linguistics ACL 2024, pages 3258-3270, Bangkok, Thailand and virtual meeting, August 2024. Association for Computational Linguistics.
- Yichi Zhang, Bofei Gao, Tianyu Liu, Keming Lu, Wayne Xiong, Yue Dong, Baobao Chang, Junjie Hu, Wen Xiao, et al. Pyramidkv: Dynamic kv cache compression based on pyramidal information funneling. arXiv preprint arXiv:2406.02069, 2024. · arXiv
- Yuhong Li, Yingbing Huang, Bowen Yang, Bharat Venkitesh, Acyr Locatelli, Hanchen Ye, Tianle Cai, Patrick Lewis, and Deming Chen. SnapKV: LLM knows what you are looking for before generation. In The Thirty-eighth Annual Conference on Neural Information Processing Systems, 2024.
- Kefei Wang and Feng Chen. Catalyst: Optimizing cache management for large in-memory key-value systems. Proceedings of the VLDB Endowment, 16(13):4339-4352, 2023.
- Iz Beltagy, Matthew E Peters, and Arman Cohan. Longformer: The long-document transformer. arXiv preprint arXiv:2004.05150, 2020. · arXiv
- Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, and Mike Lewis. Efficient streaming language models with attention sinks. arXiv preprint arXiv:2309.17453, 2023. · arXiv
- Zichang Liu, Aditya Desai, Fangshuo Liao, Weitao Wang, Victor Xie, Zhaozhuo Xu, Anastasios Kyrillidis, and Anshumali Shrivastava. Scissorhands: Exploiting the persistence of impor- tance hypothesis for llm kv cache compression at test time. Advances in Neural Information Processing Systems, 36, 2024.
- Siyu Ren and Kenny Q Zhu. On the efficacy of eviction policy for key-value constrained generative language model inference. arXiv preprint arXiv:2402.06262, 2024. · arXiv
- Huiqiang Jiang, Yucheng Li, Chengruidong Zhang, Qianhui Wu, Xufang Luo, Surin Ahn, Zhenhua Han, Amir H Abdi, Dongsheng Li, Chin-Yew Lin, et al. Minference 1.0: Accelerating pre-filling for long-context llms via dynamic sparse attention. Advances in Neural Information Processing Systems, 37:52481-52515, 2024.
- Yucheng Li, Huiqiang Jiang, Chengruidong Zhang, Qianhui Wu, Xufang Luo, Surin Ahn, Amir H Abdi, Dongsheng Li, Jianfeng Gao, Yuqing Yang, et al. Mminference: Accelerating pre-filling for long-context vlms via modality-aware permutation sparse attention. arXiv preprint arXiv:2504.16083, 2025. · arXiv
- Di Liu, Meng Chen, Baotong Lu, Huiqiang Jiang, Zhenhua Han, Qianxi Zhang, Qi Chen, Chengruidong Zhang, Bailu Ding, Kai Zhang, et al. Retrievalattention: Accelerating long- context llm inference via vector retrieval. arXiv preprint arXiv:2409.10516, 2024. · arXiv
- Renze Chen, Zhuofeng Wang, Beiquan Cao, Tong Wu, Size Zheng, Xiuhong Li, Xuechao Wei, Shengen Yan, Meng Li, and Yun Liang. Arkvale: Efficient generative llm inference with recallable key-value eviction. Advances in Neural Information Processing Systems, 37:113134- 113155, 2024.
- Hailin Zhang, Xiaodong Ji, Yilin Chen, Fangcheng Fu, Xupeng Miao, Xiaonan Nie, Weipeng Chen, and Bin Cui. Pqcache: Product quantization-based kvcache for long context llm inference. Proceedings of the ACM on Management of Data, 3(3):1-30, 2025.
- He Sun, Li Li, Mingjun Xiao, and Chengzhong Xu. Breaking the boundaries of long- context llm inference: Adaptive kv management on a single commodity gpu. arXiv preprint arXiv:2506.20187, 2025. · arXiv
- Tri Dao, Dan Fu, Stefano Ermon, Atri Rudra, and Christopher Ré. Flashattention: Fast and memory-efficient exact attention with io-awareness. Advances in Neural Information Processing Systems, 35:16344-16359, 2022.
- Tri Dao. Flashattention-2: Faster attention with better parallelism and work partitioning. arXiv preprint arXiv:2307.08691, 2023. · arXiv
- Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph Gonzalez, Hao Zhang, and Ion Stoica. Efficient memory management for large language model serving with pagedattention. In Proceedings of the 29th Symposium on Operating Systems Principles, pages 611-626, 2023.
- Cheng-Ping Hsieh, Simeng Sun, Samuel Kriman, Shantanu Acharya, Dima Rekesh, Fei Jia, Yang Zhang, and Boris Ginsburg. Ruler: What's the real context size of your long-context language models? arXiv preprint arXiv:2404.06654, 2024. · arXiv
- In Gim, Guojun Chen, Seung-seob Lee, Nikhil Sarda, Anurag Khandelwal, and Lin Zhong. Prompt cache: Modular attention reuse for low-latency inference. Proceedings of Machine Learning and Systems, 6:325-338, 2024.
- Lianmin Zheng, Liangsheng Yin, Zhiqiang Xie, Chuyue Sun, Jeff Huang, Cody Hao Yu, Shiyi Cao, Christos Kozyrakis, Ion Stoica, Joseph E Gonzalez, et al. Sglang: Efficient execution of structured language model programs. arXiv preprint arXiv:2312.07104, 2024. · arXiv
- Jang-Hyun Kim, Jinuk Kim, Sangwoo Kwon, Jae W Lee, Sangdoo Yun, and Hyun Oh Song. Kvzip: Query-agnostic kv cache compression with context reconstruction. arXiv preprint arXiv:2505.23416, 2025. · arXiv
- Alessio Devoto, Maximilian Jeblick, and Simon Jégou. Expected attention: Kv cache compres- sion by estimating attention from future queries distribution. arXiv preprint arXiv:2510.00636, 2025. · arXiv
- Kevin Galim, Ethan Ewer, Wonjun Kang, Minjae Lee, Hyung Il Koo, and Kangwook Lee. Draft-based approximate inference for llms. arXiv preprint arXiv:2506.08373, 2025. · arXiv
- Yuan Feng, Junlin Lv, Yukun Cao, Xike Xie, and S Kevin Zhou. Identify critical kv cache in llm inference from an output perturbation perspective. arXiv preprint arXiv:2502.03805, 2025. · arXiv
- Guangxuan Xiao, Jiaming Tang, Jingwei Zuo, Junxian Guo, Shang Yang, Haotian Tang, Yao Fu, and Song Han. Duoattention: Efficient long-context llm inference with retrieval and streaming heads. arXiv preprint arXiv:2410.10819, 2024. · arXiv
- Yu Fu, Zefan Cai, Abedelkadir Asi, Wayne Xiong, Yue Dong, and Wen Xiao. Not all heads matter: A head-level kv cache compression method with integrated retrieval and reasoning. arXiv preprint arXiv:2410.19258, 2024. · arXiv
- Zhewei Yao, Reza Yazdani Aminabadi, Minjia Zhang, Xiaoxia Wu, Conglong Li, and Yuxiong He. Zeroquant: Efficient and affordable post-training quantization for large-scale transformers. Advances in Neural Information Processing Systems, 35:27168-27183, 2022.
- Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, and Xia Hu. Kivi: A tuning-free asymmetric 2bit quantization for kv cache. arXiv preprint arXiv:2402.02750, 2024. · arXiv
- Shichen Dong, Wen Cheng, Jiayu Qin, and Wei Wang. Qaq: Quality adaptive quantization for llm kv cache. arXiv preprint arXiv:2403.04643, 2024. · arXiv
- Hanshi Sun, Zhuoming Chen, Xinyu Yang, Yuandong Tian, and Beidi Chen. Triforce: Lossless acceleration of long sequence generation with hierarchical speculative decoding. arXiv preprint arXiv:2404.11912, 2024. · arXiv
- Penghui Yang, Cunxiao Du, Fengzhuo Zhang, Haonan Wang, Tianyu Pang, Chao Du, and Bo An. Longspec: Long-context lossless speculative decoding with efficient drafting and verification. In ES-FoMo III: 3rd Workshop on Efficient Systems for Foundation Models.
- Yicheng Ji, Jun Zhang, Heming Xia, Jinpeng Chen, Lidan Shou, Gang Chen, and Huan Li. Specvlm: Enhancing speculative decoding of video llms via verifier-guided token pruning. arXiv preprint arXiv:2508.16201, 2025. · arXiv
- Simran Arora, Sabri Eyuboglu, Aman Timalsina, Isys Johnson, Michael Poli, James Zou, Atri Rudra, and Christopher Ré. Zoology: Measuring and improving recall in efficient language models. In ICLR, 2024.
- Tomáš Kočiskỳ, Jonathan Schwarz, Phil Blunsom, Chris Dyer, Karl Moritz Hermann, Gábor Melis, and Edward Grefenstette. The narrativeqa reading comprehension challenge. Transac- tions of the Association for Computational Linguistics, 6:317-328, 2018.
- Pradeep Dasigi, Kyle Lo, Iz Beltagy, Arman Cohan, Noah A Smith, and Matt Gardner. A dataset of information-seeking questions and answers anchored in research papers. arXiv preprint arXiv:2105.03011, 2021. · arXiv
- Zhilin Yang, Peng Qi, Saizheng Zhang, Yoshua Bengio, William W Cohen, Ruslan Salakhut- dinov, and Christopher D Manning. Hotpotqa: A dataset for diverse, explainable multi-hop question answering. arXiv preprint arXiv:1809.09600, 2018. · arXiv
- Xanh Ho, Anh-Khoa Duong Nguyen, Saku Sugawara, and Akiko Aizawa. Constructing a multi-hop QA dataset for comprehensive evaluation of reasoning steps. In Donia Scott, Nuria Bel, and Chengqing Zong, editors, Proceedings of the 28th International Conference on Computational Linguistics, pages 6609-6625, Barcelona, Spain (Online), December 2020. International Committee on Computational Linguistics.
- Harsh Trivedi, Niranjan Balasubramanian, Tushar Khot, and Ashish Sabharwal. Musique: Multihop questions via single-hop question composition. Transactions of the Association for Computational Linguistics, 10:539-554, 2022.
- Luyang Huang, Shuyang Cao, Nikolaus Parulian, Heng Ji, and Lu Wang. Efficient attentions for long document summarization. arXiv preprint arXiv:2104.02112, 2021. · arXiv
- Ming Zhong, Da Yin, Tao Yu, Ahmad Zaidi, Mutethia Mutuma, Rahul Jha, Ahmed Hassan Awadallah, Asli Celikyilmaz, Yang Liu, Xipeng Qiu, et al. Qmsum: A new benchmark for query-based multi-domain meeting summarization. arXiv preprint arXiv:2104.05938, 2021. · arXiv
- Bogdan Gliwa, Iwona Mochol, Maciej Biesek, and Aleksander Wawer. Samsum cor- pus: A human-annotated dialogue dataset for abstractive summarization. arXiv preprint arXiv:1911.12237, 2019. · arXiv
- Xin Li and Dan Roth. Learning question classifiers. In COLING 2002: The 19th International Conference on Computational Linguistics, 2002.
- Nelson F Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni, and Percy Liang. Lost in the middle: How language models use long contexts. arXiv preprint arXiv:2307.03172, 2023. · arXiv
- Xanh Ho, Anh-Khoa Duong Nguyen, Saku Sugawara, and Akiko Aizawa. Constructing a multi-hop qa dataset for comprehensive evaluation of reasoning steps. In Proceedings of the 28th International Conference on Computational Linguistics, pages 6609-6625, 2020.
- Mandar Joshi, Eunsol Choi, Daniel S Weld, and Luke Zettlemoyer. Triviaqa: A large scale distantly supervised challenge dataset for reading comprehension. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 1601-1611, 2017.
- Daya Guo, Canwen Xu, Nan Duan, Jian Yin, and Julian McAuley. Longcoder: A long-range pre-trained language model for code completion. arXiv preprint arXiv:2306.14893, 2023. · arXiv
- Tianyang Liu, Canwen Xu, and Julian McAuley. Repobench: Benchmarking repository-level code auto-completion systems. arXiv preprint arXiv:2306.03091, 2023. Full Cache 26.74 32.84 50.00 43.45 27.77 18.49 32.91 24.64 26.99 71.00 86.23 43.32 2.94 86.31 57.39 54.32 42.83 B=128 SLM 7.62 7.49 26.12 18.97 14.44 7.26 19.46 17.29 19.46 26.50 73.27 36.65 1.50 4.50 14.58 59.10 22.14 Pyramid 10.69 8.37 20.65 18.34 13.78 5.99 17.32 17.71 19.20 22.50 82.69 37.48 3.25 3.00 53.63 58.13 24.55 SnapKV 10.51 9.52 21.28 18.76 13.85 5.57 17.68 18.05 18.18 21.50 82.52 36.61 3.74 2.50 52.84 59.04 24.51 Ada-Pyramid 12.53 9.61 20.94 18.54 14.38 4.90 17.54 18.15 19.02 22.00 84.44 37.72 3.67 1.33 55.49 59.28 24.97 Ada-SnapKV 11.13 9.33 21.78 19.41 14.96 5.95 17.82 17.39 19.15 24.50 83.71 37.33 3.73 1.50 54.91 59.92 25.16 B=256 SLM 8.37 7.47 28.82 21.42 15.30 6.98 21.74 18.23 22.92 38.50 74.46 37.77 1.25 3.75 17.64 58.95 23.97 Pyramid 9.86 11.24 21.86 20.71 13.40 6.58 20.07 18.21 21.04 26.00 85.73 39.34 3.11 8.68 57.18 56.31 26.21 SnapKV 10.99 10.94 23.27 21.67 13.87 6.42 20.16 18.26 21.54 28.50 85.72 39.21 2.56 6.50 57.74 58.10 26.59 Ada-Pyramid 11.01 9.98 22.14 22.26 15.42 7.17 19.78 18.74 21.27 31.00 87.30 39.32 3.42 8.43 58.18 58.08 27.09 Ada-SnapKV 10.45 10.47 23.67 22.45 13.48 7.29 20.58 18.21 21.60 32.00 87.05 39.74 3.66 8.13 58.99 58.44 27.26 B=512 SLM 9.54 9.05 32.27 21.64 15.17 8.76 24.89 18.33 25.39 49.00 75.51 39.40 1.50 5.75 21.43 57.64 25.95 Pyramid 11.72 12.41 23.61 23.77 14.36 6.61 21.92 19.09 23.25 37.50 87.18 40.61 3.40 14.29 59.68 57.17 28.54 SnapKV 11.01 13.37 24.86 25.33 13.39 6.37 22.98 19.00 23.48 41.50 86.94 40.05 3.83 14.97 60.18 57.33 29.04 Ada-Pyramid 11.51 12.59 24.90 23.29 15.62 7.10 21.78 19.41 23.13 45.00 87.42 40.96 3.37 19.10 60.65 58.46 29.64 Ada-SnapKV 13.07 12.48 26.69 26.33 14.12 7.74 23.02 19.13 23.43 47.00 87.81 41.05 3.77 17.83 60.95 57.20 30.10 B=1024 SLM 11.05 14.15 38.89 23.79 18.25 9.71 27.20 20.25 26.20 52.50 76.96 41.79 0.00 8.50 24.24 56.58 28.13 Pyramid 12.22 16.32 28.01 26.55 15.58 7.59 23.91 20.04 25.38 46.00 87.41 41.37 3.74 34.29 63.44 58.19 31.88 SnapKV 13.43 16.30 30.57 27.04 14.88 8.48 24.97 19.71 25.64 50.50 87.32 41.19 2.87 28.21 63.55 57.38 32.00 Ada-Pyramid 12.34 17.09 30.24 27.13 14.01 8.26 23.60 20.03 25.01 52.50 87.26 42.75 3.96 39.33 62.92 57.67 32.76 Ada-SnapKV 13.86 18.39 31.07 29.03 14.92 8.24 24.82 19.86 25.59 55.50 87.81 41.98 3.04 35.96 64.32 57.95 33.27 B=2048 SLM 11.80 20.40 43.35 25.01 18.21 9.80 29.40 21.40 26.73 59.00 83.06 43.26 0.38 15.75 30.11 56.05 30.86 Pyramid 14.04 21.19 36.29 27.07 15.74 10.21 25.62 20.71 26.25 52.50 87.31 43.53 4.05 65.42 64.97 58.04 35.81 SnapKV 15.91 21.64 35.48 29.94 16.34 11.49 27.29 20.67 26.78 56.00 87.46 42.19 4.93 61.83 65.34 56.88 36.26 Ada-Pyramid 15.44 21.48 36.86 29.43 16.88 10.75 25.52 20.74 26.60 54.50 87.17 43.05 2.89 70.96 65.15 58.66 36.63 Ada-SnapKV 15.84 22.24 38.67 32.03 16.54 12.68 26.35 20.93 26.65 57.50 87.49 43.55 4.66 68.67 64.24 58.25 37.27 · arXiv
Cited by
Sorted by citations
Compactor: Calibrated Query-Agnostic KV Cache Compression with Approximate Leverage Scores
Chari, V., & Van Durme, B. (2025) · arXiv · doi:10.48550/arxiv.2507.08143 · Cited by 15
How Query Visibility Changes KV-Cache Compression Rankings: A Matched-Budget Audit
Luo, D., Liang, C., & Xuan, J. (2026) · arXiv · doi:10.48550/arxiv.2607.11942
IndexMem: Learned KV-Cache Eviction with Latent Memory for Long-Context LLM Inference
Yang, X., Gu, H., Xu, B., Li, L., Liu, B., Liu, J., Zhu, Q., Guo, Y., & Han, S. (2026) · arXiv · doi:10.48550/arxiv.2605.25475
VarRate: Training-Free Variable-Rate KV Cache Compression for Long-Context LLMs
Esmat, S., Shah, D., & Jannesari, A. (2026) · arXiv · doi:10.48550/arxiv.2607.15498
Metadata
- Authors
- Feng, Y., Lv, J., Cao, Y., Xie, X., & Zhou, S. K.
- Affiliations
- University of Science and Technology of China (CN)
- CAS
- Venue
- Advances in Neural Information Processing Systems 38
- Published
- 2025
- Pages
- 125462-125498
- ISSN
- 1049-5258 (ISSN-L)
- OpenAlex
- W4406071672
- Cited by
- 5
- References
- 3
- Citations by year
- 2026: 4 · 2025: 1
- FWCI
- 4.74
- Type
- conference paper
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- cc-by
- Locations
- neural information processing systems (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- National Natural Science Foundation of China (62271465)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Keywords
- KV cache eviction, large language model inference
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
