

The DOI matches its Crossref record; 571 of the 614 references it cites were found in a registry or an index, and 1 are not checked yet.
Evaluation of Risk of Bias in Neuroimaging-Based Artificial Intelligence Models for Psychiatric Diagnosis: A Systematic Review
Open accessAbstract
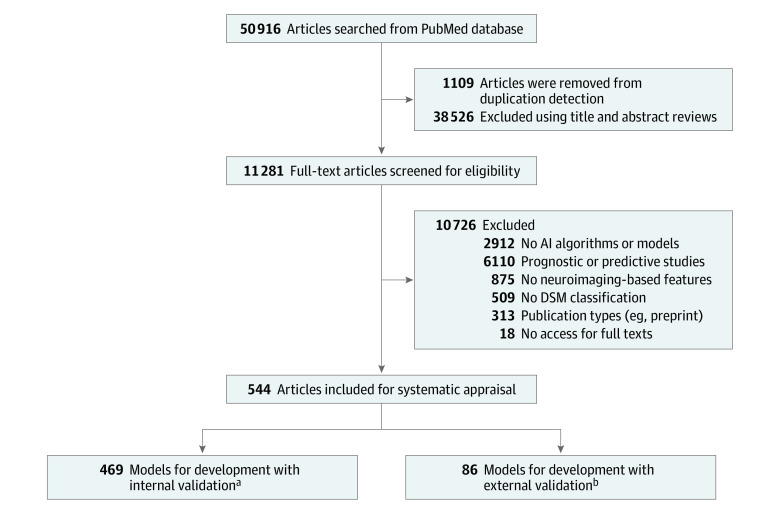
Importance: Neuroimaging-based artificial intelligence (AI) diagnostic models have proliferated in psychiatry. However, their clinical applicability and reporting quality (ie, feasibility) for clinical practice have not been systematically evaluated. Objective: To systematically assess the risk of bias (ROB) and reporting quality of neuroimaging-based AI models for psychiatric diagnosis. Evidence Review: PubMed was searched for peer-reviewed, full-length articles published between January 1, 1990, and March 16, 2022. Studies aimed at developing or validating neuroimaging-based AI models for clinical diagnosis of psychiatric disorders were included. Reference lists were further searched for suitable original studies. Data extraction followed the CHARMS (Checklist for Critical Appraisal and Data Extraction for Systematic Reviews of Prediction Modeling Studies) and PRISMA (Preferred Reporting Items for Systematic Reviews and Meta-analyses) guidelines. A closed-loop cross-sequential design was used for quality control. The PROBAST (Prediction Model Risk of Bias Assessment Tool) and modified CLEAR (Checklist for Evaluation of Image-Based Artificial Intelligence Reports) benchmarks were used to systematically evaluate ROB and reporting quality. Findings: A total of 517 studies presenting 555 AI models were included and evaluated. Of these models, 461 (83.1%; 95% CI, 80.0%-86.2%) were rated as having a high overall ROB based on the PROBAST. The ROB was particular high in the analysis domain, including inadequate sample size (398 of 555 models [71.7%; 95% CI, 68.0%-75.6%]), poor model performance examination (with 100% of models lacking calibration examination), and lack of handling data complexity (550 of 555 models [99.1%; 95% CI, 98.3%-99.9%]). None of the AI models was perceived to be applicable to clinical practices. Overall reporting completeness (ie, number of reported items/number of total items) for the AI models was 61.2% (95% CI, 60.6%-61.8%), and the completeness was poorest for the technical assessment domain with 39.9% (95% CI, 38.8%-41.1%). Conclusions and Relevance: This systematic review found that the clinical applicability and feasibility of neuroimaging-based AI models for psychiatric diagnosis were challenged by a high ROB and poor reporting quality. Particularly in the analysis domain, ROB in AI diagnostic models should be addressed before clinical application.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“identifying only 86 studies (15.5%) included external validation”
From Bias recognition and mitigation strategies in artificial intelligence healthcare applications (2025) · cites this paper as [18]
In the citing paper
“Overall, 83% of studies were rated at high ROB18.”
From Bias recognition and mitigation strategies in artificial intelligence healthcare applications (2025) · cites this paper as [18]
In the citing paper
“examined 555 published neuroimaging-based AI models for psychiatric diagnosis”
From Bias recognition and mitigation strategies in artificial intelligence healthcare applications (2025) · cites this paper as [18]
In the citing paper
“while 97.5% included only subjects from high-income regions.”
From Bias recognition and mitigation strategies in artificial intelligence healthcare applications (2025) · cites this paper as [18]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
1 retracted
Zhou, D., Liao, Z., & Chen, R. (2022) · Journal of Healthcare Engineering · doi:10.1155/2022/5222136 · Cited by 17
RetractedDermyshi, E., Wang, Y., Yan, C., Hong, W., Qiu, G., Gong, X., & Zhang, T. (2017) · Neonatology · doi:10.1159/000454668 · Cited by 24,586
Self-citationMeta-analysis of Observational Studies in Epidemiology<SUBTITLE>A Proposal for Reporting</SUBTITLE>
Stroup, D. F. (2000) · JAMA · doi:10.1001/jama.283.15.2008 · Cited by 20,623
Page, M. J., Moher, D., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., et al. (2021) · BMJ · doi:10.1136/bmj.n160 · Cited by 13,262
Machine learning: Trends, perspectives, and prospects
Jordan, M. I., & Mitchell, T. M. (2015) · Science · doi:10.1126/science.aaa8415 · Cited by 9,955
Collins, G. S., Reitsma, J. B., Altman, D. G., & Moons, K. G. M. (2015) · BMJ · doi:10.1136/bmj.g7594 · Cited by 4,388
(2023) · IEEE Access · doi:10.1109/access.6287639 · Cited by 3,358
Collins, P. G. S., Reitsma, J. B., Altman, D. G., & Moons, K. G. M. (2015) · British Journal of Cancer · doi:10.1038/bjc.2014.639 · Cited by 3,319
Towards complete and accurate reporting of studies of diagnostic accuracy: The STARD Initiative.
Bossuyt, P. M., Reitsma, J. B., Bruns, D. E., Gatsonis, C. A., Glasziou, P. P., Irwig, L. M., Lijmer, J. G., Moher, D., Rennie, D., de Vet, H. C. W., et al. (2003) · Annals of Internal Medicine · doi:10.7326/0003-4819-138-1-200301070-00010 · Cited by 3,219
Towards complete and accurate reporting of studies of diagnostic accuracy: the STARD initiative
Bossuyt, P. M., Reitsma, J. B., Bruns, D. E., Gatsonis, C. A., Glasziou, P. P., Irwig, L. M., Lijmer, J. G., Moher, D., Rennie, D., & de Vet, H. C. W. (2003) · BMJ · doi:10.1136/bmj.326.7379.41 · Cited by 3,215
Cited by
Sorted by citations
Bias recognition and mitigation strategies in artificial intelligence healthcare applications
Hasanzadeh, F., Josephson, C. B., Waters, G., Adedinsewo, D., Azizi, Z., & White, J. A. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01503-7 · Cited by 320
Data leakage inflates prediction performance in connectome-based machine learning models
Rosenblatt, M., Tejavibulya, L., Jiang, R., Noble, S., & Scheinost, D. (2024) · Nature Communications · doi:10.1038/s41467-024-46150-w · Cited by 236
BrainAGE, brain health, and mental disorders: A systematic review
Seitz‐Holland, J., Haas, S. S., Penzel, N., Reichenberg, A., & Pasternak, O. (2024) · Neuroscience & Biobehavioral Reviews · doi:10.1016/j.neubiorev.2024.105581 · Cited by 38
Chen, Z., Hu, B., Liu, X., Becker, B., Eickhoff, S. B., Miao, K., Gu, X., Tang, Y., Dai, X., Li, C., et al. (2023) · BMC Medicine · doi:10.1186/s12916-023-02941-4 · Cited by 35
Self-citationAlmarie, B., González-González, L. F., Barbosa, L. A. D. S., Lutz, A. M., Grosse, U., & Fregni, F. (2025) · Biomedicines · doi:10.3390/biomedicines13123005 · Cited by 39
Metadata
- Authors
- Chen, Z., Liu, X., Yang, Q., Wang, Y.-J., Miao, K., Gong, Z., Yu, Y., Leonov, A., Liu, C., Feng, Z., & Chuan-Peng, H.
- Affiliations
- Army Medical University (CN)
- Clark University (US)
- Qufu Normal University (CN)
- Nanjing Normal University (CN)
- Corresponding author
- Chen, Zhiyi
- Feng, Zhengzhi
- ORCID
- Venue
- JAMA Network Open
- Publisher
- American Medical Association (AMA)
- Published
- 2023-03-06
- Volume
- 6
- Issue
- 3
- Pages
- e231671
- ISSN
- 2574-3805 (ISSN-L)
- PMC
- PMC9989906
- OpenAlex
- W4323295479
- Cited by
- 43
- References
- 614
- Citations by year
- 2026: 20 · 2025: 10 · 2024: 10 · 2023: 3
- FWCI
- 0.51
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- JAMA Network Open (publishedVersion)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- Clark Digital Commons (Clark University) (submittedVersion, cc-by-nc-nd)
- Funders
- Chinese People’s Liberation Army
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Keywords
- psychiatric diagnosis, reporting quality, PROBAST, clinical applicability, model validation, sample size adequacy, model calibration
- MeSH terms
- Artificial Intelligence, Calibration, Humans, Bias, Benchmarking, Neuroimaging
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
