

The DOI matches its Crossref record; 189 of the 190 references it cites were found in a registry or an index; none of the 65 sources its claims cite is checked for support yet.
Large Language Models for Chatbot Health Advice Studies: A Systematic Review
Open accessAbstract
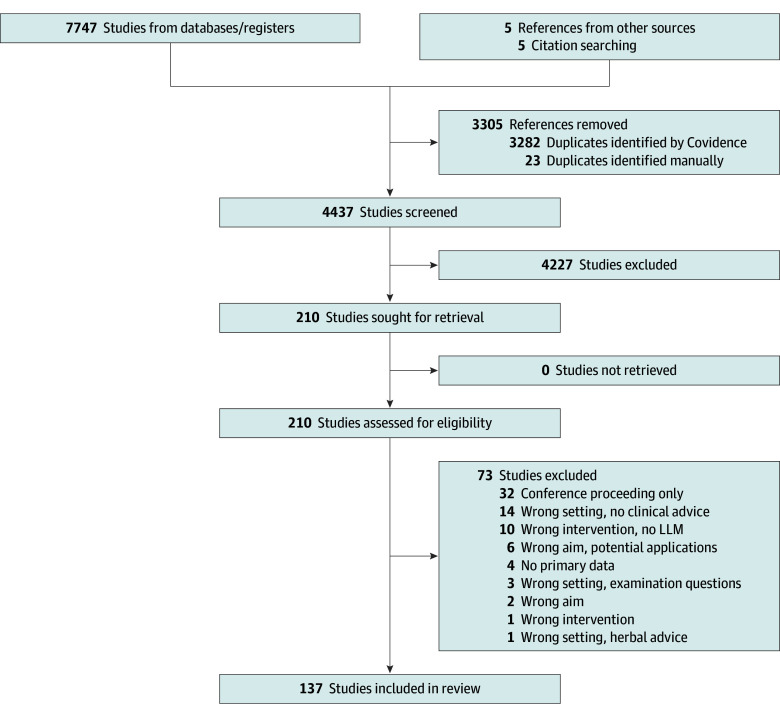
Importance: There is much interest in the clinical integration of large language models (LLMs) in health care. Many studies have assessed the ability of LLMs to provide health advice, but the quality of their reporting is uncertain. Objective: To perform a systematic review to examine the reporting variability among peer-reviewed studies evaluating the performance of generative artificial intelligence (AI)–driven chatbots for summarizing evidence and providing health advice to inform the development of the Chatbot Assessment Reporting Tool (CHART). Evidence Review: A search of MEDLINE via Ovid, Embase via Elsevier, and Web of Science from inception to October 27, 2023, was conducted with the help of a health sciences librarian to yield 7752 articles. Two reviewers screened articles by title and abstract followed by full-text review to identify primary studies evaluating the clinical accuracy of generative AI-driven chatbots in providing health advice (chatbot health advice studies). Two reviewers then performed data extraction for 137 eligible studies. Findings: A total of 137 studies were included. Studies examined topics in surgery (55 [40.1%]), medicine (51 [37.2%]), and primary care (13 [9.5%]). Many studies focused on treatment (91 [66.4%]), diagnosis (60 [43.8%]), or disease prevention (29 [21.2%]). Most studies (136 [99.3%]) evaluated inaccessible, closed-source LLMs and did not provide enough information to identify the version of the LLM under evaluation. All studies lacked a sufficient description of LLM characteristics, including temperature, token length, fine-tuning availability, layers, and other details. Most studies (136 [99.3%]) did not describe a prompt engineering phase in their study. The date of LLM querying was reported in 54 (39.4%) studies. Most studies (89 [65.0%]) used subjective means to define the successful performance of the chatbot, while less than one-third addressed the ethical, regulatory, and patient safety implications of the clinical integration of LLMs. Conclusions and Relevance: In this systematic review of 137 chatbot health advice studies, the reporting quality was heterogeneous and may inform the development of the CHART reporting standards. Ethical, regulatory, and patient safety considerations are crucial as interest grows in the clinical integration of LLMs.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This systematic review of 137 chatbot health advice studies found substantial heterogeneity and incomplete reporting of LLM characteristics, prompt engineering, query strategy, and performance evaluation. Most studies evaluated closed-source ChatGPT models and used investigator opinion rather than evidence-based reference standards, with less than one-third addressing ethics, patient safety, or regulation.
Key findings
- Of 137 CHAS, 135 (98.5%) assessed ChatGPT and 136 (99.3%) evaluated inaccessible/closed-source models; only 1 (0.7%) fully described the LLM version, and 36 (26.3%) described none of the LLM characteristics.
- Performance evaluation was often subjective: 89 studies (65.0%) used investigators’ opinion without a reference standard, while 21 (15.3%) used clinical practice guideline recommendations; 18 (13.1%) described a standardized evaluation process and 16 (11.7%) reported blinding.
- Reporting of methods was incomplete: 121 (88.3%) did not describe chatbot selection, 40 (29.2%) did not describe query strategy, 37 (27.0%) did not describe prompt source, 136 (99.3%) did not describe prompt testing/engineering, and 20 (14.6%) used standardized prompts.
- Ethical, safety, and regulatory implications were addressed by 45 (32.8%) for ethics, 44 (32.1%) for patient safety, and 22 (16.1%) for regulation of LLMs.
Methods
- Systematic review following PRISMA; protocol prospectively registered on Open Science Framework; searched MEDLINE via Ovid, Embase via Elsevier, and Web of Science on October 27, 2023.
- Two independent researchers screened titles/abstracts and full texts, with a third resolving disagreements; 7,752 articles reviewed yielded 137 eligible CHAS.
- Data extracted in Covidence; descriptive statistics and narrative synthesis were used, with no meta-analysis planned due anticipated heterogeneity; quality of evidence was not evaluated due lack of validated risk-of-bias tools for CHAS.
Limitations
- Stated: reporting in CHAS may change beyond review time due the dynamic nature of the field; much included literature used hypothetical patient cases; there is a paucity of literature detailing ethical and regulatory considerations; future patient-centered prospective research is needed.
- Stated: quality of evidence was not evaluated because no high-quality validated risk-of-bias tools were available for CHAS.
- Evident from the text: heterogeneity in study subjects and designs precluded meta-analysis; the review describes reporting practices and cannot establish causal effects of reporting on clinical outcomes.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
49 Own result · 35 Not checked yet · 7 No basis given · 5 Own method · 4 Own interpretation · 2 Sources not found
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, 136 articles (99.3%) did not describe a prompt testing/engineering phase, while 93 (67.9%) shared the full transcript of their prompts and 65 (47.4%) included the full transcript of chatbot responses.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, 136 articles (99.3%) did not describe a prompt testing/engineering phase, while 93 (67.9%) shared the full transcript of their prompts and 65 (47.4%) included the full transcript of chatbot responses.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Articles most commonly examined advice regarding treatment (91 [66.4%]), diagnosis (60 [43.8%]), and differential diagnosis (23 [16.8%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, 136 articles (99.3%) did not describe a prompt testing/engineering phase, while 93 (67.9%) shared the full transcript of their prompts and 65 (47.4%) included the full transcript of chatbot responses.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Most (64.5%) studies used subjective means as the ground truth to define the successful performance of the LLM, while less than a third addressed the ethical, regulatory, and patient safety implications of clinically integrating LLMs.”
§ Large Language Models for Chatbot Health Advice Studies > Abstract > Findings
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, 16 studies (11.7%) explained why the specific LLMs were selected to be studied.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Most (64.5%) studies used subjective means as the ground truth to define the successful performance of the LLM, while less than a third addressed the ethical, regulatory, and patient safety implications of clinically integrating LLMs.”
§ Large Language Models for Chatbot Health Advice Studies > Abstract > Findings
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“With respect to performance evaluation of chatbots, few studies described a standardized evaluation process (18 [13.1%]) or blinding (16 [11.7%]), and many studies did not describe a structured approach to performance evaluation (39 [28.5%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Study performance was suboptimal in noting the number of chat windows (32 [23.4%]) and the number of queries (48 [35.0%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Few studies noted the date (54 [39.4%]) and location (5 [3.6%]) of their query.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Performance Evaluation
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 24
- It may state two separate claims as one. 9
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Sources used to develop prompts included expert opinion (43 [31.4%]), professional society websites (28 [20.4%]), and clinical practice guidelines (24 [17.5%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Sources used to develop prompts included expert opinion (43 [31.4%]), professional society websites (28 [20.4%]), and clinical practice guidelines (24 [17.5%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, of the 137 articles reviewed, 51 (37.2%) studies queried LLMs for advice relevant for medical topics, 55 (40.1%) on surgical topics, 13 (9.5%) on primary care topics, 9 (6.6%) on radiology topics, and 7 (5.1%) on psychiatry topics (Table 1).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“There were no ongoing studies or studies awaiting classification.”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Sources used to develop prompts included expert opinion (43 [31.4%]), professional society websites (28 [20.4%]), and clinical practice guidelines (24 [17.5%]).”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In addition, there is a paucity of literature that comments in detail on the ethical and regulatory considerations of the clinical integration of LLMs that impact patient safety.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“This systematic review adheres to the reporting standards of the Preferred Reporting Items for Systematic Reviews and Meta-Analyses (PRISMA) reporting guideline.19”
§ Large Language Models for Chatbot Health Advice Studies > Methods
What the sources say
- Not checked yetcites [19] Page MJ, McKenzie JE, Bossuyt PM,. The PRISMA 2020 statement: an updated guideline for reporting systematic reviews. BMJ. 2021; 372(71): n71. doi: 10.1136/bmj.n71 33782057 PMC8005924 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The quality of the evidence was not evaluated due to the lack of high-quality, validated risk-of-bias tools available for CHAS.”
§ Large Language Models for Chatbot Health Advice Studies > Methods > Statistical Analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“To capture all relevant studies, an academic health sciences librarian (S.S.) with expertise in systematic reviews aided the study team in designing a comprehensive search strategy.”
§ Large Language Models for Chatbot Health Advice Studies > Methods > Search Strategy and Selection Criteria
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“However, chatbots are typically not designed for medical application and currently lack regulation for their use in medicine.10”
§ Large Language Models for Chatbot Health Advice Studies > Introduction
What the sources say
- Not checked yetcites [10] Li J, Dada A, Puladi B, Kleesiek J, Egger J. ChatGPT in healthcare: a taxonomy and systematic review. Comput Methods Programs Biomed. 2024; 245: 108013. doi: 10.1016/j.cmpb.2024.108013 38262126 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Furthermore, generative AI-driven chatbots present unique risks of hallucinating (ie, confident but incorrect) false results and propagating misleading information and advice.11”
§ Large Language Models for Chatbot Health Advice Studies > Introduction
What the sources say
- Not checked yetcites [11] Meskó B, Topol EJ. The imperative for regulatory oversight of large language models (or generative AI) in healthcare. NPJ Digit Med. 2023; 6(1): 120. doi: 10.1038/s41746-023-00873-0 37414860 PMC10326069 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Our protocol was prospectively registered on Open Sciences Framework.20”
§ Large Language Models for Chatbot Health Advice Studies > Methods
What the sources say
- Not matchedcites [20] Registries OSF. Protocol for a scoping review of chatbot assessment studies: guidance for the CHART tool. February 25, 2024. Accessed December 9, 2024. https://osf.io/cxsk3
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Not matched
In the paper
“With a lack of standardized reporting, the assessment of the quality of CHAS and the interpretation of their findings remain challenging.17”
§ Large Language Models for Chatbot Health Advice Studies > Introduction
What the sources say
- Not checked yetcites [17] Moher D, Schulz KF, Simera I, Altman DG. Guidance for developers of health research reporting guidelines. PLoS Med. 2010; 7(2): e1000217. doi: 10.1371/journal.pmed.1000217 20169112 PMC2821895 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Patients have reported interest in seeking medical advice from chatbots,7”
§ Large Language Models for Chatbot Health Advice Studies > Introduction
What the sources say
- Not checked yetcites [7] Shahsavar Y, Choudhury A. User intentions to use ChatGPT for self-diagnosis and health-related purposes: cross-sectional survey study. JMIR Hum Factors. 2023; 10: e47564. doi: 10.2196/47564 37195756 PMC10233444 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“In all cases, 2 independent researchers (W.T. and J.P.S.) conducted screening, with a third independent researcher casting a deciding vote to resolve cases of disagreement.”
§ Large Language Models for Chatbot Health Advice Studies > Methods > Search Strategy and Selection Criteria
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“Additionally, the existing literature base emphasizes a structured approach to performance evaluation.165”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Reporting of LLM Characteristics and Study Method
What the sources say
- Not checked yetcites [165] Guyatt GH, Oxman AD, Kunz R,. GRADE guidelines: 2. framing the question and deciding on important outcomes. J Clin Epidemiol. 2011; 64(4): 395- 400. doi: 10.1016/j.jclinepi.2010.09.012 21194891 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As these publications are largely prepared by clinicians, study teams may not have access to expertise in machine learning.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Reporting of LLM Characteristics and Study Method
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“LLMs have in-context learning capabilities that allow them to adapt to the given prompt, so prompts can be intentionally designed to support performance on further tasks, such as patient communication, administrative tasks, risk assessments, or clinical decision-making.160,161”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Reporting of LLM Characteristics and Study Method
What the sources say
- Not checked yetcites [160] Meskó B. Prompt engineering as an important emerging skill for medical professionals: tutorial. J Med Internet Res. 2023; 25(1): e50638. doi: 10.2196/50638 37792434 PMC10585440 source
- Not checked yetcites [161] Nguyen D, Swanson D, Newbury A, Kim YH. Evaluation of ChatGPT and Google Bard using prompt engineering in cancer screening algorithms. Acad Radiol. 2024; 31(5): 1799- 1804. doi: 10.1016/j.acra.2023.11.002 38103973 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Artificial intelligence–linked medical devices are considered software as a medical device and are regulated under federal departments such as Health Canada and the US Food and Drug Administration.170”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [170] Da Silva M, Flood CM, Goldenberg A, Singh D. Regulating the safety of health–related artificial intelligence. Healthc Policy. 2022; 17(4): 63- 77. doi: 10.12927/hcpol.2022.26824 35686827 PMC9170055 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“While other regulated AI medical technologies, such as radiology image analysis177 or diagnosis,178 are trained on domain-specific medical data for targeted uses, LLMs have broader complexity, applicability, and an ability to adapt in real time, which complicates their regulation.2,179,180”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [2] Thirunavukarasu AJ, Ting DSJ, Elangovan K, Gutierrez L, Tan TF, Ting DSW. Large language models in medicine. Nat Med. 2023; 29(8): 1930- 1940. doi: 10.1038/s41591-023-02448-8 37460753 source
- Not checked yetcites [179] Wu E, Wu K, Daneshjou R, Ouyang D, Ho DE, Zou J. How medical AI devices are evaluated: limitations and recommendations from an analysis of FDA approvals. Nat Med. 2021; 27(4): 582- 584. doi: 10.1038/s41591-021-01312-x 33820998 source
- Not checked yetcites [180] Nagendran M, Chen Y, Lovejoy CA,. Artificial intelligence versus clinicians: systematic review of design, reporting standards, and claims of deep learning studies in medical imaging. BMJ. 2020; 368:m689. doi: 10.1136/bmj.m689 PMC7190037 32213531 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Many studies describe this as defining a ground truth or evaluation dataset, and it is an essential step in LLM performance evaluation.166,167”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Reporting of LLM Characteristics and Study Method
What the sources say
- Not checked yetcites [166] Chang Y, Wang X, Wang J,. A survey on evaluation of large language models. ACM Trans Intell Syst Technol. 2024; 15(3): 1- 45. doi: 10.1145/3641289 source
- Not checked yetcites [167] Liang JJ, Tsou CH, Devarakonda MV. Ground truth creation for complex clinical NLP tasks: an iterative vetting approach and lessons learned. AMIA Jt Summits Transl Sci Proc. 2017; 2017: 203- 212. 28815130 PMC5543376
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Just as sufficient detail about medical or surgical interventions must be reported in traditional studies to reproduce experiments and guide critical appraisal, LLM characteristics are similarly vital.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Reporting of LLM Characteristics and Study Method
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“By engineering a comprehensive search strategy, we aimed to capture an accurate representation of the literature.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Limitations
plain- Asserted: fails — The authors may not put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The authors may not put it forward as true. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“The World Health Organization released guidance on ethics and governance of AI for health,182 which overlaps substantially with LLMs, which are unimodal models.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [182] World Health Organization. Ethics and governance of artificial intelligence for health. Accessed November 4, 2024. https://www.who.int/publications/i/item/9789240029200
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“First, the reporting used in CHAS may change beyond the time of this review due to the dynamic nature of this field.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Limitations
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“While clinical practice is informed by evidence from peer-reviewed research, LLMs replicate their input data and thus may propagate online health misinformation and prejudices,189,190 compromising patient safety.”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [189] Meyrowitsch DW, Jensen AK, Sørensen JB, Varga TV. AI chatbots and (mis)information in public health: impact on vulnerable communities. Front Public Health. 2023; 11: 1226776. doi: 10.3389/fpubh.2023.1226776 38026315 PMC10644115
- Not checked yetcites [190] Khan B, Fatima H, Qureshi A,. Drawbacks of artificial intelligence and their potential solutions in the healthcare sector. Biomed Mater Devices. 2023; 1(2): 1- 8. doi: 10.1007/s44174-023-00063-2 36785697 PMC9908503
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Concerns have also been raised related to data privacy of patient health information among proprietary LLMs.182,191”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [182] World Health Organization. Ethics and governance of artificial intelligence for health. Accessed November 4, 2024. https://www.who.int/publications/i/item/9789240029200
- Not checked yetcites [191] Yao Y, Duan J, Xu K, Cai Y, Sun Z, Zhang Y. A survey on large language model (LLM) security and privacy: the good, the bad, and the ugly. High-Confidence Computing. 2024; 4(2). doi: 10.1016/j.hcc.2024.100211
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Taken together, these factors raise major issues as we move from the technological development of LLMs to their clinical validation for use in health care settings.182”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [182] World Health Organization. Ethics and governance of artificial intelligence for health. Accessed November 4, 2024. https://www.who.int/publications/i/item/9789240029200
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
In the paper
“Standardized frameworks are under development to establish detailed reporting standards to help authors design and report these studies.18”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Limitations
What the sources say
- Not checked yetcites [18] Huo B, Cacciamani GE, Collins GS, McKechnie T, Lee Y, Guyatt G. Reporting standards for the use of large language model-linked chatbots for health advice. Nat Med. 2023; 29(12): 2988. doi: 10.1038/s41591-023-02656-2 37957381 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“There is a potential for misuse of patient data, medicolegal implications, and loss of physician-patient trust.181,192”
§ Large Language Models for Chatbot Health Advice Studies > Discussion > Ethics, Patient Safety, and LLM Regulation
What the sources say
- Not checked yetcites [181] Ong JCL, Chang SYH, William W,. Ethical and regulatory challenges of large language models in medicine. Lancet Digit Health. 2024; 6(6): e428- e432. doi: 10.1016/S2589-7500(24)00061-X 38658283 source
- Not checked yetcites [192] Wang C, Liu S, Yang H, Guo J, Wu Y, Liu J. Ethical considerations of using ChatGPT in health care. J Med Internet Res. 2023; 25: e48009. doi: 10.2196/48009 37566454 PMC10457697 source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper relies on this without support.
The generated output depends greatly on the initial input.
“However, the generated output depends greatly on the initial input.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Prior work to date on patient safety of patient-facing applications has primarily been focused on particular diagnoses or specialties”
From Large language models provide unsafe answers to patient-posed medical questions (2026) · cites this paper as [10]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“To the best of our knowledge, there have been no previous studies on patient safety of patient-facing applications for a wide range of primary care questions that patients are likely to ask.”
From Large language models provide unsafe answers to patient-posed medical questions (2026) · cites this paper as [10]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Within this review, the authors noted that the majority of studies (68%) did not consider patient safety.”
From Large language models provide unsafe answers to patient-posed medical questions (2026) · cites this paper as [10]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| No | 29 (21.7)21,22,28,35,36,37,42,51,55,60,76,78,79,80,82,88,93,108,110,113,128,130,138,140,143,150,151,152,154 |”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
Reported 21.7 · recomputed 21.167883
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Patient safety | 44 (32.8)”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
Reported 32.8 · recomputed 32.116788
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
“| Accessibility (open vs closed) | 4 (2.9)33,37,123,147 |”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
“| Not described | 121 (88.3)6,13,21,22,24,27,28,29,30,33,34,35”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
“| Yes | 3 (2.2)6,55,68,76,127 |”
§ Large Language Models for Chatbot Health Advice Studies > Results > Study Characteristics
“6,55,68,76,127”
Citations
Cites
The PRISMA 2020 statement: An updated guideline for reporting systematic reviews
Page, M. J., McKenzie, J. E., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., et al. (2021) · BMJ · doi:10.1136/bmj.n71 · Cited by 108,283
A Survey on Evaluation of Large Language Models
Chang, Y., Wang, X., Wang, J., Wu, Y., Yang, L., Zhu, K., Chen, H., Yi, X., Wang, C., Wang, Y., et al. (2024) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3641289 · Cited by 4,254
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Self-citationRevolutionizing healthcare: the role of artificial intelligence in clinical practice
Alowais, S. A., Alghamdi, S. S., Alsuhebany, N., Alqahtani, T., Alshaya, A. I., Almohareb, S. N., Aldairem, A., Alrashed, M., Bin Saleh, K., Badreldin, H. A., et al. (2023) · BMC Medical Education · doi:10.1186/s12909-023-04698-z · Cited by 3,146
Sallam, M. (2023) · Healthcare · doi:10.3390/healthcare11060887 · Cited by 3,126
Ayers, J. W., Poliak, A., Dredze, M., Leas, E. C., Zhu, Z., Kelley, J. B., Faix, D. J., Goodman, A. M., Longhurst, C. A., Hogarth, M., et al. (2023) · JAMA Internal Medicine · doi:10.1001/jamainternmed.2023.1838 · Cited by 2,613
Gilson, A., Safranek, C. W., Huang, T., Socrates, V., Chi, L., Taylor, R. A., & Chartash, D. (2023) · JMIR Medical Education · doi:10.2196/45312 · Cited by 2,078
GRADE guidelines: 2. Framing the question and deciding on important outcomes
Guyatt, G. H., Oxman, A. D., Kunz, R., Atkins, D., Brozek, J., Vist, G., Alderson, P., Glasziou, P., Falck-Ytter, Y., & Schünemann, H. J. (2011) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2010.09.012 · Cited by 1,911
Self-citation
Research works printed but not linked: 2
- Wang? Y, Visweswaran? S, Kappor? S, Kooragayalu? S, Wu? X. ChatGPT, enhanced with clinical practice guidelines, is a superior decision support tool. [published online August 13, 2023].? MedRxiv.
- Zhou? J, He? X, Sun? L, . SkinGPT-4: an interactive dermatology diagnostic system with visual large language model. Published online April 20, 2023.MedRxiv.
Cited by
Sorted by citations
Items 301–304 of 304
Sleep in Children with Chronic Illnesses: A Pediatrician's Perspective
KARA, Ş. Ş. (2026) · Bidge Yayınları eBooks · doi:10.70269/10.70269/9737156739
Ying, D., Zeng, Q., Ying, M., Min, Y., & Zhong, J. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1986047
Lu, R., Wei, Y., Wu, S., Han, Y., Zhao, S., Hu, H., & Chen, Y. (2026) · Journal of Medical Internet Research · doi:10.2196/97878
The CHART reporting guideline: the flow must go on
Huo, B., Cacciamani, G. E., Collins, P. G. S., & Guyatt, G. H. (2026) · International Journal of Surgery · doi:10.1097/js9.0000000000005729
Self-citation
Metadata
- Authors
- Huo, B., Boyle, A., Marfo, N., Tangamornsuksan, W., Steen, J. P., McKechnie, T., Lee, Y., Mayol, J., Antoniou, S. A., Thirunavukarasu, A. J., Sanger, S., Ramji, K., & Guyatt, G.
- Affiliations
- McMaster University (CA)
- H. Ross University School of Medicine, Miramar, Florida
- University of Toronto (CA)
- Universidad Complutense de Madrid (ES)
- Papageorgiou General Hospital (GR)
- University of Oxford (GB)
- Corresponding author
- Huo, Bright
- ORCID
- Venue
- JAMA Network Open
- Publisher
- American Medical Association (AMA)
- Published
- 2025-02-04
- Volume
- 8
- Issue
- 2
- Pages
- e2457879
- ISSN
- 2574-3805 (ISSN-L)
- PMC
- PMC11795331
- OpenAlex
- W4407135263
- Semantic Scholar
- 8e5b1084560f7b370363a2ad302c602e7a1ba78c
- Cited by
- 283
- References
- 184
- Citations by year
- 2026: 210 · 2025: 73
- FWCI
- 16.72
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- JAMA Network Open (publishedVersion, cc-by)
- PubMed (publishedVersion)
- PubMed Central (publishedVersion, cc-by)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- large language models, chatbots, health advice, reporting quality, generative AI, clinical integration, prompt engineering, patient safety, ethical and regulatory considerations, clinical accuracy
- MeSH terms
- Large Language Models, Generative Artificial Intelligence, Artificial Intelligence, Humans
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-07, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-07 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
