

The DOI matches its Crossref record.
From Digitization and Images to Text and Content: Transkribus as a Case Study
Abstract
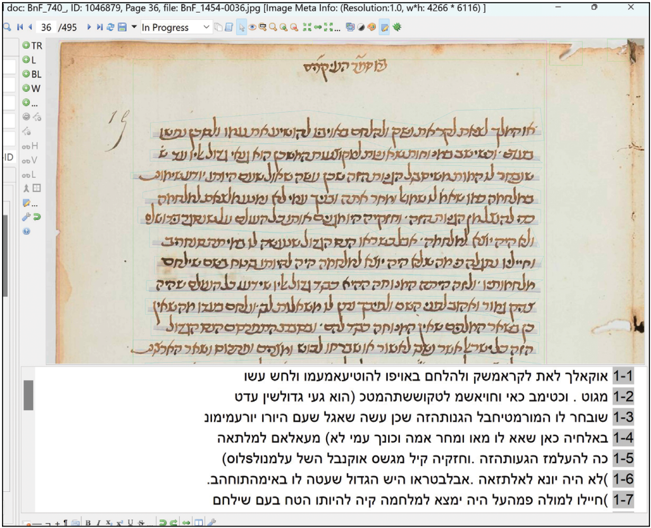
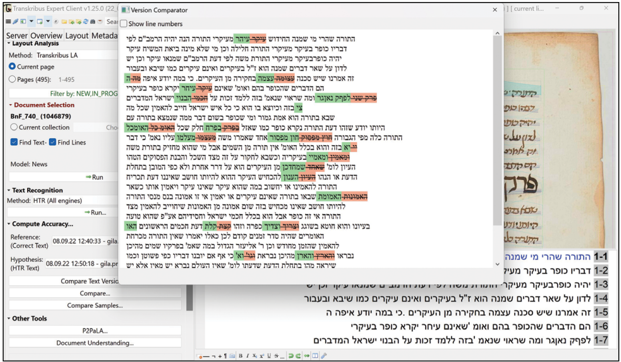
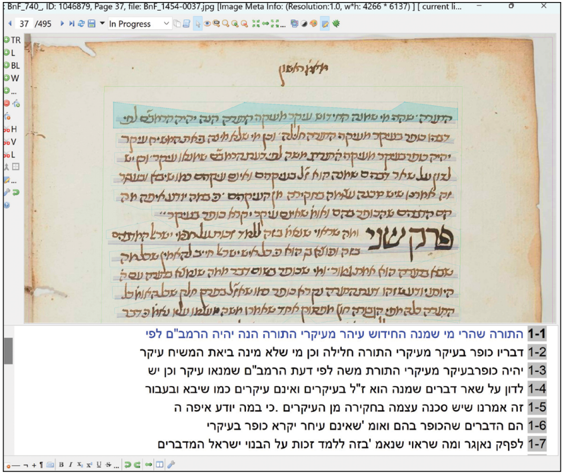
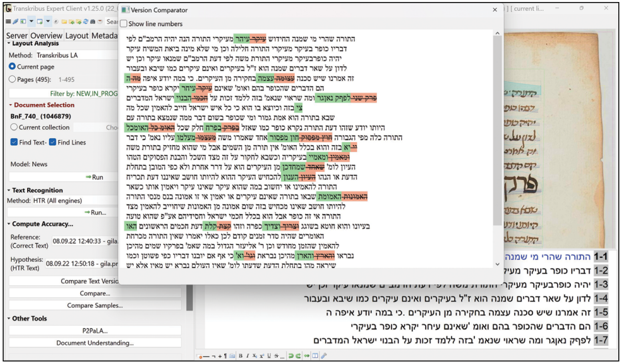
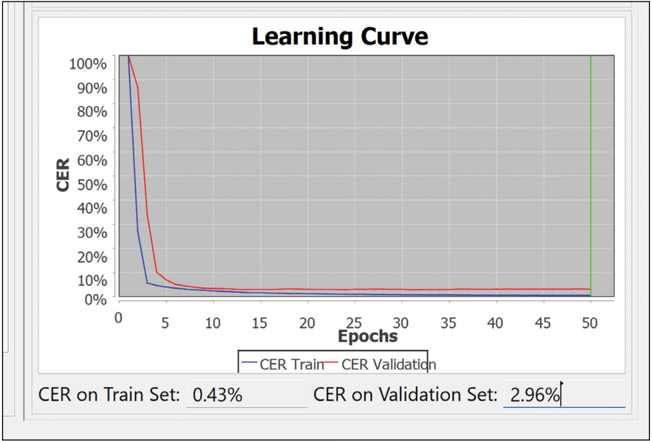
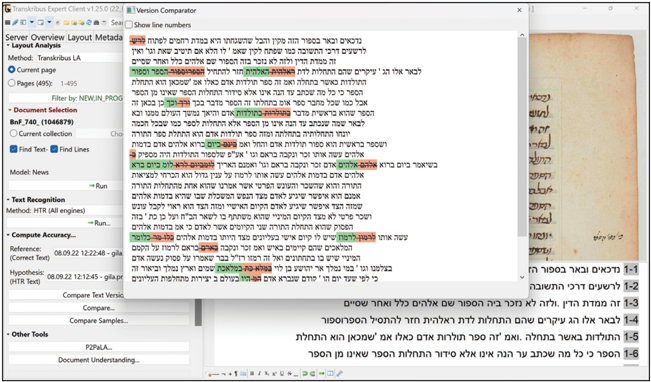
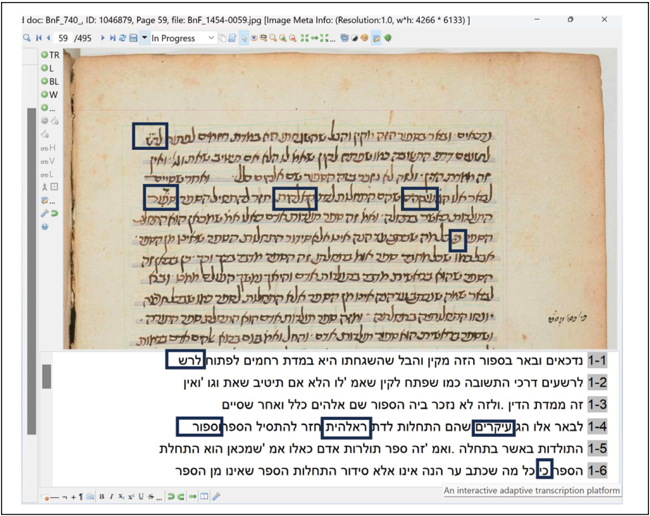
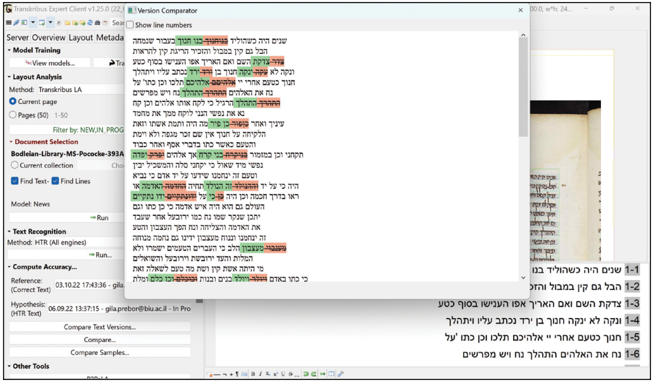
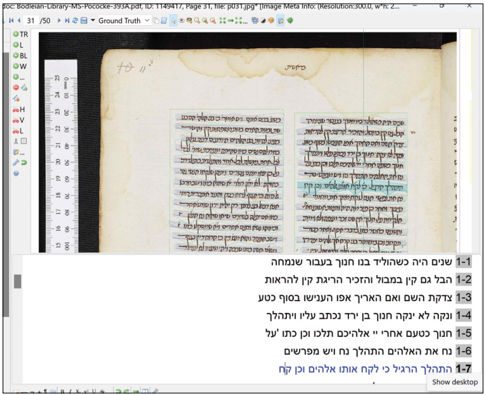
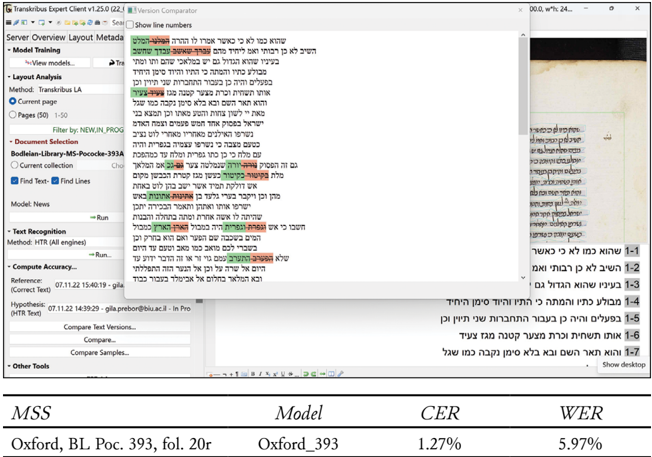
This poster explores the potential of using technological tools, specifically the Transkribus platform, for the transcription of Hebrew manuscripts. The digitization of historical resources has made them accessible, but the textual content of the scanned images remains inaccessible. Transkribus, an AI‐powered platform, offers tools for text recognition, transcription, and search of historical documents. The poster discusses the process of automatic text recognition (ATR) and the challenges it faces, particularly in handling handwritten texts and Hebrew letters. It provides an overview of the Transkribus platform, its functionalities, and the training process for creating transcription models. The author presents a case study of transcribing a 15th‐century Sephardic semi‐cursive Hebrew manuscript using the Transkribus platform and evaluates the performance of different models. The poster concludes by discussing the implications and possibilities of using Transkribus for automatic transcription of historical Hebrew manuscripts. While the results show promising improvements in accuracy, further challenges and solutions are also discussed. Overall, Transkribus offers significant potential for the study and transcription of Hebrew manuscripts, revolutionizing the field of Jewish studies and historical research.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“which is comparable to the results reported by other authors (Christlein et al 2018;Ó Raghallaigh 2022;Prebor 2023).”
From Unlocking the archives: Using large language models to transcribe handwritten historical documents (2025) · cites this paper as Prebor 2023
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
No references could be resolved yet.
Research works printed but not linked: 3
- 10.1109/ICCICCT.2014.6993174 · DOI
- 10.46298/jdmdh.6249 · DOI
- 10.1108/JD-07-2018-0114 · DOI · Paper page
Cited by
Unlocking the archives: Using large language models to transcribe handwritten historical documents
Humphries, M., Leddy, L. C., Downton, Q., Legace, M., McConnell, J., Murray, I., & Spence, E. (2025) · Historical Methods: A Journal of Quantitative and Interdisciplinary History · doi:10.1080/01615440.2025.2500309 · Cited by 72
Metadata
- Authors
- Prebor, G.
- Affiliations
- Bar Ilan University Israel
- Venue
- Proceedings of the Association for Information Science and Technology
- Publisher
- Wiley
- Published
- 2023-10
- Volume
- 60
- Issue
- 1
- Pages
- 1102-1103
- ISSN
- 2373-9231
- Cited by
- 1
- References
- 0
- Language
- en
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: From Digitization and Images to Text and Content: Transkribus as a Case Study. https://app.cochat.ai/papers/10.1002/pra2.958
- The paper
- Prebor, G. (2023). From Digitization and Images to Text and Content: Transkribus as a Case Study. Proceedings of the Association for Information Science and Technology. https://doi.org/10.1002/pra2.958
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
