

The DOI matches its Crossref record; 42 of the 42 references it cites were found in a registry or an index; 1 of the 26 sources its claims cite were checked for support.
Deep reinforcement learning-based adaptive fuzzy control for electro-hydraulic servo system
Open accessAbstract
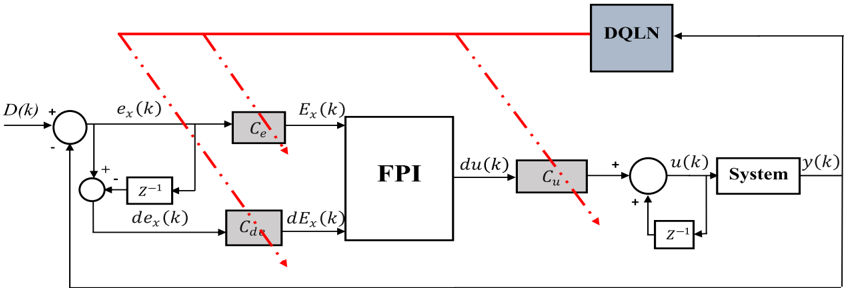
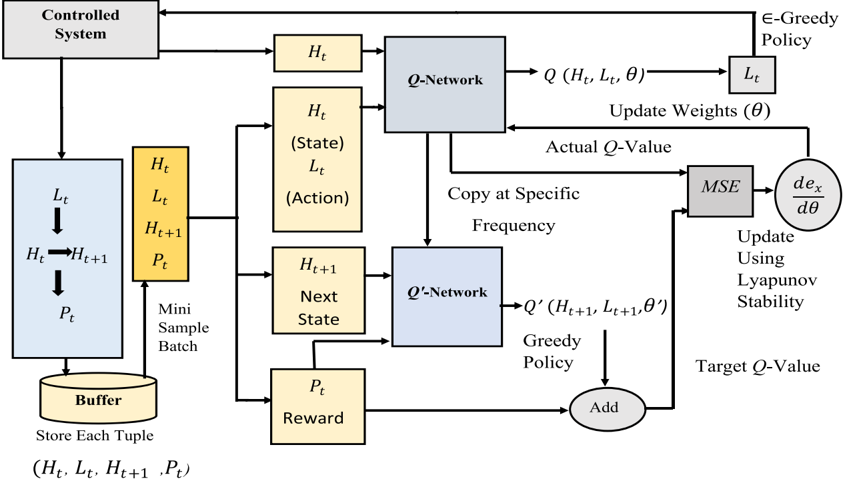
In this paper, a novel adaptive fuzzy controller based on deep reinforcement learning (DRL) is introduced for electro-hydraulic servo systems. The controller combines the strengths of fuzzy proportional–integral (PI) control and deep Q-learning network (DQLN) to achieve real-time adaptation and improve the control performance. The purpose of this paper is to address the challenges of controlling electro-hydraulic servo systems by developing an adaptive controller that can dynamically adjust its control parameters based on the system’s state. The traditional fuzzy PI controller is enhanced with DRL techniques to enable automatic adaptation and compensation for changing online conditions. The proposed adaptive controller utilizes a DQLN to dynamically adjust the scaling factors of the input/output membership functions. By using the DQLN algorithm, the controller learns from a variety of system data to determine the optimal control parameters. The update equation of the weights for the Q-network is derived using the Lyapunov stability (LS) theorem, which overcomes the limitations of gradient descent (GD) methods such as instability and local minima trapping. To evaluate the effectiveness of the proposed controller, it is practically implemented to regulate an electro-hydraulic servo system. The controller’s performance is compared against other existing controllers, and its enhancements are demonstrated through experimental evaluation.
Overview
CoChat Summary
TL;DR
The paper proposes AFPIC-DQLN, an adaptive fuzzy PI controller whose input/output scaling factors are tuned online by a deep Q-learning network with Lyapunov-stability-based weight updates, and implements it on an EHS160 electro-hydraulic servo system. In practical tests, it achieved lower IAE and ISE than PID, FPI, AFPIC-QL, and DACRL controllers across step, load, disturbance, and noise tasks, at a higher computation time (0.651 ms) that remained below the sampling period.
Key findings
- Across all four practical tasks, AFPIC-DQLN had the lowest IAE among the five controllers; e.g., Task 1 IAE was 180.50 vs PID 1788.43, FPI 1280.60, AFPIC-QL 750.33, and DACRL 200.50, and Task 4 IAE was 34.45 vs PID 250.74, FPI 155.12, AFPIC-QL 90.27, and DACRL 40.89.
- AFPIC-DQLN also had the lowest ISE; e.g., Task 1 ISE was 908.92 vs PID 6100, FPI 5550, AFPIC-QL 2312, and DACRL 1002, and Task 4 ISE was 70.21 vs PID 450.24, FPI 351.36, AFPIC-QL 150.34, and DACRL 112.24.
- The proposed controller’s computation time was 0.651 ms, higher than PID (0.045 ms), FPI (0.058 ms), AFPIC-QL (0.554 ms), and DACRL (0.597 ms), but the authors state it remains smaller than the sampling period.
- The Lyapunov-stability-based weight update is presented as overcoming gradient-descent limitations such as instability and local minima, and the controller is reported to adapt online to load changes, dynamic disturbance, and actuator noise.
Methods
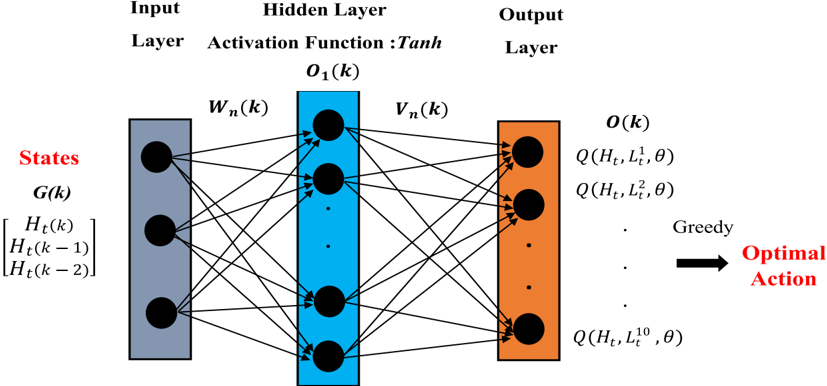
- Design: adaptive fuzzy PI controller (AFPIC) with a deep Q-learning network (DQLN) that dynamically adjusts the input/output scaling factors of the FPI controller; Q-network weights are updated using the Lyapunov stability theorem, and the target Q′-network is updated periodically.
- Data/sample: practical implementation on an EHS160 electro-hydraulic servo system controlling hydraulic motor speed, using Arduino Mega for data acquisition and MATLAB for control; training used buffer B = 1000, 5000 episodes, max 1000 steps per episode, sampling time 10 ms, learning rate 0.001, discount factor 0.05, epsilon 0.9, and scaling factor ranges Ce [0.009, 0.1], Cde [0.005, 0.5], Cu [1, 9].
- Main analysis: compared AFPIC-DQLN against PID, nonadaptive FPI, AFPIC-QL, and DACRL under step changes, 30% and 50% external loads, dynamic sinusoidal disturbance, and actuator noise; performance assessed with IAE, ISE, RMSE, transient response specifications, and computation time.
Limitations
- The paper does not include a dedicated limitations section; it states future work will employ hierarchical deep reinforcement learning based on interval type-2 fuzzy systems to accommodate potential random perturbations and statistical experimental assessments (stated).
- The proposed controller has higher computation time than all compared controllers (0.651 ms vs 0.045–0.597 ms), though the authors note it remains below the sampling period (stated in Remark 2).
- Evident from the text: evaluation is confined to one EHS160 electro-hydraulic servo system and four practical tasks, and the Data availability statement says no datasets were generated or analyzed; training requires 5000 episodes with a 1000-sample buffer and 500-sample batch, which may limit generalizability.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures





Verification
Claims the paper makes
1 Valid · 1 Not valid · 20 Not checked · 44 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
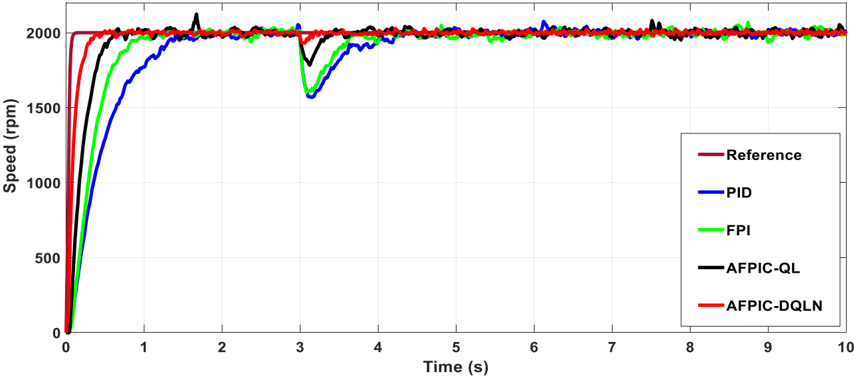
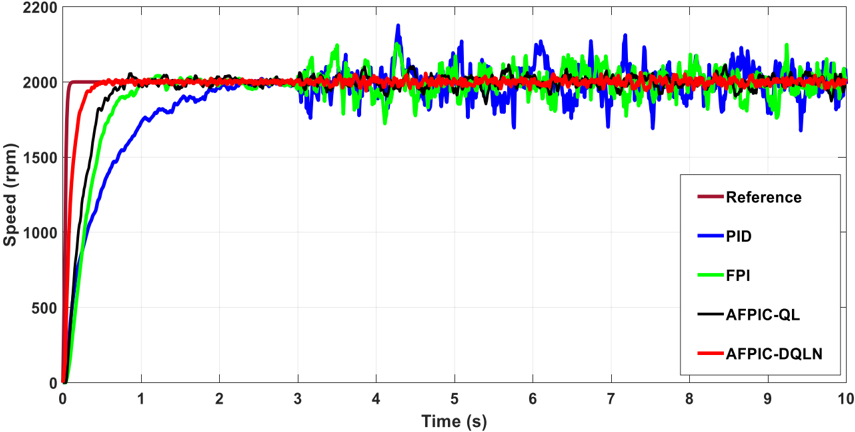
“The system's response and the control signal are displayed in Figs. 7 and 8, respectively, using various controllers, indicating that the suggested AFPIC-DQLN can rapidly track the changes in the set-point.”
hedgedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The update equation of the weights for the Q-network is derived using the Lyapunov stability (LS) theorem”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Enhancing the performance of the controlled system through the implementation of the proposed approach when compared to alternative methods.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These figures demonstrate that the proposed controller performs well in tracking the system quickly despite the presence of noise.”
boostedSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The proposed AFPIC-DQLN outperforms the other controllers.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
27 more claims
Create a free account to see all 66 claims and to verify the 2 references still open.
- It may state two separate claims as one. 20
- Probably not a substantial claim. 17
- The quote only partly states this claim. 1
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 5.2 Task 2: applying external load · p. 11
“these loads are sustained until the end of the period.”
§ 5.2.2 Second scenario: apply 50% load · p. 11
“During this task, a 50% load disturbance is applied to the hydraulic motor at t ¼ 3 s and removed at t ¼ 6 s .”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 5.2.2 Second scenario: apply 50% load · p. 11
“Figures 11 and 12 demonstrate the system response and the control signal, respectively, using various controllers”
§ 5.4 Task 4: actuator noise · p. 14
“Fig. 11 Response of the EHS160 for task 3 (Second scenario)”
Citations
Cites
Deep Reinforcement Learning: A Brief Survey
Arulkumaran, K., Deisenroth, M. P., Brundage, M., & Bharath, A. A. (2017) · IEEE Signal Processing Magazine · doi:10.1109/msp.2017.2743240 · Cited by 4,733 · cited 1×
“Random samples are selected from the M as experienced samples during each specific sample time to train a Q - network [24].”
A review of PID control, tuning methods and applications
Borase, R. P., Maghade, D. K., Sondkar, S. Y., & Pawar, S. N. (2021) · International Journal of Dynamics and Control · doi:10.1007/s40435-020-00665-4 · Cited by 1,036 · cited 1×
“…and simple design, the classical PID controllers remain the predominant control mechanism in most industrial processes, but they are not designed to control nonlinear, highly complex systems, ambiguous in the absence of precise mathematical models and the existence of uncertainty in systems [1].”
Wang, W., Yu, N., Gao, Y., & Shi, J. (2020) · IEEE Transactions on Smart Grid · doi:10.1109/tsg.2019.2962625 · Cited by 331 · cited 1×
“It uses an off-policy date and the Bellman equation [14].”
Zhang, H., Liu, Y., & Wang, Y. (2021) · IEEE Transactions on Cybernetics · doi:10.1109/tcyb.2020.2984791 · Cited by 289
Deep reinforcement learning-based controller for path following of an unmanned surface vehicle
Woo, J., Yu, C., & Kim, N. (2019) · Ocean Engineering · doi:10.1016/j.oceaneng.2019.04.099 · Cited by 246 · cited 1×
“It was able to learn different policies from traditional controllers during training because it learned how to map the system output to control actions [13].”
A Q-Learning Approach to Flocking With UAVs in a Stochastic Environment
Hung, S.-M., & Givigi, S. N. (2017) · IEEE Transactions on Cybernetics · doi:10.1109/tcyb.2015.2509646 · Cited by 196 · cited 1×
“The use of reinforcement learning (RL) in industrial process control is an intriguing application of this field in which the controllers interact with the environment through discrete actions and receive rewards [6].”
Zamfirache, I. A., Precup, R.-E., Roman, R.-C., & Petriu, E. M. (2022) · Information Sciences · doi:10.1016/j.ins.2021.10.070 · Cited by 172
Implementation Matters in Deep Policy Gradients: A Case Study on PPO and TRPO
Engstrom, L., Ilyas, A., Santurkar, S., Tsipras, D., Janoos, F., Rudolph, L., & Madry, A. (2020) · arXiv · doi:10.48550/arxiv.2005.12729 · Cited by 146
Zhang, Z., Song, X., Sun, X., & Stojanovic, V. (2023) · International Journal of Adaptive Control and Signal Processing · doi:10.1002/acs.3529 · Cited by 145
A Deep Actor-Critic Reinforcement Learning Framework for Dynamic Multichannel Access
Zhong, C., Lu, Z., Gursoy, M. C., & Velipasalar, S. (2019) · IEEE Transactions on Cognitive Communications and Networking · doi:10.1109/tccn.2019.2952909 · Cited by 123 · cited 2×
“It requires consistently training the critic without divergence that delays learning and the propagation of value estimations through the target network [16].”
Cited by
Zhang, W., Wang, B., Wu, Z., Zhang, F., Zhang, J., Zhang, S., Zhang, J., Zhang, J., Sun, H., Waters, K. E., et al. (2025) · Precision Engineering · doi:10.1016/j.precisioneng.2025.07.011 · Cited by 17
Sliding mode control of electro-hydraulic servo based on neural network adaptive observer
Sun, C., Chen, S., & Deng, Z. (2025) · Electronic Research Archive · doi:10.3934/era.2025296 · Cited by 4
Wu, Y., Wang, D., Zhou, J., et al. (2025) · Advances in Mechanical Engineering · doi:10.1177/16878132251408119 · Cited by 2
“22 Similarly, an adaptive neuro-fuzzy PID controller based on the twin delayed deep deterministic policy gradient (TD3) algorithm demonstrated effective gain tuning in highly nonlinear environments.”
Li, W., Li, M., Liu, J., Wang, G., Qi, Y., Wang, W., Li, Y., & Liu, S. (2025) · AIMS Mathematics · doi:10.3934/math.20251357 · Cited by 2
Zhang, W., Lu, J., Ge, W., et al. (2025) · World Electric Vehicle Journal · doi:10.3390/wevj16070366 · Cited by 1
Metadata
- Authors
- Khater, A. A., Fekry, M., El-Bardini, M., & El-Nagar, A. M.
- Affiliations
- Menoufia University (EG)
- Corresponding author
- El-Nagar, Ahmad M.
- ORCID
- El-Nagar, Ahmad M.
- Venue
- Neural Computing and Applications
- Published
- 2025-01-10
- Volume
- 37
- Issue
- 30
- Pages
- 24607-24624
- ISSN
- 0941-0643 (ISSN-L)
- 1433-3058
- OpenAlex
- W4406237058
- Cited by
- 17
- References
- 36
- Citations by year
- 2026: 10 · 2025: 7
- FWCI
- 4.94
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Neural Computing and Applications (publishedVersion, cc-by)
- Funders
- Minufiya University
- Topics
- Physical Sciences › Engineering › Mechanical Engineering › Hydraulic and Pneumatic Systems
- Physical Sciences › Engineering › Control and Systems Engineering › Adaptive Control of Nonlinear Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Fuzzy Logic and Control Systems
- Keywords
- electro-hydraulic servo system, deep reinforcement learning, adaptive fuzzy control, fuzzy PI controller, Lyapunov stability, real-time parameter adaptation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Deep reinforcement learning-based adaptive fuzzy control for electro-hydraulic servo system. https://app.cochat.ai/papers/10.1007/s00521-024-10741-x
- The paper
- Khater, A. A., Fekry, M., El-Bardini, M., & El-Nagar, A. M. (2025). Deep reinforcement learning-based adaptive fuzzy control for electro-hydraulic servo system. Neural Computing and Applications. https://doi.org/10.1007/s00521-024-10741-x
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
