

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
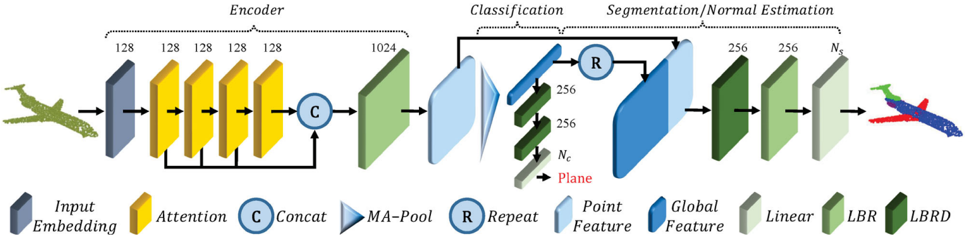
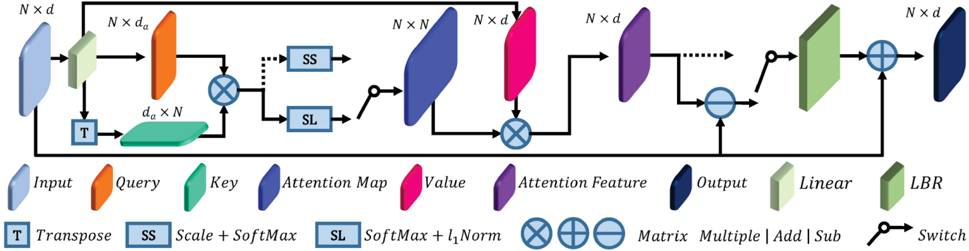
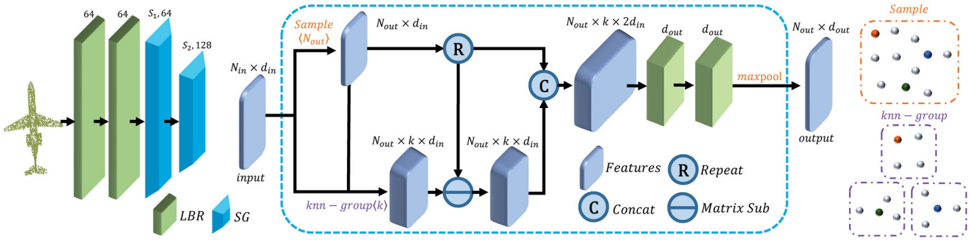
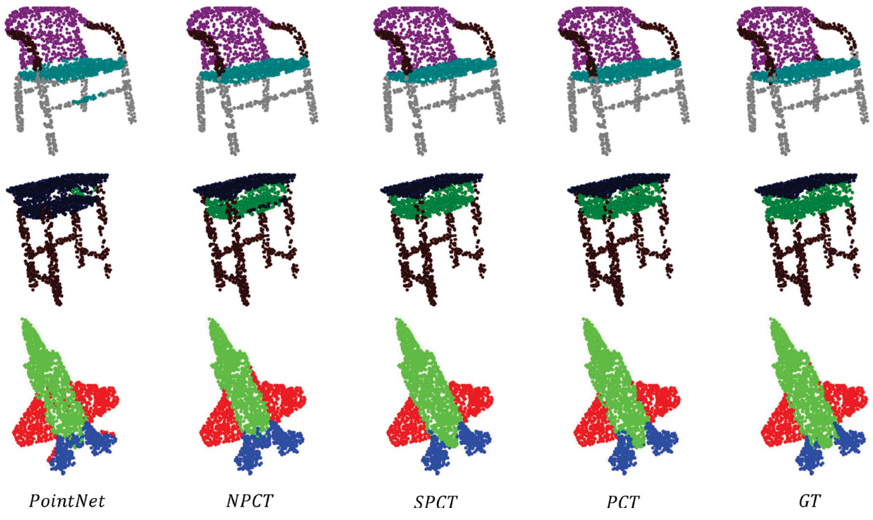
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Self-Attention Generative Adversarial Networks
Zhang, H., Goodfellow, I., Metaxas, D., & Odena, A. (2018) · arXiv · doi:10.48550/arxiv.1805.08318 · Cited by 3,353
Large-Scale Point Cloud Semantic Segmentation with Superpoint Graphs
Landrieu, L., & Simonovsky, M. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00479 · Cited by 1,543
Proceedings of the 2nd International Conference on Neural Information Processing Systems
Touretzky, D. S. (1989) · Cited by 1,439
A scalable active framework for region annotation in 3D shape collections
Yi, L., Kim, V. G., Ceylan, D., Shen, I., Yan, M., Su, H., Lu, C., Qi-xing Huang, A., Sheffer, A., & Guibas, L. J. (2016) · ACM Transactions on Graphics · doi:10.1145/2980179.2980238 · Cited by 1,209
Proceedings of the 24th annual meeting on Association for Computational Linguistics -
Biermann, A. W. (1986) · doi:10.3115/981131 · Cited by 1,083
Relation-Shape Convolutional Neural Network for Point Cloud Analysis
Liu, Y., Fan, B., Xiang, S., & Pan, C. (2019) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2019.00910 · Cited by 1,042
Visual Transformers: Token-based Image Representation and Processing for Computer VisionPreprint
Wu, B., Xu, C., Dai, X., Wan, A., Zhang, P., Yan, Z., Tomizuka, M., Gonzalez, J., Keutzer, K., & Vajda, P. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2006.03677 · Cited by 649
Tangent Convolutions for Dense Prediction in 3D
Tatarchenko, M., Park, J., Koltun, V., & Zhou, Q.-Y. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00409 · Cited by 592
Point convolutional neural networks by extension operators
Atzmon, M., Maron, H., & Lipman, Y. (2018) · ACM Transactions on Graphics · doi:10.1145/3197517.3201301 · Cited by 559
Attentional ShapeContextNet for Point Cloud Recognition
Xie, S., Liu, S., Chen, Z., & Tu, Z. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00484 · Cited by 359
Liu, X., Han, Z., Liu, Y.-S., & Zwicker, M. (2019) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v33i01.33018778 · Cited by 330
Monte Carlo convolution for learning on non-uniformly sampled point clouds
Hermosilla, P., Ritschel, T., Vázquez, P.-P., Vinacua, À., & Ropinski, T. (2018) · ACM Transactions on Graphics · doi:10.1145/3272127.3275110 · Cited by 270
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Han (2023) · doi:10.1109/tpami.2022.3152247 · Cited by 4,682
Self-citationTransformers in Vision: A Survey
Khan, S., Naseer, M., Hayat, M., Zamir, S. W., Khan, F. S., & Shah, M. (2022) · ACM Computing Surveys · doi:10.1145/3505244 · Cited by 3,595
Attention mechanisms in computer vision: A survey
Guo, M.-H., Xu, T.-X., Liu, J.-J., Liu, Z.-N., Jiang, P.-T., Mu, T.-J., Zhang, S.-H., Martin, R. R., Cheng, M.-M., & Hu, S.-M. (2022) · Computational Visual Media · doi:10.1007/s41095-022-0271-y · Cited by 2,566
“Recently, various pure deep self-attention networks (visual transformers) [27], [34], [44], [45], [46], [47], [48], [49] have appeared, showing the huge potential of attention-based models.”
BackgroundInfluentialSelf-citationMultiscale vision transformers
Fan, H., Xiong, B., Mangalam, K., Li, Y., Yan, Z., Malik, J., & Feichtenhofer, C. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00675 · Cited by 1,407
“An emerging thread of work aims at applying transformers to vision tasks such as object detection [5], semantic segmentation [121, 105], 3D reconstruction [77], pose estimation [113], generative modeling [17], image retrieval [30], medical image segmentation [16,103,117], point clouds [45], video instance segmentation…”
BackgroundGuo, M.-H., Lu, C.-Z., Liu, Z.-N., Cheng, M., & Hu, S. (2023) · Computational Visual Media · doi:10.1007/s41095-023-0364-2 · Cited by 1,235
Self-citation
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
