

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
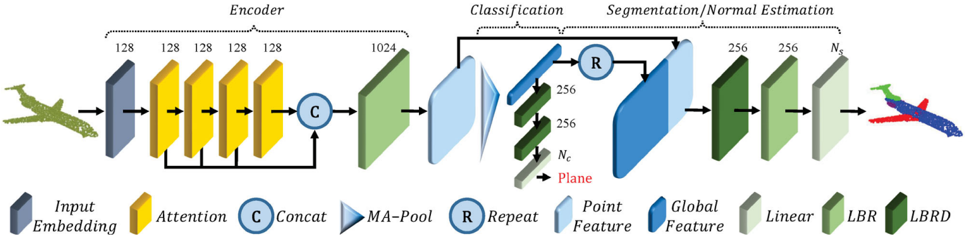
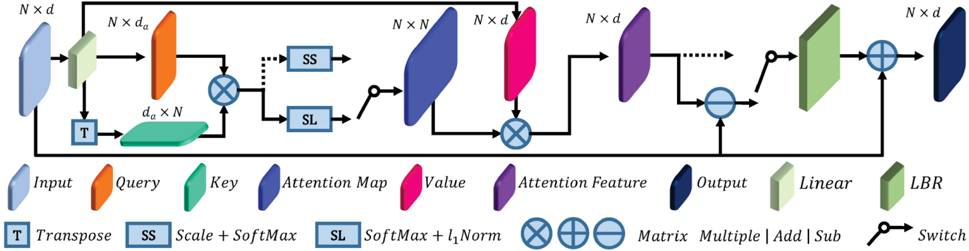
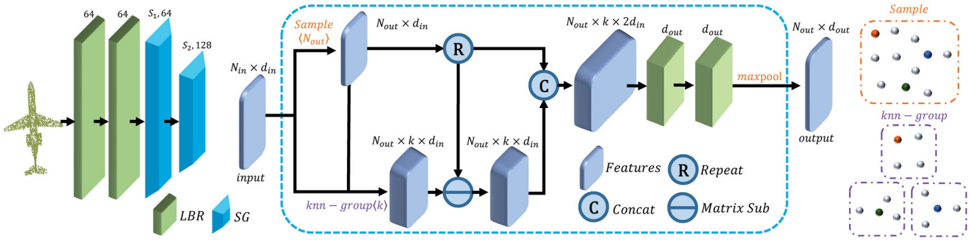
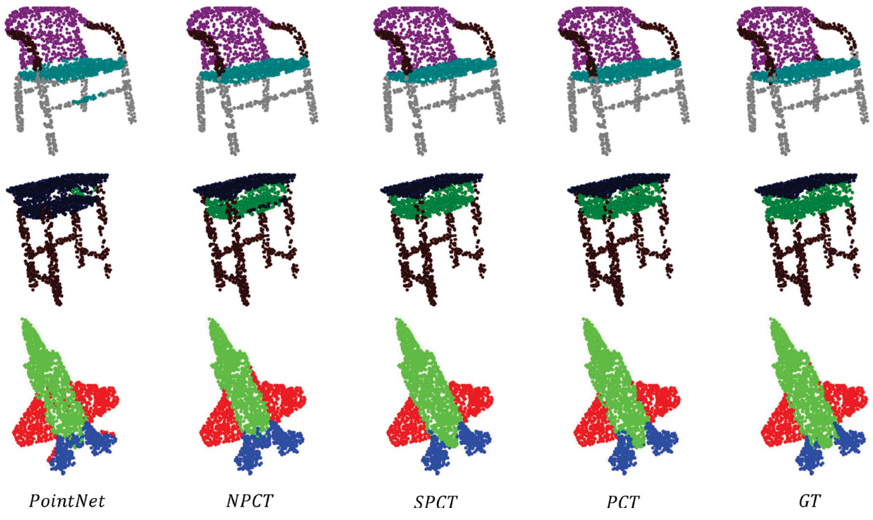
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Han (2023) · doi:10.1109/tpami.2022.3152247 · Cited by 4,682
Self-citationTransformers in Vision: A Survey
Khan, S., Naseer, M., Hayat, M., Zamir, S. W., Khan, F. S., & Shah, M. (2022) · ACM Computing Surveys · doi:10.1145/3505244 · Cited by 3,595
Attention mechanisms in computer vision: A survey
Guo, M.-H., Xu, T.-X., Liu, J.-J., Liu, Z.-N., Jiang, P.-T., Mu, T.-J., Zhang, S.-H., Martin, R. R., Cheng, M.-M., & Hu, S.-M. (2022) · Computational Visual Media · doi:10.1007/s41095-022-0271-y · Cited by 2,566
“Recently, various pure deep self-attention networks (visual transformers) [27], [34], [44], [45], [46], [47], [48], [49] have appeared, showing the huge potential of attention-based models.”
BackgroundInfluentialSelf-citationMultiscale vision transformers
Fan, H., Xiong, B., Mangalam, K., Li, Y., Yan, Z., Malik, J., & Feichtenhofer, C. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00675 · Cited by 1,407
“An emerging thread of work aims at applying transformers to vision tasks such as object detection [5], semantic segmentation [121, 105], 3D reconstruction [77], pose estimation [113], generative modeling [17], image retrieval [30], medical image segmentation [16,103,117], point clouds [45], video instance segmentation…”
BackgroundGuo, M.-H., Lu, C.-Z., Liu, Z.-N., Cheng, M., & Hu, S. (2023) · Computational Visual Media · doi:10.1007/s41095-023-0364-2 · Cited by 1,235
Self-citationMultimodal learning with transformers: A survey
Xu, P., Zhu, X., & Clifton, D. A. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3275156 · Cited by 1,072
Point-BERT: Pre-training 3D Point Cloud Transformers with Masked Point Modeling
Yu, X., Tang, L., Rao, Y., Huang, T., Zhou, J., & Lu, J. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01871 · Cited by 922
Point Transformer V3: Simpler, Faster, Stronger
Wu, X., Jiang, L., Wang, P., Liu, Z., Liu, X., Qiao, Y., Ouyang, W., He, T., & Zhao, H. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00463 · Cited by 863
Self-citationBeyond Self-Attention: External Attention Using Two Linear Layers for Visual Tasks
Guo, M.-H., Liu, Z.-N., Mu, T., & Hu, S. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2022.3211006 · Cited by 703
Self-citationOn the Integration of Self-Attention and Convolution
Pan, X., Ge, C., Lü, R., Song, S., Chen, G.-F., Huang, Z., & Huang, G. M. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00089 · Cited by 628
Masked Autoencoders for Point Cloud Self-supervised Learning
Pang, Y., Wang, W., Tay, F. E. H., Liu, W., Tian, Y., & Yuan, L. (2022) · Lecture Notes in Computer Science · doi:10.1007/978-3-031-20086-1_35 · Cited by 605
A Survey of Visual Transformers
Liu, Y., Zhang, Y., Wang, Y., Hou, F., Yuan, J. S., Tian, J., Zhang, Y. S., Shi, Z., Jianping Fan, B., & He, Z. (2023) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2022.3227717 · Cited by 652
Ding, Y., Jia, M., Miao, Q., & Cao, Y. (2022) · Mechanical Systems and Signal Processing · doi:10.1016/j.ymssp.2021.108616 · Cited by 559
PointCLIP: Point Cloud Understanding by CLIP
Zhang, R., Guo, Z., Zhang, W., Li, K., Miao, X., Cui, B., Qiao, Y., Gao, P., & Li, H. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00836 · Cited by 538
TransWeather: Transformer-based Restoration of Images Degraded by Adverse Weather Conditions
Valanarasu, J. M. J., Yasarla, R., & Patel, V. M. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00239 · Cited by 479
Perceiver: General Perception with Iterative Attention
Jaegle, A., Gimeno, F., Brock, A., Zisserman, A., Vinyals, O., & Carreira, J. (2021) · arXiv · doi:10.48550/arxiv.2103.03206 · Cited by 414
Rethinking and Improving Relative Position Encoding for Vision Transformer
Wu, K., Peng, H., Chen, M., Fu, J., & Chao, H. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00988 · Cited by 419
SnowflakeNet: Point Cloud Completion by Snowflake Point Deconvolution with Skip-Transformer
Peng, X. F., Wen, X., Liu, Y.-S., Cao, Y., Wan, P., Zheng, W., & Han, Z. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00545 · Cited by 363
FlowFormer: A Transformer Architecture for Optical Flow
Huang, Z., Shi, X., Zhang, C., Wang, Q., Cheung, K. C., Qin, H., Dai, J., & Li, H. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19790-1_40 · Cited by 373
Walk in the Cloud: Learning Curves for Point Clouds Shape Analysis
Xiang, T., Zhang, C., Song, Y., Yu, J., & Cai, W. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00095 · Cited by 340
Embracing Single Stride 3D Object Detector with Sparse Transformer
Fan, L., Pang, Z., Zhang, T., Wang, Y.-X., Zhao, H., Wang, F., Wang, N., & Zhang, Z. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00827 · Cited by 314
Learning Dynamic and Hierarchical Traffic Spatiotemporal Features With Transformer
Yan, H., Ma, X., & Pu, Z. (2021) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2021.3102983 · Cited by 302
Zhou, C., & Ling, Q. (2023) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2023.3336053 · Cited by 287
Improving 3D Object Detection with Channel-wise Transformer
Shenga, H., Cai, S., Liu, Y., Deng, B., Huang, J., Hua, X.-S., & Zhao, M.-J. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00274 · Cited by 305
Yao, S., Guan, R., Huang, X., Li, Z., Sha, X., Yue, Y., Lim, E. G., Seo, H., Man, K. L., Zhu, X., et al. (2023) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2023.3307157 · Cited by 312
FaceFormer: Speech-Driven 3D Facial Animation with Transformers
Fan, Y., Lin, Z., Saito, J., Wang, W., & Komura, T. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01821 · Cited by 295
ULIP: Learning a Unified Representation of Language, Images, and Point Clouds for 3D Understanding
Xue, L., Gao, M., Chen, X., Martín-Martín, R., Wu, J., Xiong, C., Xu, R., Niebles, J. C., & Savarese, S. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00120 · Cited by 336
Transformer-Based Visual Segmentation: A Survey
Li, X., Ding, H., Yuan, H., Zhang, W., Pang, J., Cheng, G., Chen, K., Liu, Z., & Loy, C. C. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3434373 · Cited by 305
Self-citationVoxel Set Transformer: A Set-to-Set Approach to 3D Object Detection from Point Clouds
He, C., Li, R., Li, S., & Zhang, L. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00823 · Cited by 257
Park, C., Jeong, Y., Cho, M., & Park, J. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01644 · Cited by 251
Deep learning-based 3D point cloud classification: A systematic survey and outlook
Zhang, H., Wang, C., Tian, S., Lu, B., Zhang, L., Ning, X., & Bai, X. P. (2023) · Displays · doi:10.1016/j.displa.2023.102456 · Cited by 221
Comprehensive Review of Deep Learning-Based 3D Point Cloud Completion Processing and Analysis
Fei, B., Yang, W., Chen, W., Li, Z., Li, Y., Ma, T., Hu, X., & Ma, L. (2022) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2022.3195555 · Cited by 219
Contrastive Boundary Learning for Point Cloud Segmentation
Tang, L., Zhan, Y., Chen, Z., Yu, B., & Tao, D. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00830 · Cited by 216
Adaptive Graph Convolution for Point Cloud Analysis
Zhou, H., Feng, Y., Fang, M., Wei, M., Qin, J., & Lü, T. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00492 · Cited by 202
Wu, T., Zhang, J., Fu, X. Y., Wang, Y., Ren, J., Pan, L., Wu, W., Yang, L., Wang, J., Qian, C., et al. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00084 · Cited by 246
Self-citationPRA-Net: Point Relation-Aware Network for 3D Point Cloud Analysis
Cheng, S., Chen, X., He, X., Liu, Z., & Bai, X. (2021) · IEEE Transactions on Image Processing · doi:10.1109/tip.2021.3072214 · Cited by 194
Self-citation3DShape2VecSet: A 3D Shape Representation for Neural Fields and Generative Diffusion Models
Zhang, B., Tang, J., Nießner, M., & Wonka, P. (2023) · ACM Transactions on Graphics · doi:10.1145/3592442 · Cited by 264
Liu, Z., Wang, Y., Tu, Z., Xiao, Y., & Tang, B. (2021) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3474085.3475601 · Cited by 176
Self-citationSPViT: Enabling Faster Vision Transformers via Latency-Aware Soft Token Pruning
Kong, Z., Dong, P., Ma, X., Meng, X., Niu, W., Sun, M., Shen, X., Yuan, G., Ren, B., Tang, H., et al. (2022) · Lecture Notes in Computer Science · doi:10.1007/978-3-031-20083-0_37 · Cited by 169
AdaPoinTr: Diverse Point Cloud Completion With Adaptive Geometry-Aware Transformers
Yu, X., Rao, Y., Wang, Z., Lu, J., & Zhou, J. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3309253 · Cited by 202
Chen, C., Wu, Y., Dai, Q., Zhou, H.-Y., Xu, M., Yang, S., Han, X., & Yu, Y. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3445463 · Cited by 198
EPNet++: Cascade Bi-Directional Fusion for Multi-Modal 3D Object Detection
Liu, Z., Huang, T., Li, B., Chen, X., Wang, X., & Bai, X. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2022.3228806 · Cited by 168
Self-citationMasked Discrimination for Self-supervised Learning on Point Clouds
Liu, H., Cai, M., & Lee, Y. J. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20086-1_38 · Cited by 175
A Survey of Techniques for Optimizing Transformer Inference
Chitty-Venkata, K. T., Mittal, S., Emani, M., Vishwanath, V., & Somani, A. K. (2023) · Journal of Systems Architecture · doi:10.1016/j.sysarc.2023.102990 · Cited by 154
M3DETR: Multi-representation, Multi-scale, Mutual-relation 3D Object Detection with Transformers
Guan, T., Wang, J., Lan, S., Chandra, R., Wu, Z., Davis, L. S., & Manocha, D. (2022) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv51458.2022.00235 · Cited by 157
Pyramid Point Cloud Transformer for Large-Scale Place Recognition
Hui, L., Yang, H., Cheng, M., Xie, J., & Yang, J. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00604 · Cited by 154
CAT-Det: Contrastively Augmented Transformer for Multimodal 3D Object Detection
Zhang, Y., Chen, J., & Huang, D. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00098 · Cited by 151
Swin3D: A Pretrained Transformer Backbone for 3D Indoor Scene Understanding
Yang, Y., Guo, Y., Xiong, J.-Y., Liu, Y., Pan, H., Wang, P., Tong, X., & Guo, B. (2025) · Computational Visual Media · doi:10.26599/cvm.2025.9450383 · Cited by 233
Transformers in computational visual media: A survey
Xu, Y., Wei, H., Lin, M., Deng, Y., Sheng, K., Zhang, M., Tang, F., Dong, W., Huang, F., & Xu, C. (2021) · Computational Visual Media · doi:10.1007/s41095-021-0247-3 · Cited by 144
Efficient 3D Semantic Segmentation with Superpoint Transformer
Robert, D., Raguet, H., & Landrieu, L. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01577 · Cited by 137
Self-Positioning Point-Based Transformer for Point Cloud Understanding
Park, J., Lee, S., Kim, S., Xiong, Y., & Kim, H. J. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02089 · Cited by 139
Subdivision-based Mesh Convolution Networks
Hu, S., Liu, Z.-N., Guo, M.-H., Cai, J.-X., Huang, J., Mu, T., & Martin, R. R. (2022) · ACM Transactions on Graphics · doi:10.1145/3506694 · Cited by 148
Self-citationLearning 3D Representations from 2D Pre-Trained Models via Image-to-Point Masked Autoencoders
Zhang, R., Wang, L., Qiao, Y., Gao, P., & Li, H. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02085 · Cited by 156
SAT-GCN: Self-attention graph convolutional network-based 3D object detection for autonomous driving
Wang, L., Song, Z., Zhang, X., Wang, C., Zhang, G., Zhu, L., Li, J., & Liu, H. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2022.110080 · Cited by 132
PTTR: Relational 3D Point Cloud Object Tracking with Transformer
Zhou, C., Luo, Z., Luo, Y., Liu, T., Pan, L., Cai, Z., Zhao, H., & Lu, S. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00834 · Cited by 130
FlowFormer++: Masked Cost Volume Autoencoding for Pretraining Optical Flow Estimation
Shi, X., Huang, Z., Li, D., Zhang, M., Cheung, K. C., See, S. C. W., Qin, H., Dai, J., & Li, H. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00160 · Cited by 137
Starting from Non-Parametric Networks for 3D Point Cloud Analysis
Zhang, R., Wang, L., Wang, Y., Gao, P., Li, H., & Shi, J. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00517 · Cited by 193
FlatFormer: Flattened Window Attention for Efficient Point Cloud Transformer
Liu, Z., Yang, X., Tang, H., Shang, Y., & Han, S. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00122 · Cited by 135
Self-citation3DCTN: 3D Convolution-Transformer Network for Point Cloud Classification
Lu, D., Xie, Q., Gao, K., Xu, L., & Li, J. (2022) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2022.3198836 · Cited by 129
PVT: Point‐voxel transformer for point cloud learning
Zhang, C., Wan, H., Shen, X., & Wu, Z. (2022) · International Journal of Intelligent Systems · doi:10.1002/int.23073 · Cited by 133
Learning Discriminative Features by Covering Local Geometric Space for Point Cloud Analysis
Wang, C., Ning, X., Sun, L., Zhang, L., Li, W., & Bai, X. P. (2022) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2022.3170493 · Cited by 121
Point Cloud Classification Using Content-Based Transformer via Clustering in Feature Space
Liu, Y., Wang, B., Lv, Y.-S., Li, L., & Wang, F. (2023) · IEEE/CAA Journal of Automatica Sinica · doi:10.1109/jas.2023.123432 · Cited by 113
PointCutMix: Regularization strategy for point cloud classification
Zhang, J., Chen, L., Ouyang, B., Liu, B., Zhu, J., Chen, Y., Meng, Y., & Wu, D. (2022) · Neurocomputing · doi:10.1016/j.neucom.2022.07.049 · Cited by 135
Neural Architecture Search for Transformers: A Survey
Chitty-Venkata, K. T., Emani, M., Vishwanath, V., & Somani, A. K. (2022) · IEEE Access · doi:10.1109/access.2022.3212767 · Cited by 118
Attention-Based Point Cloud Edge Sampling
Wu, C., Zheng, J., Pfrommer, J., & Beyerer, J. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00516 · Cited by 116
Dual Transformer for Point Cloud Analysis
Han, X.-F., Jin, Y. J., Cheng, H.-X., & Xiao, G. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3198318 · Cited by 115
Query2Label: A Simple Transformer Way to Multi-Label ClassificationPreprint
Liu, S., Zhang, L., Yang, X., Su, H., & Zhu, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.10834 · Cited by 242
PointMixer: MLP-Mixer for Point Cloud Understanding
Choe, J., Park, C., Rameau, F., Park, J., & Kweon, I. S. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19812-0_36 · Cited by 111
MVImgNet: A Large-scale Dataset of Multi-view Images
Yu, X., Xu, M., Zhang, Y., Liu, H., Ye, C., Wu, Y., Yan, Z., Zhu, C., Xiong, Z., Liang, T., et al. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00883 · Cited by 139
PointVector: A Vector Representation In Point Cloud Analysis
Deng, X., Zhang, W., Ding, Q. W., & Zhang, X. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00912 · Cited by 109
ProxyFormer: Proxy Alignment Assisted Point Cloud Completion with Missing Part Sensitive Transformer
Li, S., Gao, P., Tan, X., & Wei, M. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00913 · Cited by 106
Localization Distillation for Object Detection
Zheng, Z., Ye, R., Hou, Q., Ren, D., Wang, P., Zuo, W., & Cheng, M. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3248583 · Cited by 110
Snowflake Point Deconvolution for Point Cloud Completion and Generation with Skip-Transformer
Peng, X., Wen, X., Liu, Y.-S., Cao, Y., Wan, P., Zheng, W., & Han, Z. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2022.3217161 · Cited by 105
Are we ready for a new paradigm shift? A survey on visual deep MLP
Liu, R., Li, Y., Tao, L., Liang, D., & Zheng, H.-T. (2022) · Patterns · doi:10.1016/j.patter.2022.100520 · Cited by 110
VISTA: Boosting 3D Object Detection via Dual Cross-VIew SpaTial Attention
Deng, S., Liang, Z., Sun, L., & Jia, K. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00826 · Cited by 98
Sarker, S., Sarker, P., Stone, G., Gorman, R., Tavakkoli, A., Bebis, G. N., & Sattarvand, J. (2024) · Machine Vision and Applications · doi:10.1007/s00138-024-01543-1 · Cited by 101
Zhu, S., Guendel, R. G., Yarovoy, A. G., & Fioranelli, F. (2022) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2022.3189746 · Cited by 102
Tian, Y., Li, X., Zhang, H., Zhao, C., Li, B., Wang, X., Wang, X., & Wang, F. (2023) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2023.3307012 · Cited by 102
AGConv: Adaptive Graph Convolution on 3D Point Clouds
Wei, M., Wei, Z., Zhou, H., Hu, F., Si, H., Chen, Z., Zhu, Z., Qiu, J., Yan, X., Guo, Y., et al. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3238516 · Cited by 94
PU-Transformer: Point Cloud Upsampling Transformer
Qiu, S., Anwar, S., & Barnes, N. M. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26319-4_20 · Cited by 96
Wang, S., Mei, L., Liu, R., Jiang, W., Yin, Z., Deng, X., & He, T. (2024) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2024.3398004 · Cited by 112
SVT-Net: Super Light-Weight Sparse Voxel Transformer for Large Scale Place Recognition
Fan, Z., Song, Z., Liu, H., Lu, Z., He, J., & Du, X. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i1.19934 · Cited by 99
PatchFormer: An Efficient Point Transformer with Patch Attention
Zhang, C., Wan, H., Shen, X., & Wu, Z. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01150 · Cited by 104
LCPFormer: Towards Effective 3D Point Cloud Analysis via Local Context Propagation in Transformers
Huang, Z., Zhao, Z., Li, B., & Han, J. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3247506 · Cited by 97
DropKey for Vision Transformer
Li, B., Hu, Y., Nie, X., Han, C., Jiang, X., Guo, T., & Liu, L. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02174 · Cited by 106
PTT: Point-Track-Transformer Module for 3D Single Object Tracking in Point Clouds
Shan, J., Zhou, S., Fang, Z., & Cui, Y. (2021) · IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros51168.2021.9636821 · Cited by 98
Pei, X., Zheng, X., & Wu, J. (2021) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2021.3119137 · Cited by 96
PointAttN: You Only Need Attention for Point Cloud Completion
Wang, J., Cui, Y., Guo, D., Li, J., Liu, Q., & Shen, C. (2024) · AAAI Publications (The Association for the Advancement of Artificial Intelligence (AAAI)) · doi:10.1609/aaai.v38i6.28356 · Cited by 92
Mamba3D: Enhancing Local Features for 3D Point Cloud Analysis via State Space Model
Han, X., Tang, Y., Wang, Z., & Li, X. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3681173 · Cited by 91
A Novel Local–Global Graph Convolutional Method for Point Cloud Semantic Segmentation
Du, Z., Ye, H., & Cao, F. (2022) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2022.3155282 · Cited by 91
OcTr: Octree-Based Transformer for 3D Object Detection
Zhou, C., Zhang, Y., Chen, J., & Huang, D. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00500 · Cited by 88
CASSPR: Cross Attention Single Scan Place Recognition
Xia, Y., Gladkova, M., Wang, R., Li, Q., Stilla, U., Henriques, J. F., & Cremers, D. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00777 · Cited by 87
Liang, Z., Zhao, K., Liang, G., Li, S., Wu, Y., & Zhou, Y. (2023) · Knowledge-Based Systems · doi:10.1016/j.knosys.2023.110987 · Cited by 87
DA-RoadNet: A Dual-Attention Network for Road Extraction From High Resolution Satellite Imagery
Wan, J., Xie, Z., Xu, Y., Chen, S., & Qiu, Q. (2021) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2021.3083055 · Cited by 85
A New Pest Detection Method Based on Improved YOLOv5m
Dai, M., Dorjoy, M. M. H., Miao, H., & Zhang, S. (2023) · Insects · doi:10.3390/insects14010054 · Cited by 85
Vision-Language-Action Models for Robotics: A Review Towards Real-World Applications
Kawaharazuka, K., Oh, J., Yamada, J., Posner, I., & Zhu, Y. (2025) · IEEE Access · doi:10.1109/access.2025.3609980 · Cited by 134
Self-Contrastive Learning with Hard Negative Sampling for Self-supervised Point Cloud Learning
Du, B., Gao, X., Hu, W., & Li, X. (2021) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3474085.3475458 · Cited by 82
Emerging trends in autonomous vehicle perception: Multimodal fusion for 3D object detection
Alaba, S. Y., Gurbuz, A. C., & Ball, J. E. (2024) · World Electric Vehicle Journal · doi:10.3390/wevj15010020 · Cited by 82
Liu, J., Xu, L., & Chen, N. (2022) · Journal of Hydrology · doi:10.1016/j.jhydrol.2022.127748 · Cited by 79
A review of non-rigid transformations and learning-based 3D point cloud registration methods
Monji-Azad, S., Hesser, J., & Löw, N. (2023) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2022.12.023 · Cited by 85
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
