

The DOI matches its Crossref record; 68 of the 70 references it cites were found in a registry or an index; none of the 44 sources its claims cite is checked for support yet.
ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts
Open accessAbstract
ASReview LAB v.2 introduces an advancement in AI-assisted systematic reviewing by enabling collaborative screening with multiple experts ("a crowd of oracles") using a shared AI model. The platform supports multiple AI agents within the same project, allowing users to switch between fast general-purpose models and domain-specific, semantic, or multilingual transformer models. Leveraging the SYNERGY benchmark dataset, performance has improved significantly, showing a 24.1% reduction in loss compared to version 1 through model improvements and hyperparameter tuning. ASReview LAB v.2 follows user-centric design principles and offers reproducible, transparent workflows. It logs key configuration and annotation data while balancing full model traceability with efficient storage. Future developments include automated model switching based on performance metrics, noise-robust learning, and ensemble-based decision-making.
Overview
CoChat Summary
Written by AI from the paper’s full text.
TL;DR
ASReview LAB v.2 is an open-source Python platform for AI-assisted systematic review screening that adds multiagent model switching and collaborative crowd screening with a shared active-learning model. Using the SYNERGY benchmark, its optimized default model reduced mean loss by 24.1% versus v.1 and retrieved relevant PTSD records after screening far fewer papers in simulation.
Key findings
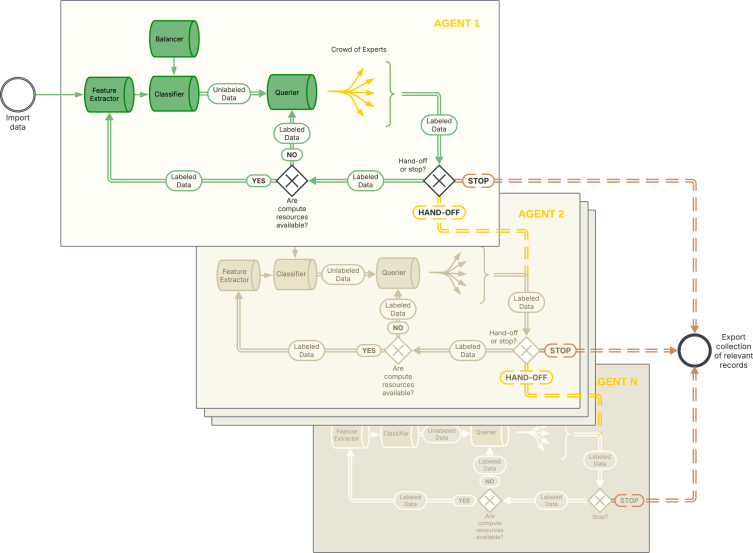
- ASReview LAB v.2 introduces a multiagent, multiexpert system: multiple AI agents can hand off sequentially within one project, and a crowd of experts can jointly label records from a shared ranked queue.
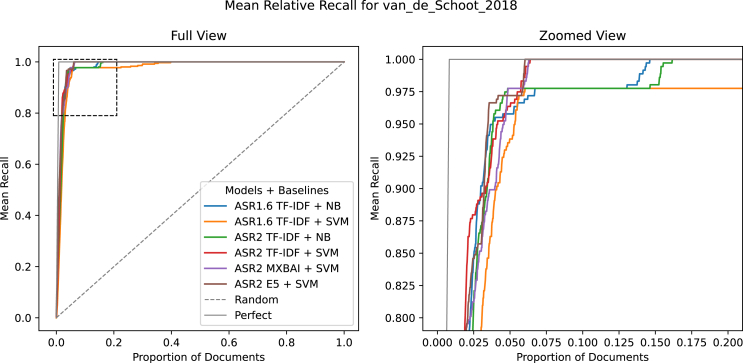
- Hyperparameter optimization on 24 SYNERGY datasets and 10 prior combinations found the v.2 default (TF-IDF + SVM) had mean validation loss 0.0623 (SD 0.0040), compared with the v.1 default (TF-IDF + naive Bayes) at 0.0821 (SD 0.0081), a 24.1% reduction. MXBAI (+SVM) had loss 0.0610 (SD 0.0046), and E5 (+SVM) had 0.0640 (SD 0.0043).
- In a PTSD systematic review example with 4,455 papers and 38 relevant records, the v.1 default would have found all relevant records after screening 542.1 papers (±189.47); the v.2 Ultra model required 270.6 papers (±11.48), ELAS-heavy required 266.8 (±25.84), and ELAS-lang required 269.9 (±2.88).
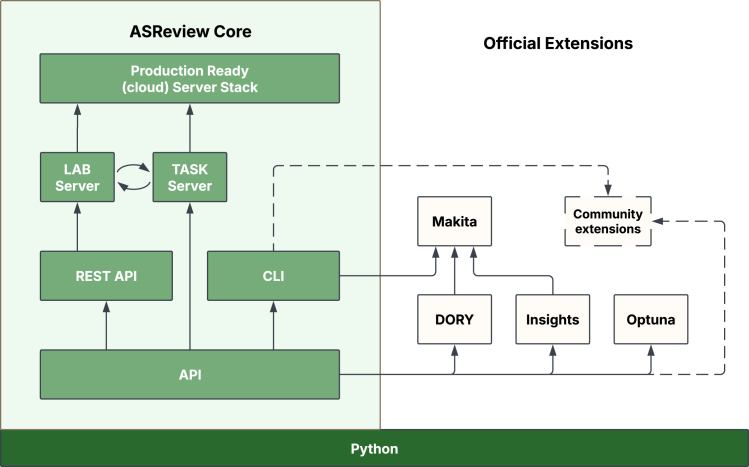
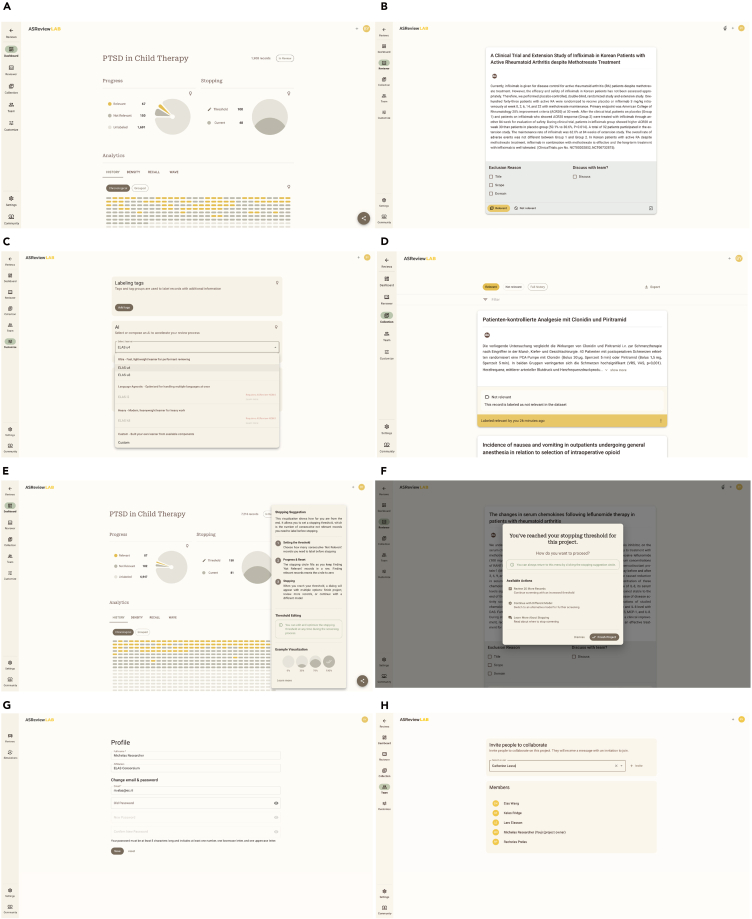
- The platform logs project setup, expert actions, and training-cycle information to balance reproducibility and storage, while supporting simulation, model switching, stopping suggestions, and extensions such as Insights, Makita, and Dory.
Methods
- Design: software and infrastructure paper describing ASReview LAB v.2’s multiagent active-learning architecture, crowd-screening workflow, simulation projects, data storage, and extension ecosystem.
- Data and analysis: hyperparameters were optimized on 24 labeled systematic reviews from the SYNERGY dataset, with 10 prior combinations per dataset sampled using a geometric distribution (p = 0.5) for test and validation sets; Optuna minimized mean loss across datasets and prior combinations.
- The PTSD review example used a fully labeled dataset of 4,455 papers with 38 relevant records to compare recall and screening effort across v.1 and v.2 model configurations.
Limitations
- Stated: automatic hand-off based on performance metrics is planned but not yet implemented; future work includes simultaneous multiagent ensembles, noise-robust learning, and data-driven stopping estimators. The paper also notes that v.2 simulations assume all labels in fully labeled datasets are accurate, and that non-text data simulation is currently supported only via CLI and Python API, not the web app.
- Stated: crowd screening assigns each record to only one expert, so no interrater reliability can be computed; the paper says this is not the goal of the crowd-screening option.
- Evident from the text: the reported performance evidence comes from simulations on already-labeled datasets, not from a prospective real-world evaluation of crowd screening or multiagent hand-off in practice.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
114 Own result · 21 Own interpretation · 13 Check pending · 13 No basis given · 9 Not checked yet · 3 Sources not found · 2 No full text of the sources · 2 Own method
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Therefore, ASReview v.2 offers the possibility of using a crowd of experts to label large amounts of textual data while jointly training AI models.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > Introduction
hedgedstates a possible cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The results show that the mean loss for each v.2 model is lower than that of any v.1 model.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > The multiagent, multiexpert system > Default models and their hyperparameters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“With the further optimized Ultra model in v.2, only 270.6 papers (±11.48) would need to be screened.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > The multiagent, multiexpert system > Default models and their hyperparameters
hedgedstates a causeSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“To address these concerns (see also Lombaers et al.23), ASReview maintains a project file that captures essential setup information, including the learner’s hyperparameters of the AI agent, the feature matrix or matrices, and any initially labeled records.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > The multiagent, multiexpert system > Data storage
What the sources say
- Check pendingcites Lombaers et al. [23] Lombaers, 2024, Reproducibility and data storage for active learning-aided systematic reviews, Appl. Sci. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For model reproducibility, recording only the type of agent (e.g., the classifier plus its features), the number (or specific record IDs) of labeled records used in each training cycle used to train that classifier typically suffices to re-create the model’s predictions.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > The multiagent, multiexpert system > Data storage
hedgedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 143
- It may state two separate claims as one. 55
Create a free account to see these claims.
Create a free account to see these assumptions.
23 more claims
Create a free account to see all 177 claims and to verify the 30 references still open.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > The multiagent, multiexpert system > Implementation
“a fully labeled dataset is assumed, K=K⁺∧K⁻.”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > Simulation projects
“The simulation requires a fully labeled dataset K with both positive K⁺ and negative K⁻ labels: K=K⁺∪K⁻.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > Introduction
“| Dashboard | X | V | V |”
§ ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts > Introduction
“| Dashboard | X | X | V |”
Citations
Cites
Scikit-learn: Machine Learning in Python
Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Müller, A., Nothman, J., Louppe, G., et al. (2012) · arXiv · doi:10.48550/arxiv.1201.0490 · Cited by 71,016
Rayyan-a web and mobile app for systematic reviews.
Ouzzani, M., Hammady, H., Fedorowicz, Z., & Elmagarmid, A. (2016) · Systematic Reviews · doi:10.1186/s13643-016-0384-4 · Cited by 26,092
Page, M. J., Moher, D., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., et al. (2021) · BMJ · doi:10.1136/bmj.n160 · Cited by 13,262 · cited 1×
“The multiexpert approach blends the power of crowd screening 40,41 with the Screenathon approach, 42 where experts work together in large consortia.”
Larian Studios Dev Team (2024) · doi:10.1145/3292500.3330701 · Cited by 8,618
Scikit-learn: Machine Learning in Python
(2011) · Journal of Machine Learning Research · doi:10.5555/1953048.2078195 · Cited by 8,539
Estimating the Population Size for Capture-Recapture Data with Unequal Catchability
Chao, A. (1987) · Biometrics · doi:10.2307/2531532 · Cited by 2,459
A Comprehensive Survey of Multiagent Reinforcement Learning
Busoniu, L., Babuska, R., & De Schutter, B. (2008) · IEEE Transactions on Systems, Man, and Cybernetics, Part C (Applications and Reviews) · doi:10.1109/tsmcc.2007.913919 · Cited by 2,235
Multiagent systems: algorithmic, game-theoretic, and logical foundations
(2009) · Choice Reviews Online · doi:10.5860/choice.46-5662 · Cited by 1,756
An open source machine learning framework for efficient and transparent systematic reviews
van de Schoot, R., de Bruin, J., Schram, R., Zahedi, P., de Boer, J., Weijdema, F., Kramer, B., Huijts, M., Hoogerwerf, M., Ferdinands, G., et al. (2021) · Nature Machine Intelligence · doi:10.1038/s42256-020-00287-7 · Cited by 1,157
Multiagent Systems: Algorithmic, Game-Theoretic, and Logical Foundations
Shoham, Y., & Leyton-Brown, K. (2008) · doi:10.1017/cbo9780511811654 · Cited by 995
Research works printed but not linked: 3
- Bron, M.P., Greijn, B., Coimbra, B.M., Schoot, R.v.d., and Bagheri, A. (2024). Combining Large Language Model Classifications and Active Learning for Improved Technology-Assisted Review. 77-95. ceur-ws.org/Vol-3770/paper8.pdf.
- Li, 2023, AnglE-optimized Text Embeddings, arXiv
- De Bruin, J., Ma, Y., Ferdinands, G., Teijema, J., and Van de Schoot, R. (2023). SYNERGY - Open Machine Learning Dataset on Study Selection in Systematic Reviews. V1 ed. DataverseNL. https://doi.org/10.34894/HE6NA. · DOI
Cited by
Bourke, M., Maddren, C. I., Sippel, F., & Thomas, G. (2026) · Archives of Pediatrics and Adolescent Medicine · doi:10.1001/jamapediatrics.2025.6490 · Cited by 22
One anastomosis gastric bypass (OAGB): a scoping review
Ortíz-Gómez, J. E., González-Barajas, A. I., Guevara-Díaz, J. A., Mancilla-Galindo, J., Kammar‐García, A., & Gutiérrez, M. A. G. (2025) · BMC Surgery · doi:10.1186/s12893-025-03215-x · Cited by 9
Verdonschot, R. G., Dilles, T., Cahir, C., Graef, M. D., Holis, R. V., Frydenlund, J., Denig, P., Grimes, T., Karapinar‐Çarkit, F., & Schor, M. (2026) · Systematic Reviews · doi:10.1186/s13643-026-03185-y · Cited by 5
Does advancement in marker-less pose-estimation mean more quality research? A systematic review
Bhola, S., Kim, H., Kim, H. S., Gu, B., & Yoo, J. (2025) · Frontiers in Behavioral Neuroscience · doi:10.3389/fnbeh.2025.1663089 · Cited by 4
AI Agents for Organizational Knowledge Retrieval and Sharing: A Systematic Literature Review
Anjelia, S. R., Sensuse, D. I., & Lusa, S. (2025) · International Journal of Advances in Data and Information Systems · doi:10.59395/ijadis.v6i3.1462 · Cited by 4
Metadata
- Authors
- de Bruin, J., Lombaers, P., Kaandorp, C., Teijema, J., van der Kuil, T., Yazan, B., Dong, A., & van de Schoot, R.
- Affiliations
- Utrecht University (NL)
- Corresponding author
- van de Schoot, Rens
- Venue
- Patterns
- Publisher
- Elsevier BV
- Published
- 2025-07
- Volume
- 6
- Issue
- 7
- Pages
- 101318
- ISSN
- 2666-3899 (ISSN-L)
- PMC
- PMC12416088
- OpenAlex
- W4412002745
- Cited by
- 27
- References
- 70
- Citations by year
- 2026: 22 · 2025: 5
- FWCI
- 5.63
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Patterns (publishedVersion, cc-by)
- SSRN Electronic Journal (submittedVersion)
- PubMed (publishedVersion)
- PubMed Central (publishedVersion, cc-by)
- Utrecht University Repository (Utrecht University) (submittedVersion, other-oa)
- Funders
- Innovative Health Initiative
- Nederlandse Organisatie voor Wetenschappelijk Onderzoek (101132847, 406.22)
- Topics
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Social Sciences › General Social Sciences › Computational and Text Analysis Methods
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Keywords
- crowdsourcing, transformer models, multilingual models, model traceability, annotation workflow, ensemble decision making
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-12, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-12 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts. https://app.cochat.ai/papers/10.1016/j.patter.2025.101318
- The paper
- de Bruin, J., Lombaers, P., Kaandorp, C., Teijema, J., van der Kuil, T., Yazan, B., Dong, A., & van de Schoot, R. (2025). ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts. Patterns. https://doi.org/10.1016/j.patter.2025.101318
