

The DOI matches its Crossref record; 21 of the 23 references it cites were found in a registry or an index, and 2 are not checked yet.
Benchmark evaluation of DeepSeek large language models in clinical decision-making
Open accessAbstract
Large language models (LLMs) are increasingly transforming medical applications. However, proprietary models such as GPT-4o face significant barriers to clinical adoption because they cannot be deployed on site within healthcare institutions, making them noncompliant with stringent privacy regulations. Recent advancements in open-source LLMs such as DeepSeek models offer a promising alternative because they allow efficient fine-tuning on local data in hospitals with advanced information technology infrastructure. Here, to demonstrate the clinical utility of DeepSeek-V3 and DeepSeek-R1, we benchmarked their performance on clinical decision support tasks against proprietary LLMs, including GPT-4o and Gemini-2.0 Flash Thinking Experimental. Using 125 patient cases with sufficient statistical power, covering a broad range of frequent and rare diseases, we found that DeepSeek models perform equally well and in some cases better than proprietary LLMs. Our study demonstrates that open-source LLMs can provide a scalable pathway for secure model training enabling real-world medical applications in accordance with data privacy and healthcare regulations.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
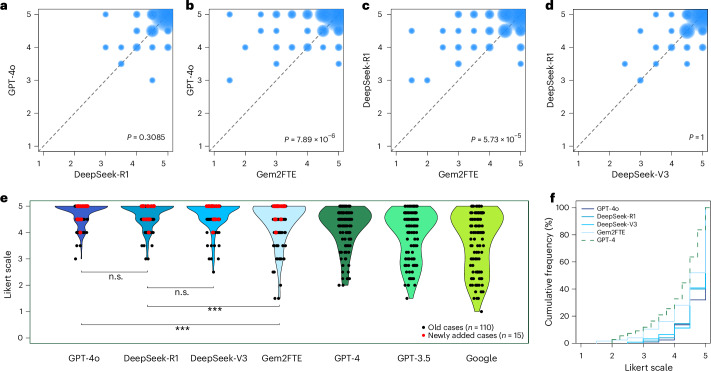
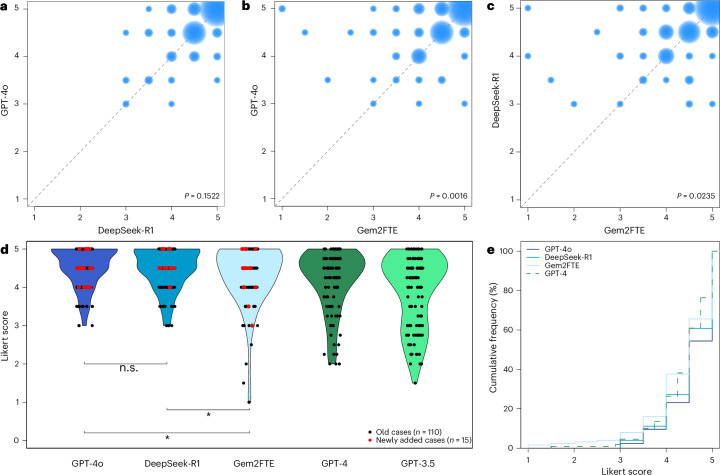
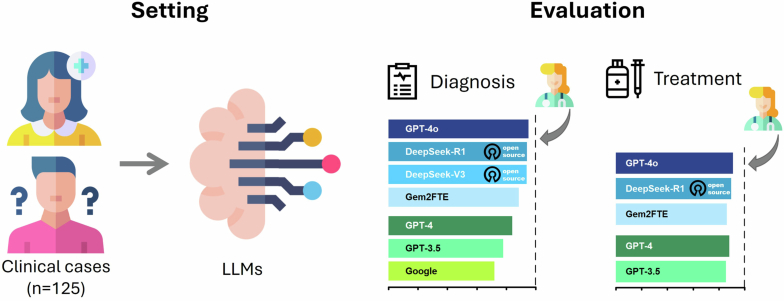
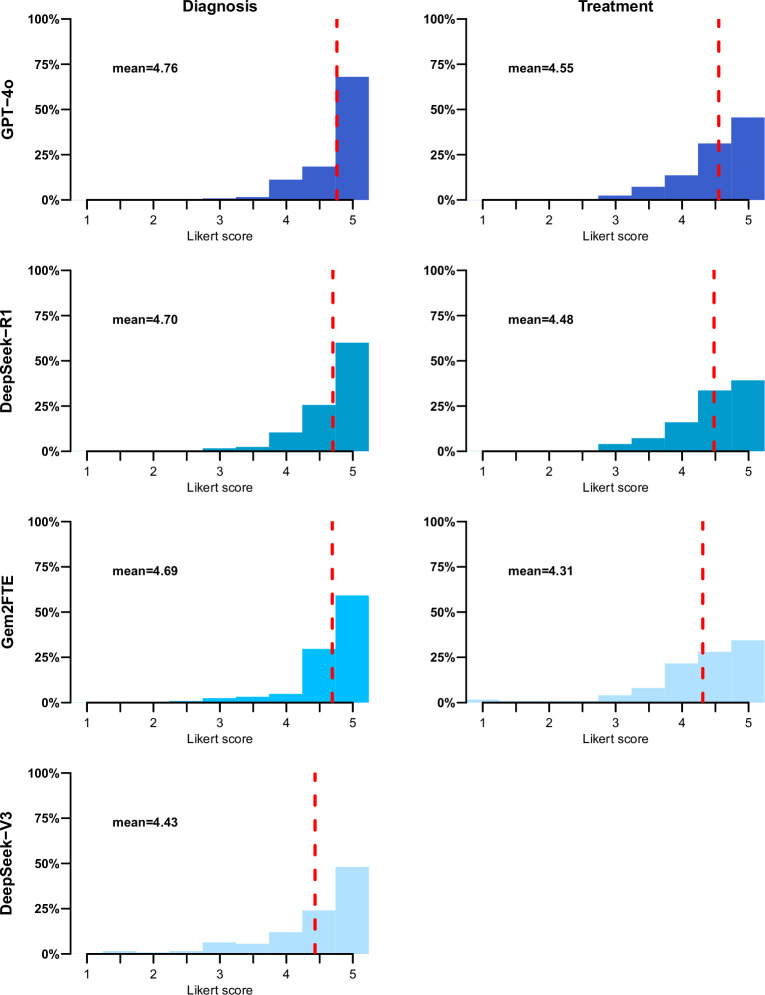
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, these frameworks typically focus on narrow clinical scenarios (1–28 datasets), rely on limited data sources or synthetic data, and assess primarily accuracy without comprehensive taxonomy validation or deployment considerations.”
From Holistic evaluation of large language models for medical tasks with MedHELM (2026) · cites this paper as [22]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
On a Test of Whether one of Two Random Variables is Stochastically Larger than the Other
Mann, H. B., & Whitney, D. R. (1947) · The Annals of Mathematical Statistics · doi:10.1214/aoms/1177730491 · Cited by 14,320
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2020) · Applied Sciences · doi:10.48550/arxiv.2009.13081 · Cited by 2,339
Artificial hallucinations in ChatGPT: implications in scientific writing
Alkaissi, H., & McFarlane, S. I. (2023) · Cureus · doi:10.7759/cureus.35179 · Cited by 1,540
Evaluation and mitigation of the limitations of large language models in clinical decision-making
Hager, P., Jungmann, F., Holland, R., Bhagat, K., Hubrecht, I., Knauer, M., Vielhauer, J., Makowski, M., Braren, R., Kaissis, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03097-1 · Cited by 798
DescTools: Tools for Descriptive Statistics
Signorell, A. (2014) · doi:10.32614/cran.package.desctools · Cited by 723
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2021) · Applied Sciences · doi:10.3390/app11146421 · Cited by 718
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
DeepSeek-AI, Guo, D., Yang, D., Zhang, H., Song, J., Wang, P., Zhu, Q., Xu, R., Zhang, R., Ma, S., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12948 · Cited by 538
Medical large language models are vulnerable to data-poisoning attacks
Alber, D. A., Yang, Z., Alyakin, A., Yang, E., Rai, S., Valliani, A. A., Zhang, J., Rosenbaum, G. R., Amend-Thomas, A. K., Kurland, D. B., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03445-1 · Cited by 242 · cited 1×
“Concerns regarding data privacy, algorithmic bias and the potential for generating inaccurate or misleading information remain paramount 8–10 .”
Systematic analysis of ChatGPT, Google search and Llama 2 for clinical decision support tasks
Sandmann, S., Riepenhausen, S., Plagwitz, L., & Varghese, J. (2024) · Nature Communications · doi:10.1038/s41467-024-46411-8 · Cited by 228
Self-citationGuidelines for clinical guidelines
Jackson, R., & Feder, G. S. (1998) · BMJ · doi:10.1136/bmj.317.7156.427 · Cited by 206
Research works printed but not linked: 1
- Bonferroni, C. E. Teoria statistica delle classi e calcolo delle probabilita. Pubblicazioni del R. Istituto Super. di Sci. Economiche e Commericiali di Firenze 8, 3–62 (1936).
Cited by
Sorted by citations
Quantifying the reasoning abilities of LLMs on clinical cases
Qiu, P., Wu, C., Liu, S., Fan, Y., Zhao, W., Chen, Z., Gu, H., Peng, C., Zhang, Y., Wang, Y., et al. (2025) · Nature Communications · doi:10.1038/s41467-025-64769-1 · Cited by 53
Holistic evaluation of large language models for medical tasks with MedHELM
Bedi, S., Cui, H., Fuentes, M., Unell, A., Wornow, M., Banda, J. M., Kotecha, N., Keyes, T., Mai, Y., Oez, M., et al. (2026) · Nature Medicine · doi:10.1038/s41591-025-04151-2 · Cited by 59
A large language model improves clinicians’ diagnostic performance in complex critical illness cases
Wu, X. C., Huang, Y., & He, Q. (2025) · Critical Care · doi:10.1186/s13054-025-05468-7 · Cited by 51
Chen, H., Zeng, W., Chen, C., Cai, L., Wang, F., Shi, Y., Wang, L., Zhang, W., Li, Y., Yan, H., et al. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107848 · Cited by 32
Large language models in global health
Ong, J. C. L., Ning, Y., Yang, R., Bitterman, D. S., Liu, X., Tham, Y. C., Collins, P. G. S., Jiménez, M., Mateen, B. A., Amissah-Arthur, K. N., et al. (2026) · Nature Health · doi:10.1038/s44360-025-00024-7 · Cited by 16
Metadata
- Authors
- Sandmann, S., Hegselmann, S., Fujarski, M., Bickmann, L., Wild, B., Eils, R., & Varghese, J.
- Affiliations
- University of Münster (DE)
- Berlin Institute of Health at Charité - Universitätsmedizin Berlin (DE)
- Shanghai Medical College of Fudan University (CN)
- Otto-von-Guericke-Universität Magdeburg (DE)
- Corresponding author
- Eils, Roland
- Venue
- Nature Medicine
- Published
- 2025-04-23
- Volume
- 31
- Issue
- 8
- Pages
- 2546-2549
- ISSN
- 1078-8956 (ISSN-L)
- 1546-170X
- PMC
- PMC12353792
- OpenAlex
- W4409695426
- Cited by
- 233
- References
- 20
- Citations by year
- 2026: 171 · 2025: 62
- FWCI
- 55.69
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature Medicine (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- Funders
- Deutsche Forschungsgemeinschaft (SFB 1470)
- National Natural Science Foundation of China (W2441025)
- Bundesministerium für Bildung und Forschung (01KX2121)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- DeepSeek, open-source large language models, clinical decision support, benchmarking, GPT-4o, Gemini, DeepSeek-V3, DeepSeek-R1, data privacy, rare diseases, clinical adoption
- MeSH terms
- Clinical Decision-Making, Large Language Models, Humans, Benchmarking, Decision Support Systems, Clinical
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
