

The DOI matches its Crossref record; 21 of the 23 references it cites were found in a registry or an index, and 2 are not checked yet.
Benchmark evaluation of DeepSeek large language models in clinical decision-making
Open accessAbstract
Large language models (LLMs) are increasingly transforming medical applications. However, proprietary models such as GPT-4o face significant barriers to clinical adoption because they cannot be deployed on site within healthcare institutions, making them noncompliant with stringent privacy regulations. Recent advancements in open-source LLMs such as DeepSeek models offer a promising alternative because they allow efficient fine-tuning on local data in hospitals with advanced information technology infrastructure. Here, to demonstrate the clinical utility of DeepSeek-V3 and DeepSeek-R1, we benchmarked their performance on clinical decision support tasks against proprietary LLMs, including GPT-4o and Gemini-2.0 Flash Thinking Experimental. Using 125 patient cases with sufficient statistical power, covering a broad range of frequent and rare diseases, we found that DeepSeek models perform equally well and in some cases better than proprietary LLMs. Our study demonstrates that open-source LLMs can provide a scalable pathway for secure model training enabling real-world medical applications in accordance with data privacy and healthcare regulations.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
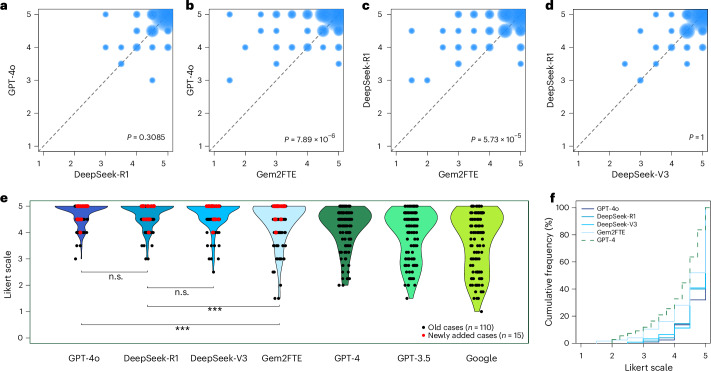
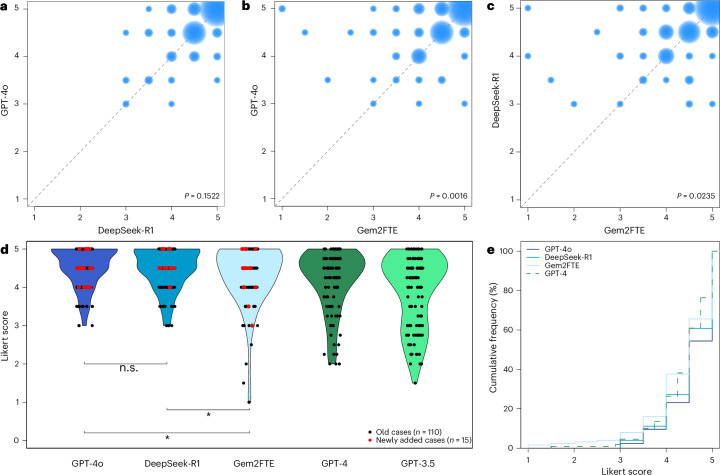
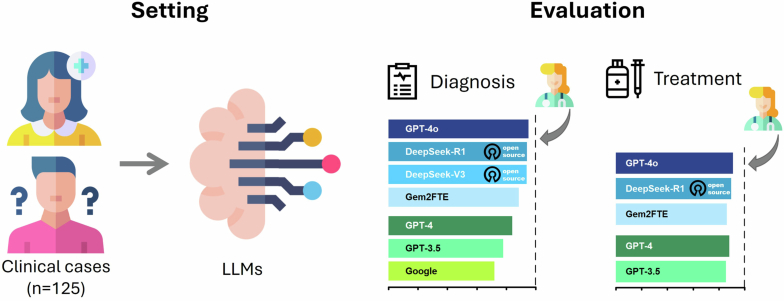
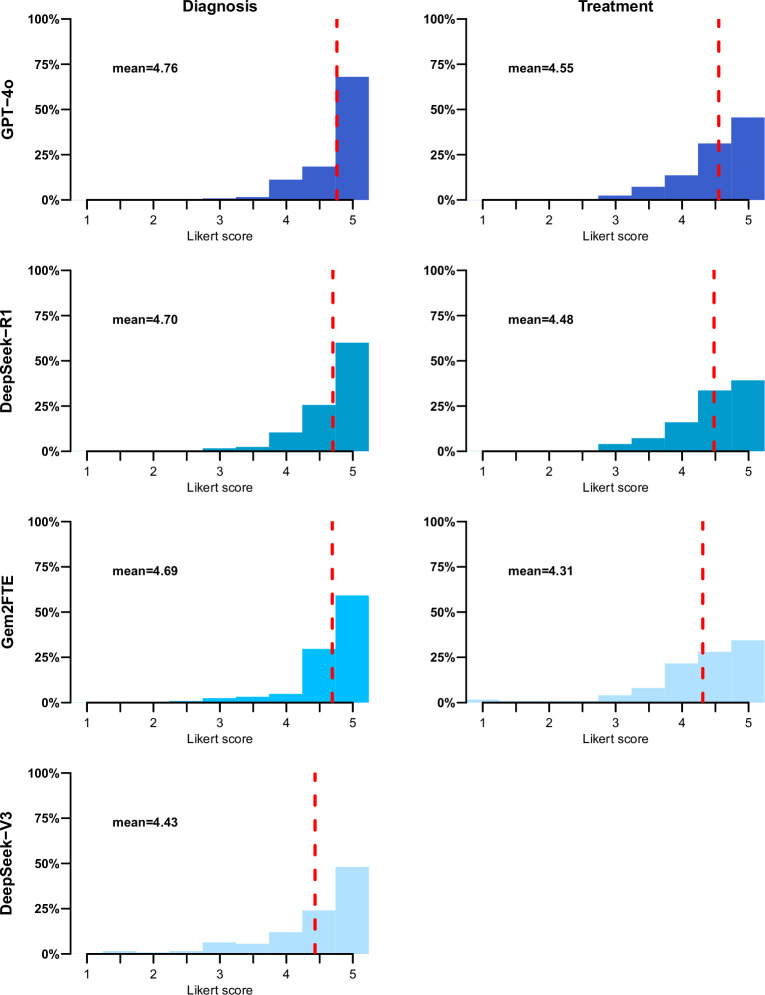
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, these frameworks typically focus on narrow clinical scenarios (1–28 datasets), rely on limited data sources or synthetic data, and assess primarily accuracy without comprehensive taxonomy validation or deployment considerations.”
From Holistic evaluation of large language models for medical tasks with MedHELM (2026) · cites this paper as [22]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
On a Test of Whether one of Two Random Variables is Stochastically Larger than the Other
Mann, H. B., & Whitney, D. R. (1947) · The Annals of Mathematical Statistics · doi:10.1214/aoms/1177730491 · Cited by 14,320
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2020) · Applied Sciences · doi:10.48550/arxiv.2009.13081 · Cited by 2,339
Artificial hallucinations in ChatGPT: implications in scientific writing
Alkaissi, H., & McFarlane, S. I. (2023) · Cureus · doi:10.7759/cureus.35179 · Cited by 1,540
Evaluation and mitigation of the limitations of large language models in clinical decision-making
Hager, P., Jungmann, F., Holland, R., Bhagat, K., Hubrecht, I., Knauer, M., Vielhauer, J., Makowski, M., Braren, R., Kaissis, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03097-1 · Cited by 798
DescTools: Tools for Descriptive Statistics
Signorell, A. (2014) · doi:10.32614/cran.package.desctools · Cited by 723
Jin, D., Pan, E., Oufattole, N., Weng, W.-H., Fang, H., & Szolovits, P. (2021) · Applied Sciences · doi:10.3390/app11146421 · Cited by 718
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
DeepSeek-AI, Guo, D., Yang, D., Zhang, H., Song, J., Wang, P., Zhu, Q., Xu, R., Zhang, R., Ma, S., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12948 · Cited by 538
Medical large language models are vulnerable to data-poisoning attacks
Alber, D. A., Yang, Z., Alyakin, A., Yang, E., Rai, S., Valliani, A. A., Zhang, J., Rosenbaum, G. R., Amend-Thomas, A. K., Kurland, D. B., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03445-1 · Cited by 242 · cited 1×
“Concerns regarding data privacy, algorithmic bias and the potential for generating inaccurate or misleading information remain paramount 8–10 .”
Systematic analysis of ChatGPT, Google search and Llama 2 for clinical decision support tasks
Sandmann, S., Riepenhausen, S., Plagwitz, L., & Varghese, J. (2024) · Nature Communications · doi:10.1038/s41467-024-46411-8 · Cited by 228
Self-citationGuidelines for clinical guidelines
Jackson, R., & Feder, G. S. (1998) · BMJ · doi:10.1136/bmj.317.7156.427 · Cited by 206
Research works printed but not linked: 1
- Bonferroni, C. E. Teoria statistica delle classi e calcolo delle probabilita. Pubblicazioni del R. Istituto Super. di Sci. Economiche e Commericiali di Firenze 8, 3–62 (1936).
Cited by
Sorted by citations
Quantifying the reasoning abilities of LLMs on clinical cases
Qiu, P., Wu, C., Liu, S., Fan, Y., Zhao, W., Chen, Z., Gu, H., Peng, C., Zhang, Y., Wang, Y., et al. (2025) · Nature Communications · doi:10.1038/s41467-025-64769-1 · Cited by 53
Holistic evaluation of large language models for medical tasks with MedHELM
Bedi, S., Cui, H., Fuentes, M., Unell, A., Wornow, M., Banda, J. M., Kotecha, N., Keyes, T., Mai, Y., Oez, M., et al. (2026) · Nature Medicine · doi:10.1038/s41591-025-04151-2 · Cited by 59
A large language model improves clinicians’ diagnostic performance in complex critical illness cases
Wu, X. C., Huang, Y., & He, Q. (2025) · Critical Care · doi:10.1186/s13054-025-05468-7 · Cited by 51
Chen, H., Zeng, W., Chen, C., Cai, L., Wang, F., Shi, Y., Wang, L., Zhang, W., Li, Y., Yan, H., et al. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107848 · Cited by 32
Large language models in global health
Ong, J. C. L., Ning, Y., Yang, R., Bitterman, D. S., Liu, X., Tham, Y. C., Collins, P. G. S., Jiménez, M., Mateen, B. A., Amissah-Arthur, K. N., et al. (2026) · Nature Health · doi:10.1038/s44360-025-00024-7 · Cited by 16
DeepSeek-assisted LI-RADS classification: AI-driven precision in hepatocellular carcinoma diagnosis
Zhang, J., Liu, J., Guo, M., Zhang, X., Xiao, W., & Chen, F. (2025) · International Journal of Surgery · doi:10.1097/js9.0000000000002763 · Cited by 14
Principles and Practice Guidelines of Microbiota Medicine: Statements From the CHINAGUT Conference
Zhang, F., Pi, Z., Wong, H. S., Ahuja, V., Porcari, S., Ishikawa, D., Cao, H., Chen, L., Chen, N., Chen, X., et al. (2026) · Microbiota Medicine Research · doi:10.1002/mmr3.70001 · Cited by 15
Cao, H., Hao, C., Zhang, T., Zheng, X., Gao, Z., Wu, J., Gan, L., Liu, Y., Zeng, X., & Wang, W. (2025) · Frontiers in Public Health · doi:10.3389/fpubh.2025.1605908 · Cited by 13
Chen, K., Hou, X., Li, X., Xu, W., & Yi, H. (2025) · Academic Radiology · doi:10.1016/j.acra.2025.07.046 · Cited by 14
Iyenghar, P. (2025) · Electronics · doi:10.3390/electronics14183624 · Cited by 11
Yu, H., Chen, T., Zhang, X., Yang, Y., Liu, Q., Yang, C., Shen, K., Li, H., Tang, W., Zhong, X., et al. (2025) · Journal of Medical Internet Research · doi:10.2196/77334 · Cited by 13
Ilić, N., Marić, N., Cvetković, D., Bogosavljević, M., Bukara-Radujković, G., Krstić, J., Paunović, Z., Begović, N. N., Zarić, S. P., Todorovic, S., et al. (2025) · Genes · doi:10.3390/genes16070762 · Cited by 10
Reviewing clinical knowledge in medical large language models: Training and beyond
Li, Q. Y., Liu, H., Guo, C., Gao, C., Chen, D., Wang, M., Gao, F., van Harmelen, F., & Gu, J. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.114215 · Cited by 14
Karaca, B., Çakmak, Y. E., & Erkal, D. (2025) · Australian Endodontic Journal · doi:10.1111/aej.70040 · Cited by 10
Multimodal artificial intelligence in medicine: a task-oriented framework for clinical translation
Zhang, R., Chen, Y., Yue, W., Zhang, Y., Li, X., Feng, S., Yuan, F., & Luo, M. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2025.1736272 · Cited by 15
Gong, E. J., Bang, C. S., & Shin, Y. S. (2026) · Bioengineering · doi:10.3390/bioengineering13030365 · Cited by 14
Gu, Y., Hu, X., Lee, H. W., Yao, Z., Zhou, T., Xia, N., Yang, P., Guo, J., Huang, H., Wang, L., et al. (2025) · Integrative Medicine Research · doi:10.1016/j.imr.2025.101214 · Cited by 10
Wu, X., Huang, Y., & He, Q. (2025) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2025.106088 · Cited by 8
Wang, M., Zhang, R.-P., Wu, W.-J., Lu, Y., Wei, X.-E., Sun, Z., Guan, B.-H., Zhang, J.-J., Wu, X., Zhang, L., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02380-4 · Cited by 10
iDesignGPT enhances conceptual design via large language model agentic workflows
Liu, S., Shen, Y., Zhang, Y., Hou, Z., Wang, X., Luo, J., & Zhang, Z. (2026) · Nature Communications · doi:10.1038/s41467-026-68672-1 · Cited by 21
Zhuang, Y., Dong, F., Li, P., Bai, B., Hei, X., Feng, L., Li, W., & Zhang, S. (2025) · Frontiers in Cell and Developmental Biology · doi:10.3389/fcell.2025.1642539 · Cited by 9
Jintao, 薛. X., Shenlei, 鲍. B., Chao, 程. C., Xianglin, 卜. B., Qian, 刘. L., Liqun, 魏. W., Yihao, 杨. Y., Wenfu, 张. Z., & Binhao, 王. W. (2025) · Acta Optica Sinica · doi:10.3788/aos251285 · Cited by 7
A clinical environment simulator for dynamic AI evaluation
Luo, L., Kim, S. E., Zhang, X., Kernbach, J. M., Kenia, R., Acosta, J. N., Nathanson, L. A., Haimovich, A. D., Rodman, A. M., Goh, E., et al. (2026) · Nature Medicine · doi:10.1038/s41591-026-04252-6 · Cited by 14
A Dataset for Evaluating Large Language Models on Chinese National Medical Licensing Examinations
Zong, H., Cha, J., Wang, J., Song, Y., Zhao, Y., Shi, M., & Shen, B. (2026) · Scientific Data · doi:10.1038/s41597-026-07261-9 · Cited by 7
He, Z., Zhao, L., Li, G., Wang, J., Cai, S., Tu, P., Chen, J., Wu, J., Zhang, J., Chen, R., et al. (2025) · Frontiers in Digital Health · doi:10.3389/fdgth.2025.1670510 · Cited by 8
Benchmarking pre-trained genomic language models for RNA sequence-related predictive applications
You, N., Liu, C., Lin, H. B., Wu, S., Chen, G., & Shen, N. (2025) · Nature Communications · doi:10.1038/s41467-025-66899-y · Cited by 7
Li, P., Xu, Y., Liu, X., Shen, Z., Wang, Y., Lv, X., Lu, Z., Wu, H., Zhuang, J., & Chen, Y. (2026) · JMIR Medical Informatics · doi:10.2196/81422 · Cited by 6
Roemer, A., Schlicker, N., Kernder, A. L., Albe, B., Hack, J., Hirsch, M., Mayr, A. J., Kuhn, S., & Knitza, J. (2026) · BMC Medical Education · doi:10.1186/s12909-026-09079-w · Cited by 15
ChatGPT-5 versus other mainstream large language models in core diabetic retinopathy patient queries
Cang, X., MengXia, N., Song, C., Zhao, J., Guo, Y., Zou, Y., Zhang, Z., & Jiang, L. (2026) · Frontiers in Cell and Developmental Biology · doi:10.3389/fcell.2026.1754221 · Cited by 6
Jiang, L., Zhu, Y., Song, C., Hu, X., Fan, X., Yang, W., & Zhao, Y. (2026) · Frontiers in Cell and Developmental Biology · doi:10.3389/fcell.2026.1785731 · Cited by 6
Wu, L., Mai, L., Wang, H., Huang, J., He, X., Zhan, X., Khalemsky, A., Kumar, V. A., Paxton, J. H., Tsilimingras, D., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02522-8 · Cited by 8
Innovating global regulatory frameworks for generative AI in medical devices is an urgent priority
Ong, J. C. L., Ning, Y., Liu, M., Ma, Y., Zhao, L., Singh, K., Chang, R. T., Vogel, S., Lim, J. C. W., Tan, I. S. K., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02552-2 · Cited by 7
Benchmarking large multimodal models for ophthalmic visual question answering with OphthalWeChat
Xu, P., Gong, X., Chen, X., Zhang, W., Yang, J., Yan, B., Yuan, M., Yalin, Z., He, M., & Shi, D. (2025) · Advances in Ophthalmology Practice and Research · doi:10.1016/j.aopr.2025.10.006 · Cited by 8
Duan, Z., Huang, X., Lu, R., Xu, W., Liu, H., Geng, Y., Takahashi, N., Wu, Y., Wang, Q., Song, Y., et al. (2025) · Cell Reports Medicine · doi:10.1016/j.xcrm.2025.102465 · Cited by 5
Self-citationAlmulla, A. A., & Khasawneh, M. A. S. (2025) · Psychiatric Quarterly · doi:10.1007/s11126-025-10243-6 · Cited by 9
Performance of Large Language Models in Metabolic Bariatric Surgery: a Comparative Study
El-Masry, H., El‐mezayen, M. Y., Farouk, B., Tawfik, A. M., Sharsher, P. S., Mohamed, B. H., Elmagd, A. A., Khammas, A. A., Nimeri, A. A., COHEN, R. V., et al. (2025) · Obesity Surgery · doi:10.1007/s11695-025-08418-y · Cited by 6
Sun, M., Zang, D., & Chen, J. (2026) · Frontiers in Bioengineering and Biotechnology · doi:10.3389/fbioe.2026.1750225 · Cited by 6
Hu, H., Wang, L., Chen, L., Lin, H., Huang, L.-T., Wang, Z.-W., & Hou, X. (2026) · Journal of Medicinal Chemistry · doi:10.1021/acs.jmedchem.5c03511 · Cited by 5
Zhang, L., Pan, Y., Lai, W., Liang, Z., Zhong, H., & Lin, X. (2026) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-026-03364-w · Cited by 6
BRIDGE: benchmarking large language models for understanding real-world clinical practice texts
Wu, J., Gu, B., Zhou, R., Xie, K., Snyder, D., Jiang, Y., Carducci, V., Wyss, R., Desai, R. J., Alsentzer, E., et al. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-026-01719-2 · Cited by 28
Zhang, Z., Zhang, Z., Zhang, S., et al. (2025) · International Journal of Surgery · doi:10.1097/js9.0000000000002951 · Cited by 4
Groza, T., Marcello, A., Carlisle, T., Lim, W. K., Haendel, M. A., Karnani, N., Robinson, P. N., Graeßner, H., Chong, J. X., Baynam, G. S., et al. (2025) · Human Genetics and Genomics Advances · doi:10.1016/j.xhgg.2025.100558 · Cited by 5
Chen, P., Cai, J., Zhou, J., Chen, S., Xu, C., Yuan, L., Dai, X., Chen, X., Wei, Y., Li, X., et al. (2026) · Communications Medicine · doi:10.1038/s43856-026-01576-9 · Cited by 6
Evaluation of DeepSeek-R1 for Ophthalmic Diagnosis and Reasoning: A Comparison with OpenAI o1 and o3
Ming, S., Yao, X., Guo, Q., Chen, D., Guo, X., Xie, K., & Lei, B. (2025) · Journal of Medical Systems · doi:10.1007/s10916-025-02264-2 · Cited by 4
Al-Anezi, F. M. (2026) · Journal of Healthcare Leadership · doi:10.2147/jhl.s590498 · Cited by 6
Zhou, Y., Feng, L., Lan, M., Yang, X., Li, Q., Ke, Y., Jiang, X., & Zhang, W. (2025) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2025.09.007 · Cited by 3
Yang, Y., Yang, F., Xiao, S., et al. (2025) · Journal of Magnetic Resonance Imaging · doi:10.1002/jmri.70140 · Cited by 3
Evaluating the Performance of DeepSeek-R1 as a Patient Education Tool
Hu, J., Wang, J., He, L., Qiu, Z., Sun, S., & Peng, F. (2025) · Journal of Medical Systems · doi:10.1007/s10916-025-02282-0 · Cited by 3
Luo, D., Liu, M., Zhang, H., Wang, X., Gao, Q., Kuang, N., Yin, T., & Zheng, Z. (2025) · Scientific Reports · doi:10.1038/s41598-025-23973-1 · Cited by 3
Abudari, M. O., Abu-Abbas, M., Al‐Ma'ani, M., Alradaydeh, M. F., & Alduraidi, H. (2025) · BMC Nursing · doi:10.1186/s12912-025-04068-8 · Cited by 4
Wang, J., & Redelmeier, D. A. (2025) · BMJ Quality & Safety · doi:10.1136/bmjqs-2025-019299 · Cited by 4
Lu, J., Huang, J., Guo, Y. H., Wu, Q., Jiang, Z., Yang, T., Bian, J., & Bo, L. (2026) · BMC Anesthesiology · doi:10.1186/s12871-025-03605-x · Cited by 3
Agentic memory-augmented retrieval and evidence grounding for medical question-answering tasks
Jia, S., Bit, S., Jasodanand, V. H., Liu, Y., & Kolachalama, V. B. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106339 · Cited by 6
Cai, H., Wang, C., Zhang, Y., Ding, H., Hong, W., Zhao, Y., Cheng, S., & Wang, Y. (2026) · Diagnostics · doi:10.3390/diagnostics16040616 · Cited by 3
Wu, H., Deng, J., Qiu, X., Xu, L. L., Lu, L., Fan, M., Yu, D., Liu, C., Chen, Z., Wang, K., et al. (2026) · Frontiers in Endocrinology · doi:10.3389/fendo.2026.1667159 · Cited by 3
Cao, W., Qu, M., Zhu, T., Liu, J., Shen, Y., Zou, J., Li, Y., Wang, H., Zhang, L., Liu, H., et al. (2026) · Journal of NeuroEngineering and Rehabilitation · doi:10.1186/s12984-026-01903-0 · Cited by 7
Liang, J., Xing, M., Xiang, P., Wang, G., Chen, M., Fang, Q., Zhou, T., Lu, Z., Leng, X., Huang, J., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02537-1 · Cited by 4
Huang, G., Li, L.-J., Li, P.-S., Fan, Z., & Lu, B.-Q. (2026) · European Archives of Oto-Rhino-Laryngology · doi:10.1007/s00405-026-10133-y · Cited by 3
Promises and challenges of applying large language models in the healthcare domain
Wang, Q., Gong, Z., Lai, Z., Bu, L., Dahlweid, F.-M., & Sun, H. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1772274 · Cited by 4
Li, Z., Liu, H., Tan, W., Tang, D., Duan, S., Zhou, B., Tang, L., Hu, X., Huang, L., Zhao, P., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02645-y · Cited by 5
Saraboji, K., Gopalakrishnan, K., Sood, D., Kaur, A., Shivaram, S., Helgeson, S. A., Arunachalam, S. P., & Mitra, D. (2026) · AI in Medicine · doi:10.3390/aimed1020016 · Cited by 4
Zang, T., Li, J., Wei, L., et al. (2025) · Journal of Craniofacial Surgery · doi:10.1097/scs.0000000000011930 · Cited by 2
Chen, G., Lin, C., Zhang, L., Luo, Z., Shin, Y. S., & Li, X. (2025) · BMC Medical Education · doi:10.1186/s12909-025-07872-7 · Cited by 5
Niu, S., Liu, X., Huang, L., Li, Y.-Q., & Wang, G. (2025) · BMC Medical Education · doi:10.1186/s12909-025-08184-6 · Cited by 2
Liu, K., Cheng, L., Wang, W., Wu, R., Li, C., Yao, K., & Ge, J. (2025) · Intelligent Medicine · doi:10.1016/j.imed.2025.11.002 · Cited by 2
Jiang, W., Wang, D., Zeng, Y., Huang, J., Xu, C., & Liu, C. (2025) · Journal of Medical Internet Research · doi:10.2196/80770 · Cited by 2
Zou, Z., Yang, J., Xu, Y., Chen, L., Zeng, D., Li, H., & Qin, Y. (2025) · The Visual Computer · doi:10.1007/s00371-025-04280-2 · Cited by 2
DeepSeek-R1 performance in fusion planning of adolescent idiopathic scoliosis: A preliminary study
Jia, J., Shi, B., shi, B., et al. (2026) · Orthopaedics & Traumatology Surgery & Research · doi:10.1016/j.otsr.2026.104660 · Cited by 2
Ferdowsi, M., Moustafa, N., Keshk, M., & Turnbull, B. (2026) · Electronics · doi:10.3390/electronics15071519 · Cited by 2
Dave, R., Vediya, N., Sharma, N., Shah, A., Whelan, D. B., & Wolfstadt, J. I. (2026) · Journal of the American Academy of Orthopaedic Surgeons · doi:10.5435/jaaos-d-25-01242 · Cited by 3
Zhou, T., Zou, L., Wang, W., et al. (2026) · Computers in Industry · doi:10.1016/j.compind.2026.104479 · Cited by 2
Wei, J., Jiang, S., Yin, T., Ma, J., Li, Q., Tian, Y., Yan, M., Shen, Z., Lv, X., Ma, X., et al. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1780425 · Cited by 2
Peng, L., Zhang, Y., Zhao, A., Li, R., Li, Z., Zhao, J., Yu, P., Liu, Y., Shi, H., Liang, R., et al. (2026) · Annals of Surgical Oncology · doi:10.1245/s10434-026-19745-4 · Cited by 2
Generative Artificial Intelligence and Large Language Models in Clinical Oncology
Yu, Y., Zhao, Z., Wang, Z., Lin, R., Tan, Y., Chen, Y., Li, T., Baptista‐Hon, D. T., Zhang, X., Wu, C., et al. (2026) · MedComm · doi:10.1002/mco2.70833 · Cited by 2
LLM Reasoning Does Not Protect Against Clinical Cognitive Biases - An Evaluation Using BiasMedQAPreprint
Kim, S. H., Ziegelmayer, S., Busch, F., Mertens, C. J., Keicher, M., Adams, L. C., Bressem, K. K., Braren, R., Makowski, M. R., Kirschke, J. S., et al. (2025) · medRxiv · doi:10.1101/2025.06.22.25330078 · Cited by 2
Roemer, A., Schlicker, N., Kernder, A. L., Albe, B., Hack, J., Hirsch, M., Mayr, A. J., Kühn, S., & Knitza, J. (2025) · doi:10.2196/preprints.79716 · Cited by 2
Data Space and LLM Enabled Decision-Making Support System: An Application in Drug Development
Wang, C., Ming, X., Zhang, X., et al. (2025) · International Conference on Electronic Engineering and Information Systems (EEISS) · doi:10.1109/eeiss65394.2025.11085518 · Cited by 1
Qing, J., Cheungpasitporn, W., Qin, K., Wang, X., Li, Y., & Wu, J. (2025) · American Journal of Nephrology · doi:10.1159/000549005 · Cited by 1
Zhao, Y., Zhang, Y., Su, Z., Cui, L., & Miao, C. (2026) · IEEE International Conference on Data Engineering (ICDE) · doi:10.1109/icde65706.2026.00106 · Cited by 1
Wang, R., Wang, J., Wang, Y., Zheng, C., Huang, S., Liu, X., Tan, G., Zhao, W., Wang, Z., Peng, S., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02285-8 · Cited by 1
Zhou, M., Gui, F., Ai, C., Ling, L., Zhang, X., Lu, Y., Han, D., Zhao, B., Zhong, F., Liu, J., et al. (2026) · Graefe s Archive for Clinical and Experimental Ophthalmology · doi:10.1007/s00417-025-07092-1 · Cited by 3
Artefacts in continuous neuromonitoring
Chen, X., Bögli, S. Y., Olakorede, I., Xu, W., Beqiri, E., Tang, C., Occhipinti, L. G., Gao, S., & Smielewski, P. (2026) · Nature Reviews Bioengineering · doi:10.1038/s44222-025-00378-3 · Cited by 2
Lu, J., Chiu, K. W.-H., Chan, C., Cheng, H.-M., Zhou, J., Justin Christopher, N. G., Tang, F. F. Y., Kan, W. K., Yu, P. L. H., & Seto, W. (2026) · European Journal of Radiology · doi:10.1016/j.ejrad.2026.112689 · Cited by 1
Weiglein, A., Kriebel, J., Varghese, J., Herrmann, T., Sandmann, S., & Bruns, C. (2026) · JMIR AI · doi:10.2196/84362 · Cited by 3
Self-citationChen, A., & ZHANG, X. (2026) · Asian Journal of Medical Humanities · doi:10.1515/ajmedh-2025-0035 · Cited by 1
Comparative Performance of DeepSeek and ChatGPT-4o in the Chinese Nursing Licensing Exam
Liu, X., Wang, H., Guo, X., Tian, S., & Cao, H. (2026) · Journal of Nursing Education · doi:10.3928/01484834-20250926-03 · Cited by 1
Arzideh, K., Hosch, R., Turki, A. T., Eryılmaz, B., Bahn, M., Schäfer, H., Idrissi-Yaghir, A., Khattab, S., Dada, A., Baba, H. A., et al. (2026) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00254 · Cited by 1
Jiang, S., Yang, C., Huang, Z., et al. (2026) · Journal of Extracellular Vesicles · doi:10.1002/jev2.70233 · Cited by 1
Sugihara, Y., Milosavljević, A. M., Jankovskaja, S., & Falk, M. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1778786 · Cited by 4
Virtual medicine: medical AI in human health and diseases
Zhang, C., Wang, F.-X., Tang, X., Li, J.-L., Ding, N., Hong, Y., Song, P., Bai, L., & Su, J. (2026) · Military Medical Research · doi:10.1016/j.mmr.2026.100012 · Cited by 1
Jin, Y., Feng, C., Zhao, J., Lin, W., & Li, B. (2026) · Journal of International Medical Research · doi:10.1177/03000605261438348 · Cited by 1
Screening Routine Clinical Notes for Epilepsy Surgery Candidates Using Large Language Models
Fennig, U., Amir, N., Schiller, M., Loebenstein, R., Nissan, J., Boxer, M., Gofrit, S. G., Goshen, G., Beniczky, S., & Maggio, N. (2026) · Annals of Clinical and Translational Neurology · doi:10.1002/acn3.70427 · Cited by 1
Viculin, I., Vrdoljak, J., Tomić, K., Canjko, I., Čerina, D., Ćurin, M., Bošković, L., Družijanić, Z., Vuković, B., Dunkić, N., et al. (2026) · Journal of Medical Internet Research · doi:10.2196/91733 · Cited by 2
Wu, X., Li, J., Liu, S., Li, Y., Wang, Q., Luo, C., Shi, L., Zheng, Y., Meng, L., Fan, M., et al. (2026) · Calcified Tissue International · doi:10.1007/s00223-026-01546-2 · Cited by 1
Gerchow, L., Schnall, R., & Liu, J. P. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106492 · Cited by 1
Rethinking healthcare data interoperability in the age of large language models
von Arnim, G., Kohler, S., Hegselmann, S., Marschollek, M., Eils, R., & Wild, B. (2026) · Med · doi:10.1016/j.medj.2026.101146 · Cited by 2
Self-citationYe, X., Qi, X., Fan, L., Yu, Q., Zhou, S., Ren, C., & Yang, D. (2026) · Journal of Medical Internet Research · doi:10.2196/87802 · Cited by 1
Wu, D., Chen, K., Wu, X., Jin, J., & Xu, F. (2026) · Infection and Drug Resistance · doi:10.2147/idr.s593763 · Cited by 1
Bilgiç, B., Turan, S., Avcıl, S., & Pekcanlar, A. A. (2026) · BMC Psychiatry · doi:10.1186/s12888-026-08280-x · Cited by 2
Tao, Y., Lin, X., Sun, H., Bao, W., Zhu, X., Wu, S., Liu, Y., Li, Z., Wu, J., Zhao, Z., et al. (2026) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocag053 · Cited by 1
Metadata
- Authors
- Sandmann, S., Hegselmann, S., Fujarski, M., Bickmann, L., Wild, B., Eils, R., & Varghese, J.
- Affiliations
- University of Münster (DE)
- Berlin Institute of Health at Charité - Universitätsmedizin Berlin (DE)
- Shanghai Medical College of Fudan University (CN)
- Otto-von-Guericke-Universität Magdeburg (DE)
- Corresponding author
- Eils, Roland
- Venue
- Nature Medicine
- Published
- 2025-04-23
- Volume
- 31
- Issue
- 8
- Pages
- 2546-2549
- ISSN
- 1078-8956 (ISSN-L)
- 1546-170X
- PMC
- PMC12353792
- OpenAlex
- W4409695426
- Cited by
- 233
- References
- 20
- Citations by year
- 2026: 171 · 2025: 62
- FWCI
- 55.69
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature Medicine (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- Funders
- Deutsche Forschungsgemeinschaft (SFB 1470)
- National Natural Science Foundation of China (W2441025)
- Bundesministerium für Bildung und Forschung (01KX2121)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- DeepSeek, open-source large language models, clinical decision support, benchmarking, GPT-4o, Gemini, DeepSeek-V3, DeepSeek-R1, data privacy, rare diseases, clinical adoption
- MeSH terms
- Clinical Decision-Making, Large Language Models, Humans, Benchmarking, Decision Support Systems, Clinical
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
