

Evaluation metrics and statistical tests for machine learning
Open accessThe DOI matches its Crossref record; 58 of the 60 references it cites were found in a registry or an index.
Abstract
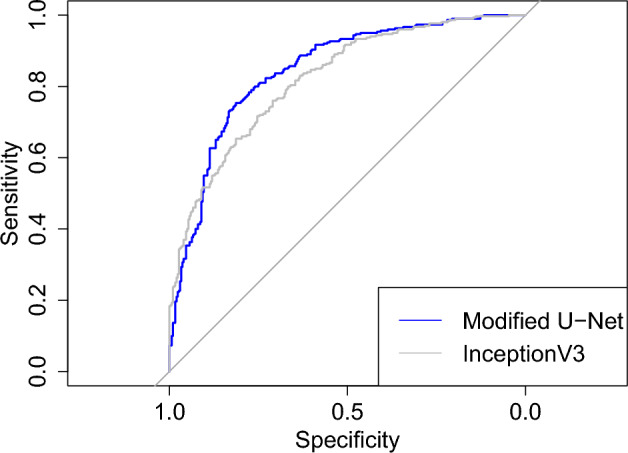
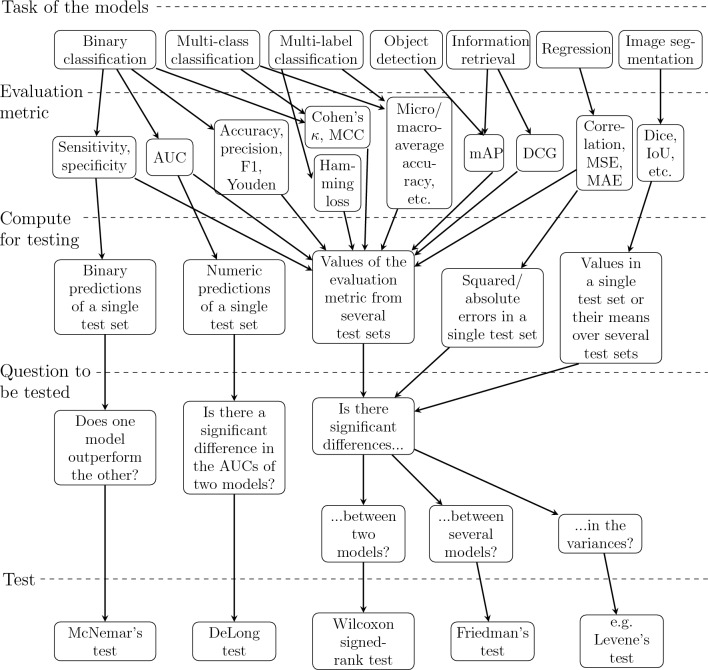
Research on different machine learning (ML) has become incredibly popular during the past few decades. However, for some researchers not familiar with statistics, it might be difficult to understand how to evaluate the performance of ML models and compare them with each other. Here, we introduce the most common evaluation metrics used for the typical supervised ML tasks including binary, multi-class, and multi-label classification, regression, image segmentation, object detection, and information retrieval. We explain how to choose a suitable statistical test for comparing models, how to obtain enough values of the metric for testing, and how to perform the test and interpret its results. We also present a few practical examples about comparing convolutional neural networks used to classify X-rays with different lung infections and detect cancer tumors in positron emission tomography images.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures

Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
R: A Language and Environment for Statistical Computing
R Core Team (2025) · doi:10.32614/r.manuals · Cited by 352,181
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
A Coefficient of Agreement for Nominal Scales
Cohen, J. (1960) · Educational and Psychological Measurement · doi:10.1177/001316446002000104 · Cited by 42,398
SciPy 1.0: fundamental algorithms for scientific computing in Python
Virtanen, P., Gommers, R., Oliphant, T. E., Haberland, M., Reddy, T., Cournapeau, D., Burovski, E., Peterson, P., Weckesser, W., Bright, J., et al. (2020) · Nature Methods · doi:10.1038/s41592-019-0686-2 · Cited by 38,430
An analysis of variance test for normality (complete samples)
SHAPIRO, S. S., & WILK, M. B. (1965) · Biometrika · doi:10.1093/biomet/52.3-4.591 · Cited by 23,480
DeLong, E. R., DeLong, D. M., & Clarke-Pearson, D. L. (1988) · Biometrics · doi:10.2307/2531595 · Cited by 22,649 · cited 1×
“Namely, DeLong et al. 49 noticed that the Mann-Whitney statistic can be used as an estimate of an AUC and the theory of generalized U-statistic can be applied to compare two AUCs.”
MethodpROC: an open-source package for R and S+ to analyze and compare ROC curves
Robin, X., Turck, N., Hainard, A., Tiberti, N., Lisacek, F., Sanchez, J.-C., & Müller, M. (2011) · BMC Bioinformatics · doi:10.1186/1471-2105-12-77 · Cited by 13,697
Measures of the Amount of Ecologic Association Between Species
Dice, L. R. (1945) · Ecology · doi:10.2307/1932409 · Cited by 11,874
SciPy 1.0: fundamental algorithms for scientific computing in Python
Virtanen, P., Gommers, R., Oliphant, T. E., Haberland, M., Reddy, T., Cournapeau, D., Burovski, E., Peterson, P., Weckesser, W., Bright, J., et al. (2019) · Apollo - University of Cambridge Repository · doi:10.17863/cam.64134 · Cited by 10,460
Machine learning: Trends, perspectives, and prospects
Jordan, M. I., & Mitchell, T. M. (2015) · Science · doi:10.1126/science.aaa8415 · Cited by 9,955
Research works printed but not linked: 9
- Demšar, J. Statistical comparisons of classifiers over multiple data sets. J. Mach. Learn. Res. 7, 1–30 (2006).
- Planche, B. & Andres, E. Hands-On Computer Vision with TensorFlow 2: Leverage Deep Learning to Create Powerful Image Processing Apps with TensorFlow 2.0 and Keras (Packt Publishing, 2019).
- Zhu, W., Zeng, N. & Wang, N. Sensitivity, specificity, accuracy, associated confidence interval and ROC analysis with practical SAS implementations. In NESUG proceedings: health care and life sciences, Baltimore, Maryland 67, vol. 19 (2010).
- Small Casler, K. & Gawlik, K. (eds) Laboratory Screening and Diagnostic Evaluation: An Evidence-Based Approach (Springer, 2022).
- Lantz, B. Machine Learning with R: Learn Techniques for Building and Improving Machine Learning Models, from Data Preparation to Model Tuning, Evaluation, and Working with Big Data (Packt Publishing, 2023).
- Sørensen, T. A method of establishing groups of equal amplitude in plant sociology based on similarity of species and its application to analyses of the vegetation on Danish commons. K. Dan. Vidensk. Selsk. 5(4), 1–34 (1948).
- van Rossum, G. & Drake, F. L. Python 3 Reference Manual (CreateSpace, 2009).
- Bartlett, M. S. Properties of sufficiency and statistical tests. Proc. R. Stat. Soc. Ser. A 160, 268–282 (1937).
- Fox, J. & Weisberg, S. An R Companion to Applied Regression 3rd edn. (Sage, 2019).
Cited by
Lee, M. C. H., Braet, J., & Springael, J. (2024) · Applied Sciences · doi:10.3390/app14219863 · Cited by 251
Yunita, A., Pratama, I. P. A., Almuzakki, M. Z., Ramadhan, H., Akhir, E. A. P., Mansur, A. B. F., & Basori, A. H. (2025) · MethodsX · doi:10.1016/j.mex.2025.103462 · Cited by 215
AI-Driven Drug Discovery: A Comprehensive Review
Ferreira, F. J. N., & Carneiro, A. S. (2025) · ACS Omega · doi:10.1021/acsomega.5c00549 · Cited by 202
A Review of CNN Applications in Smart Agriculture Using Multimodal Data
El Sakka, M., Ivanovici, M., Chaari, L., & Mothe, J. (2025) · Sensors · doi:10.3390/s25020472 · Cited by 176
Koçak, B., Klontzas, M. E., Stanzione, A., Meddeb, A., Demircioğlu, A., Blüthgen, C., Bressem, K. K., Ugga, L., Mercaldo, N. D., Díaz, O., et al. (2025) · European Journal of Radiology Artificial Intelligence · doi:10.1016/j.ejrai.2025.100030 · Cited by 144
Metadata
- Authors
- Rainio, O., Teuho, J., & Klén, R.
- Affiliations
- University of Turku (FI)
- Corresponding author
- Rainio, Oona
- Venue
- Scientific Reports
- Published
- 2024-03-13
- Volume
- 14
- Issue
- 1
- Pages
- 6086-6086
- ISSN
- 2045-2322 (ISSN-L)
- PMC
- PMC10937649
- OpenAlex
- W4392741075
- Cited by
- 1,338
- References
- 60
- Citations by year
- 2026: 594 · 2025: 593 · 2024: 151
- FWCI
- 197.04
- Type
- journal article
- Language
- en
- Update notices
- correction (2024-07-08)
- Open access
- gold
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Scientific Reports (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- UTUPub (University of Turku) (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Suomen Kulttuurirahasto
- Jenny ja Antti Wihurin Rahasto
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Data Classification
- Physical Sciences › Computer Science › Artificial Intelligence › Imbalanced Data Classification Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Keywords
- hypothesis testing, model comparison, supervised learning, binary classification, multi-class classification, multi-label classification, regression analysis, image segmentation, object detection, information retrieval, convolutional neural networks
- MeSH terms
- Machine Learning, Supervised Machine Learning, Image Processing, Computer-Assisted, Neural Networks, Computer, Positron-Emission Tomography
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Evaluation metrics and statistical tests for machine learning. https://app.cochat.ai/papers/10.1038/s41598-024-56706-x
- The paper
- Rainio, O., Teuho, J., & Klén, R. (2024). Evaluation metrics and statistical tests for machine learning. Scientific Reports. https://doi.org/10.1038/s41598-024-56706-x
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
