

The DOI matches its Crossref record; 55 of the 55 references it cites were found in a registry or an index; 8 of the 10 sources its claims cite were checked for support.
Biomedical knowledge graph-optimized prompt generation for large language models
Open accessAbstract
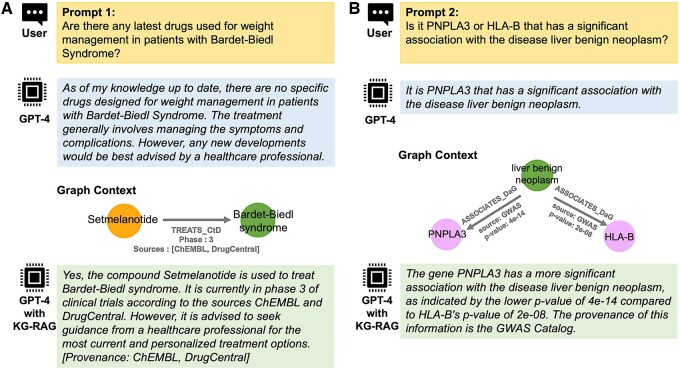
MOTIVATION: Large language models (LLMs) are being adopted at an unprecedented rate, yet still face challenges in knowledge-intensive domains such as biomedicine. Solutions such as pretraining and domain-specific fine-tuning add substantial computational overhead, requiring further domain-expertise. Here, we introduce a token-optimized and robust Knowledge Graph-based Retrieval Augmented Generation (KG-RAG) framework by leveraging a massive biomedical KG (SPOKE) with LLMs such as Llama-2-13b, GPT-3.5-Turbo, and GPT-4, to generate meaningful biomedical text rooted in established knowledge. RESULTS: Compared to the existing RAG technique for Knowledge Graphs, the proposed method utilizes minimal graph schema for context extraction and uses embedding methods for context pruning. This optimization in context extraction results in more than 50% reduction in token consumption without compromising the accuracy, making a cost-effective and robust RAG implementation on proprietary LLMs. KG-RAG consistently enhanced the performance of LLMs across diverse biomedical prompts by generating responses rooted in established knowledge, accompanied by accurate provenance and statistical evidence (if available) to substantiate the claims.
Overview
CoChat Summary
## TL;DR
This paper introduces KG-RAG, a token-optimized retrieval-augmented generation framework that uses the SPOKE biomedical knowledge graph to ground LLM outputs in established biomedical knowledge. Across benchmark tasks, it reduced token use by more than 50% versus prior KG-RAG approaches and improved Llama-2 performance on a challenging MCQ dataset by 71%.
## Key findings
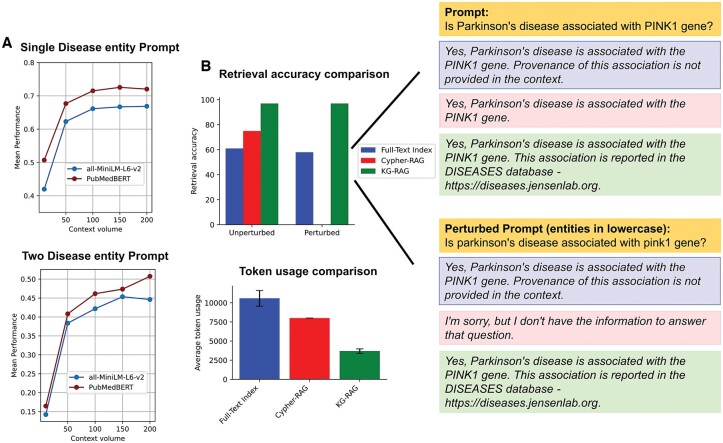
- On a 100-question retrieval benchmark, KG-RAG achieved 97% retrieval accuracy, compared with 75% for Cypher-RAG and 61% for full-text index retrieval.
- Under prompt perturbation (lowercasing entity names), Cypher-RAG retrieval accuracy dropped to 0%, while KG-RAG maintained 97% and full-text index dropped slightly to 58% from 61%.
- KG-RAG used an average of 3,693 tokens per response, versus 8,006 for Cypher-RAG and 10,590 for full-text index, corresponding to 53.9% and 65.1% token reductions, respectively.
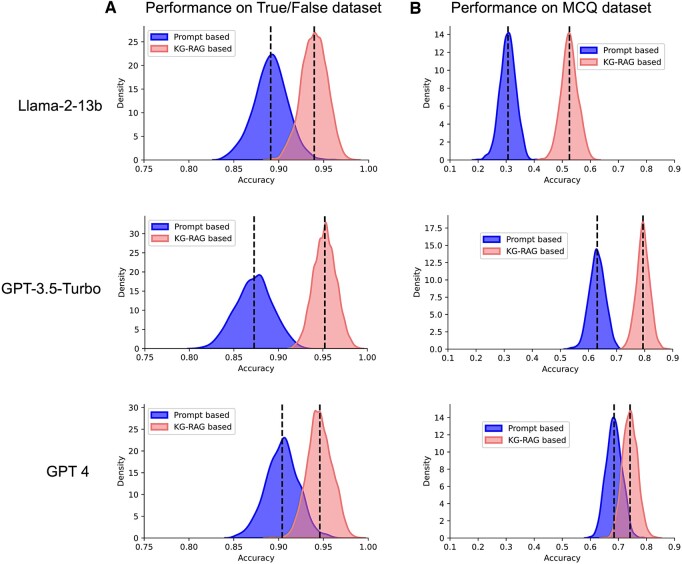
- On the MCQ dataset, KG-RAG increased Llama-2 accuracy from 0.31 ± 0.03 to 0.53 ± 0.03, described as approximately a 71% boost; on the same KG-RAG setup, GPT-3.5-Turbo outperformed GPT-4 on MCQ (0.79 ± 0.02 vs 0.74 ± 0.03, P < 0.0001).
## Methods
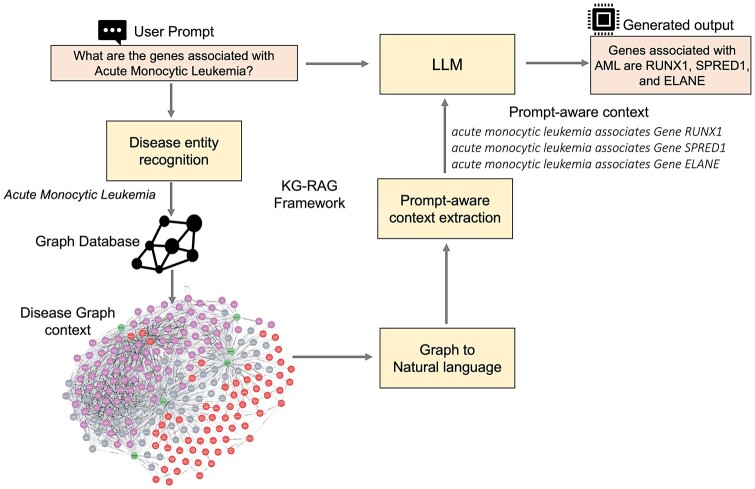
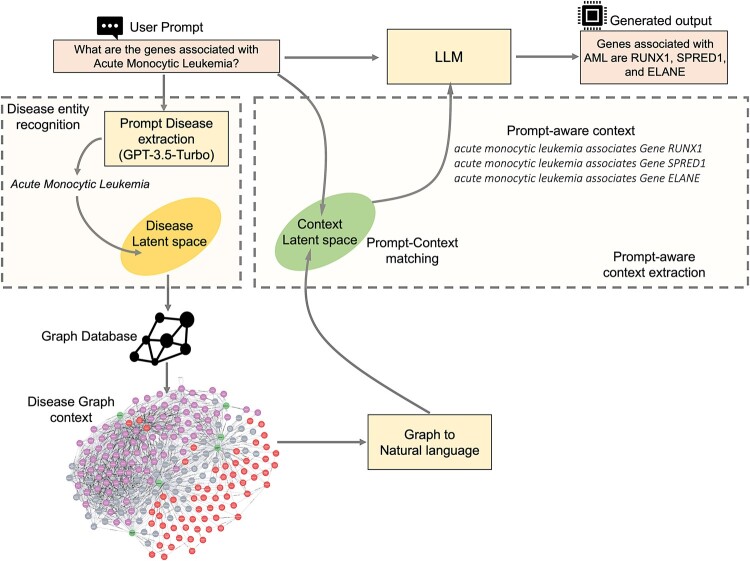
- Framework design: disease entity extraction from user prompts, disease-node matching in SPOKE, neighborhood/context retrieval from the graph, context pruning with sentence-transformer embeddings and cosine-similarity thresholds, then prompt assembly and LLM generation.
- Data/sample: SPOKE, a biomedical knowledge graph with 42 million nodes, 160 million edges, and 41 integrated biomedical databases; benchmark datasets included 311 True/False questions, 306 MCQs, and 100 retrieval-comparison questions, plus 165 validation questions for hyperparameter tuning.
- Analysis: compared KG-RAG with prompt-only, Cypher-RAG, and full-text index approaches using accuracy, Jaccard similarity, robustness to prompt perturbation, and token usage; LLMs tested were Llama-2-13b, GPT-3.5-Turbo, and GPT-4 with temperature set to 0.
## Limitations
- The paper states the approach is currently limited to biomedical questions centered on diseases, though it includes a proof of concept extending to more than 87,000 non-disease nodes; this is an explicit limitation.
- The paper says it was developed on SPOKE only and future work will extend it to other biomedical KGs and domains; this is an explicit limitation.
- The paper notes that context quality depends on the underlying graph and that SPOKE is “not entirely error free” or ready for clinical use; this is an explicit limitation.
- Evident from the text: the evaluation focuses on curated benchmark questions and retrieval tasks rather than a formal clinical validation of the KG-RAG system in real-world biomedical use.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
4 Valid · 2 Not valid · 0 Not checked · 50 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Thus, while SPOKE’s reliability has been demonstrated through its successful application in various biomedical contexts (Supplementary S1 Text; Himmelstein and Baranzini, 2015, Himmelstein et al. 2017, Nelson et al. 2019, Nelson et al. 2021a,b, Baranzini et al. 2022, Morris et al. 2023, Soman et al. 2023a,b, Tang et al. 2024)”
§ Biomedical knowledge graph-optimized prompt generation for large language models > 3 Results > 3.4 Performance on True/False and MCQ datasets
What the sources say
- Partly supportedcites Himmelstein and Baranzini, 2015 sourceExperimental — accuracy not yet measured
The Discussion reports that this paper’s heterogeneous-network predictions successfully prioritized disease–gene associations across 29 diseases and helped identify three multiple-sclerosis susceptibility genes. That supports a successful biomedical application of a related network approach, but our copy does not identify the network as SPOKE or demonstrate SPOKE’s reliability across various contexts. (LLM, conf=0.83)
- Could not verifycites Himmelstein et al. 2017 sourceExperimental — accuracy not yet measured
The Introduction and Results > Hetionet v1.0 describe Hetionet and its use in drug repurposing and prototype biomedical queries, not SPOKE. Searches for SPOKE and its reliability found no passage in our copy addressing whether SPOKE was successfully applied across biomedical contexts; page numbers were unavailable. (LLM, conf=0.76)
- Partly supportedcites Morris et al. 2023 sourceExperimental — accuracy not yet measured
The Discussion reports that SPOKE has been used in several biomedical applications and that one approach predicted multiple sclerosis diagnoses with up to 83% accuracy. It does not establish SPOKE’s general reliability across those varied contexts; the documented success is specific to that prediction application. (LLM, conf=0.80)
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Nevertheless, the “implicit representation” of knowledge in LLM has also been shown to generate non-factual information despite linguistically coherent answers (i.e. “hallucination”) as a response to the input prompt (Maynez et al. 2020, Raunak et al. 2021, Ji et al. 2023).”
§ Biomedical knowledge graph-optimized prompt generation for large language models > 1 Introduction
What the sources say
- Partly supportedcites Maynez et al. 2020 sourceExperimental — accuracy not yet measured
Section 5.3, “Assessment of Factual Hallucinations” (page unavailable), reports that over 90% of BERTS2S hallucinations were erroneous, supporting the point that generated text can be non-factual. But the study concerns abstractive summaries of documents, not LLM answers to prompts, and it does not establish that an implicit representation of knowledge causes the errors; it says pretraining helps generate more factual summaries. (LLM, conf=0.86)
- Partly supportedcites Raunak et al. 2021 sourceExperimental — accuracy not yet measured
The Introduction describes NMT hallucinations as outputs decoupled from the source sequence despite being fluent in the target language, and the Conclusion reports experiments on when such hallucinations arise. This supports the claim’s general point about fluent but unsupported output. The paper studies neural machine translation, however, not LLM answers to prompts or an ‘implicit representation’ of knowledge. (LLM, conf=0.88)
- Not matchedcites Ji et al. 2023
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“To achieve this, we make use of the biomedical KG called SPOKE (Morris et al. 2023) that integrates more than 40 publicly available biomedical knowledge sources of separate domains where each source is centered around a biomedical concept, such as genes, proteins, drugs, compounds, diseases, and one or more of their known relationships.”
§ Biomedical knowledge graph-optimized prompt generation for large language models > 1 Introduction
What the sources say
- Supportedcites Morris et al. 2023 source
The Introduction describes SPOKE as connecting 41 specialized databases across biomedical fields, using distinct node and relationship types. Table 1 in Section 2.1 lists sources for concepts including genes, proteins, compounds and diseases; the Results describe the relationships connecting them. Page numbers are not provided in our copy. (LLM, conf=0.90)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, we demonstrated that this method can be sensitive to how the prompt is formulated. Even slight perturbations to the prompt can lead to incorrect Cypher queries and subsequently impact downstream generative processes.”
§ Biomedical knowledge graph-optimized prompt generation for large language models > 2 Materials and methods > 2.8 Cypher-RAG
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Furthermore, KG-RAG enhanced the performance of proprietary GPT models, such as GPT-3.5 and GPT-4.”
§ Biomedical knowledge graph-optimized prompt generation for large language models > Abstract > Results
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
25 more claims
Create a free account to see all 56 claims and every source verdict.
- Probably not a substantial claim. 7
- It may state two separate claims as one. 21
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Empirical evidence supporting the utility of LLMs in neurodegenerative disease characterization continues to emerge.”
From Review of Artificial Intelligence for Clinical Use in Alzheimer's Disease and Related Dementias (2026) · cites this paper as [21]
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“provided neuropathologic differential diagnoses with high correlation to experts using human-curated clinical summaries.21”
From Review of Artificial Intelligence for Clinical Use in Alzheimer's Disease and Related Dementias (2026) · cites this paper as [21]
Experimental — accuracy not yet measured
Citations
Cites
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Survey of Hallucination in Natural Language Generation
Ji, Z., Lee, N., Frieske, R., Yu, T., Su, D., Xu, Y., Ishii, E., Bang, Y. J., Madotto, A., & Fung, P. (2023) · ACM Computing Surveys · doi:10.1145/3571730 · Cited by 5,025 · cited 1×
“Nevertheless, the “implicit representation” of knowledge in LLM has also been shown to generate non-factual information despite linguistically coherent answers (i.e. “hallucination”) as a response to the input prompt (Maynez et al. 2020, Raunak et al. 2021, Ji et al. 2023).”
BackgroundChain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2201.11903 · Cited by 4,263
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083 · cited 1×
“This approach has led to the creation of models such as PubMedBERT (Lee et al. 2020, Gu et al. 2021) BlueBERT (Peng et al. 2019), SciBERT (Beltagy et al. 2019), ClinicalBERT (Huang et al. 2019), BioGPT (Luo et al. 2022), Med-PaLM (Singhal et al. 2022), and BioMedGPT (Luo et al. 2023).”
MethodRetrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Lewis, P., Perez, E., Piktus, A., Petroni, F., Karpukhin, V., Goyal, N., Küttler, H., Lewis, M., Yih, W.-T., Rocktäschel, T., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.11401 · Cited by 3,101
Piñero, J., Bravo, À., Queralt-Rosinach, N., Gutiérrez-Sacristán, A., Deu-Pons, J., Centeno, E., García-García, J., Sanz, F., & Furlong, L. I. (2017) · Nucleic Acids Research · doi:10.1093/nar/gkw943 · Cited by 2,680
Llama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Cited by
Retrieval augmented generation for large language models in healthcare: A systematic review
Amugongo, L. M., Mascheroni, P., Brooks, S., Doering, S., & Seidel, J. (2025) · PLOS Digital Health · doi:10.1371/journal.pdig.0000877 · Cited by 267
A survey on knowledge-oriented retrieval-augmented generation
Cheng, M., Luo, Y., Ouyang, J., Liu, Q., Liu, H., Li, L., Yu, S., Zhang, B., Cao, J., Ma, J., et al. (2025) · arXiv · doi:10.48550/arxiv.2503.10677 · Cited by 140
Zhao, X., Liu, S., Yang, S.-Y., & Miao, C. (2025) · Proceedings of the ACM on Web Conference 2025 · doi:10.1145/3696410.3714782 · Cited by 116
A comprehensive survey on integrating large language models with knowledge-based methods
Yang, W., Some, L., Bain, M., & Kang, B. H. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.113503 · Cited by 154
Prompt Engineering in Clinical Practice: Tutorial for Clinicians
Liu, J., Liu, F., Wang, C., & Liu, S. (2025) · Journal of Medical Internet Research · doi:10.2196/72644 · Cited by 76
Metadata
- Authors
- Soman, K., Rose, P. W., Morris, J. H., Akbas, R. E., Smith, B., Peetoom, B., Villouta-Reyes, C., Cerono, G., Shi, Y., Rizk-Jackson, A., Israni, S., Nelson, C. A., Huang, S., & Baranzini, S. E.
- Affiliations
- University of California, San Francisco (US)
- San Diego Supercomputer Center (US)
- Institute for Systems Biology (US)
- Bakar Computational Health Sciences Institute, University of California , San Francisco, CA 94158,
- Mate Bioservices, Inc. Swallowtail Ct. , Brisbane, CA 94005,
- Corresponding author
- Baranzini, Sergio E
- Venue
- Bioinformatics
- Publisher
- Oxford University Press (OUP)
- Published
- 2024-09
- Volume
- 40
- Issue
- 9
- ISSN
- 1367-4803 (ISSN-L)
- 1367-4811
- PMC
- PMC11441322
- OpenAlex
- W4402567773
- Cited by
- 135
- References
- 35
- Citations by year
- 2026: 61 · 2025: 63 · 2024: 9
- FWCI
- 10.72
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Bioinformatics (publishedVersion, cc-by)
- PubMed (publishedVersion)
- eScholarship (California Digital Library) (submittedVersion, cc-by)
- PubMed Central (submittedVersion, cc-by)
- Funders
- National Science Foundation (NSF_2033569)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Advanced Graph Neural Networks
- Keywords
- knowledge graph retrieval-augmented generation, prompt generation, large language models, biomedical knowledge graphs, context extraction, Llama 2, GPT-4, GPT-3.5-turbo
- MeSH terms
- Algorithms, Humans, Natural Language Processing, Computational Biology
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Biomedical knowledge graph-optimized prompt generation for large language models. https://app.cochat.ai/papers/10.1093/bioinformatics/btae560
- The paper
- Soman, K., Rose, P. W., Morris, J. H., Akbas, R. E., Smith, B., Peetoom, B., Villouta-Reyes, C., Cerono, G., Shi, Y., Rizk-Jackson, A., Israni, S., Nelson, C. A., Huang, S., & Baranzini, S. E. (2024). Biomedical knowledge graph-optimized prompt generation for large language models. Bioinformatics. https://doi.org/10.1093/bioinformatics/btae560
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
