

The DOI matches its Crossref record; 38 of the 38 references it cites were found in a registry or an index.
Using AI-generated suggestions from ChatGPT to optimize clinical decision support
Open accessAbstract
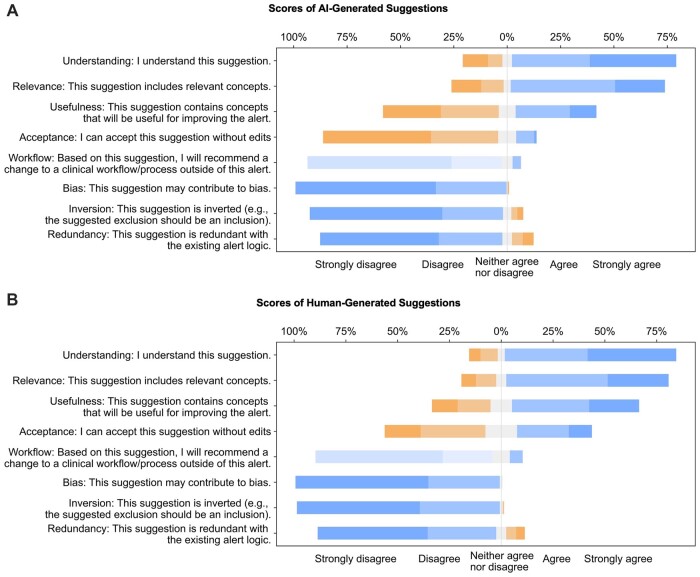
Objective: To determine if ChatGPT can generate useful suggestions for improving clinical decision support (CDS) logic and to assess noninferiority compared to human-generated suggestions. Methods: We supplied summaries of CDS logic to ChatGPT, an artificial intelligence (AI) tool for question answering that uses a large language model, and asked it to generate suggestions. We asked human clinician reviewers to review the AI-generated suggestions as well as human-generated suggestions for improving the same CDS alerts, and rate the suggestions for their usefulness, acceptance, relevance, understanding, workflow, bias, inversion, and redundancy. Results: Five clinicians analyzed 36 AI-generated suggestions and 29 human-generated suggestions for 7 alerts. Of the 20 suggestions that scored highest in the survey, 9 were generated by ChatGPT. The suggestions generated by AI were found to offer unique perspectives and were evaluated as highly understandable and relevant, with moderate usefulness, low acceptance, bias, inversion, redundancy. Conclusion: AI-generated suggestions could be an important complementary part of optimizing CDS alerts, can identify potential improvements to alert logic and support their implementation, and may even be able to assist experts in formulating their own suggestions for CDS improvement. ChatGPT shows great potential for using large language models and reinforcement learning from human feedback to improve CDS alert logic and potentially other medical areas involving complex, clinical logic, a key step in the development of an advanced learning health system.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The integration of AI-powered tools into clinical pharmacy practices could bolster efficiency, decision-making, and patient outcomes.9”
From ChatGPT and Clinical Training: Perception, Concerns, and Practice of Pharm-D Students (2023) · cites this paper as [9]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
A guideline of selecting and reporting intraclass correlation coefficients for reliability research
Koo, T. K., & Li, M. Y. (2016) · Journal of Chiropractic Medicine · doi:10.1016/j.jcm.2016.02.012 · Cited by 31,709
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
A General Inductive Approach for Analyzing Qualitative Evaluation Data
Thomas, D. R. (2006) · American Journal of Evaluation · doi:10.1177/1098214005283748 · Cited by 10,858
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Kung, T. H., Cheatham, M., ChatGPT, Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., et al. (2022) · doi:10.1101/2022.12.19.22283643 · Cited by 4,115
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
Kawamoto, K., Houlihan, C. A., Balas, E. A., & Lobach, D. F. (2005) · BMJ · doi:10.1136/bmj.38398.500764.8f · Cited by 2,703
Effect of Clinical Decision-Support Systems: A Systematic Review
Bright, T. J., Wong, A., Dhurjati, R., Bristow, E., Bastian, L., Coeytaux, R. R., Samsa, G., Hasselblad, V., Williams, J. W., Musty, M. D., et al. (2012) · Annals of Internal Medicine · doi:10.7326/0003-4819-157-1-201207030-00450 · Cited by 1,200
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185
Research works printed but not linked: 1
- de Winter, 2010, Five-point Likert items: t test versus Mann-Whitney-Wilcoxon, Pract Assess Res Eval, 15, 11
Cited by
Accuracy and Reliability of Chatbot Responses to Physician Questions
Goodman, R. S., Patrinely, J. R., Stone, C. A., Zimmerman, E., Donald, R. R., Chang, S. S., Berkowitz, S. T., Finn, A. P., Jahangir, E., Scoville, E. A., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.36483 · Cited by 484
Tam, T. Y. C., Sivarajkumar, S., Kapoor, S., Stolyar, A. V., Polanska, K., McCarthy, K. R., Osterhoudt, H., Wu, X., Visweswaran, S., Fu, S., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01258-7 · Cited by 424
Generative AI in Medicine and Healthcare: Promises, Opportunities and Challenges
Zhang, P., & Kamel Boulos, M. N. (2023) · Future Internet · doi:10.3390/fi15090286 · Cited by 411
“Through their applications in clinical decision support, GPT models can assist health-care professionals in formulating their suggestions for optimizing their decision-making, leading to improved patient outcomes and the overall quality of healthcare services [3].”
Ma, X., & Huo, Y. (2023) · Technology in Society · doi:10.1016/j.techsoc.2023.102362 · Cited by 346
Generative AI Literacy: Twelve Defining Competencies
Annapureddy, R., Fornaroli, A., & Gatica-Perez, D. (2025) · Digital Government: Research and Practice · doi:10.1145/3685680 · Cited by 333
Metadata
- Authors
- Liu, S., Wright, A. P., Patterson, B. L., Wanderer, J. P., Turer, R. W., Nelson, S. D., McCoy, A. B., Sittig, D. F., & Wright, A.
- Affiliations
- Vanderbilt University Medical Center (US)
- The University of Texas Southwestern Medical Center (US)
- The University of Texas Health Science Center at Houston (US)
- Corresponding author
- Liu, Siru
- ORCID
- Venue
- Journal of the American Medical Informatics Association
- Publisher
- Oxford University Press (OUP)
- Published
- 2023-04-22
- Volume
- 30
- Issue
- 7
- Pages
- 1237-1245
- ISSN
- 1067-5027 (ISSN-L)
- 1527-974X
- PMC
- PMC10280357
- OpenAlex
- W4366769280
- Cited by
- 397
- References
- 38
- Citations by year
- 2026: 64 · 2025: 126 · 2024: 144 · 2023: 61
- FWCI
- 15.73
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Journal of the American Medical Informatics Association (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Digital Commons-TMC (Texas Medical Center) (submittedVersion)
- Funders
- NIH (K99LM014097-01, R01AG062499-01, R01LM013995-01)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Electronic Health Records Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- ChatGPT, clinical decision support, large language models, non-inferiority, reinforcement learning from human feedback, learning health systems
- MeSH terms
- Learning Health System, Artificial Intelligence, Humans, Language, Decision Support Systems, Clinical, Workflow
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Using AI-generated suggestions from ChatGPT to optimize clinical decision support. https://app.cochat.ai/papers/10.1093/jamia/ocad072
- The paper
- Liu, S., Wright, A. P., Patterson, B. L., Wanderer, J. P., Turer, R. W., Nelson, S. D., McCoy, A. B., Sittig, D. F., & Wright, A. (2023). Using AI-generated suggestions from ChatGPT to optimize clinical decision support. Journal of the American Medical Informatics Association. https://doi.org/10.1093/jamia/ocad072
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
