

Using AI-generated suggestions from ChatGPT to optimize clinical decision support
Open accessThe DOI matches its Crossref record; 39 of the 39 references it cites were found in a registry or an index.
Abstract
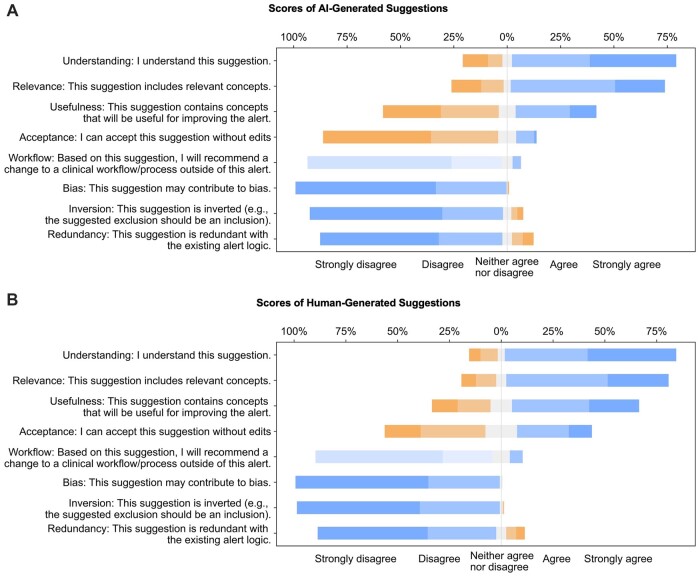
Objective: To determine if ChatGPT can generate useful suggestions for improving clinical decision support (CDS) logic and to assess noninferiority compared to human-generated suggestions. Methods: We supplied summaries of CDS logic to ChatGPT, an artificial intelligence (AI) tool for question answering that uses a large language model, and asked it to generate suggestions. We asked human clinician reviewers to review the AI-generated suggestions as well as human-generated suggestions for improving the same CDS alerts, and rate the suggestions for their usefulness, acceptance, relevance, understanding, workflow, bias, inversion, and redundancy. Results: Five clinicians analyzed 36 AI-generated suggestions and 29 human-generated suggestions for 7 alerts. Of the 20 suggestions that scored highest in the survey, 9 were generated by ChatGPT. The suggestions generated by AI were found to offer unique perspectives and were evaluated as highly understandable and relevant, with moderate usefulness, low acceptance, bias, inversion, redundancy. Conclusion: AI-generated suggestions could be an important complementary part of optimizing CDS alerts, can identify potential improvements to alert logic and support their implementation, and may even be able to assist experts in formulating their own suggestions for CDS improvement. ChatGPT shows great potential for using large language models and reinforcement learning from human feedback to improve CDS alert logic and potentially other medical areas involving complex, clinical logic, a key step in the development of an advanced learning health system.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The integration of AI-powered tools into clinical pharmacy practices could bolster efficiency, decision-making, and patient outcomes.9”
From ChatGPT and Clinical Training: Perception, Concerns, and Practice of Pharm-D Students (2023) · cites this paper as [9]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
A guideline of selecting and reporting intraclass correlation coefficients for reliability research
Koo, T. K., & Li, M. Y. (2016) · Journal of Chiropractic Medicine · doi:10.1016/j.jcm.2016.02.012 · Cited by 31,709
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
A General Inductive Approach for Analyzing Qualitative Evaluation Data
Thomas, D. R. (2006) · American Journal of Evaluation · doi:10.1177/1098214005283748 · Cited by 10,858
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Kung, T. H., Cheatham, M., ChatGPT, Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., et al. (2022) · doi:10.1101/2022.12.19.22283643 · Cited by 4,115
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
Kawamoto, K., Houlihan, C. A., Balas, E. A., & Lobach, D. F. (2005) · BMJ · doi:10.1136/bmj.38398.500764.8f · Cited by 2,703
Effect of Clinical Decision-Support Systems: A Systematic Review
Bright, T. J., Wong, A., Dhurjati, R., Bristow, E., Bastian, L., Coeytaux, R. R., Samsa, G., Hasselblad, V., Williams, J. W., Musty, M. D., et al. (2012) · Annals of Internal Medicine · doi:10.7326/0003-4819-157-1-201207030-00450 · Cited by 1,200
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185
Research works printed but not linked: 1
- de Winter, 2010, Five-point Likert items: t test versus Mann-Whitney-Wilcoxon, Pract Assess Res Eval, 15, 11
Cited by
Dwivedi, Y. K., Pandey, N., Currie, W., & Micu, A. (2024) · International Journal of Contemporary Hospitality Management · doi:10.1108/ijchm-05-2023-0686 · Cited by 570
Ethical Considerations of Using ChatGPT in Health Care
Wang, C., Liu, S., Yang, H., Guo, J., Wu, Y., & Liu, J. (2023) · Journal of Medical Internet Research · doi:10.2196/48009 · Cited by 541
Self-citationUnlocking the opportunities through ChatGPT Tool towards ameliorating the education system
Javaid, M., Haleem, A., Singh, R. P., Khan, S., & Khan, I. H. (2023) · BenchCouncil Transactions on Benchmarks, Standards and Evaluations · doi:10.1016/j.tbench.2023.100115 · Cited by 535
Utility of ChatGPT in Clinical Practice
Liu, J., Wang, C., & Liu, S. (2023) · Journal of Medical Internet Research · doi:10.2196/48568 · Cited by 505
Self-citationAccuracy and Reliability of Chatbot Responses to Physician Questions
Goodman, R. S., Patrinely, J. R., Stone, C. A., Zimmerman, E., Donald, R. R., Chang, S. S., Berkowitz, S. T., Finn, A. P., Jahangir, E., Scoville, E. A., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.36483 · Cited by 484
ChatGPT in healthcare: A taxonomy and systematic review
Li, J., Dada, A., Puladi, B., Kleesiek, J., & Egger, J. (2024) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2024.108013 · Cited by 452
Tam, T. Y. C., Sivarajkumar, S., Kapoor, S., Stolyar, A. V., Polanska, K., McCarthy, K. R., Osterhoudt, H., Wu, X., Visweswaran, S., Fu, S., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01258-7 · Cited by 424
“Liu et al. combined the -Whitne- Manny Wilcoxon test and the Kruskal – Wallis test for evaluating the reviewer ratings for the AI-generated suggestions 5 .”
MethodGenerative AI in Medicine and Healthcare: Promises, Opportunities and Challenges
Zhang, P., & Kamel Boulos, M. N. (2023) · Future Internet · doi:10.3390/fi15090286 · Cited by 411
“Through their applications in clinical decision support, GPT models can assist health-care professionals in formulating their suggestions for optimizing their decision-making, leading to improved patient outcomes and the overall quality of healthcare services [3].”
Ma, X., & Huo, Y. (2023) · Technology in Society · doi:10.1016/j.techsoc.2023.102362 · Cited by 346
A Survey of GPT-3 Family Large Language Models Including ChatGPT and GPT-4
Kalyan, K. S. (2024) · Natural Language Processing Journal · doi:10.1016/j.nlp.2023.100048 · Cited by 335
Generative AI Literacy: Twelve Defining Competencies
Annapureddy, R., Fornaroli, A., & Gatica-Perez, D. (2025) · Digital Government: Research and Practice · doi:10.1145/3685680 · Cited by 333
Leveraging large language models for decision support in personalized oncology
Benary, M., Wang, X. D., Schmidt, M., Soll, D., Hilfenhaus, G., Nassir, M., Sigler, C., Knödler, M., Keller, U., Beule, D., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.43689 · Cited by 306
Large Language Models for Chatbot Health Advice Studies: A Systematic Review
Huo, B., Boyle, A., Marfo, N., Tangamornsuksan, W., Steen, J. P., McKechnie, T., Lee, Y., Mayol, J., Antoniou, S. A., Thirunavukarasu, A. J., et al. (2025) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.57879 · Cited by 283
Retrieval-augmented generation for generative artificial intelligence in health care
Yang, R., Ning, Y., Keppo, E., Liu, M., Hong, C., Bitterman, D. S., Ong, J. C. L., Ting, D. S. W., & Liu, N. (2025) · npj Health Systems · doi:10.1038/s44401-024-00004-1 · Cited by 269
Yu, P., Xu, H., Hu, X., & Deng, C. (2023) · Healthcare · doi:10.3390/healthcare11202776 · Cited by 257
Moulaei, K., Yadegari, A., Baharestani, M., Farzanbakhsh, S., Sabet, B., & Reza Afrash, M. (2024) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2024.105474 · Cited by 244
A Comprehensive Survey of Foundation Models in Medicine
Khan, W., Leem, S., See, K. B., Wong, J. K., Zhang, S., & Fang, R. (2025) · IEEE Reviews in Biomedical Engineering · doi:10.1109/rbme.2025.3531360 · Cited by 214
AI for Decision Support: Balancing Accuracy, Transparency, and Trust Across Sectors
Kővári, A. (2024) · Information · doi:10.3390/info15110725 · Cited by 213
Tun, H. M., Rahman, H. A., Naing, L., & Malik, O. A. (2025) · Journal of Medical Internet Research · doi:10.2196/69678 · Cited by 210
The Potential and Concerns of Using AI in Scientific Research: ChatGPT Performance Evaluation
Khlaif, Z. N., Mousa, A., Hattab, M. K., Itmazi, J., Hassan, A. A., Sanmugam, M., & Ayyoub, A. (2023) · JMIR Medical Education · doi:10.2196/47049 · Cited by 205
“Therefore, AI-generated text tools can be integrated into the medical curriculum and can be used in medical research [49].”
BackgroundEvaluation of ChatGPT-generated medical responses: A systematic review and meta-analysis
Wei, Q., Yao, Z., Cui, Y., Wei, B., Jin, Z., & Xu, X. (2024) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2024.104620 · Cited by 201
Liu, S., McCoy, A. B., & Wright, A. (2025) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocaf008 · Cited by 200
Self-citationAI Hallucinations: A Misnomer Worth Clarifying
Maleki, N., Padmanabhan, B., & Dutta, K. (2024) · 2024 IEEE Conference on Artificial Intelligence (CAI) · doi:10.1109/cai59869.2024.00033 · Cited by 194
Assessing the research landscape and clinical utility of large language models: a scoping review
Park, Y.-J., Pillai, A., Deng, J., Guo, E., Gupta, M., Paget, M., & Naugler, C. (2024) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-024-02459-6 · Cited by 187
Temsah, M.-H., Aljamaan, F., Malki, K. H., Alhasan, K., Altamimi, I., Aljarbou, R., Bazuhair, F., Alsubaihin, A., Abdulmajeed, N., Alshahrani, F. S., et al. (2023) · Healthcare · doi:10.3390/healthcare11131812 · Cited by 179
Wang, L., Wan, Z., Ni, C., Song, Q., Li, Y., Clayton, E., Malin, B., & Yin, Z. (2024) · Journal of Medical Internet Research · doi:10.2196/22769 · Cited by 165
Caruccio, L., Cirillo, S., Polese, G., Solimando, G., Sundaramurthy, S., & Tortora, G. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121186 · Cited by 153
Williamson, S. M., & Prybutok, V. (2024) · Information · doi:10.3390/info15060299 · Cited by 146
Assessing the capabilities of ChatGPT to improve additive manufacturing troubleshooting
Badini, S., Regondi, S., Frontoni, E., & Pugliese, R. (2023) · Advanced Industrial and Engineering Polymer Research · doi:10.1016/j.aiepr.2023.03.003 · Cited by 134
Recent Advances in Large Language Models for Healthcare
Nassiri, K., & Akhloufi, M. A. (2024) · BioMedInformatics · doi:10.3390/biomedinformatics4020062 · Cited by 134
Mathis, W. S., Zhao, S., Pratt, N., Weleff, J., & Paoli, S. D. (2024) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2024.108356 · Cited by 131
Yang, Z., Xu, X., Yao, B., Rogers, E., Zhang, S., Intille, S., Shara, N., Gao, G. G., & Wang, D. (2024) · Proceedings of the ACM on Interactive, Mobile, Wearable and Ubiquitous Technologies · doi:10.1145/3659625 · Cited by 120
Huang, Y., Gomaa, A., Semrau, S., Haderlein, M., Lettmaier, S., Weissmann, T., Grigo, J., Tkhayat, H. B., Frey, B., Gaipl, U., et al. (2023) · Frontiers in Oncology · doi:10.3389/fonc.2023.1265024 · Cited by 112
Wosny, M., Strasser, L. M., & Hastings, J. (2023) · JMIR Human Factors · doi:10.2196/50357 · Cited by 110
Large Language Model–Based Responses to Patients’ In-Basket Messages
Small, W. R., Wiesenfeld, B., Brandfield-Harvey, B., Jonassen, Z., Mandal, S., Stevens, E. R., Major, V. J., Lostraglio, E., Szerencsy, A., Jones, S., et al. (2024) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.22399 · Cited by 106
ChatGPT and Clinical Decision Support: Scope, Application, and Limitations
Ferdush, J., Begum, M., & Hossain, S. T. (2023) · Annals of Biomedical Engineering · doi:10.1007/s10439-023-03329-4 · Cited by 98
Pardos, Z. A., & Bhandari, S. (2024) · PLOS ONE · doi:10.1371/journal.pone.0304013 · Cited by 97
“Among its many healthcare applications, ChatGPT has shown effectiveness in generating suggestions for clinical decision support and creating differential-diagnosis lists for cases involving common chief complaints [38, 39].”
BackgroundKhan, N., Khan, Z., Koubaa, A., Khan, M. K., & Salleh, R. B. (2024) · Connection Science · doi:10.1080/09540091.2024.2353630 · Cited by 97
Brown, K. E., Yan, C., Li, Z., Zhang, X., Collins, B. X., Chen, Y., Clayton, E. W., Kantarcıoğlu, M., Vorobeychik, Y., & Malin, B. (2025) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocaf038 · Cited by 89
Wu, Y., Wu, M., Wang, C., Lin, J., Liu, J., & Liu, S. (2024) · JMIR Medical Informatics · doi:10.2196/54811 · Cited by 87
Self-citationOniani, D., Wu, X., Visweswaran, S., Kapoor, S., Kooragayalu, S., Polanska, K., & Wang, Y. (2024) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi61247.2024.00111 · Cited by 87
Leveraging large language models for generating responses to patient messages—a subjective analysis
Liu, S., McCoy, A. B., Wright, A. P., Carew, B., Genkins, J. Z., Huang, S. S., Peterson, J. F., Steitz, B., & Wright, A. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae052 · Cited by 86
Self-citationFaruk, L. I. D., Rohan, R., Ninrutsirikun, U., & Pal, D. (2023) · doi:10.1145/3628454.3629552 · Cited by 85
Fatima, A., Shafique, M. A., Alam, K., Fadlalla Ahmed, T. K., & Mustafa, M. S. (2024) · Medicine · doi:10.1097/md.0000000000039250 · Cited by 81
The Potential Applications and Challenges of ChatGPT in the Medical Field
Mu, Y., & He, D. (2024) · International Journal of General Medicine · doi:10.2147/ijgm.s456659 · Cited by 78
Ethical implications of AI in the Metaverse
Zhuk, A. (2024) · AI and Ethics · doi:10.1007/s43681-024-00450-5 · Cited by 78
AI with agency: a vision for adaptive, efficient, and ethical healthcare
Fuentes, V. G. H., Karim, H. B. A., Tan, M. J. T., & AlDahoul, N. (2025) · Frontiers in Digital Health · doi:10.3389/fdgth.2025.1600216 · Cited by 77
Abdullahi, T., Singh, R., & Eickhoff, C. (2024) · JMIR Medical Education · doi:10.2196/51391 · Cited by 76
“Consequently, we surmise that LLMs are not yet ready to be used as stand-alone tools, which aligns with the findings of previous studies [5,17,18].”
BackgroundResultInfluentialPrompt Engineering in Clinical Practice: Tutorial for Clinicians
Liu, J., Liu, F., Wang, C., & Liu, S. (2025) · Journal of Medical Internet Research · doi:10.2196/72644 · Cited by 76
Self-citationYan, C., Grabowska, M. E., Dickson, A. L., Li, B., Wen, Z., Roden, D. M., Michael Stein, C., Embí, P. J., Peterson, J. F., Feng, Q., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01038-3 · Cited by 73
AI in health: keeping the human in the loop
Henry, S. B. (2023) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocad091 · Cited by 73
Large language models and generative AI in telehealth: a responsible use lens
Pool, J., Indulska, M., & Sadiq, S. W. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae035 · Cited by 69
Evaluating large language models and agents in healthcare: key challenges in clinical applications
Chen, X., Xiang, J., Lu, S., Liu, Y., He, M., & Shi, D. (2025) · Intelligent Medicine · doi:10.1016/j.imed.2025.03.002 · Cited by 68
Human–large language model collaboration in clinical medicine: a systematic review and meta-analysis
Wang, G., Zhang, K., Jiang, J., Wang, C., Bi, H., Liang, H., Qi, Z., Huang, Y., Li, Y., & Yang, X. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02382-2 · Cited by 67
Reasoning with large language models for medical question answering
Lucas, M. M., Yang, J., Pomeroy, J. K., & Yang, C. C. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae131 · Cited by 66
Two artificial intelligence models underperform on examinations in a veterinary curriculum
Coleman, M. C., & Moore, J. N. (2024) · Journal of the American Veterinary Medical Association · doi:10.2460/javma.23.12.0666 · Cited by 65
Wind of change: how ChatGPT and big data can reshape the knowledge management paradigm?
Sumbal, M. S., Amber, Q., Tariq, A., Raziq, M. M., & Tsui, E. (2024) · Industrial Management & Data Systems · doi:10.1108/imds-06-2023-0360 · Cited by 65
Salah, M., Abdelfattah, F., & Halbusi, H. A. (2024) · Current Opinion in Psychology · doi:10.1016/j.copsyc.2024.101872 · Cited by 65
Creative Use of OpenAI in Education: Case Studies from Game Development
French, F., Levi, D., Maczo, C., Simonaityte, A., Triantafyllidis, S., & Varda, G. (2023) · Multimodal Technologies and Interaction · doi:10.3390/mti7080081 · Cited by 64
Mendel, T., Singh, N., Mann, D. M., Wiesenfeld, B., & Nov, O. (2025) · Journal of Medical Internet Research · doi:10.2196/64290 · Cited by 64
“LLMs, such as ChatGPT, have demonstrated promising performance in clinical decision-making [11] and diagnosis [12].”
Large language models for oncological applications
Sorin, V., Barash, Y., Konen, E., & Klang, E. (2023) · Journal of Cancer Research and Clinical Oncology · doi:10.1007/s00432-023-04824-w · Cited by 64
ChatGPT: a game changer for knowledge management in organizations
Sumbal, M. S., & Amber, Q. (2024) · Kybernetes · doi:10.1108/k-06-2023-1126 · Cited by 63
Qualitative evaluation of artificial intelligence-generated weight management diet plans
Kim, D. W., Park, J. S., Sharma, K., Velazquez, A., Li, L., Ostrominski, J. W., Tran, T., Peréz, R. H. S., & Shin, J. (2024) · Frontiers in Nutrition · doi:10.3389/fnut.2024.1374834 · Cited by 61
Large language models and synthetic health data: progress and prospects
Smolyak, D., Bjarnadóttir, M. V., Crowley, K., & Agarwal, R. (2024) · JAMIA Open · doi:10.1093/jamiaopen/ooae114 · Cited by 60
RARE: Retrieval-Augmented Reasoning Enhancement for Large Language Models
Tran, H., Yao, Z., Yang, Z., Wang, J., Zhang, Y., Han, S., Ouyang, F., & Hong, Y. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.896 · Cited by 60
Chatbots for HIV Prevention and Care: a Narrative Review
van Heerden, A. C., Bosman, S., Swendeman, D. T., & Comulada, W. S. (2023) · Current HIV/AIDS Reports · doi:10.1007/s11904-023-00681-x · Cited by 59
Tracing the Influence of Large Language Models across the Most Impactful Scientific Works
Petroșanu, D.-M., Pîrjan, A., & Tăbușcă, A. (2023) · Electronics · doi:10.3390/electronics12244957 · Cited by 58
Evaluating the evaluators: a comparative study of AI and Teacher Assessments in Higher Education
Coşkun, T. K., & Alper, A. (2024) · Digital Education Review · doi:10.1344/der.2024.45.124-140 · Cited by 58
Korucu‐Kış, S. (2024) · Thinking Skills and Creativity · doi:10.1016/j.tsc.2024.101639 · Cited by 58
Using generative AI as decision-support tools: unraveling users’ trust and AI appreciation
Huynh, M.-T. (2024) · Journal of Decision System · doi:10.1080/12460125.2024.2428166 · Cited by 58
Kao, H.-J., Chien, T.-W., Wang, W.-C., Chou, W., & Chow, J. C. (2023) · Medicine · doi:10.1097/md.0000000000034068 · Cited by 57
“In a study, [24] a total of 36 AI-generated suggestions and 29 human-generated suggestions for 7 alerts were analyzed by 5 clinicians.”
BackgroundInfluentialShafik, W. (2023) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3693-0502-7.ch001 · Cited by 56
Generative artificial intelligence in graduate medical education
Janumpally, R., Nanua, S., Ngo, A., & Youens, K. (2025) · Frontiers in Medicine · doi:10.3389/fmed.2024.1525604 · Cited by 54
Opportunities and Challenges for Large Language Models in Primary Health Care
Qin, H., & Tong, Y. (2025) · Journal of Primary Care & Community Health · doi:10.1177/21501319241312571 · Cited by 54
Kim, J., Wang, K., Weng, C., & Liu, C. (2024) · The American Journal of Human Genetics · doi:10.1016/j.ajhg.2024.08.010 · Cited by 53
Rodriguez, D. V., Lawrence, K. S., González, J., Brandfield-Harvey, B., Xu, L., Tasneem, S., Levine, D. L., & Mann, D. (2024) · JMIR Human Factors · doi:10.2196/52885 · Cited by 54
Liu, X., Wu, J., Shao, A., Shen, W., Ye, P., Wang, Y., Ye, J., Jin, K., & Yang, J. (2024) · Journal of Medical Internet Research · doi:10.2196/51926 · Cited by 52
Analyzing evaluation methods for large language models in the medical field: a scoping review
Lee, J., Park, S., Shin, J., & Cho, B. (2024) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-024-02709-7 · Cited by 52
A publishing infrastructure for AI-assisted academic authoring
Pividori, M., & Greene, C. S. (2023) · doi:10.1101/2023.01.21.525030 · Cited by 52
Seo, J., Choi, D., Kim, T., Cha, W. C., Kim, M., Yoo, H., Oh, N., Yi, Y., Lee, K. H., & Choi, E. (2024) · Journal of Medical Internet Research · doi:10.2196/58329 · Cited by 52
The Application of ChatGPT in Medicine: A Scoping Review and Bibliometric Analysis
Wu, J., Ma, Y., Wang, J., & Xiao, M. (2024) · Journal of Multidisciplinary Healthcare · doi:10.2147/jmdh.s463128 · Cited by 52
Porkodi, S., & Cedro, T. L. (2025) · European Journal of Business Management and Research · doi:10.24018/ejbmr.2025.10.1.2535 · Cited by 52
ChatGPT and Clinical Training: Perception, Concerns, and Practice of Pharm-D Students
Zawiah, M., Al-Ashwal, F., Gharaibeh, L., Abu Farha, R., Alzoubi, K., Abu Hammour, K., Qasim, Q. A., & Abrah, F. (2023) · Journal of Multidisciplinary Healthcare · doi:10.2147/jmdh.s439223 · Cited by 51
“9 However, despite the promise, the accuracy, reliability, and practical viability of ChatGPT in real-world clinical pharmacy settings have yet to be comprehensively explored.”
BackgroundHumans are still better than ChatGPT: Case of the IEEEXtreme competition
Koubâa, A., Qureshi, B., Ammar, A., Khan, Z., Boulila, W., & Ghouti, L. (2023) · Heliyon · doi:10.1016/j.heliyon.2023.e21624 · Cited by 51
Chen, Y., Huang, X., Yang, F., Lin, H., Lin, H., Zheng, Z., Liang, Q., Zhang, J., & Li, X. (2024) · BMC Medical Education · doi:10.1186/s12909-024-06309-x · Cited by 50
A publishing infrastructure for Artificial Intelligence (AI)-assisted academic authoring
Pividori, M., & Greene, C. S. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae139 · Cited by 50
Brainstorming Will Never Be the Same Again—A Human Group Supported by Artificial Intelligence
Lavrič, F., & Škraba, A. (2023) · Machine Learning and Knowledge Extraction · doi:10.3390/make5040065 · Cited by 50
Lorenzi, A., Pugliese, G., Maniaci, A., Lechien, J. R., Allevi, F., Boscolo‐Rizzo, P., Vaira, L. A., & Saibene, A. M. (2024) · European Archives of Oto-Rhino-Laryngology · doi:10.1007/s00405-024-08746-2 · Cited by 50
Understanding natural language: Potential application of large language models to ophthalmology
Yang, Z., Wang, D., Zhou, F., Song, D., Zhang, Y., Jiang, J., Kong, K., Liu, X., Qiao, Y., Chang, R. T., et al. (2024) · Asia-Pacific Journal of Ophthalmology · doi:10.1016/j.apjo.2024.100085 · Cited by 50
Exploring Generative Artificial Intelligence Research: A Bibliometric Analysis Approach
Dwivedi, R., & Elluri, L. (2024) · IEEE Access · doi:10.1109/access.2024.3450629 · Cited by 50
Abi-Rafeh, J., Xu, H. H., Kazan, R., Tevlin, R., & Furnas, H. (2024) · Aesthetic Surgery Journal · doi:10.1093/asj/sjad260 · Cited by 49
Artificial Intelligence in Intensive Care Medicine: Toward a ChatGPT/GPT-4 Way?
Lu, Y., Wu, H., Qi, S., & Cheng, K. (2023) · Annals of Biomedical Engineering · doi:10.1007/s10439-023-03234-w · Cited by 49
Shao, C.-Y., Li, H., Liu, X.-L., Li, C., Yang, L.-Q., Zhang, Y.-J., Luo, J., & Zhao, J. (2023) · Interactive Journal of Medical Research · doi:10.2196/46900 · Cited by 49
Kedia, N., Sanjeev, S., Ong, J., & Chhablani, J. K. (2024) · Eye · doi:10.1038/s41433-023-02915-z · Cited by 49
Nwachukwu, B. U., Varady, N. H., Allen, A. A., Dines, J. S., Altchek, D. W., Williams, R. J., & Kunze, K. N. (2024) · Arthroscopy The Journal of Arthroscopic and Related Surgery · doi:10.1016/j.arthro.2024.07.040 · Cited by 49
Generative Artificial Intelligence in Anatomic Pathology
Brodsky, V., Ullah, E., Bychkov, A., Song, A. H., Walk, E. E., Louis, P., Rasool, G., Singh, R. S., Mahmood, F., Bui, M. M., et al. (2025) · Archives of Pathology & Laboratory Medicine · doi:10.5858/arpa.2024-0215-ra · Cited by 48
Exploring Capabilities of Large Language Models such as ChatGPT in Radiation Oncology
Dennstädt, F., Hastings, J., Putora, P. M., Vu, E., Fischer, G. F., Süveg, K., Glatzer, M., Riggenbach, E., Hà, H.-L., & Cihoric, N. (2024) · Advances in Radiation Oncology · doi:10.1016/j.adro.2023.101400 · Cited by 48
Diagnostic accuracy of large language models in psychiatry
Gargari, O. K., Fatehi, F., Mohammadi, I., Firouzabadi, S. R., Shafiee, A., & Habibi, G. (2024) · Asian Journal of Psychiatry · doi:10.1016/j.ajp.2024.104168 · Cited by 48
Evaluating the Diagnostic Accuracy and Management Recommendations of ChatGPT in Uveitis
Rojas-Carabali, W., Cifuentes-González, C., Wei, X., Putera, I., Sen, A., Thng, Z. X., Agrawal, R., Elze, T., Sobrin, L., Kempen, J. H., et al. (2024) · Ocular Immunology and Inflammation · doi:10.1080/09273948.2023.2253471 · Cited by 47
Bečulić, H., Begagić, E., Skomorac, R., Mašović, A., Selimović, E., & Pojskić, M. (2023) · Medicinski Glasnik · doi:10.17392/1661-23 · Cited by 47
Metadata
- Authors
- Liu, S., Wright, A. P., Patterson, B. L., Wanderer, J. P., Turer, R. W., Nelson, S. D., McCoy, A. B., Sittig, D. F., & Wright, A.
- Affiliations
- Vanderbilt University Medical Center (US)
- The University of Texas Southwestern Medical Center (US)
- The University of Texas Health Science Center at Houston (US)
- Corresponding author
- Liu, Siru
- ORCID
- Venue
- Journal of the American Medical Informatics Association
- Publisher
- Oxford University Press (OUP)
- Published
- 2023-04-22
- Volume
- 30
- Issue
- 7
- Pages
- 1237-1245
- ISSN
- 1067-5027 (ISSN-L)
- 1527-974X
- PMC
- PMC10280357
- OpenAlex
- W4366769280
- Cited by
- 397
- References
- 34
- Citations by year
- 2026: 64 · 2025: 126 · 2024: 144 · 2023: 61
- FWCI
- 15.73
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Journal of the American Medical Informatics Association (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Digital Commons-TMC (Texas Medical Center) (submittedVersion)
- Funders
- NIH (K99LM014097-01, R01AG062499-01, R01LM013995-01)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Electronic Health Records Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- ChatGPT, clinical decision support, large language models, non-inferiority, reinforcement learning from human feedback, learning health systems
- MeSH terms
- Learning Health System, Artificial Intelligence, Humans, Language, Decision Support Systems, Clinical, Workflow
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
