

The DOI matches its Crossref record; 8 of the 8 references it cites were found in a registry or an index.
DeepLoc 2.1: multi-label membrane protein type prediction using protein language models
Abstract
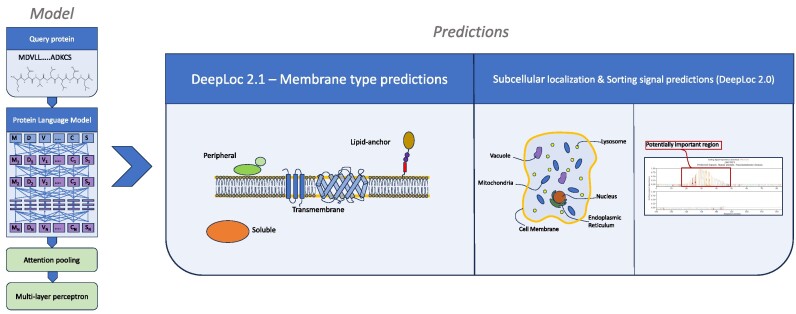
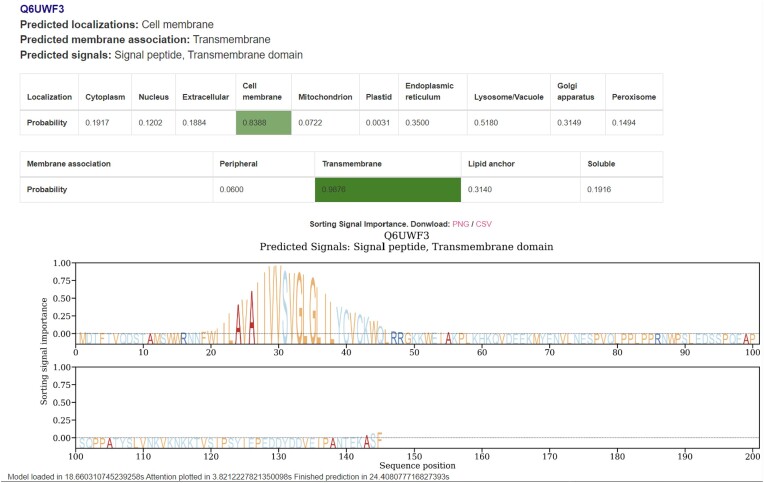
DeepLoc 2.0 is a popular web server for the prediction of protein subcellular localization and sorting signals. Here, we introduce DeepLoc 2.1, which additionally classifies the input proteins into the membrane protein types Transmembrane, Peripheral, Lipid-anchored and Soluble. Leveraging pre-trained transformer-based protein language models, the server utilizes a three-stage architecture for sequence-based, multi-label predictions. Comparative evaluations with other established tools on a test set of 4933 eukaryotic protein sequences, constructed following stringent homology partitioning, demonstrate state-of-the-art performance. Notably, DeepLoc 2.1 outperforms existing models, with the larger ProtT5 model exhibiting a marginal advantage over the ESM-1B model. The web server is available at https://services.healthtech.dtu.dk/services/DeepLoc-2.1.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Here, we identified 234 proteins with differential abundance in the TET2-super competitors compared to WT competitors (adjusted p<0.05, log2FC >0.5) (Figure 5D), 75 of which were classified as probable secreted proteins by the DeepLoc protein localization tool”
From A scalable in vitro cell competition model identifies preleukemic super competitor clones (2026) · cites this paper as Ødum et al, 2024
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
UniProt: the Universal Protein Knowledgebase in 2023
The UniProt Consortium, Bateman, A., Martin, M.-J., Orchard, S., Magrane, M., Ahmad, S., Alpi, E., Bowler-Barnett, E. H., Britto, R., Bye-A-Jee, H., et al. (2023) · Nucleic Acids Research · doi:10.1093/nar/gkac1052 · Cited by 7,210
Chicco, D., & Jurman, G. (2020) · BMC Genomics · doi:10.1186/s12864-019-6413-7 · Cited by 6,143 · cited 1×
“As opposed to other accuracy metrics, the threshold optimization using the MCC-score better accommodates label imbalance ( 22 ).”
Evolutionary-scale prediction of atomic level protein structure with a language model
Lin, Z., Akin, H., Rao, R., Hie, B., Zhu, Z., Lu, W., Smetanin, N., Verkuil, R., Kabeli, O., Shmueli, Y., et al. (2022) · doi:10.1101/2022.07.20.500902 · Cited by 5,990
How many drug targets are there?
Overington, J. P., Al-Lazikani, B., & Hopkins, A. L. (2006) · Nature Reviews Drug Discovery · doi:10.1038/nrd2199 · Cited by 3,505
Rives, A., Meier, J., Sercu, T., Goyal, S., Lin, Z., Liu, J., Guo, D., Ott, M., Zitnick, C. L., Ma, J., et al. (2021) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2016239118 · Cited by 3,286
Rives, A., Meier, J., Sercu, T., Goyal, S., Lin, Z., Liu, J., Guo, D., Ott, M., Zitnick, C. L., Ma, J., et al. (2019) · doi:10.1101/622803 · Cited by 3,280 · cited 2×
“We use sequence-based embeddings from the ProtT5 ( 6 ) and ESM-1B protein language models ( 7 ) and implement the same model architecture used by DeepLoc 2.0, performing interpretable attention pooling over sequence embeddings with discrete cosine transform regularization.”
InfluentialProtTrans: Toward Understanding the Language of Life Through Self-Supervised Learning
Elnaggar, A., Heinzinger, M., Dallago, C., Rehawi, G., Wang, Y., Jones, L., Gibbs, T., Feher, T., Angerer, C., Steinegger, M., et al. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2021.3095381 · Cited by 2,329
Transformer protein language models are unsupervised structure learners
Rao, R., Meier, J., Sercu, T., Ovchinnikov, S., & Rives, A. (2020) · doi:10.1101/2020.12.15.422761 · Cited by 341
Research works printed but not linked: 16
- Alberts, 2002, Membrane proteins
- Yin, 2016, Drugging membrane protein interactions, Annu. Rev. Biom. Eng., 18, 51, 10.1146/annurev-bioeng-092115-025322 · DOI
- Thumuluri, 2022, DeepLoc 2.0: multi-label subcellular localization prediction using protein language models, Nucleic Acids Res., 50, W228, 10.1093/nar/gkac278 · DOI
- Almagro Armenteros, 2017, DeepLoc: prediction of protein subcellular localization using deep learning, Bioinformatics, 33, 3387, 10.1093/bioinformatics/btx431 · DOI
- Wan, 2016, Mem-ADSVM: a two-layer multi-label predictor for identifying multi-functional types of membrane proteins, J. Theor. Biol., 398, 32, 10.1016/j.jtbi.2016.03.013 · DOI
- Pierleoni, 2011, MemPype: a pipeline for the annotation of eukaryotic membrane proteins, Nucleic Acids Res., 39, W375, 10.1093/nar/gkr282 · DOI
- Chou, 2007, MemType-2L: a web server for predicting membrane proteins and their types by incorporating evolution information through Pse-PSSM, Biochem. Biophys. Res. Commun., 360, 339, 10.1016/j.bbrc.2007.06.027 · DOI
- Vaswani, 2017, Attention is all you need, 5998
- Vig, 2021, BERTology meets biology: interpreting attention in protein language models
- Teufel, 2022, SignalP 6.0 predicts all five types of signal peptides using protein language models, Nat. Biotechnol., 40, 1023, 10.1038/s41587-021-01156-3 · DOI
- Almagro Armenteros, 2019, Detecting sequence signals in targeting peptides using deep learning, Life Sci. Alliance, 2, e201900429, 10.26508/lsa.201900429 · DOI
- Gíslason, 2021, Prediction of GPI-anchored proteins with pointer neural networks, Curr. Res. Biotechnol., 3, 6, 10.1016/j.crbiot.2021.01.001 · DOI
- Teufel, 2023, GraphPart: homology partitioning for biological sequence analysis, NAR Genom. Bioinform., 5, lqad088, 10.1093/nargab/lqad088 · DOI
- Tseng, 2020, Fourier-transform-based attribution priors improve the interpretability and stability of deep learning models for genomics, 1913
- Lin, 2020, Focal loss for dense object detection, IEEE T. Pattern Anal. Mach. Intel., 42, 318, 10.1109/TPAMI.2018.2858826 · DOI · Paper page
- Steinegger, 2017, MMseqs2 enables sensitive protein sequence searching for the analysis of massive data sets, Nat. Biotechnol., 35, 1026, 10.1038/nbt.3988 · DOI · Paper page
Cited by
Synergistic role of CSPBP and SGS1 in sporozoite entry into Aedes aegypti salivary glands
Morvay, A., Araújo, H. R. C., Capurro, M. L., & Burini, B. C. (2026) · Scientific Reports · doi:10.1038/s41598-026-46444-7
A scalable in vitro cell competition model identifies preleukemic super competitor clones
Cabrera-Cosme, L., Rubio-Lara, J. A., Bennett, E., Miłek, J., Baldreki, C., Dowle, A., Vijayabaskar, M. S., Davies, S. J., Taylor-Smith, E., Bain, F. M., et al. (2026) · doi:10.64898/2026.10.21.760611
Metadata
- Authors
- Ødum, M. T., Teufel, F., Thumuluri, V., Almagro Armenteros, J. J., Johansen, A. R., Winther, O., & Nielsen, H.
- Affiliations
- Section for Bioinformatics, Department of Health Technology, Technical University of Denmark , 2800 Kongens Lyngby, Denmark
- Bioinformatics Centre, Department of Biology, University of Copenhagen , 2200 Copenhagen, Denmark
- University of California , San Diego, CA 92093, USA
- Bristol Myers Squibb Company, Informatics and Predictive Sciences Research , Calle Isaac Newton 4, Sevilla 41092, Spain
- Department of Computer Science, Stanford University , Stanford, CA 94305, USA
- ORCID
- Nielsen, Henrik
- Venue
- Nucleic Acids Research
- Publisher
- Oxford University Press (OUP)
- Published
- 2024-04-08
- Volume
- 52
- Issue
- W1
- Pages
- W215-W220
- ISSN
- 0305-1048
- 1362-4962
- PMC
- PMC11223819
- Cited by
- 285
- References
- 8
- Language
- en
- Funders
- Novo Nordisk Foundation (NNF20OC0062606)
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: DeepLoc 2.1: multi-label membrane protein type prediction using protein language models. https://app.cochat.ai/papers/10.1093/nar/gkae237
- The paper
- Ødum, M. T., Teufel, F., Thumuluri, V., Almagro Armenteros, J. J., Johansen, A. R., Winther, O., & Nielsen, H. (2024). DeepLoc 2.1: multi-label membrane protein type prediction using protein language models. Nucleic Acids Research. https://doi.org/10.1093/nar/gkae237
