

The DOI matches its Crossref record; 1 of the 1 references it cites were found in a registry or an index.
TIS Transformer: Remapping the Human Proteome Using Deep Learning
Open accessPreprint — published as 10.1093/nargab/lqad021 · Paper page
Abstract
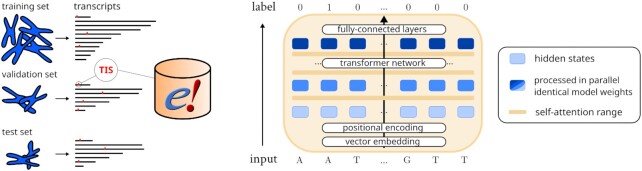
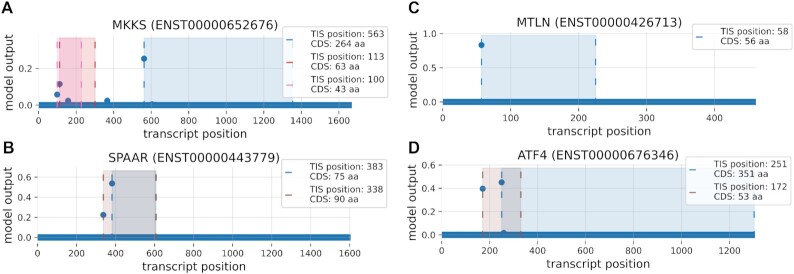
A bstract: The correct mapping of the proteome is an important step towards advancing our understanding of biological systems and cellular mechanisms. Methods that provide better mappings can fuel important processes such as drug discovery and disease understanding. Currently, true determination of translation initiation sites is primarily achieved by in vivo experiments. Here we propose TIS Transformer, a deep learning model for the determination of translation start sites solely utilizing the information embedded in the transcript nucleotide sequence. The method is built upon deep learning techniques first designed for natural language processing. We prove this approach to be best suited for learning the semantics of translation, outperforming previous approaches by a large margin. We demonstrate that limitations in the model performance is primarily due to the presence of low quality annotations against which the model is evaluated against. Advantages of the method are its ability to detect key features of the translation process and multiple coding sequences on a transcript. These include micropeptides encoded by short Open Reading Frames, either alongside a canonical coding sequence or within long non-coding RNAs. To demonstrate the use of our methods, we applied TIS Transformer to remap the full human proteome.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Highly accurate protein structure prediction with AlphaFold
Jumper, J., Evans, R., Pritzel, A., Green, T., Figurnov, M., Ronneberger, O., Tunyasuvunakool, K., Bates, R., Žídek, A., Potapenko, A., et al. (2021) · Nature · doi:10.1038/s41586-021-03819-2 · Cited by 43,764
Research works printed but not linked: 48
- Aken BL et al. 2016. The Ensembl Gene Annotation System. Database. 2016: · DOI · Paper page
- 2013, Translational Repression of the McKusickKaufman Syndrome Transcript by Unique Upstream Open Reading Frames Encoding Mitochondrial Proteins with Alternative Polyadenylation Sites, Biochimica et Biophysica Acta (BBA) - General Subjects, 1830, 2728, 10.1016/j.bbagen.2012.12.010 · DOI
- 10.1038/nrg3520 · DOI
- 10.1016/j.ab.2014.06.022 · DOI
- Cheng J , Dong L , and Lapata M. 2016. Long Short-Term Memory-Networks for Machine Reading. arXiv:1601.06733 [cs]. · DOI
- Choromanski K et al. 2021. Rethinking Attention with Performers. arXiv:2009.14794 [cs, stat]. · arXiv
- 10.1038/369371a0 · DOI
- 10.1016/j.molcel.2015.11.013 · DOI
- 2006, The Abundance of Short Proteins in the Mammalian Proteome, PLOS Genetics, 2, e52, 10.1371/journal.pgen.0020052 · DOI
- 10.1016/j.heliyon.2020.e04825 · DOI
- Jorgensen RA and Dorantes-Acosta AE. 2012. Conserved Peptide Upstream Open Reading Frames Are Associated with Regulatory Genes in Angiosperms. Frontiers in Plant Science. 0: · DOI
- 10.1016/j.compbiomed.2015.09.010 · DOI
- 2019, DeepGSR: An Optimized Deep-Learning Structure for the Recognition of Genomic Signals and Regions, Bioinformatics, 35, 1125, 10.1093/bioinformatics/bty752 · DOI
- 2018, MOXI Is a Mitochondrial Micropeptide That Enhances Fatty Acid β-Oxidation, Cell Reports, 23, 3701, 10.1016/j.celrep.2018.05.058 · DOI
- 10.1038/nature21034 · DOI
- 10.1038/s41587-022-01369-0 · DOI
- Mudge JM , Ruiz-Orera J , Prensner JR , Brunet MA , Gonzalez JM , et al. 2021. A Community-Driven Roadmap to Advance Research on Translated Open Reading Frames Detected by Ribo-Seq. bioRxiv. 2021.06.10.447896. · DOI
- Parikh A , Täckström O , Das D , and Uszkoreit J 2016. A Decomposable Attention Model for Natural Language Inference. In: Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing. Austin, Texas: Association for Computational Linguistics, pp. 2249–2255. · DOI
- 10.1002/bies.201400103 · DOI
- 2021, Most Non-Canonical Proteins Uniquely Populate the Proteome or Immunopeptidome, Cell Reports, 34, 108815, 10.1016/j.celrep.2021.108815 · DOI
- 10.1093/bioinformatics/btm177 · DOI
- 2018, Mitoregulin: A lncRNA-Encoded Microprotein That Supports Mitochondrial Supercomplexes and Respiratory Efficiency, Cell Reports, 23, 3710, 10.1016/j.celrep.2018.06.002 · DOI
- Sundararajan M , Taly A , and Yan Q. 2017. Axiomatic Attribution for Deep Networks. arXiv:1703.01365 [cs]. · arXiv
- 10.2527/jas2016.94supplement4184x · DOI · Paper page
- 2017, Attention Is All You Need, Advances in Neural Information Processing Systems, 30, 5998
- 2021, The Role of Micropeptides in Biology, Cellular and Molecular Life Sciences, 78, 3285, 10.1007/s00018-020-03740-3 · DOI
- Wang S , Li BZ , Khabsa M , Fang H , and Ma H. 2020. Linformer: Self-Attention with Linear Complexity. arXiv:2006.04768 [cs, stat]. · arXiv
- 10.1016/j.dsp.2021.103202 · DOI
- 10.1016/S0968-0004(03)00051-3 · DOI
- Xiong Y , Zeng Z , Chakraborty R , Tan M , Fung G , Li Y , and Singh V. 2021. Nystr\”omformer: A Nystr\”om-Based Algorithm for Approximating Self-Attention. arXiv:2102.03902 [cs]. · DOI · Paper page
- 10.1093/nar/gkv1157 · DOI
- 2020, Emerging Role of Long Noncoding RNA-Encoded Micropeptides in Cancer, Cancer Cell International, 20, 506, 10.1186/s12935-020-01589-x · DOI
- 10.1074/jbc.R116.733899 · DOI
- 2020, Advances in Neural Information Processing Systems, 33, 17283
- 10.1093/bioinformatics/btx247 · DOI
- 10.1093/bioinformatics/16.9.799 · DOI
- 10.1504/IJDMB.2018.094781 · DOI
- 10.1016/j.ab.2014.06.022 · DOI
- K. Choromanski , V. Likhosherstov , D. Dohan , X. Song , A. Gane , T. Sarlos , P. Hawkins , J. Davis , A. Mo-hiuddin , L. Kaiser , D. Belanger , L. Colwell , and A. Weller . Rethinking Attention with Performers. arXiv:2009.14794 [cs, stat], Mar. 2021. · arXiv
- 10.1016/j.heliyon.2020.e04825 · DOI
- 10.1016/j.compbiomed.2015.09.010 · DOI
- 10.1093/bioinformatics/bty752 · DOI
- 10.1038/s41587-022-01369-0 · DOI
- 10.1093/bioinformatics/btm177 · DOI
- 10.1016/j.dsp.2021.103202 · DOI
- 10.1093/bioinformatics/btx247 · DOI
- 10.1093/bioinformatics/16.9.799 · DOI
- 10.1504/IJDMB.2018.094781 · DOI
Metadata
- Authors
- Clauwaert, J., Gupta, R., McVey, Z., & Menschaert, G.
- Affiliations
- Ghent University (BE)
- Novo Nordisk (United Kingdom) (GB)
- Corresponding author
- Clauwaert, Jim
- Menschaert, Gerben
- Venue
- NAR Genomics and Bioinformatics
- Publisher
- openRxiv
- Published
- 2021-11-19
- Volume
- 5
- Issue
- 1
- Pages
- lqad021-lqad021
- ISSN
- 2631-9268 (ISSN-L)
- PMC
- PMC9985340
- OpenAlex
- W4323076266
- Cited by
- 26
- References
- 1
- Citations by year
- 2026: 8 · 2025: 6 · 2024: 3 · 2023: 9
- FWCI
- 2.32
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- NAR Genomics and Bioinformatics (publishedVersion, cc-by)
- bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Ghent University Academic Bibliography (Ghent University) (publishedVersion)
- Ghent University Academic Bibliography (Ghent University) (submittedVersion, cc-by)
- Funders
- Universiteit Gent
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › RNA and protein synthesis mechanisms
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Machine Learning in Bioinformatics
- Keywords
- translation initiation sites, transformer models, transcript sequences, micropeptides, open reading frames, long non-coding RNA, alternative translation initiation, annotation quality
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
