

The DOI matches its Crossref record; 22 of the 23 references it cites were found in a registry or an index.
Softermax: Hardware/Software Co-Design of an Efficient Softmax for Transformers
Open accessAbstract
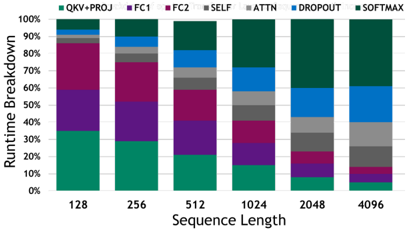
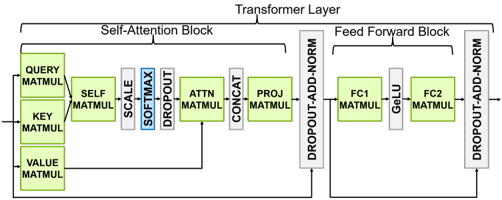
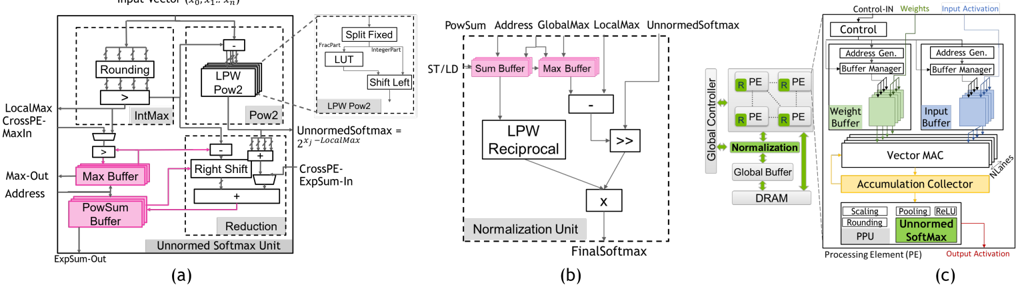
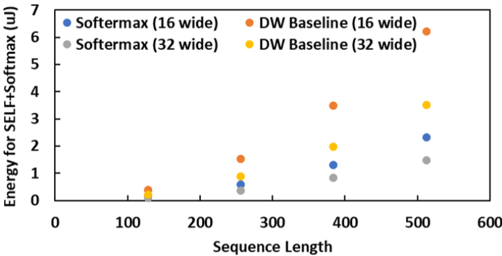
Transformers have transformed the field of natural language processing. Their superior performance is largely attributed to the use of stacked “self-attention” layers, each of which consists of matrix multiplies as well as softmax operations. As a result, unlike other neural networks, the softmax operation accounts for a significant fraction of the total run-time of Transformers. To address this, we propose Softermax, a hardware-friendly softmax design. Softermax consists of base replacement, low-precision softmax computations, and an online normalization calculation. We show Softermax results in 2.35x the energy efficiency at 0.90x the size of a comparable baseline, with negligible impact on network accuracy.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
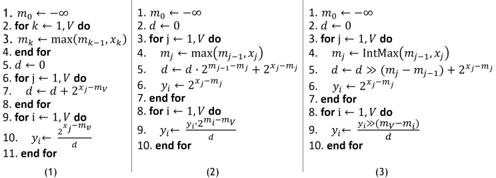
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Non-linear operations like Softmax, LayerNorm, and GELU, though less prevalent, present computational challenges on conventional hardware due to their complexity, potentially restricting the enhancement of end-to-end transformer inference [31].”
From Model Quantization and Hardware Acceleration for Vision Transformers: A Comprehensive Survey (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“A large portion of the inference time in ViT models is consumed by floating-point non-linear activations, normalizations, and the associated quantization and dequantization operations [31].”
From Model Quantization and Hardware Acceleration for Vision Transformers: A Comprehensive Survey (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“In addition, various approximation methods that hold floating-point arithmetic are presented [36, 50]; while they lower certain computational costs, they cannot meet the demands of integer arithmetic.”
From I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference (2023) · cites this paper as [36]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Due to the non-linearity, Softmax cannot follow the dyadic arithmetic pipeline discussed above, and the exponential arithmetic in Eq. 11 is typically unsupported by integer-only logic units [36].”
From I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference (2023) · cites this paper as [36]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter
Sanh, V., Debut, L., Chaumond, J., & Wolf, T. (2019) · arXiv · doi:10.48550/arxiv.1910.01108 · Cited by 4,653
In-Datacenter Performance Analysis of a Tensor Processing Unit
Jouppi, N. P., Young, C., Patil, N., Patterson, D., Agrawal, G., Bajwa, R., Bates, S., Bhatia, S., Boden, N., Borchers, A., et al. (2017) · Proceedings of the 44th Annual International Symposium on Computer Architecture · doi:10.1145/3079856.3080246 · Cited by 4,537
HuggingFace's Transformers: State-of-the-art Natural Language Processing
Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., et al. (2019) · arXiv · doi:10.48550/arxiv.1910.03771 · Cited by 3,347
In-Datacenter Performance Analysis of a Tensor Processing Unit
Jouppi, N. P., Young, C., Patil, N. P., Patterson, D. A., Agrawal, G., Bajwa, R. S., Bates, S., Bhatia, S., Boden, N., Borchers, A., et al. (2017) · ACM SIGARCH Computer Architecture News · doi:10.1145/3140659.3080246 · Cited by 1,541
Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism
Shoeybi, M., Patwary, M., Puri, R., LeGresley, P., Casper, J., & Catanzaro, B. (2019) · arXiv · doi:10.48550/arxiv.1909.08053 · Cited by 893
Research works printed but not linked: 2
- 2017, Nvidia tesla v100 gpu architecture
- radford, 2019, Language models are unsupervised multitask learners, OpenAIRE blog, 1, 9
Cited by
Sorted by citations
Yenduri, G., Ramalingam, M., Selvi, G. C., Supriya, Y., Srivastava, G., Maddikunta, P. K. R., Raj, G. D., Jhaveri, R. H., Prabadevi, B., Wang, W., et al. (2024) · IEEE Access · doi:10.1109/access.2024.3389497 · Cited by 916
I-ViT: Integer-only Quantization for Efficient Vision Transformer Inference
Li, Z., & Gu, Q. (2023) · 2023 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01565 · Cited by 141
“11 is typically unsupported by integer-only logic units [36].”
BackgroundMethodX-Former: In-Memory Acceleration of Transformers
Sridharan, S., Stevens, J. R., Roy, K., & Raghunathan, A. (2023) · IEEE Transactions on Very Large Scale Integration (VLSI) Systems · doi:10.1109/tvlsi.2023.3282046 · Cited by 74
Self-citationA 95.6-TOPS/W Deep Learning Inference Accelerator With Per-Vector Scaled 4-bit Quantization in 5 nm
Keller, B., Venkatesan, R., Dai, S. X., Tell, S. G., Zimmer, B., Sakr, C., Dally, W. J., Gray, C. T., & Khailany, B. (2023) · IEEE Journal of Solid-State Circuits · doi:10.1109/jssc.2023.3234893 · Cited by 66
Self-citationSaha, S., & Xu, L. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.130417 · Cited by 85
Metadata
- Authors
- Stevens, J. R., Venkatesan, R., Dai, S., Khailany, B., & Raghunathan, A.
- Affiliations
- Purdue University West Lafayette (US)
- Nvidia (United Kingdom) (GB)
- Venue
- 2021 58th ACM/IEEE Design Automation Conference (DAC)
- Publisher
- IEEE
- Published
- 2021-12-05
- Pages
- 469-474
- ISSN
- 0738-100X (ISSN-L)
- OpenAlex
- W3137649401
- Cited by
- 148
- References
- 23
- Citations by year
- 2026: 22 · 2025: 68 · 2024: 35 · 2023: 16 · 2022: 5 · 2021: 2
- FWCI
- 4.74
- Type
- conference paper
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- ACM/IEEE Design Automation Conference (DAC) (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by-nc-nd)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Hardware and Architecture › Parallel Computing and Optimization Techniques
- Physical Sciences › Engineering › Electrical and Electronic Engineering › Low-power high-performance VLSI design
- Keywords
- softmax, transformer models, hardware-software co-design, self-attention, low-precision arithmetic, energy efficiency, neural network acceleration
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
