

ModDrop: Adaptive Multi-Modal Gesture Recognition
Open accessThe DOI matches its Crossref record; 71 of the 77 references it cites were found in a registry or an index; 6 of the 18 sources its claims cite were checked for support.
Abstract
We present a method for gesture detection and localisation based on multi-scale and multi-modal deep learning. Each visual modality captures spatial information at a particular spatial scale (such as motion of the upper body or a hand), and the whole system operates at three temporal scales. Key to our technique is a training strategy which exploits: i) careful initialization of individual modalities; and ii) gradual fusion involving random dropping of separate channels (dubbed ModDrop) for learning cross-modality correlations while preserving uniqueness of each modality-specific representation. We present experiments on the ChaLearn 2014 Looking at People Challenge gesture recognition track, in which we placed first out of 17 teams. Fusing multiple modalities at several spatial and temporal scales leads to a significant increase in recognition rates, allowing the model to compensate for errors of the individual classifiers as well as noise in the separate channels. Furthermore, the proposed ModDrop training technique ensures robustness of the classifier to missing signals in one or several channels to produce meaningful predictions from any number of available modalities. In addition, we demonstrate the applicability of the proposed fusion scheme to modalities of arbitrary nature by experiments on the same dataset augmented with audio.
Overview
CoChat Summary
TL;DR
The paper presents ModDrop, a multi-modal and multi-scale deep learning method for gesture detection and localization that placed first in the ChaLearn 2014 LAP Challenge track 3. ModDrop trains shared fusion layers with random modality dropping, improving recognition and making predictions robust to missing or corrupted channels.
Key findings
- The method placed first out of 17 teams in the ChaLearn 2014 LAP Challenge track 3, with the submitted hybrid model scoring 0.850 Jaccard index and surpassing the second-best score by 1.61 percentage points; post-challenge improvements raised the score to 0.870.
- On ChaLearn 2014 LAP augmented with audio, ModDrop improved robustness to missing channels: with mocap missing, accuracy rose from 38.41% to 92.82% and Jaccard from 0.306 to 0.859; with both hands missing, accuracy rose from 53.13% to 73.28% and Jaccard from 0.466 to 0.680.
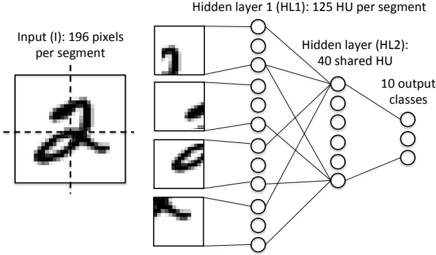
- On an MNIST multi-modal sanity check, ModDrop reduced test error under occlusion: 1 segment covered 2.30% vs 10.74%, 2 segments covered 7.19% vs 35.91%, and 3 segments covered 24.88% vs 68.03%.
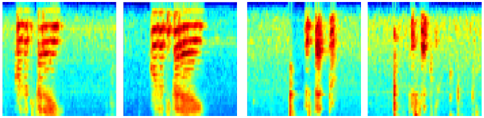
- Adding audio improved Jaccard by 1.3 points, and learned audio representations outperformed a phoneme-recognition baseline (F-measure 79.71% vs 56.50%; Jaccard 0.545 vs 0.256).
Methods
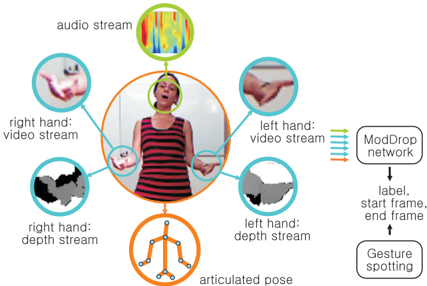
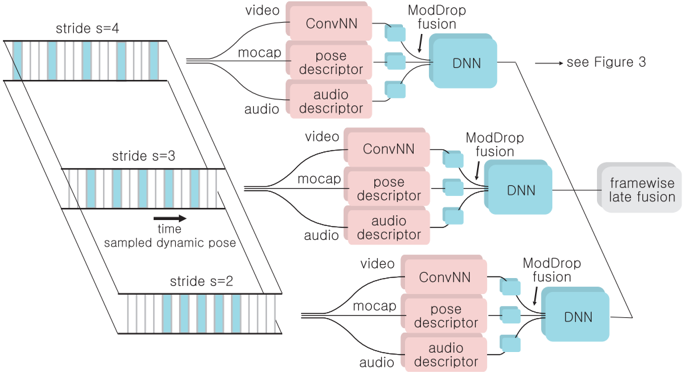
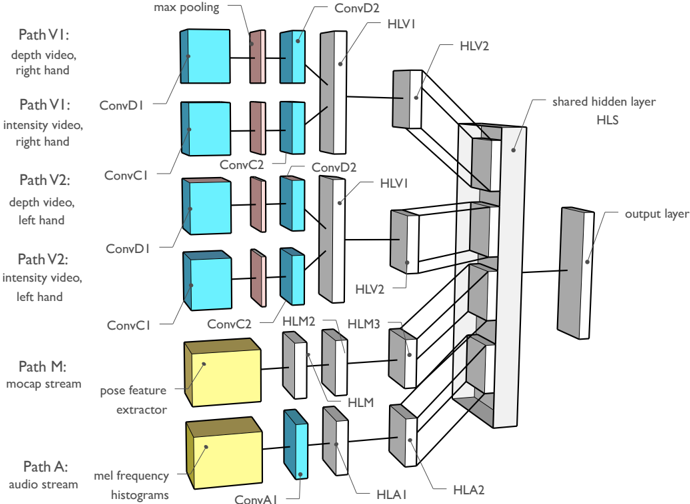
- A multi-scale, multi-modal convolutional architecture uses parallel single-scale paths over dynamic poses of 5 frames sampled with a given temporal stride, integrating depth and intensity video, articulated pose (183-dimensional per frame; 915-dimensional dynamic pose), and optionally audio.
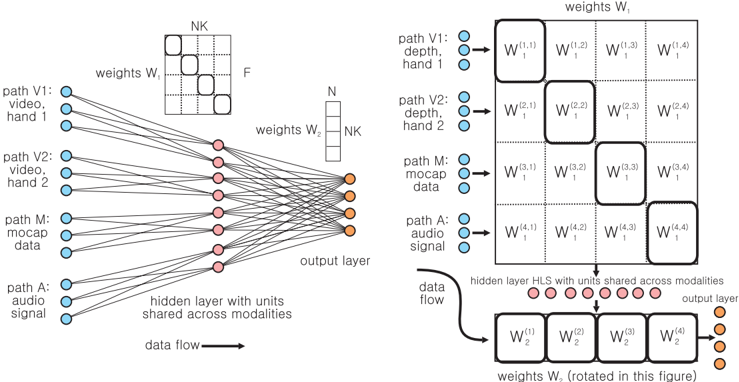
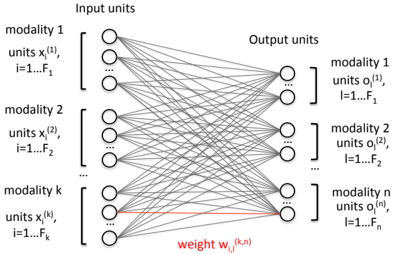
- Training proceeds by per-modality pretraining, initialization of shared fusion layers to a normalized geometric mean of per-model outputs, and gradual fusion with ModDrop, which randomly drops separate modality channels during training.
- Experiments use the ChaLearn 2014 Looking at People Challenge track 3 dataset (13,858 gesture instances, 20 gesture categories), augmented with audio from the ChaLearn 2013 Multi-modal Challenge, plus MNIST sanity checks; performance is measured mainly by Jaccard index.
Limitations
- Stated: audio alone does not allow robust gesture start/end localization because of natural gesture-speech desynchronization; annotations are video-based while spoken words/phrases are typically shorter, and vocalization may be delayed or ahead of the gesture, yielding poor audio-only Jaccard scores.
- Evident from the text: evaluation centers on the ChaLearn 2014 LAP dataset plus MNIST sanity checks and ChaLearn 2013 audio augmentation; hyperparameters and ModDrop/dropout rates were optimized on validation data, and hidden-unit dropout degraded performance due to the model’s compactness.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
5 Valid · 4 Not valid · 13 Not checked · 74 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Unfortunately, implementing the arithmetic mean in the case of early fusion and non-linear shared layers is not straightforward [51].”
What the sources say
- Partly supportedcites [51] [51] I. J. Goodfellow, D. Warde-Farley, M. Mirza, A. Courville, and Y. Bengio, 'Maxout Networks,' in arXiv:1302.4389v4 , 2013. - sourceExperimental — accuracy not yet measured
Maxout Networks (p. 2) says it is not obvious how to compute the arithmetic mean of predictions from the exponentially many models trained by dropout. Section 7 (pp. 6–7) discusses approximate model averaging in deep networks, but does not address early fusion or establish the claim specifically for non-linear shared layers. (LLM, conf=0.84)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Currently, the state-of-the-art for a fully-connected 7821200-1200-10 network with dropout regularization (50% for hidden units and 20% for the input) and tanh activations [53] is 107 errors on the MNIST test set (see Table 7).”
What the sources say
- Partly supportedcites [53] [53] G. E. Hinton, N. Srivastava, A. Krizhevsky, I. Sutskever, and R. R. Salakhutdinov, 'Improving neural networks by preventing coadaptation of feature detectors,' in arXiv:1207.0580 , 2012. - sourceExperimental — accuracy not yet measured
Appendix A.1 (p. 8) lists the 784-1200-1200-10 MNIST architecture and specifies 50% dropout for hidden units and 20% for input units. The main text (p. 2) reports about 110 test errors with those dropout rates, but our copy does not establish exactly 107 errors for that architecture or specify tanh activations. (LLM, conf=0.86)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Finally, as has been shown by [52] for dropout, the multiplier proportional to the derivative of the sigmoid activation makes the regularization effect adaptive to the magnitude of the weights.”
What the sources say
- Supportedcites [52] [52] P. Baldi and P. Sadowski, 'The dropout learning algorithm,' Journal of Artificial Intelligence , vol. 210, pp. 78-122, 2014. - source
Section 11.4 gives an approximate dropout regularization term proportional to the sigmoid derivative and the squared weights. It explicitly says the derivative adaptively scales the magnitude of that term. The result is presented as an approximation for a sigmoidal unit. (LLM, conf=0.88)
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“From our observations, inter-modality fusion is effective at early stages if both channels are of the same nature and convey complementary information.”
hedgedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We present experiments on the ChaLearn 2014 Looking at People Challenge gesture recognition track, in which we placed first out of 17 teams.”
- Also stated in: § 1 INTRODUCTION · p. 1 · plain
“The deep learning method described in this paper placed first in the 2014 version of this competition [14].”
plainn = 2,014- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 INTRODUCTION · p. 1 · plain
46 more claims
Create a free account to see all 96 claims and every source verdict.
- It may state two separate claims as one. 34
- Probably not a substantial claim. 19
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“The resulting adaptation offers significant savings compared to training a separate model for each input combination or retraining the model using some specialized training strategy like modality dropout [18, 17] or knowledge distillation [20, 22].”
From Robust Multimodal Learning with Missing Modalities via Parameter-Efficient Adaptation (2025) · cites this paper as [17]
The cited source says what the claim attributes to it.
In the citing paper
“The practitioner should be careful when determining whether or not 2 modalities are correlated under the warning that choosing a fusion strategy blindly for 2 essentially different modalities at an early stage has a high risk of learning fake cross-modality correlations and interactions (Neverova et al. 2014).”
From A review of multimodal deep learning methods for genomic-enabled prediction in plant breeding (2024) · cites this paper as Neverova et al. 2014
The cited source says what the claim attributes to it.
In the citing paper
“Studies have also shown that fusing highly correlated features in earlier layers and less correlated features in deeper layers improve model performance50,51.”
From Fusion of medical imaging and electronic health records using deep learning: a systematic review and implementation guidelines (2020) · cites this paper as [51]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ of parameters > Effect of ModDrop on ChaLearn 2014+audio. · p. 13
“In all cases, dropout (20%) and ModDrop (10%) are applied to the input signal.”
§ of parameters > Effect of ModDrop training under occlusion and noise. · p. 12
“| no | no | no | no | 91 . 94 |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ of parameters > 8 CONCLUSION · p. 13
“Each of the visual modalities captures spatial information at a particular spatial scale (such as motion of the upper body or a hand), and the whole system operates at two temporal scales.”
§ 3 GESTURE CLASSIFICATION · p. 3
“Fig. 2. The ModDrop network operating at 3 temporal scales corresponding to 3 durations of dynamic poses.”
Citations
Cites
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155
Gradient-based learning applied to document recognition
Lecun, Y., Bottou, L., Bengio, Y., & Haffner, P. (1998) · Proceedings of the IEEE · doi:10.1109/5.726791 · Cited by 58,805
Rich Feature Hierarchies for Accurate Object Detection and Semantic Segmentation
Girshick, R., Donahue, J., Darrell, T., & Malik, J. (2014) · 2014 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2014.81 · Cited by 32,684
Geurts, P., Ernst, D., & Wehenkel, L. (2006) · Machine Learning · doi:10.1007/s10994-006-6226-1 · Cited by 9,300
Two-Stream Convolutional Networks for Action Recognition in Videos
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1406.2199 · Cited by 6,756
DeepFace: Closing the Gap to Human-Level Performance in Face Verification
Taigman, Y., Yang, M., Ranzato, M., & Wolf, L. (2014) · 2014 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2014.220 · Cited by 6,542
Improving neural networks by preventing co-adaptation of feature detectors
Hinton, G. E., Srivastava, N., Krizhevsky, A., Sutskever, I., & Salakhutdinov, R. R. (2012) · arXiv · doi:10.48550/arxiv.1207.0580 · Cited by 6,382
Large-Scale Video Classification with Convolutional Neural Networks
Karpathy, A., Toderici, G., Shetty, S., Leung, T., Sukthankar, R., & Fei-Fei, L. (2014) · 2014 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2014.223 · Cited by 6,354
3D Convolutional Neural Networks for Human Action Recognition
Ji, S., Xu, W., Yang, M., & Yu, K. (2013) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2012.59 · Cited by 6,235
Real-time human pose recognition in parts from single depth images
Shotton, J., Fitzgibbon, A., Cook, M., Sharp, T., Finocchio, M., Moore, R., Kipman, A., & Blake, A. (2011) · CVPR 2011 · doi:10.1109/cvpr.2011.5995316 · Cited by 3,491
Research works printed but not linked: 2
- [60] A. Lee, T. Kawahara, and K. Shikano, 'Julius - an open source realtime large vocabulary recognition engine,' in Interspeech , 2001. -
- [65] Y. LeCun, L. Bottou, Y. Bengio, and P. Haffner, 'Gradient-based learning applied to document recognition,' in Proceedings of the IEEE , vol. 86(11), 1998, pp. 2278-2324. <!-- image --> Natalia Neverova is a PhD student at INSA de Lyon and LIRIS (CNRS, France) working in the area of gesture and action recognition with emphasis on multi-modal aspects and deep learning methods. She is advised by Christian Wolf and Graham Taylor, and her research is a part of Interabot project in partnership with Awabot SAS. She was a visiting researcher at University of Guelph in 2014 and at Google in 2015. <!-- image --> 0 <!-- image --> <!-- image --> Christian Wolf is assistant professor at INSA de Lyon and LIRIS, CNRS, since 2005. He is interested in computer vision and machine learning, especially the visual analysis of complex scenes in motion, structured models, graphical models and deep learning. He received his MSc in computer science from Vienna University of Technology in 2000, and a PhD from the National Institute of Applied Science (INSA de Lyon), in 2003. In 2012 he obtained the habilitation diploma. Graham Taylor is an assistant professor at University of Guelph. He is interested in statistical machine learning and biologicallyinspired computer vision, with an emphasis on unsupervised learning and time series analysis. He completed his PhD at the University of Toronto in 2009, where his thesis co-advisors were Geoffrey Hinton and Sam Roweis. He did a postdoc at NYU with Chris Bregler, Rob Fergus, and Yann LeCun. Florian Nebout is a project manager at Awabot, leading different robotics projects, which are mostly dedicated to remote presence applications. He is especially interested in human robot interaction and how robotics can change our daily life. He graduated from INSA de Lyon, France and worked at CSIRO Human Computer Interaction team and ANU Information and Human Centred Computing Research Group in Canberra, Australia. · DOI · Paper page
Cited by
Items 201–300 of 418
HRI in an ecological dynamic experiment: The GEE corpus based approach for the Emox robot
Guillaume, L., Bonnefond, N., Nègre, A., Tsvetanova, L., Girard-Rivier, M., Aubergé, V., Magnani, R., Aman, F., Cottier, C., Sasa, Y., et al. (2015) · IEEE Workshop on Advanced Robotics and its Social Impacts (ARSO) · doi:10.1109/arso.2015.7428207 · Cited by 8
Self-citation3D Skeletal Gesture Recognition via Sparse Coding of Time-Warping Invariant Riemannian Trajectories
Liu, X., & Zhao, G. (2018) · Lecture notes in computer science · doi:10.1007/978-3-030-05710-7_56 · Cited by 11
Temporal Hierarchical Dictionary with HMM for Fast Gesture Recognition
Chen, H., Liu, X., & Zhao, G. (2018) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr.2018.8546245 · Cited by 8
Self-Supervised Audio-Visual Feature Learning for Single-Modal Incremental Terrain Type Clustering
Ishikawa, R., Hachiuma, R., & Saitô, H. (2021) · IEEE Access · doi:10.1109/access.2021.3075582 · Cited by 8
Multimodal artificial intelligence in medicine: a task-oriented framework for clinical translation
Zhang, R., Chen, Y., Yue, W., Zhang, Y., Li, X., Feng, S., Yuan, F., & Luo, M. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2025.1736272 · Cited by 27
Multimodal Deception Detection: A Survey
Zhang, J., Lin, X., Huang, J., Ye, S., Guo, X., Zhu, D., Hu, R., Guo, D., Liang, Y., Yu, Z., et al. (2026) · Machine Intelligence Research · doi:10.1007/s11633-025-1625-x · Cited by 20
Context Aware Robot Architecture, Application to the RoboCup@Home Challenge
Jumel, F., Saraydaryan, J., Leber, R., et al. (2019) · Lecture notes in computer science · doi:10.1007/978-3-030-27544-0_17 · Cited by 7
Self-citationA Multimodal Approach to Device-Directed Speech Detection with Large Language Models
Wagner, D., Churchill, A., Sigtia, S., Georgiou, P., Mirsamadi, M., Mishra, A., & Marchi, E. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10446224 · Cited by 16
Computer vision based working environment monitoring to analyze Generalized Anxiety Disorder (GAD)
Manocha, A., & Singh, R. (2019) · Multimedia Tools and Applications · doi:10.1007/s11042-019-7700-7 · Cited by 7
Gomaa, A., & Feld, M. (2023) · INTERNATIONAL CONFERENCE ON MULTIMODAL INTERACTION · doi:10.1145/3577190.3616121 · Cited by 11
Gu, Y., Saito, K., & Ma, J. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-05182-0_28 · Cited by 19
MMP: Towards Robust Multi-Modal Learning with Masked Modality Projection
Nezakati, N., Reza, M. K., Patil, A. D., Solh, M., & Asif, M. S. (2025) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata66926.2025.11401652 · Cited by 20
Feature Importance Estimation Using Gradient Based Method for Multimodal Fused Neural Networks
Azmat, M., & Alessio, A. M. (2022) · IEEE Nuclear Science Symposium and Medical Imaging Conference (NSS/MIC) · doi:10.1109/nss/mic44845.2022.10398969 · Cited by 8
Learning to Recognize Touch Gestures: Recurrent vs. Convolutional Features and Dynamic Sampling
Debard, Q., Wolf, C., Canu, S., & Arné, J. (2018) · International Conference on Automatic Face and Gesture Recognition · doi:10.1109/fg.2018.00026 · Cited by 21
Self-citationEvent Camera-Based Real-Time Gesture Recognition for Improved Robotic Guidance
Aitsam, M., Davies, S., & Nuovo, A. G. D. (2024) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn60899.2024.10650870 · Cited by 12
Activity recognition with volume motion templates and histograms of 3D gradients
Doğan, E., Eren, G., Wolf, C., et al. (2015) · Proceedings - International Conference on Image Processing · doi:10.1109/icip.2015.7351642 · Cited by 6
Self-citationAttention-driven Multi-sensor Selection
Braun, S., Neil, D., Anumula, J., Ceolini, E., & Liu, S. (2019) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn.2019.8852396 · Cited by 11
Optimal system design of language training strategy based on artificial intelligence
Guo, J., & Liu, J. (2020) · Journal of Intelligent & Fuzzy Systems · doi:10.3233/jifs-189503 · Cited by 9
Retracted3D Skeletal Gesture Recognition via Sparse Coding of Time-Warping Invariant Riemannian TrajectoriesPreprint
Liu, X., & Zhao, G. (2018) · EasyChair preprint · doi:10.29007/xhfp · Cited by 6
Towards a General Model of Knowledge for Facial Analysis by Multi-Source Transfer LearningPreprint
Vielzeuf, V., Lechervy, A., Pateux, S., & Jurie, F. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1911.03222 · Cited by 5
Improved Lite Audio-Visual Speech EnhancementPreprint
Chuang, S.-Y., Wang, H., & Tsao, Y. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2008.13222 · Cited by 6
Jony, R. I. (2023) · Queensland University of Technology · doi:10.5204/thesis.eprints.238058 · Cited by 9
Gomaa, A., Reyes, G., Feld, M., & Krüger, A. (2024) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3640543.3645152 · Cited by 5
Gesture based robot programming using process knowledge — An example for welding applications
Heimann, O., Hügle, J., & Krüger, J. (2017) · IEEE International Conference on Emerging Technologies and Factory Automation (ETFA) · doi:10.1109/etfa.2017.8247761 · Cited by 5
Signer-Independent Sign Language Recognition with Adversarial Neural Networks
Ferreira, P. M., Pernes, D., Rebelo, A., & Cardoso, J. S. (2021) · International Journal of Machine Learning and Computing · doi:10.18178/ijmlc.2021.11.2.1024 · Cited by 5
Studying Multi-modal Human Robot Interaction Using a Mobile VR Simulation
Milde, S., Runzheimer, T., Friesen, S., Peiffer, J.-H., Höfler, J.-J., Geis, K., Milde, J., & Blum, R. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-35602-5_11 · Cited by 5
EduVigil: Shaping the Future of Education with AI - An Intriguing Case Study
Saravanan, A., Azariya, S. D. S., Soms, N., et al. (2023) · International Conference on Computing, Communication and Networking Technologies (ICCCNT) · doi:10.1109/icccnt56998.2023.10307866 · Cited by 5
Modality-convolutions: Multi-modal gesture recognition based on convolutional neural network
Huo, D., Chen, Y., Li, F., & Lei, Z. (2017) · International Conference on Computer Science and Education · doi:10.1109/iccse.2017.8085515 · Cited by 6
Industrial object detection with multi-modal SSD: closing the gap between synthetic and real images
Cohen, J., Crispim-Junior, C. F., Chiappa, J.-M., & Tougne, L. (2023) · Multimedia Tools and Applications · doi:10.1007/s11042-023-15367-0 · Cited by 6
Holoscopic 3D Micro-Gesture Recognition Based on Fast Preprocessing and Deep Learning Techniques
Lei, T., Jia, X., Zhang, Y., et al. (2018) · International Conference on Automatic Face and Gesture Recognition · doi:10.1109/fg.2018.00128 · Cited by 5
Goyal, N., Singh, T., & Goraya, M. S. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.112657 · Cited by 7
Deep multimodal learning for time series analysis in social computing: a survey
Yang, C., Chen, Y., Li, Z., Wang, X., Shi, K., Yao, L., Xu, G., & Guo, Z. (2025) · International Journal of Multimedia Information Retrieval · doi:10.1007/s13735-025-00363-x · Cited by 7
Analyzing Multi-Channel Networks for Gesture Recognition
Narayana, P., Beveridge, J. R., & Draper, B. A. (2019) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn.2019.8851991 · Cited by 4
Cazau, D., Duc, P. N. H., Druon, J., Matwins, S., & Fablet, R. (2021) · Machine Learning · doi:10.1007/s10994-021-06029-z · Cited by 6
A Task-Conditional Mixture-of-Experts Model for Missing Modality Segmentation
Novosad, P., Carano, R. A. D., & Krishnan, A. P. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72114-4_4 · Cited by 6
Recognizing Words from Gestures: Discovering Gesture Descriptors Associated with Spoken Utterances
Okada, S., & Otsuka, K. (2017) · International Conference on Automatic Face and Gesture Recognition · doi:10.1109/fg.2017.60 · Cited by 4
Action-Affect-Gender Classification Using Multi-task Representation Learning
Shields, T. J., Amer, M. R., Ehrlich, M., & Tamrakar, A. (2017) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw.2017.279 · Cited by 4
Enhanced Action Recognition Using Multiple Stream Deep Learning with Optical Flow and Weighted Sum
Kim, H., Park, S., Park, H., et al. (2020) · Sensors · doi:10.3390/s20143894 · Cited by 4
Revisiting spatio-temporal layouts for compositional action recognition
Radevski, G., Moens, M., & Tuytelaars, T. (2021) · British Machine Vision Conference (BMVC) · doi:10.5244/c.35.278 · Cited by 32
A hybrid fusion precipitation bias correction approach for Yin‐He global spectral model
Hu, Y., Yin, F., Zhang, W., & Deng, K. (2022) · Meteorological Applications · doi:10.1002/met.2097 · Cited by 4
Features Fusion Framework for Multimodal Irregular Time-series Events
Tang, P., & Zhang, X. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20862-1_27 · Cited by 6
Exploiting Video Classification Using Deep Learning Models for Human Activity Recognition
Singh, U., & Singhal, N. (2023) · Algorithms for intelligent systems · doi:10.1007/978-981-19-7892-0_14 · Cited by 4
Deep fusion of visual signatures for client-server facial analysis
Bhattarai, B., Sharma, G., & Jurie, F. (2016) · Indian Conference on Computer Vision, Graphics and Image Processing · doi:10.1145/3009977.3010062 · Cited by 3
Multi-Loss Recurrent Residual Networks for Gesture Detection and Recognition
Bastos, I. L. O., de Melo, V. H. C., & Schwartz, W. R. (2019) · SIBGRAPI Conference on Graphics, Patterns and Images (SIBGRAPI) · doi:10.1109/sibgrapi.2019.00031 · Cited by 4
Exploiting LSTM-RNNs and 3D Skeleton Features for Hand Gesture Recognition
Guo, H., Yang, Y., & Cai, H. (2019) · WRC Symposium on Advanced Robotics and Automation (WRC SARA) · doi:10.1109/wrc-sara.2019.8931937 · Cited by 4
Multi-modal Sign Language Recognition with Enhanced Spatiotemporal Representation
Xiao, S., Fang, Y., & Ni, L. (2021) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn52387.2021.9533707 · Cited by 4
Articulated motion and deformable objects
Wan, J., Escalera, S., Perales, F. J., & Kittler, J. (2018) · Pattern Recognition · doi:10.1016/j.patcog.2018.01.038 · Cited by 5
3D Motion Reconstruction From 2D Motion Data Using Multimodal Conditional Deep Belief Network
Heydari, M. J., & Ghidary, S. S. (2019) · IEEE Access · doi:10.1109/access.2019.2904117 · Cited by 4
Multimodal Conditionality for Natural Language GenerationPreprint
Sollami, M., & Jain, A. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.01229 · Cited by 8
Exploring Missing Modality in Multimodal Egocentric Datasets
Ramazanova, M., Pardo, A., Alwassel, H., & Ghanem, B. (2025) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw67362.2025.00013 · Cited by 18
Sensing Technologies for Hand Gesture Recognition in Human–Robot Interaction: A Review
Liang, B., Li, N., Li, G., Huang, J., Yu, Z., & Zhao, X. (2025) · IEEE Sensors Journal · doi:10.1109/jsen.2025.3635622 · Cited by 6
Liu, Y., Peng, Y., Hong, Y., Zhang, P., Wu, D., Wu, F., Pan, Z., Wu, J., Jin, Y., Ren, T., et al. (2026) · InfoMat · doi:10.1002/inf2.70115 · Cited by 3
mWhisper-Flamingo for Multilingual Audio-Visual Noise-Robust Speech Recognition
Rouditchenko, A., Thomas, S., Kuehne, H., Feris, R., & Glass, J. R. (2025) · IEEE Signal Processing Letters · doi:10.1109/lsp.2025.3569210 · Cited by 11
Multimodal learning rebalanced: Negative correlation ensembles for improved performance
Wang, Z., Zhang, T., & Huang, W. X. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107686 · Cited by 3
Dang, X. H., Shah, S. Y., & Zerfos, P. (2020) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2020/634 · Cited by 7
Wi-ID: WiFi-Based Identification System Using Rock-Paper-Scissors Hand Gestures
Zheng, Z., Yu, N. H., Zhang, J., Dai, H., Wang, Q., & Wang, Q. (2022) · Wireless Personal Communications · doi:10.1007/s11277-022-10029-0 · Cited by 4
A diagnostic method for cardiomyopathy based on multimodal data
Shen, L., Zhang, X., Huang, S., Wu, B., & Li, J. (2023) · Biomedizinische Technik/Biomedical Engineering · doi:10.1515/bmt-2023-0099 · Cited by 4
Unveiling hierarchical relationships for social image representation learning
Han, L. T., Zhang, X., Zhang, L., Lu, M., Huang, F., & Liu, Y. (2023) · Applied Soft Computing · doi:10.1016/j.asoc.2023.110792 · Cited by 3
Schreiber, A., Ji, T., McPherson, D. L., & Driggs-Campbell, K. (2023) · IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros55552.2023.10341852 · Cited by 4
MAAL: Multimodality-Aware Autoencoder-based Affordance Learning for 3D Articulated Objects
Liang, Y., Wang, X., Zhu, L., & Yang, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00027 · Cited by 5
Cross-Modality Calibration in Multi-Input Network for Axillary Lymph Node Metastasis Evaluation
Gravina, M., Santucci, D., Cordelli, E., Soda, P., & Sansone, C. (2024) · IEEE Transactions on Artificial Intelligence · doi:10.1109/tai.2024.3397246 · Cited by 3
CentralNet: a Multilayer Approach for Multimodal Fusion
Vielzeuf, V., Lechervy, A., Pateux, S., & Jurie, F. (2018) · HAL · doi:10.48550/arxiv.1808.07275 · Cited by 3
Multi-view learning review: understanding methods and their application
배강일, 이영섭, & 임창원 (2019) · 응용통계연구 = The Korean journal of applied statistics · doi:10.5351/kjas.2019.32.1.041 · Cited by 4
Visual Scene-Aware Hybrid and Multi-Modal Feature Aggregation for Facial Expression Recognition
Lee, M. K., Kim, D. H., & Song, B. C. (2020) · Sensors · doi:10.3390/s20185184 · Cited by 4
HSFE Network and Fusion Model based Dynamic Hand Gesture Recognition
Do, N.-T., Na, I. S., & Kim, S. J. (2020) · KSII Transactions on Internet and Information Systems · doi:10.3837/tiis.2020.09.020 · Cited by 3
Bongers, C. C. W. G., & Eijsvogels, T. M. H. (2018) · Temperature · doi:10.1080/23328940.2018.1462656 · Cited by 3
Enhancing dynamic hand gesture recognition through the HMM-LRB/LR algorithm
Ikram, A., & Liu, Y. (2025) · Multimedia Tools and Applications · doi:10.1007/s11042-025-20972-2 · Cited by 2
A deep learning-based method combines manual and non-manual features for sign language recognition
Harrouch, H., Trabelsi, L., Jebali, M., & Gammoudi, O. (2025) · Scientific Reports · doi:10.1038/s41598-025-32768-3 · Cited by 4
Automatic recognition of wheat growth stages with a lightweight multimodal data fusion network
Zhang, L., Zhang, B., Zhang, H., et al. (2025) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2025.111373 · Cited by 2
Trustworthy Multimodal Depression Screening via Cross-Attention Fusion and Calibrated Uncertainty
Gupta, A., & Pirzada, U. S. M. (2026) · Journal of Trends in Computer Science and Smart Technology · doi:10.36548/jtcsst.2026.3.004 · Cited by 2
Multimodal Affective Computing Based on Weighted Linear Fusion
Jin, K., Wang, Y., & Wu, C. (2020) · Advances in intelligent systems and computing · doi:10.1007/978-3-030-55190-2_1 · Cited by 6
Visual Methods for Sign Language Recognition: A Modality-Based Review
Seddik, B., & Amara, N. E. B. (2021) · Smart sensors, measurement and instrumentation · doi:10.1007/978-3-030-81982-8_9 · Cited by 6
Gesture retrieval and its application to the study of multimodal communication
Parian, M. A., Uhrig, P., Rossetto, L., Dupont, S., & Schuldt, H. (2023) · International Journal on Digital Libraries · doi:10.1007/s00799-023-00367-0 · Cited by 4
Accommodating Missing Modalities in Time-Continuous Multimodal Emotion Recognition
Vazquez-Rodriguez, J., Lefebvre, G., Cumin, J., & Crowley, J. L. (2023) · International Conference on Affective Computing and Intelligent Interaction and workshops · doi:10.1109/acii59096.2023.10388079 · Cited by 9
Group Image Compression for Dual Use of Machine and Human Vision
Fang, X., Wu, X., Li, F., et al. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3486558 · Cited by 2
M3 LUC: Multi-modal Model for Urban Land-Use Classification
Li, S., Zhang, X., Lin, Y., & Li, Y. (2024) · ACM SIGSPATIAL International Conference on Advances in Geographic Information Systems (SIGSPATIAL GIS) · doi:10.1145/3678717.3691278 · Cited by 3
Hybrid Multi-modal Fusion for Human Action Recognition
Seddik, B., Gazzah, S., & Amara, N. E. B. (2017) · Lecture notes in computer science · doi:10.1007/978-3-319-59876-5_23 · Cited by 2
A Collaborative Multi-modality Selection Method Based on Data Utility Assessment
Xiao, Y., Gu, Y., Wang, J., & Wu, T. (2019) · IEEE SmartWorld, Ubiquitous Intelligence & Computing, Advanced & Trusted Computing, Scalable Computing & Communications, Cloud & Big Data Computing, Internet of People and Smart City Innovation (SmartWorld/SCALCOM/UIC/ATC/CBDCom/IOP/SCI) · doi:10.1109/smartworld-uic-atc-scalcom-iop-sci.2019.00120 · Cited by 3
Dynamic Gesture Recognition with Pose-based CNN Features derived from videos using LSTM
Roy, K., & Sahay, R. R. (2018) · Indian Conference on Computer Vision, Graphics and Image Processing · doi:10.1145/3293353.3293398 · Cited by 2
Single-modal Incremental Terrain Clustering from Self-Supervised Audio-Visual Feature Learning
Ishikawa, R., Hachiuma, R., Kurobe, A., et al. (2021) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr48806.2021.9412638 · Cited by 2
Audio-Video Based Fusion Mechanism Using Deep Learning for Categorical Emotion Recognition
Kumar, H., & Martín, A. (2023) · International Conference on Self Sustainable Artificial Intelligence Systems (ICSSAS) · doi:10.1109/icssas57918.2023.10331779 · Cited by 2
Gesture Recognition by Using Depth Data: Comparison of Different Methodologies
Cicirelli, G., & D’Orazio, T. (2017) · InTech eBooks · doi:10.5772/68118 · Cited by 3
Ensembling 3D CNN Framework for Video Recognition
Huang, R., Dong, H., Yin, G., & Fu, Q. (2019) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn.2019.8852054 · Cited by 2
Multimodal Dance Generation Networks Based on Audio-Visual Analysis
Duan, L., Xu, X. W., & En, Q. (2021) · International Journal of Multimedia Data Engineering and Management · doi:10.4018/ijmdem.2021010102 · Cited by 2
Gu, Y., Li, Y., Chen, Y., Wang, J., & Shen, J. (2021) · Lecture notes in computer science · doi:10.1007/978-3-030-67832-6_6 · Cited by 4
WITHDRAWN: Adaptive multiclass support vector machine for multimodal data analysis
Zhang, X., Zhang, X., Zhang, X., et al. (2017) · Pattern Recognition · doi:10.1016/j.patcog.2017.05.006 · Cited by 2
RetractedAudio-Visual Kinship VerificationPreprint
Wu, X., Granger, É., & Feng, X. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1906.10096 · Cited by 2
Deep Learning Based Multi-Modal Data Fusion for Car Crash Detection
Bhowmik, T. K., & Rateria, R. (2023) · International Conference on Computers and Devices for Communication · doi:10.1109/codec60112.2023.10466222 · Cited by 1
Kurdish Sign Language Recognition Using Pre-Trained Deep Learning Models
Alsaud, A. A. (2024) · Journal of Electrical Systems · doi:10.52783/jes.2887 · Cited by 1
Training Strategies for Modality Dropout Resilient Multi-Modal Target Speaker Extraction
Korse, S., Elminshawi, M., Habets, E. A. P., & Chetupalli, S. R. (2024) · IEEE International Conference on Acoustics, Speech, and Signal Processing Workshops (ICASSPW) · doi:10.1109/icasspw62465.2024.10627296 · Cited by 1
Robust Inference under Modality Missing in Multimodal Split Learning
Yamashita, Y., Taya, A., & Tobe, Y. (2025) · doi:10.1145/3737899.3768524 · Cited by 1
Mariyam, S., & Sadia, H. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-10783-1_26 · Cited by 3
Huang, J., Zhu, D., Zitong, Y. U., Ma, H., Zhang, J., Zhu, C., & Cao, X. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37447-9_33 · Cited by 1
Manufacturing, Sensing, and Applications of Data Gloves: A Review
Shao, S., Li, M., Hu, Y., & Li, M. (2026) · IEEE Sensors Journal · doi:10.1109/jsen.2026.3681433 · Cited by 2
Turdalyuly, M., Zholdassova, A., Turdalykyzy, T., & Doshybekov, A. (2026) · Information · doi:10.3390/info17040368 · Cited by 1
Depression and anxiety characterization and detection with multimodal deep learning
Lu, T., Cho, L., Qiu, Z., Wang, Y., Niu, W., Leung, Y. W., Wang, Y., Zhang, H., Chang, W. C., Tanveer, M., et al. (2026) · Nature Mental Health · doi:10.1038/s44220-026-00632-6 · Cited by 4
Multi-modal gesture recognition with voting-based dynamic time warping
Kuang, Y., Cheng, H., Hao, J., et al. (2019) · International Journal of Advanced Robotic Systems · doi:10.1177/1729881419892398 · Cited by 1
Bayrak, Ş., & Yücel, E. (2022) · Studies in computational intelligence · doi:10.1007/978-981-19-2416-3_1 · Cited by 1
Goddy-Worlu, R., Ferreira, M. D., Peachey, M., et al. (2022) · IEEE International Conference on Artificial Intelligence and Virtual Reality (AIVR) · doi:10.1109/aivr56993.2022.00025 · Cited by 1
The Application of Multimodal Learning to Enhance Language Proficiency in Oral English Teaching
Zeng, Y. (2023) · Adult and Higher Education · doi:10.23977/aduhe.2023.051806 · Cited by 5
Metadata
- Authors
- Neverova, N., Wolf, C., Taylor, G., & Nebout, F.
- Affiliations
- Centre National de la Recherche Scientifique (FR)
- University of Guelph (CA)
- Venue
- IEEE Transactions on Pattern Analysis and Machine Intelligence
- Published
- 2016-08-01
- Volume
- 38
- Issue
- 8
- Pages
- 1692-1706
- ISSN
- 0162-8828 (ISSN-L)
- 2160-9292
- OpenAlex
- W1533025524
- Cited by
- 420
- References
- 77
- Citations by year
- 2026: 89 · 2025: 28 · 2024: 28 · 2023: 35 · 2022: 24 · 2021: 44 · 2020: 41 · 2019: 44 · 2018: 34 · 2017: 34 · 2016: 14
- FWCI
- 55.12
- Type
- journal article
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- IEEE Transactions on Pattern Analysis and Machine Intelligence (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- HAL (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Investissement's d’Avenir
- Briques Génériques du Logiciel Embarqué
- Topics
- Physical Sciences › Computer Science › Human-Computer Interaction › Hand Gesture Recognition Systems
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Context-Aware Activity Recognition Systems
- Keywords
- gesture recognition, multimodal fusion, multi-scale deep learning, spatial and temporal scales, missing modality robustness, upper body movement, hand movement
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
