

The DOI matches its Crossref record; 46 of the 46 references it cites were found in a registry or an index; 5 of the 19 sources its claims cite were checked for support.
EXTRA: An Exact First-Order Algorithm for Decentralized Consensus Optimization
Open accessAbstract
Recently, there has been growing interest in solving consensus optimization problems in a multiagent network. In this paper, we develop a decentralized algorithm for the consensus optimization problem $\mathrm{minimize}_{x\in\mathbb{R}^p}~\bar{f}(x)=\frac{1}{n}\sum_{i=1}^n f_i(x),$ which is defined over a connected network of $n$ agents, where each function $f_i$ is held privately by agent $i$ and encodes the agent's data and objective. All the agents shall collaboratively find the minimizer while each agent can only communicate with its neighbors. Such a computation scheme avoids a data fusion center or long-distance communication and offers better load balance to the network. This paper proposes a novel decentralized exact first-order algorithm (abbreviated as EXTRA) to solve the consensus optimization problem. “Exact” means that it can converge to the exact solution. EXTRA uses a fixed, large step size, which can be determined independently of the network size or topology. The local variable of every agent $i$ converges uniformly and consensually to an exact minimizer of $\bar{f}$. In contrast, the well-known decentralized gradient descent (DGD) method must use diminishing step sizes in order to converge to an exact minimizer. EXTRA and DGD have the same choice of mixing matrices and similar per-iteration complexity. EXTRA, however, uses the gradients of the last two iterates, unlike DGD which uses just that of the last iterate. EXTRA has the best known convergence rates among the existing synchronized first-order decentralized algorithms for minimizing convex Lipschitz--differentiable functions. Specifically, if the $f_i$'s are convex and have Lipschitz continuous gradients, EXTRA has an ergodic convergence rate $O(\frac{1}{k})$ in terms of the first-order optimality residual. In addition, as long as $\bar{f}$ is (restricted) strongly convex (not all individual $f_i$'s need to be so), EXTRA converges to an optimal solution at a linear rate $O(C^{-k})$ for some constant $C>1$.
Overview
CoChat Summary
TL;DR
EXTRA is a synchronous decentralized exact first-order algorithm for consensus optimization that can use a fixed step size independent of network size and converges to an exact solution. It achieves an ergodic O(1/k) rate for convex Lipschitz-differentiable objectives and a linear rate under restricted strong convexity.
Key findings
- EXTRA uses a fixed large step size and converges exactly, unlike DGD with a fixed step size, which stalls in an O(α)-neighborhood and requires diminishing step sizes for exact convergence.
- Under Assumptions 1–3 and step size \(0<\alpha<2\lambda_{\min}(\tilde W)/L_f\), the sequence \(z_k\) converges to an optimal \(z^*\), with contraction factor \(\zeta=1-\alpha L_f/(2\lambda_{\min}(\tilde W))\); running-average progress is \(O(1/k)\), running-best progress is \(o(1/k)\), and running-average optimality residuals are \(O(1/k)\).
- If \(g(x)=f(x)+\frac{1}{4\alpha}\|x\|^2_{\tilde W-W}\) is restricted strongly convex with constant \(\mu_g>0\), then with proper step size \(\alpha<2\mu_g\lambda_{\min}(\tilde W)/L_f^2\), \(\|z_k-z^*\|_G^2\) converges Q-linearly at \(O((1+\delta)^{-k})\), and \(\|x_k-x^*\|_{\tilde W}^2\) converges R-linearly at the same rate.
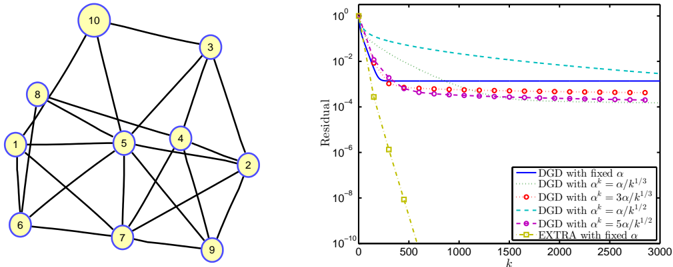
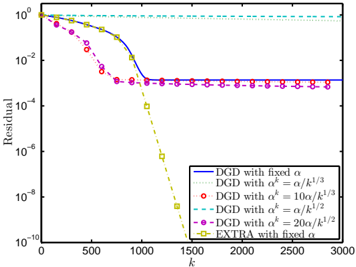
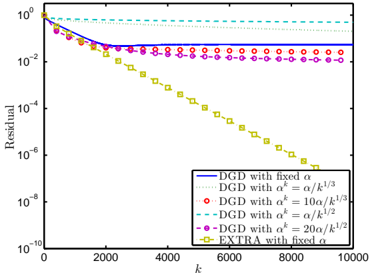
- Numerical experiments: in decentralized least squares with \(n=10\), \(m_i=1\), \(p=5\), connectivity ratio \(r=0.5\), \(L_f=1\), and \(\|x^*-x_0\|=300\), DGD with fixed step size and EXTRA show similar linear convergence for the first 200 iterations, after which DGD slows and stalls while EXTRA continues. In decentralized logistic regression with \(n=200\), \(r=0.2\), \(m_i=10\), \(p=20\), and 2000 samples, EXTRA outperforms DGD and shows linear exact convergence.
Methods
- Design: a synchronous decentralized first-order algorithm where each agent holds a local copy \(x^{(i)}\) and communicates only with neighbors; EXTRA is derived by taking the difference of two DGD updates and uses gradients of the last two iterates.
- Data/sample: numerical tests on decentralized least squares, decentralized robust least squares with Huber loss, and decentralized logistic regression over randomly generated connected networks.
- Analysis: convergence is established under mixing-matrix assumptions, convex Lipschitz-differentiable objectives, and solution existence; rates are derived via a contraction recursion, ergodic averaging, and restricted strong convexity.
Limitations
- The paper states EXTRA is “far from perfect” and that more work is needed to adapt it to asynchronous and dynamic network settings; these are left as open questions.
- The paper notes it is open whether \(\|z_k-z_{k+1}\|_G^2\) is monotonic; if monotonicity could be shown, the rates would hold for the last point in the running sequence. It also states that proving linear convergence under the numerically observed larger step size \(O(1/L_f)\) remains open.
- The paper states that determining \(\mu_g\) or a lower bound is tricky except when each \(f_i\) is restricted strongly convex, and that deriving an optimal step size and explicit linear rate is “quite tricky and messy.” The numerical results are described as preliminary.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
5 Valid · 0 Not valid · 11 Not checked · 58 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“(iii) min t ≤ k { a t } = o ( 1 k ) .”
What the sources say
- Supportedcites [6] D. Davis and W. Yin, Convergence Rate Analysis of Several Splitting Systems , preprint, arXiv:1406.4834, 2014. source
Section 2 ('Summable sequence convergence lemma', Lemma 3, p. 8) states Part 4 'No monotonicity', defining the best-so-far sequence and asserting that '(a_j^best) is monotonically nonincreasing and the above bounds continue to hold when a_k is replaced with a_k^best', while the Part 1a proof on the same page gives a_k = o(1/(Λ_k − Λ_⌈k/2⌉)) = o(1/(k+1)) when (λ_j) is bounded away from 0 (i.e. unweighted summability). Together these yield exactly the claim: a nonnegative sequence with finite sum has running minimum o(1/k) (the source writes o(1/(k+1)), the same rate up to index shift). The remark on p. 9 confirms the setting — Part 1 generalizes the known result that a nonnegative, summable, monotonic sequence converges at o(1/(k+1)) — and p. 12 applies Lemma 3 to a running minimum, min_{i=0,…,k}{‖e_i‖}. (LLM, conf=0.85)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“An EXTRA update is, therefore, a DGD update with a cumulative correction term.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this subsection we prove that EXTRA with a proper step size reaches linear convergence if the original objective ¯ f is restricted strongly convex.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In subsection 2.1, we have argued that the DGD update cannot reach consensus asymptotically unless α asymptotically vanishes.”
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In other words, a fixed and rather large step size is permitted by EXTRA.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
31 more claims
Create a free account to see all 74 claims and to verify the 9 references still open.
- Probably not a substantial claim. 21
- It may state two separate claims as one. 26
- The quote only partly states this claim. 1
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“EXTRA converges at an o (1 /k ) rate when the objective function in (1) is convex, and it has a Q-linear rate when the objective function is strongly convex.”
From Achieving Geometric Convergence for Distributed Optimization Over Time-Varying Graphs (2017) · cites this paper as [62]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Proposition 1 ( [62]). Assume null { I -W } = span { 1 } where W ∈ R n × n . If x ∗ satisfies conditions: (i) x ∗ = Wx ∗ (consensus), (ii) 1 ⊤ ∇ f ( x ∗ ) = 0 (optimality), then the rows of x ∗ are the same as each other and the transpose of each row is an optimal solution of the problem (1) .”
From Achieving Geometric Convergence for Distributed Optimization Over Time-Varying Graphs (2017) · cites this paper as [62]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Algorithm 1: EXTRA · p. 9
“null { U } = (span { 1 } ) ⊥”
§ Algorithm 1: EXTRA · p. 7
“null { W -˜ W } = span { 1 } , null { I -˜ W } ⊇ span { 1 } .”
Citations
Cites
Distributed Subgradient Methods for Multi-Agent Optimization
Nedic, A., & Ozdaglar, A. (2009) · IEEE Transactions on Automatic Control · doi:10.1109/tac.2008.2009515 · Cited by 3,719
Fast linear iterations for distributed averaging
Xiao, L., & Boyd, S. (2004) · Systems & Control Letters · doi:10.1016/j.sysconle.2004.02.022 · Cited by 2,706
Distributed Optimization Over Time-Varying Directed Graphs
Nedic, A., & Olshevsky, A. (2015) · IEEE Transactions on Automatic Control · doi:10.1109/tac.2014.2364096 · Cited by 1,187
Distributed average consensus with least-mean-square deviation
Xiao, L., Boyd, S., & Kim, S.-J. (2007) · Journal of Parallel and Distributed Computing · doi:10.1016/j.jpdc.2006.08.010 · Cited by 1,107
Optimal decentralized protocol for electric vehicle charging
Gan, L., Topcu, U., & Low, S. H. (2013) · IEEE Transactions on Power Systems · doi:10.1109/tpwrs.2012.2210288 · Cited by 997
Dual Averaging for Distributed Optimization: Convergence Analysis and Network Scaling
Duchi, J. C., Agarwal, A., & Wainwright, M. J. (2012) · IEEE Transactions on Automatic Control · doi:10.1109/tac.2011.2161027 · Cited by 947
On the Linear Convergence of the ADMM in Decentralized Consensus Optimization
Shi, W., Ling, Q., Yuan, K., Wu, G., & Yin, W. (2014) · IEEE Transactions on Signal Processing · doi:10.1109/tsp.2014.2304432 · Cited by 820
Self-citationDistributed Stochastic Subgradient Projection Algorithms for Convex Optimization
Sundhar Ram, S., Nedić, A., & Veeravalli, V. V. (2010) · Journal of Optimization Theory and Applications · doi:10.1007/s10957-010-9737-7 · Cited by 814 · cited 1×
“1) has additional constraints that force x into a bounded set, which also leads to bounded (sub)gradients and a Hessian, projected first-order algorithms are applicable [27, 37].”
BackgroundOn Distributed Convex Optimization Under Inequality and Equality Constraints
Zhu, M., & Martinez, S. (2012) · IEEE Transactions on Automatic Control · doi:10.1109/tac.2011.2167817 · Cited by 759
Fastest Mixing Markov Chain on a Graph
Boyd, S., Diaconis, P., & Xiao, L. (2004) · SIAM Review · doi:10.1137/s0036144503423264 · Cited by 744
Research works printed but not linked: 6
- I. Chen, Fast Distributed First-Order Methods , Master's thesis, Department of Electrical Engineering and Computer Science, Massachusetts Institute of Technology, Cambridge, MA, 2012.
- Forero P., 2010, J. Mach. Learn. Res., 59, 1663
- B. Johansson, On Distributed Optimization in Networked Systems , Ph.D. thesis, KTH, Stockholm, Sweden, 2008.
- Ling Q., 2012, NJ, 2925
- Nedic A., 2013, NJ, 6855
- J. Tsitsiklis, Problems in Decentralized Decision Making and Computation , Ph.D. thesis, Department of Electrical Engineering and Computer Science, Massachusetts Institute of Technology, Cambridge, MA, 1984.
Cited by
SCAFFOLD: Stochastic Controlled Averaging for Federated Learning
Karimireddy, S. P., Kale, S., Mohri, M., Reddi, S. J., Stich, S. U., & Suresh, A. T. (2019) · arXiv · doi:10.48550/arxiv.1910.06378 · Cited by 1,734
Achieving Geometric Convergence for Distributed Optimization Over Time-Varying Graphs
Nedić, A., Olshevsky, A., & Shi, W. (2017) · SIAM Journal on Optimization · doi:10.1137/16m1084316 · Cited by 1,069
Self-citationA survey of distributed optimization
Yang, T., Yi, X., Wu, J., Yuan, Y., Wu, D., Meng, Z., Hong, Y., Wang, H., Lin, Z., & Johansson, K. H. (2019) · Annual Reviews in Control · doi:10.1016/j.arcontrol.2019.05.006 · Cited by 913
Decentralized federated learning: Fundamentals, state of the art, frameworks, trends, and challenges
Martínez Beltrán, E. T., Pérez, M. Q., Sánchez, P. M. S., Bernal, S. L., Bovet, G., Pérez, M. G., Pérez, G. M., & Celdrán, A. H. (2023) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2023.3315746 · Cited by 625
“Some examples are Decentralized Gradient Descent (DGD) [104], decentralized Alternating Direction Method of Multipliers (ADMM) [105], EXTRA [106], and ADMM based on Jacobi-Proximal [107].”
Harnessing Smoothness to Accelerate Distributed Optimization
Qu, G., & Li, N. (2018) · IEEE Transactions on Control of Network Systems · doi:10.1109/tcns.2017.2698261 · Cited by 565
Metadata
- Authors
- Shi, W., Ling, Q., Wu, G., & Yin, W.
- Venue
- SIAM Journal on Optimization
- Published
- 2015-01
- Volume
- 25
- Issue
- 2
- Pages
- 944-966
- ISSN
- 1052-6234 (ISSN-L)
- 1095-7189
- OpenAlex
- W1571416372
- Cited by
- 1,261
- References
- 25
- Citations by year
- 2026: 75 · 2025: 116 · 2024: 131 · 2023: 131 · 2022: 145 · 2021: 138 · 2020: 158 · 2019: 140 · 2018: 97 · 2017: 62 · 2016: 43 · 2015: 21
- FWCI
- 85.01
- Type
- journal article
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- SIAM Journal on Optimization (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- National Science Foundation (0748839, 1317602)
- National Natural Science Foundation of China (61004137)
- China Scholarship Council
- Ministry of Industry and Information Technology of the People's Republic of China
- Topics
- Physical Sciences › Engineering › Control and Systems Engineering › Distributed Control Multi-Agent Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Stochastic Gradient Optimization Techniques
- Physical Sciences › Computer Science › Computer Networks and Communications › Distributed Sensor Networks and Detection Algorithms
- Keywords
- multi-agent systems, large step size, linear convergence, ergodic convergence rate, strongly convex functions, distributed optimization
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: EXTRA: An Exact First-Order Algorithm for Decentralized Consensus Optimization. https://app.cochat.ai/papers/10.1137/14096668x
- The paper
- Shi, W., Ling, Q., Wu, G., & Yin, W. (2015). EXTRA: An Exact First-Order Algorithm for Decentralized Consensus Optimization. SIAM Journal on Optimization. https://doi.org/10.1137/14096668x
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
