

The DOI matches its Crossref record; 59 of the 59 references it cites were found in a registry or an index; 6 of the 16 sources its claims cite were checked for support.
Grounded Copilot: How Programmers Interact with Code-Generating Models
Open accessAbstract
Powered by recent advances in code-generating models, AI assistants like Github Copilot promise to change the face of programming forever. But what is this new face of programming? We present the first grounded theory analysis of how programmers interact with Copilot, based on observing 20 participants—with a range of prior experience using the assistant—as they solve diverse programming tasks across four languages. Our main finding is that interactions with programming assistants are bimodal : in acceleration mode , the programmer knows what to do next and uses Copilot to get there faster; in exploration mode , the programmer is unsure how to proceed and uses Copilot to explore their options. Based on our theory, we provide recommendations for improving the usability of future AI programming assistants.
Overview
CoChat Summary
TL;DR
This paper presents a grounded theory of how programmers interact with GitHub Copilot, based on observing 20 participants across four programming languages. Its central finding is that Copilot-assisted programming is bimodal: programmers use Copilot either in acceleration mode, to execute a known plan faster, or in exploration mode, to discover how to proceed.
Key findings
- Interactions with Copilot are bimodal: acceleration mode occurs when the programmer already knows what to do next and uses Copilot to get there faster; exploration mode occurs when the programmer is unsure how to proceed and uses Copilot to explore options or get a starting point.
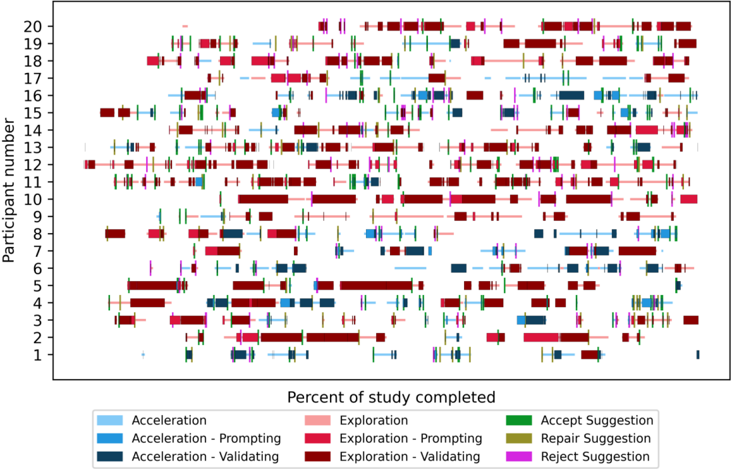
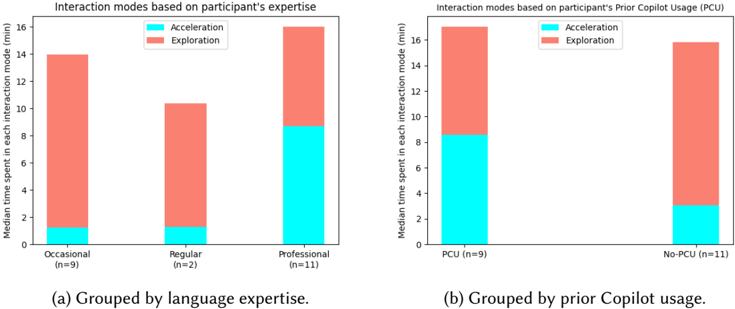
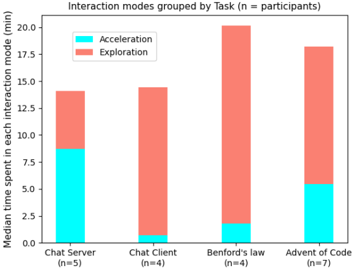
- Across all participants, total study time in exploration mode was 248.6 minutes, more than twice the 104.7 minutes in acceleration mode.
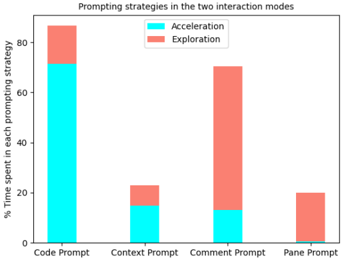
- Prompting strategies differed by mode: in acceleration mode, code prompts were most common (71.4%) and context prompts second (15.2%); in exploration mode, comment prompts were much more common than in acceleration mode (57.2% vs 13.1%).
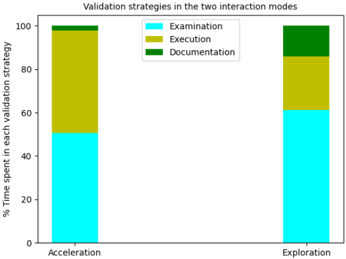
- Validation also differed: exploration involved more careful examination and documentation reading, while acceleration more often used execution for rapid feedback; participants also used five livestream videos to confirm behavior consistent with the theory.
Methods
- The authors conducted a Straussian grounded theory study with 20 participants (15 from academia, 5 from industry; 9 had prior Copilot usage) who solved programming tasks with Copilot across Python, Rust, Haskell, and Java.
- Participants completed a training task, a core task lasting about 20–40 minutes while talking through their interactions, and a semi-structured interview; sessions were recorded and transcribed.
- Analysis interleaved data collection and qualitative coding, with open, axial, and selective coding, theoretical sampling, and theoretical saturation at the 20th participant; the authors then re-coded videos quantitatively and qualitatively analyzed five livestream videos from YouTube and Twitch.
Limitations
- Stated in the paper: participants worked on tasks of the authors’ design rather than their own projects, and the tasks focused only on code authorship, not refactoring, testing, debugging, or other software engineering activities.
- Stated in the paper: the 20-participant sample skews toward academia and is not representative of all programmers; 11 participants had not used Copilot before the study, and prior users may have formed usage patterns during the technical preview.
- Stated in the paper: the authors could not observe programmers over a longer period to study changing usage patterns, and rapid progress in code-generating models could render the findings obsolete.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
4 Valid · 0 Not valid · 8 Not checked · 13 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“OpenAI's Codex model [Chen et al. 2021], which contains 12 billion model parameters and is trained on 54 million software repositories on GitHub, is able to correctly solve 30-70% of novel Python problems”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 1 INTRODUCTION
What the sources say
- Partly supportedcites [Chen et al. 2021] sourceExperimental — accuracy not yet measured
Section 3.1 (p. 4) says the training data came from 54 million public GitHub repositories, and Section 3 (p. 4) describes Codex models with up to 12 billion parameters. The Abstract (p. 1) reports 28.8% of HumanEval problems solved with one sample and 70.2% with 100 samples per problem. The claimed 30–70% range is approximately right, but it omits that the upper end required repeated sampling and evaluation on a specific problem set. (LLM, conf=0.86)
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Copilot is powered by the OpenAI Codex family of models [Chen et al. 2021], which are derived by fine-tuning GPT-3 [Brown et al. 2020] on publicly available Github repositories.”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 2 COPILOT-ASSISTED PROGRAMMING, BY EXAMPLE
What the sources say
- Supportedcites [Chen et al. 2021] source
The Introduction (p. 1) says descendants of the Codex models described in this paper power GitHub Copilot. The Abstract (p. 1) identifies Codex as fine-tuned on publicly available GitHub code, and Methods (p. 4) describes fine-tuning from the GPT-3 model family. (LLM, conf=0.94)
- Supportedcites [Brown et al. 2020] source
The Brown et al. citation is attached to “GPT-3,” identifying the model used in the citing sentence. The Abstract (p. 1) states that the paper trains GPT-3. The separate claims about Copilot, Codex, and GitHub repositories are not attributed to this citation. (LLM, conf=0.93)
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“has recently been adopted to study phenomena in software engineering [Stol et al. 2016] and programming languages [Lubin and Chasins 2021].”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 1 INTRODUCTION
What the sources say
- Supportedcites [Stol et al. 2016] source
The citation to Stol et al. is attached to the software-engineering portion of the sentence, not the programming-languages portion. The Conclusion (p. 11) describes grounded theory as an increasingly popular research method in software engineering and reports its use in SE studies. (LLM, conf=0.94)
- Supportedcites [Lubin and Chasins 2021] source
The Lubin and Chasins citation is attached to the programming-languages portion of the sentence. Section 8.1 describes their work as a grounded theory analysis of programming sessions by expert programmers, and Section 4 presents the resulting theory. The separate software-engineering portion is attributed to Stol et al., not this source. (LLM, conf=0.94)
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“We follow the framework laid out by Strauss and Corbin [Strauss and Corbin 1990], commonly called Straussian Grounded Theory [Stol et al. 2016].”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > Grounded Theory Process.
What the sources say
- Not matchedcites [Strauss and Corbin 1990]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Supportedcites [Stol et al. 2016] source
The citation to Stol et al. supports the name of the framework, not the citing authors’ statement that they follow it. Section 2.3 (p. 4) explicitly identifies Strauss and Corbin’s grounded theory as “Straussian GT.” (LLM, conf=0.95)
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our main finding is that interactions with programming assistants are bimodal: in acceleration mode, the programmer knows what to do next and uses Copilot to get there faster; in exploration mode, the programmer is unsure how to proceed and uses Copilot to explore their options.”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > Abstract
20 more claims
Create a free account to see all 25 claims and every source verdict.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Earlier research noted the difficulties users faced in effectively communicating intent and matching their abstraction level to the model's capabilities, often relying on explicit comments (Sarkar et al., 2022a; Barke et al., 2023).”
From Vibe coding: programming through conversation with artificial intelligence (2025) · cites this paper as Barke et al., 2023
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“While a number of researchers have looked at how current developers may use LLM-based tools [32,52,81] and how LLM-tools may be incorporated into professional software development tools [84], the participants in these studies have been programmers who learned to code initially without using LLMs.”
From The Robots Are Here: Navigating the Generative AI Revolution in Computing Education (2023) · cites this paper as [32]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“These two activities align with the grounded theory proposed by Barke et al. [18], which describes two developers' interaction modes with AI assistants -acceleration (supported by code generation) and exploration (supported by code summarization).”
From Using AI-based coding assistants in practice: State of affairs, perceptions, and ways forward (2025) · cites this paper as [18]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This focus on augmenting the content quality of completions has inadvertently overshadowed a vital aspect of the user experience: the interaction dynamics between the developers and the AI tools [2, 34, 42].”
From A Transformer-Based Approach for Smart Invocation of Automatic Code Completion (2024) · cites this paper as [2]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This introduces a workflow where the programmer may intentionally allow the AI to 'drive' more consistently, even for familiar tasks, creating an fluid interaction style that is distinct from the segmented modes previously identified (Barke et al., 2023).”
From Vibe coding: programming through conversation with artificial intelligence (2025) · cites this paper as Barke et al., 2023
Experimental — accuracy not yet measured
16 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > Usability of Copilot.
“only one participant in our study was an undergraduate student”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > PCU
“P9 Rust 1 Occasional No Undergraduate Student Benford's law P10 Python Occasional No Undergraduate Student Chat Client”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 4.2.5 Programmers Validate Suggestions Explicitly.
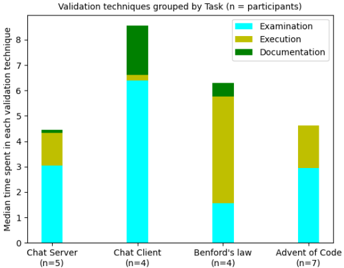
“All participants in the Advent of Code task ran their code to check whether they parsed the input file correctly.”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > Static analysis.
“P17 did not run their code even once for the Advent of Code task”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 5.1.2 Prompting Strategies across Interaction Modes.
“Fig. 6 shows the aggregate percentage of times the 20 participants invoked Copilot using the four different prompting strategies.”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 8 LIMITATIONS AND THREATS TO VALIDITY
“Fig. 6.Prevalence of prompting strategy as percentage of total prompting time.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > 4.1.2 Programmers Focus on Small Logical Units.
“when P1 wanted to send a message to a client connection object in the Chat Client task”
§ Grounded Copilot: How Programmers Interact with Code-Generating Models > PCU
“P1 Python Professional Yes Professor Chat Server”
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Exploiting Generative AI to Scale up Intelligent Tutoring Systems
Jakubův, J., Chvalovský, K., Goertzel, Z., Kaliszyk, C., Olšák, M., Piotrowski, B., Schulz, S., Suda, M., & Urban, J. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,658
The Discovery of Grounded Theory; Strategies for Qualitative Research
Glaser, B. G., Strauss, A. L., & Strutzel, E. (1968) · Nursing Research · doi:10.1097/00006199-196807000-00014 · Cited by 39,449
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
The SAGE Handbook of Grounded Theory
Bryant, A., & Charmaz, K. (2007) · SAGE · doi:10.4135/9781848607941 · Cited by 2,798
Flow and the Foundations of Positive Psychology: The Collected Works of Mihaly Csikszentmihalyi
Csikszentmihalyi, M. (2014) · doi:10.1007/978-94-017-9088-8 · Cited by 1,653
Evaluating Large Language Models Trained on Code
Chen, M., Tworek, J., Jun, H., Yuan, Q., Pinto, H. P. D. O., Kaplan, J., Edwards, H., Burda, Y., Joseph, N., Brockman, G., et al. (2021) · arXiv · doi:10.48550/arxiv.2107.03374 · Cited by 1,436
Competition-Level Code Generation with AlphaCode
Li, Y., Choi, D., Chung, J., Kushman, N., Schrittwieser, J., Leblond, R., Eccles, T., Keeling, J., Gimeno, F., Lago, A. D., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.07814 · Cited by 1,043
(2000) · doi:10.1145/351240.351266 · Cited by 753
Vaithilingam, P., Zhang, T., & Glassman, E. L. (2022) · CHI Conference on Human Factors in Computing Systems Extended Abstracts · doi:10.1145/3491101.3519665 · Cited by 660
Automating string processing in spreadsheets using input-output examples
Gulwani, S. (2011) · ACM SIGPLAN Notices · doi:10.1145/1925844.1926423 · Cited by 581
Code completion with statistical language models
Raychev, V., Vechev, M., & Yahav, E. (2014) · Proceedings of the 35th ACM SIGPLAN Conference on Programming Language Design and Implementation · doi:10.1145/2594291.2594321 · Cited by 555
Stimulus structures and mental representations in expert comprehension of computer programs
Pennington, N. (1987) · Cognitive Psychology · doi:10.1016/0010-0285(87)90007-7 · Cited by 526
Asleep at the Keyboard? Assessing the Security of GitHub Copilot’s Code Contributions
Pearce, H., Ahmad, B., Tan, B., Dolan-Gavitt, B., & Karri, R. (2022) · 2022 IEEE Symposium on Security and Privacy (SP) · doi:10.1109/sp46214.2022.9833571 · Cited by 476
Grounded theory in software engineering research: a critical review and guidelines
Stol, K.-J., Ralph, P., & Fitzgerald, B. (2016) · Proceedings of the 38th International Conference on Software Engineering · doi:10.1145/2884781.2884833 · Cited by 470 · cited 3×
“[Stol et al. 2016] provide a survey and a critical evaluation of 93 GT studies in software engineering.”
BackgroundMethodAutomating string processing in spreadsheets using input-output examples
Gulwani, S. (2011) · Proceedings of the 38th annual ACM SIGPLAN-SIGACT symposium on Principles of programming languages · doi:10.1145/1926385.1926423 · Cited by 446
Solar-Lezama, A. (2013) · International Journal on Software Tools for Technology Transfer · doi:10.1007/s10009-012-0249-7 · Cited by 226
DeepCoder: Learning to Write Programs
Balog, M., Gaunt, A. L., Brockschmidt, M., Nowozin, S., & Tarlow, D. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1611.01989 · Cited by 212
Software Design — Cognitive Aspects
Détienne, F. (2002) · Practitioner Series · doi:10.1007/978-1-4471-0111-6 · Cited by 205
Code completion with statistical language models
Raychev, V., Vechev, M., & Yahav, E. (2014) · ACM SIGPLAN Notices · doi:10.1145/2666356.2594321 · Cited by 189
InCoder: A Generative Model for Code Infilling and Synthesis
Fried, D., Aghajanyan, A., Lin, J., Wang, S., Wallace, E., Shi, F., Zhong, R., Yih, W.-T., Zettlemoyer, L., & Lewis, M. (2022) · arXiv · doi:10.48550/arxiv.2204.05999 · Cited by 187
OverCode: Visualizing Variation in Student Solutions to Programming Problems at Scale
Glassman, E. L., Scott, J., Singh, R., Guo, P. J., & Miller, R. C. (2015) · ACM Transactions on Computer-Human Interaction · doi:10.1145/2699751 · Cited by 177
Curiosity, Creativity, and Surprise as Analytic Tools: Grounded Theory Method
Muller, M. J. (2014) · Springer eBooks · doi:10.1007/978-1-4939-0378-8_2 · Cited by 173
Motivational Effects on Self-Regulated Learning with Different Tasks
Vollmeyer, R., & Rheinberg, F. (2006) · Educational Psychology Review · doi:10.1007/s10648-006-9017-0 · Cited by 173
Neural-Guided Deductive Search for Real-Time Program Synthesis from ExamplesPreprint
Kalyan, A., Mohta, A., Polozov, O., Batra, D., Jain, P., & Gulwani, S. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1804.01186 · Cited by 166
In-IDE Code Generation from Natural Language: Promise and Challenges
Xu, F. F., Vasilescu, B., & Neubig, G. (2022) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3487569 · Cited by 154
In-IDE Code Generation from Natural Language: Promise and Challenges
Xu, F. F., Vasilescu, B., & Neubig, G. (2021) · arXiv · doi:10.48550/arxiv.2101.11149 · Cited by 153
Programmers Are Users Too: Human-Centered Methods for Improving Programming Tools
Myers, B. A., Ko, A. J., LaToza, T. D., & Yoon, Y. (2016) · Computer · doi:10.1109/mc.2016.200 · Cited by 144
Drosos, I., Barik, T., Guo, P. J., DeLine, R. A., & Gulwani, S. (2020) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3313831.3376442 · Cited by 142
Perfection Not Required? Human-AI Partnerships in Code Translation
Weisz, J. D., Muller, M., Houde, S., Richards, J., Ross, S. I., Martinez, F., Agarwal, M., & Talamadupula, K. (2021) · 26th International Conference on Intelligent User Interfaces · doi:10.1145/3397481.3450656 · Cited by 129
Rousillon: Scraping Distributed Hierarchical Web Data
Chasins, S., Mueller, M., & Bodík, R. (2018) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3242587.3242661 · Cited by 119
Live functional programming with typed holes
Omar, C., Voysey, I., Chugh, R., & Hammer, M. A. (2019) · Proceedings of the ACM on Programming Languages · doi:10.1145/3290327 · Cited by 109
Interactive Program Synthesis by Augmented Examples
Zhang, T., Lowmanstone, L., Wang, X., & Glassman, E. L. (2020) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3379337.3415900 · Cited by 80
Jiang, E., Toh, E., Molina, A., Olson, K., Kayacik, C., Donsbach, A., Cai, C. J., & Terry, M. (2022) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3491102.3501870 · Cited by 79
Incorporating External Knowledge through Pre-training for Natural Language to Code Generation
Xu, F. F., Jiang, Z., Yin, P., Vasilescu, B., & Neubig, G. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.538 · Cited by 78
Falx: Synthesis-Powered Visualization Authoring
Wang, C., Feng, Y., Bodík, R., Dillig, I., Cheung, A., & Ko, A. J. (2021) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3411764.3445249 · Cited by 62
A rational reinterpretation of dual-process theories
Milli, S., Lieder, F., & Griffiths, T. L. (2021) · Cognition · doi:10.1016/j.cognition.2021.104881 · Cited by 61
The Impact of Background and Experience on Software Inspections
Carver, J. C. (2004) · Empirical Software Engineering · doi:10.1023/b:emse.0000027786.04555.97 · Cited by 61
On the fly synthesis of edit suggestions
Miltner, A., Gulwani, S., Le, V., Leung, A., Radhakrishna, A., Soares, G., Tiwari, A., & Udupa, A. (2019) · Proceedings of the ACM on Programming Languages · doi:10.1145/3360569 · Cited by 57
Projection Boxes: On-the-fly Reconfigurable Visualization for Live Programming
Lerner, S. (2020) · Proceedings of the 2020 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3313831.3376494 · Cited by 54
An Empirical Cybersecurity Evaluation of GitHub Copilot's Code ContributionsPreprint
Pearce, H., Ahmad, B., Tan, B., Dolan-Gavitt, B., & Karri, R. (2021) · arXiv.org · doi:10.48550/arxiv.2108.09293 · Cited by 53
Small-Step Live Programming by Example
Ferdowsi, K., Ordookhanians, A., Peleg, H., Lerner, S., & Polikarpova, N. (2020) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3379337.3415869 · Cited by 52
Self-citationProgramming not only by example
Peleg, H., Shoham, S., & Yahav, E. (2018) · ACM/IEEE International Conference on Software Engineering: Companion Proceedings (ICSE-Companion) · doi:10.1145/3180155.3180189 · Cited by 49
Efficient Training of Language Models to Fill in the Middle
Bavarian, M., Jun, H., Tezak, N., Schulman, J., McLeavey, C., Tworek, J., & Chen, M. (2022) · arXiv · doi:10.48550/arxiv.2207.14255 · Cited by 47
What is it like to program with artificial intelligence?
Sarkar, A., Gordon, A. D., Negreanu, C., Poelitz, C., Ragavan, S. S., & Zorn, B. (2022) · arXiv · doi:10.48550/arxiv.2208.06213 · Cited by 47 · cited 1×
“[Sarkar et al. 2022] compiled observations from the above user studies and additionally gathered experience reports of programming assistants usage from Hacker News.”
BackgroundExploring the Learnability of Program Synthesizers by Novice Programmers
Jayagopal, D., Lubin, J., & Chasins, S. E. (2022) · Proceedings of the 35th Annual ACM Symposium on User Interface Software and Technology · doi:10.1145/3526113.3545659 · Cited by 40 · cited 2×
“[Jayagopal et al. 2022] study how undergraduate students learned to use six different synthesizers— Copilot among them—with different interaction modes.”
BackgroundInterpretable Program Synthesis
Zhang, T., Chen, Z., Zhu, Y., Vaithilingam, P., Wang, X., & Glassman, E. L. (2021) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3411764.3445646 · Cited by 36
Learning to Complete Code with SketchesPreprint
Guo, D., Svyatkovskiy, A., Yin, J., Duan, N., Brockschmidt, M., & Allamanis, M. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.10158 · Cited by 35
PLIERS: A Process that Integrates User-Centered Methods into Programming Language Design
Coblenz, M. J., Kambhatla, G., Koronkevich, P., Wise, J., Barnaby, C., Sunshine, J. S., Aldrich, J., & Myers, B. A. (2021) · ACM Transactions on Computer-Human Interaction · doi:10.1145/3452379 · Cited by 34
Digging for fold: synthesis-aided API discovery for Haskell
James, M. B., Guo, Z. K., Wang, Z., Doshi, S., Peleg, H., Jhala, R., & Polikarpova, N. (2020) · Proceedings of the ACM on Programming Languages · doi:10.1145/3428273 · Cited by 34
Self-citationProgramming with a read-eval-synth loop
Peleg, H., Gabay, R., Itzhaky, S., & Yahav, E. (2020) · Proceedings of the ACM on Programming Languages · doi:10.1145/3428227 · Cited by 22
reCode : A Lightweight Find-and-Replace Interaction in the IDE for Transforming Code by Example
Ni, W., Sunshine, J. S., Le, V., Gulwani, S., & Barik, T. (2021) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3472749.3474748 · Cited by 22
Synthesizing analytical SQL queries from computation demonstration
Zhou, X., Bodík, R., Cheung, A., & Wang, C. (2022) · ACM SIGPLAN Conference on Programming Language Design and Implementation (PLDI) · doi:10.1145/3519939.3523712 · Cited by 19
How statically-typed functional programmers write code
Lubin, J., & Chasins, S. E. (2021) · Proceedings of the ACM on Programming Languages · doi:10.1145/3485532 · Cited by 18 · cited 2×
“” P16 normally writes a high-level design first and then gets to function implementations—as the grounded theory from [Lubin and Chasins 2021] describes of functional programmers.”
BackgroundLooPy: interactive program synthesis with control structures
Ferdowsifard, K., Barke, S., Peleg, H., Lerner, S., & Polikarpova, N. (2021) · Proceedings of the ACM on Programming Languages · doi:10.1145/3485530 · Cited by 18
Self-citationDetecting Affective Flow States of Knowledge Workers Using Physiological SensorsPreprint
Lee, M. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2006.10635 · Cited by 10
Grounded Copilot: How Programmers Interact with Code-Generating Models
(2023) · doi:10.5281/zenodo.7713789 · Cited by 2
Self-citationGrounded Copilot: How Programmers Interact with Code-Generating Models
Barke, S., James, M. B., & Polikarpova, N. (2023) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.7713769 · Cited by 2
Self-citationIncorporating External Knowledge through Pre-training for Natural Language to Code Generation
Xu, F. F., Jiang, Z., Yin, P., et al. (2020) · arXiv · doi:10.48550/arxiv.2004.09015
Research works printed but not linked: 8
- Mohammad Bavarian Heewoo Jun Nikolas Tezak John Schulman Christine McLeavey Jerry Tworek and Mark Chen. 2022. Efficient Training of Language Models to Fill in the Middle. Jul https://doi.org/10.48550/arXiv.2207.14255 arXiv:2207.14255 [cs]. · DOI · Paper page
- Daniel Fried Armen Aghajanyan Jessy Lin Sida Wang Eric Wallace Freda Shi Ruiqi Zhong Wen-tau Yih Luke Zettlemoyer and Mike Lewis. 2022. InCoder: A Generative Model for Code Infilling and Synthesis. Apr https://doi.org/10.48550/arXiv.2204.05999 arXiv:2204.05999 [cs]. · DOI · Paper page
- Daniel Kahneman . 2011. Thinking , fast and slow . Penguin Books . isbn:978-0-14-103357-0 Daniel Kahneman. 2011. Thinking, fast and slow. Penguin Books. isbn:978-0-14-103357-0
- Kite. 2020 . Kite: AI-Powered Completions for JupyterLab. https://www.kite.com/integrations/jupyter/ Kite. 2020. Kite: AI-Powered Completions for JupyterLab. https://www.kite.com/integrations/jupyter/
- Yujia Li David Choi Junyoung Chung Nate Kushman Julian Schrittwieser Rémi Leblond Tom Eccles James Keeling Felix Gimeno Agustin Dal Lago Thomas Hubert Peter Choy Cyprien de Masson d'Autume Igor Babuschkin Xinyun Chen Po-Sen Huang Johannes Welbl Sven Gowal Alexey Cherepanov James Molloy Daniel J. Mankowitz Esme Sutherland Robson Pushmeet Kohli Nando de Freitas Koray Kavukcuoglu and Oriol Vinyals. 2022. Competition-Level Code Generation with AlphaCode. https://doi.org/10.48550/ARXIV.2203.07814 · DOI · Paper page
- Anselm L. Strauss and Juliet Corbin . 1990 . Basics of Qualitative Reseach: Grounded Theory Procedures and Techniques. SAGE Publications, Inc .. isbn:0-8039-3250-2 Anselm L. Strauss and Juliet Corbin. 1990. Basics of Qualitative Reseach: Grounded Theory Procedures and Techniques. SAGE Publications, Inc.. isbn:0-8039-3250-2
- Steven J. Taylor and Robert Bogdan . 1998 . Introduction to qualitative research methods: A guidebook and resource, 3 rd ed. John Wiley and Sons Inc . isbn:978-0-471-16868-3 Steven J. Taylor and Robert Bogdan. 1998. Introduction to qualitative research methods: A guidebook and resource, 3rd ed. John Wiley and Sons Inc. isbn:978-0-471-16868-3
- Ashish Vaswani Noam Shazeer Niki Parmar Jakob Uszkoreit Llion Jones Aidan N. Gomez Lukasz Kaiser and Illia Polosukhin. 2017. Attention Is All You Need. Dec https://doi.org/10.48550/arXiv.1706.03762 arXiv:1706.03762 [cs]. · DOI · Paper page
Cited by
The Robots Are Here: Navigating the Generative AI Revolution in Computing Education
Prather, J., Denny, P., Leinonen, J., Becker, B. A., Albluwi, I., Craig, M., Keuning, H., Kiesler, N., Kohn, T., Luxton-Reilly, A., et al. (2023) · Proceedings of the 2023 Working Group Reports on Innovation and Technology in Computer Science Education · doi:10.1145/3623762.3633499 · Cited by 396
“Some focused on finding interaction patterns [32, 148, 176] while others focused more on how productivity is impacted by the use of models [101, 131], whether code produced when using AI code generators is less secure than when not [162], and how students use code explanations generated by”
BackgroundInfluentialA Survey on Large Language Models: Applications, Challenges, Limitations, and Practical Usage
Hadi, M. U., tashi, Q. A., Qureshi, R., Shah, A., muneer, A., Irfan, M., Zafar, A., Shaikh, M. B., Akhtar, N., Wu, J., et al. (2023) · doi:10.36227/techrxiv.23589741.v1 · Cited by 370
Using an LLM to Help With Code Understanding
Nam, D., Macvean, A., Hellendoorn, V., Vasilescu, B., & Myers, B. (2024) · Proceedings of the IEEE/ACM 46th International Conference on Software Engineering · doi:10.1145/3597503.3639187 · Cited by 487
Computing Education in the Era of Generative AI
Denny, P., Prather, J., Becker, B. A., Finnie-Ansley, J., Hellas, A., Leinonen, J., Luxton-Reilly, A., Reeves, B. N., Santos, E. A., & Sarsa, S. (2024) · Communications of the ACM · doi:10.1145/3624720 · Cited by 316
“Other recent work has shown that developers are more successful working with Copilot when they decompose larger programming statements into smaller tasks and then explicitly prompt Copilot for each of the subtasks [1, 18].”
BackgroundDenny, P., Kumar, V., & Giacaman, N. (2023) · Proceedings of the 54th ACM Technical Symposium on Computer Science Education V. 1 · doi:10.1145/3545945.3569823 · Cited by 287
Metadata
- Authors
- Barke, S., James, M. B., & Polikarpova, N.
- Affiliations
- University of California San Diego (US)
- Venue
- Proceedings of the ACM on Programming Languages
- Published
- 2023-04-06
- Volume
- 7
- Issue
- OOPSLA1
- Pages
- 85-111
- ISSN
- 2475-1421 (ISSN-L)
- OpenAlex
- W4362659486
- Cited by
- 436
- References
- 46
- Citations by year
- 2026: 147 · 2025: 131 · 2024: 119 · 2023: 39
- FWCI
- 102.07
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Licence
- Locations
- Proceedings of the ACM on Programming Languages (publishedVersion, cc-by)
- Funders
- National Science Foundation (2107397, 1955457)
- Topics
- Physical Sciences › Computer Science › Information Systems › Software Engineering Research
- Physical Sciences › Computer Science › Information Systems › Software Engineering Techniques and Practices
- Physical Sciences › Computer Science › Computer Science Applications › Teaching and Learning Programming
- Keywords
- GitHub Copilot, acceleration mode, exploration mode, usability, human-AI collaboration, programming tasks
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-09-27 (prompt extract-v2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
