

The DOI matches its Crossref record; 43 of the 43 references it cites were found in a registry or an index.
Rescriber: Smaller-LLM-Powered User-Led Data Minimization for LLM-Based Chatbots
Open accessAbstract
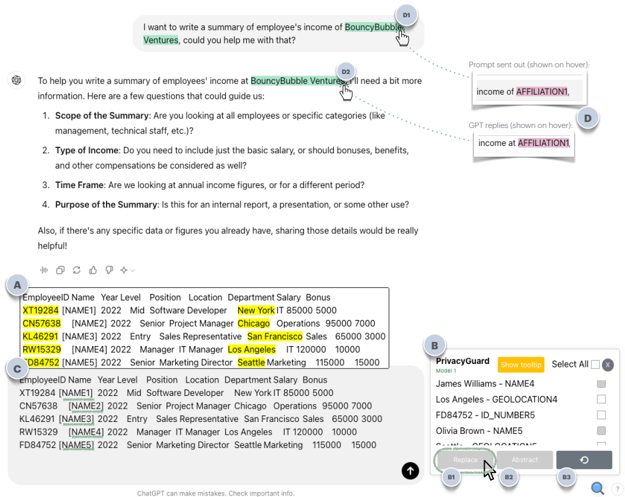
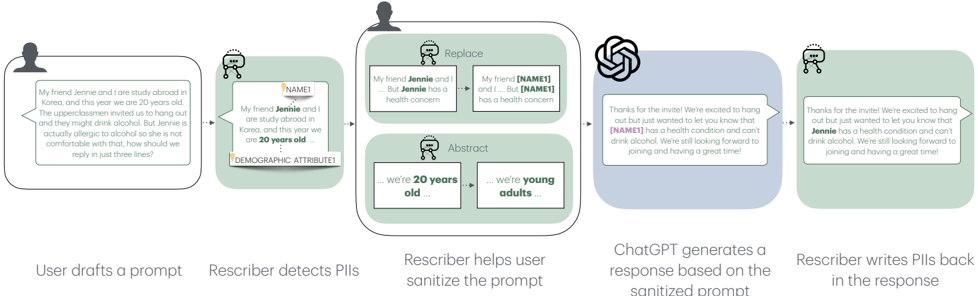
The proliferation of LLM-based conversational agents has resulted in excessive disclosure of identifiable or sensitive information.However, existing technologies fail to offer perceptible control or account for users' personal preferences about privacy-utility tradeoffs due to the lack of user involvement.To bridge this gap, we designed, built, and evaluated Rescriber, a browser extension that supports user-led data minimization in LLM-based conversational agents by helping users detect and sanitize personal information in their prompts.Our studies (N=Rescriber) showed that Rescriber helped users reduce unnecessary disclosure and addressed their privacy concerns.Users' subjective perceptions of the system powered by Llama3-8B were on par with that by GPT-4o.The comprehensiveness and consistency of the detection and sanitization emerge as essential factors that affect users' trust and perceived protection.Our findings confirm the viability of smaller-LLM-powered, userfacing, on-device privacy controls, presenting a promising approach to address the privacy and trust challenges of AI.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602
Internet Users' Information Privacy Concerns (IUIPC): The Construct, the Scale, and a Causal Model
Malhotra, N. K., Kim, S. S., & Agarwal, J. (2004) · Information Systems Research · doi:10.1287/isre.1040.0032 · Cited by 3,173 · cited 1×
“Additionally, providing granular control also helps users better minimize unnecessary disclosure by striking a balance between privacy and utility.”
(2011) · IEEE Software · doi:10.1109/ms.2011.67 · Cited by 1,989
Sparks of Artificial General Intelligence: Early experiments with GPT-4
Bubeck, S., Chandrasekaran, V., Eldan, R., Gehrke, J., Horvitz, E., Kamar, E., Lee, P., Lee, Y. T., Li, Y., Lundberg, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.12712 · Cited by 1,526
Emergent Abilities of Large Language Models
Wei, J., Tay, Y., Bommasani, R., Raffel, C., Zoph, B., Borgeaud, S., Yogatama, D., Bosma, M., Zhou, D., Metzler, D., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.07682 · Cited by 1,264
Large Language Models Can Be Strong Differentially Private LearnersPreprint
Li, X., Tramèr, F., Liang, P., & Hashimoto, T. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.05679 · Cited by 485
Schaar, P. (2010) · Identity in the Information Society · doi:10.1007/s12394-010-0055-x · Cited by 387
Beyer, H., & Holtzblatt, K. (1999) · Interactions · doi:10.1145/291224.291229 · Cited by 367
A taxonomy of privacy-preserving record linkage techniques
Vatsalan, D., Christen, P., & Verykios, V. S. (2013) · Information Systems · doi:10.1016/j.is.2012.11.005 · Cited by 295 · cited 1×
“” Concerns about identifiability also extended beyond direct identifiers to demographic details like gender, raising fears of linkage attacks [50] and broader profiles emerging from multiple data points.”
UMUX-LITE: when there's no time for the SUS
Lewis, J. R., Utesch, B. S., & Maher, D. E. (2013) · Proceedings of the SIGCHI Conference on Human Factors in Computing Systems · doi:10.1145/2470654.2481287 · Cited by 270
Research works printed but not linked: 8
- Youngwook Do, Nivedita Arora, Ali Mirzazadeh, Injoo Moon, Eryue Xu, Zhihan Zhang, Gregory D Abowd, and Sauvik Das. 2023. Powering for privacy: improving user trust in smart speaker microphones with intentional powering and perceptible assurance. In 32nd USENIX Security Symposium (USENIX Security 23). 2473–2490.
- Nikhil Kandpal, Eric Wallace, and Colin Raffel. 2022. Deduplicating training data mitigates privacy risks in language models. In International Conference on Machine Learning. PMLR, 10697–10707.
- Niloofar Mireshghallah Maria Antoniak Yash More Yejin Choi and Golnoosh Farnadi. 2024. Trust No Bot: Discovering Personal Disclosures in Human-LLM Conversations in the Wild. arXiv preprint arXiv:https://arXiv.org/abs/2407.11438 (2024). · arXiv
- Annika Willoch Olstad, Anthi Papadopoulou, and Pierre Lison. 2023. Generation of Replacement Options in Text Sanitization. In Proceedings of the 24th Nordic Conference on Computational Linguistics (NoDaLiDa). 292–300.
- Bashir Rastegarpanah Krishna Gummadi and Mark Crovella. 2021. Auditing black-box prediction models for data minimization compliance. Advances in Neural Information Processing Systems 34 (2021) 20621–20632.
- Rylan Schaeffer Brando Miranda and Sanmi Koyejo. 2024. Are emergent abilities of large language models a mirage? Advances in Neural Information Processing Systems 36 (2024).
- Tanusree Sharma, Lin Kyi, Yang Wang, and Asia J Biega. 2024. " I’m not convinced that they don’t collect more than is necessary":{ User-Controlled} Data Minimization Design in Search Engines. In 33rd USENIX Security Symposium (USENIX Security 24). 2797–2812.
- Lianmin Zheng, Wei-Lin Chiang, Ying Sheng, Siyuan Zhuang, Zhanghao Wu, Yonghao Zhuang, Zi Lin, Zhuohan Li, Dacheng Li, Eric P. Xing, Hao Zhang, Joseph E. Gonzalez, and Ion Stoica. 2024. Judging LLM-as-a-judge with MT-bench and Chatbot Arena. In Proceedings of the 37th International Conference on Neural Information Processing Systems (New Orleans, LA, USA) (NIPS ’23). Curran Associates Inc., Red Hook, NY, USA, Article 2020, 29 pages.
Cited by
Luo, H., Liu, Y., Zhang, R., Wang, J., Sun, G., Niyato, D. T., Yu, H., Xiong, Z., Wang, X., & Shen, X. (2025) · IEEE Transactions on Cognitive Communications and Networking · doi:10.1109/tccn.2025.3612760 · Cited by 93
Chen, C., Zhou, D., Ye, Y., Li, T. J.-J., & Yao, Y. (2025) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3708359.3712156 · Cited by 63
Self-citationUnderstanding Users' Privacy Perceptions Towards LLM's RAG-based Memory
Zhang, S., Ma, R., Ma, Y., Li, S., Xu, Y., Yi, X., & Li, H. (2025) · Proceedings of the 2025 Workshop on Human-Centered AI Privacy and Security · doi:10.1145/3733816.3760750 · Cited by 6
“Some operate at the data interface: OneShield [2] filters both user inputs and model outputs, while Rescriber [50] leverages an LLM to minimize sensitive content in queries in real time.”
Sharma, T., Tseng, Y., Zhang, L., Ide, A., Mack, K., Findlater, L., Gurari, D., & Wang, Y. (2025) · International ACM SIGACCESS Conference on Computers and Accessibility (ASSETS) · doi:10.1145/3663547.3746335 · Cited by 19
Towards Aligning Personalized AI Agents with Users' Privacy Preference
Zhang, S., Ma, Y., Chen, J., Li, S., Yi, X., & Li, H. (2025) · doi:10.1145/3733816.3760752 · Cited by 19
Metadata
- Authors
- Zhou, J., Xu, E., Wu, Y., & Li, T.
- Affiliations
- Northeastern University (US)
- Venue
- Proceedings of the 2025 CHI Conference on Human Factors in Computing Systems
- Publisher
- ACM
- Published
- 2025-04-25
- Pages
- 1-28
- OpenAlex
- W4409870977
- Semantic Scholar
- f1366e505de4f1d0e901903e3c17471033758a96
- Cited by
- 17
- References
- 23
- Citations by year
- 2026: 12 · 2025: 5
- FWCI
- 57.11
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- CHI Conference on Human Factors in Computing Systems (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- Topics
- Social Sciences › Sociology and Political Science › Privacy, Security, and Data Protection
- Physical Sciences › Computer Science › Artificial Intelligence › Privacy-Preserving Technologies in Data
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Keywords
- LLM-based chatbots, data minimization, user privacy control, personal information detection, prompt sanitization, browser extension, small language models, privacy-utility trade-off, user trust, sensitive information disclosure, Llama-3-8B, GPT-4o
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Rescriber: Smaller-LLM-Powered User-Led Data Minimization for LLM-Based Chatbots. https://app.cochat.ai/papers/10.1145/3706598.3713701
- The paper
- Zhou, J., Xu, E., Wu, Y., & Li, T. (2025). Rescriber: Smaller-LLM-Powered User-Led Data Minimization for LLM-Based Chatbots. Proceedings of the 2025 CHI Conference on Human Factors in Computing Systems. https://doi.org/10.1145/3706598.3713701
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
