

The DOI matches its Crossref record; 100 of the 100 references it cites were found in a registry or an index; none of the 74 sources its claims cite is checked for support yet.
Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing
Open accessAbstract
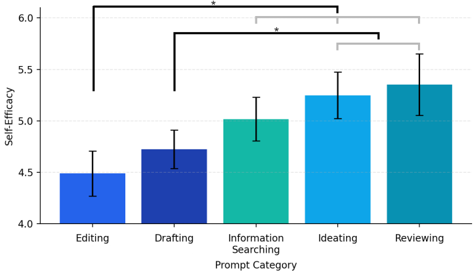
Large language models (LLMs) are increasingly used as collaborative partners in writing. However, this raises a critical challenge of authorship, as users and models jointly shape text across interaction turns. Understanding authorship in this context requires examining users’ evolving internal states during collaboration, particularly self-efficacy and trust. Yet, the dynamics of these states and their associations with users’ prompting strategies and authorship outcomes remain underexplored. We examined these dynamics through a study of 302 participants in LLM-assisted writing, capturing interaction logs and turn-by-turn self-efficacy and trust ratings. Our analysis showed that collaboration generally decreased users’ self-efficacy while increasing trust. Participants who lost self-efficacy were more likely to ask the LLM to edit their work directly, whereas those who recovered self-efficacy requested more review and feedback. Furthermore, participants with stable self-efficacy showed higher actual and perceived authorship of the final text. Based on these findings, we propose design implications for understanding and supporting authorship in human-LLM collaboration.
Overview
CoChat Summary
TL;DR
This study tracked turn-by-turn self-efficacy and trust in 302 participants completing LLM-assisted argumentative essays, finding that self-efficacy generally decreased while trust increased. Stable self-efficacy was associated with higher actual and perceived authorship, whereas decreasing self-efficacy was linked to more editing prompts and lower authorship.
Key findings
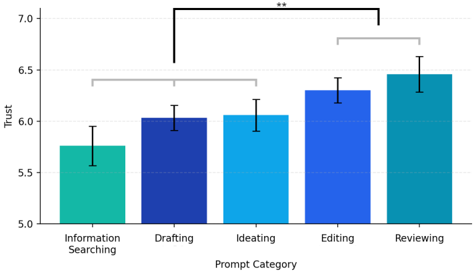
- Across 302 participants and 1,410 prompt–response pairs, self-efficacy decreased by 0.115 points per turn (p < 0.001) and trust increased by 0.111 points per turn (p < 0.001); higher trust buffered self-efficacy decline (turn × trust β = 0.038, p < 0.001).
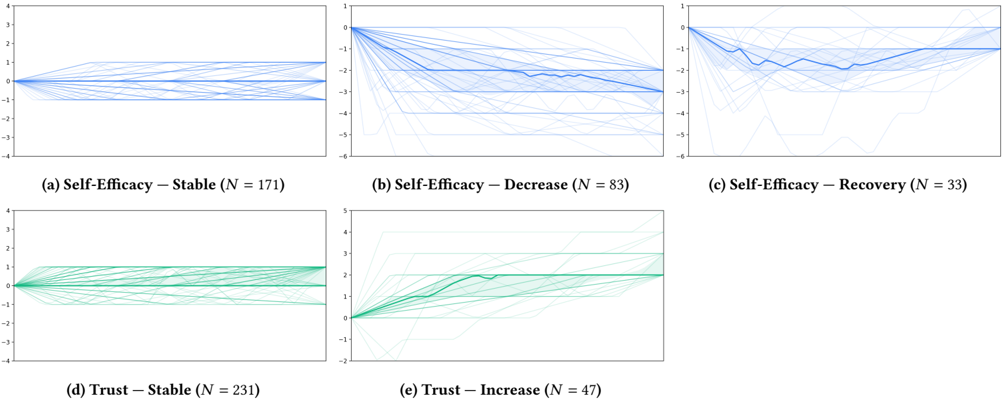
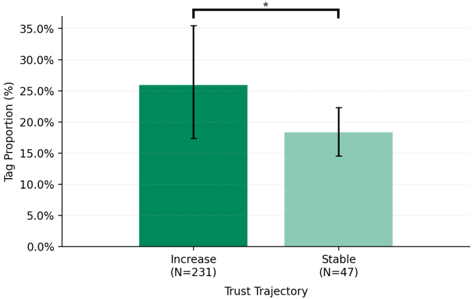
- Self-efficacy trajectories were 56.6% stable, 27.5% decrease, 10.9% recovery, 4.0% increase, and 1.0% reversion; trust trajectories were 76.5% stable, 15.6% increase, 5.3% recovery, 1.7% reversion, and 1.0% decrease.
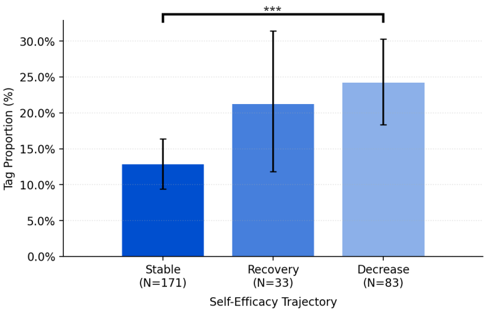
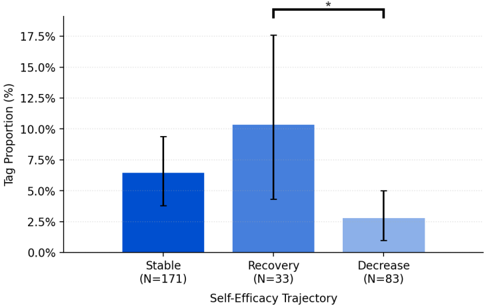
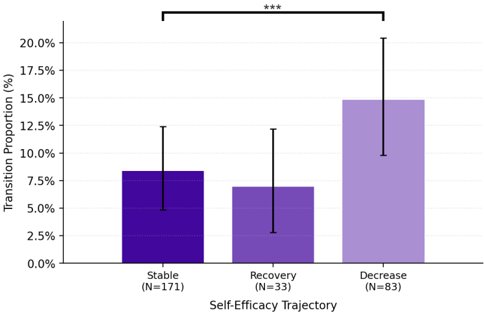
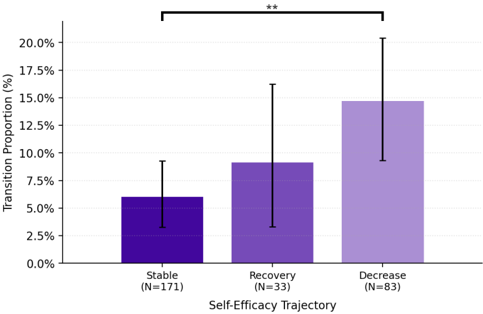
- The decrease self-efficacy group used a higher proportion of editing prompts than the stable group (p_adj < 0.001) and showed more drafting–editing and editing–editing transitions (p_adj < 0.001 and p_adj < 0.01); the recovery group used more reviewing prompts than the decrease group (p_adj < 0.05).
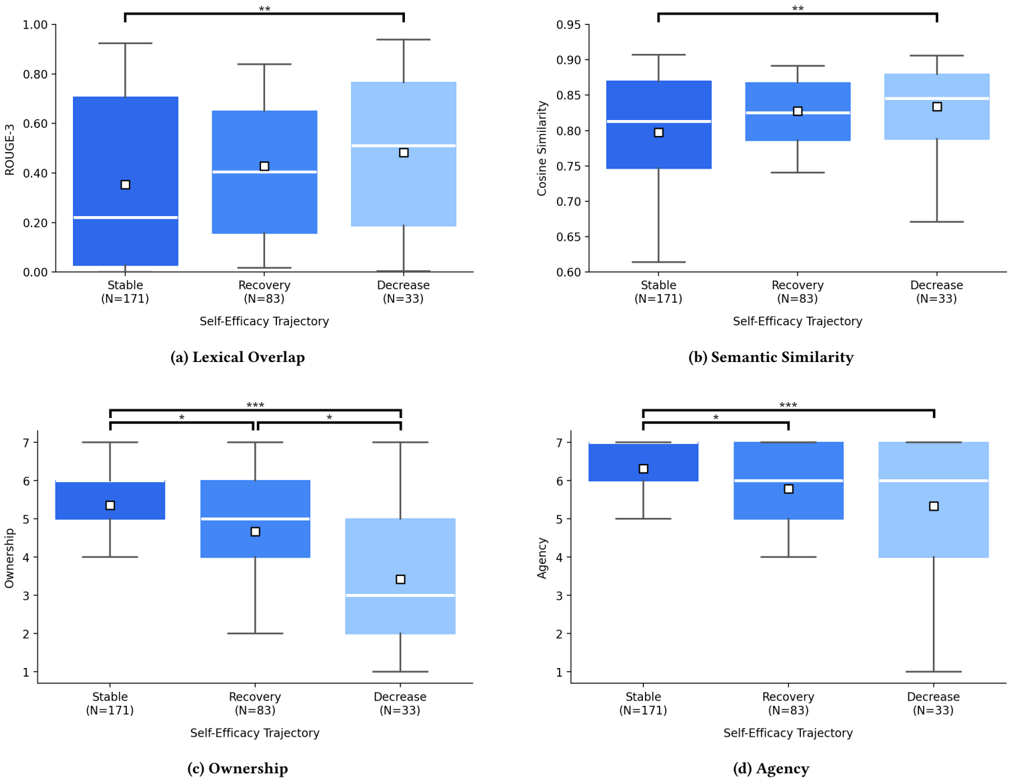
- The decrease trajectory had higher lexical overlap and semantic similarity with LLM-original content than stable (p_adj < 0.01 for both) and lower perceived ownership and agency; stable > recovery > decrease for ownership, and stable had higher agency than recovery and decrease. Trust trajectory patterns showed no significant differences across authorship measures (p > 0.05).
Methods
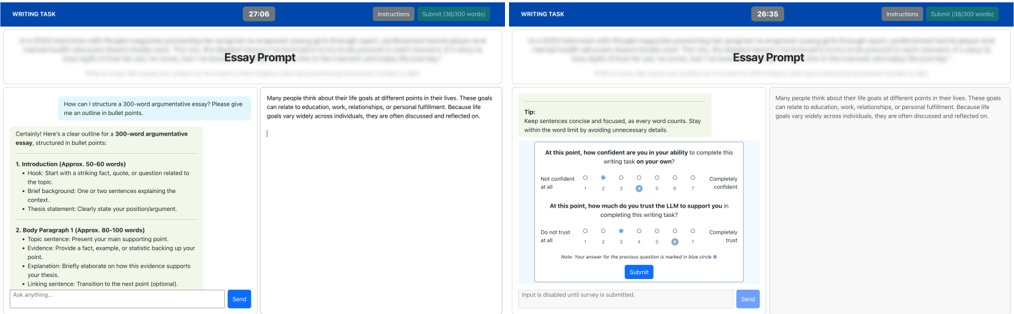
- Online experiment with 302 final participants (313 recruited, 11 excluded) from Prolific: native English speakers, approval rating ≥95%, and LLM use within the last month; participants wrote a minimum 300-word argumentative essay within 30 minutes using an embedded GPT-4.1 chat and text editor.
- Data included pre-survey baseline self-efficacy/trust, turn-by-turn 7-point self-efficacy and trust ratings before each prompt, post-survey ownership and agency, and logs of prompts, LLM responses, essay states, and timestamps.
- Analysis used a 2-point Minimal Detectable Change threshold to classify trajectories; linear mixed-effects models with random intercepts and slopes; qualitative prompt intention coding (κ = 0.867 and 0.789); ROUGE-3 lexical overlap and gemini-embedding-001 semantic similarity for actual authorship; and Kruskal-Wallis, Mann-Whitney U, and Dunn tests.
Limitations
- Stated: turn-by-turn self-reported ratings may have influenced natural interaction; 76.7% reported no effect, but 19.2% found the ratings distracting or made them more mindful, and logging was limited to in-platform events, so external tool use could not be determined.
- Stated: the study identifies empirical patterns but not qualitative reasons behind them; it was confined to a single session, did not account for individual or system factors such as task proficiency or LLM tone, and used a single LLM.
- Evident from the text: the appendix turn-level analysis aggregates across interactions without normalizing for varying numbers of turns per participant, so highly active users may contribute proportionally more data points; the authors call these associations exploratory rather than definitive.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 1 Not valid · 37 Not checked · 117 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On the other hand, participants' trust levels in the LLM were higher than that of self-efficacy, with a mean of 6.00 (𝑆𝐷 = 1.28, 𝑚𝑖𝑛 = 1, 𝑚𝑎𝑥 = 7).”
§ Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing > 4.1 Descriptive Statistics
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On average, participants' self-efficacy decreased over turns, specifically, 0.115 points per turn on the 7-point Likert scale.”
§ Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing > Changes in Self-Efficacy.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Through the mixed-effects model, we first found a significant main effect for turn on self-efficacy (𝛽 = -0.115,𝑆𝐸 = 0.023, 𝑧 = -4.90,𝑝 < 0.001).”
§ Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing > Changes in Self-Efficacy.
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also found a significant turn × trust interaction (𝛽 = 0.038, 𝑆𝐸 = 0.009, 𝑧 = 4.10, 𝑝 < 0.001).”
§ Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing > Changes in Self-Efficacy.
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Post-hoc Dunn's test with Holm-Bonferroni correction [29] further showed that users with decrease self-efficacy trajectory showed a significantly higher proportion of drafting-editing transitions than those in the stable trajectory (𝑝 adj < 0.001, Fig 5a).”
§ Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing > 4.3.2 Prompt-to-Prompt Transitions.
What the sources say
- Not matchedcites [29]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
73 more claims
Create a free account to see all 155 claims and every source verdict.
- It may state two separate claims as one. 42
- The quote only partly states this claim. 1
- Probably not a substantial claim. 44
Statistics recomputed
Every reported test result, recomputed from its test statistic and degrees of freedom. A result shows as not adding up only once an independent check has confirmed it.
- Consistentz = -4.9reported p < .001 · recomputed p < .001
“z = -4.90,p < .001”
- Consistentz = 2.63reported p < .01 · recomputed p = .009
“z = 2.63, p < .01”
- Consistentz = 4.1reported p < .001 · recomputed p < .001
“z = 4.10, p < .001”
- Consistentz = 10.13reported p < .001 · recomputed p < .001
“z = 10.13,p < .001”
- Consistentz = 3.67reported p < .001 · recomputed p < .001
“z = 3.67, p < .001”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Self-check results appear here once an independent check has confirmed them.
Citations
Cites
Self-efficacy: Toward a unifying theory of behavioral change
Bandura, A. (1977) · Psychological Review · doi:10.1037/0033-295x.84.2.191 · Cited by 43,925
An integrative model of organizational trust
Mayer, R. C., Davis, J. H., & Schoorman, F. D. (1995) · The Academy of Management Review · doi:10.2307/258792 · Cited by 10,736
ChatGPT for good? On opportunities and challenges of large language models for education
Kasneci, E., Sessler, K., Küchemann, S., Bannert, M., Dementieva, D., Fischer, F., Gasser, U., Groh, G., Günnemann, S., Hüllermeier, E., et al. (2023) · Learning and Individual Differences · doi:10.1016/j.lindif.2023.102274 · Cited by 7,326
Trust in Automation: Designing for Appropriate Reliance
Lee, J. D., & See, K. A. (2004) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1518/hfes.46.1.50_30392 · Cited by 6,605 · cited 2×
“On the other hand, the increase in trust aligns with outcome-based trust calibration in automation [44, 87], where trust evolves through the repeated observation of successful performance.”
Computer Self-Efficacy: Development of a Measure and Initial Test
Compeau, D. R., & Higgins, C. A. (1995) · MIS Quarterly · doi:10.2307/249688 · Cited by 6,553
Self-Efficacy and Academic Motivation
Schunk, D. H. (1991) · Educational Psychologist · doi:10.1080/00461520.1991.9653133 · Cited by 4,292
Self-efficacy and work-related performance: A meta-analysis.
Stajković, A. D., & Luthans, F. (1998) · Psychological Bulletin · doi:10.1037//0033-2909.124.2.240 · Cited by 3,782
Trust in Automation: Integrating Empirical Evidence on Factors That Influence Trust
Hoff, K. A., & Bashir, M. (2015) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1177/0018720814547570 · Cited by 2,817
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Understanding Power and Rules of Thumb for Determining Sample Sizes
Wilson Van Voorhis, C. R., & Morgan, B. L. (2007) · Tutorials in Quantitative Methods for Psychology · doi:10.20982/tqmp.03.2.p043 · Cited by 1,939
Research works printed but not linked: 5
- Albert Bandura. 1997. Self-efficacy: The exercise of control. Macmillan.
- Tom Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared D Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert-Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel Ziegler, Jeffrey Wu, Clemens Winter, Chris Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam McCandlish, Alec Radford, Ilya Sutskever, and Dario Amodei. 2020. Language Models are Few-Shot Learners. In Advances in Neural Information Processing Systems , H. Larochelle, M. Ranzato, R. Hadsell, M.F. Balcan, and H. Lin (Eds.), Vol. 33. Curran Associates, Inc., 1877–1901.
- Cecilia Ka Yuk Chan. 2023. Is AI Changing the Rules of Academic Misconduct? An In-depth Look at Students’ Perceptions of ’AI-giarism’. arxiv:https://arXiv.org/abs/2306.03358 [cs.CY] https://arxiv.org/abs/2306.03358 · arXiv
- Sture Holm. 1979. A Simple Sequentially Rejective Multiple Test Procedure. Scandinavian Journal of Statistics 6 2 (1979) 65–70. http://www.jstor.org/stable/4615733
- Brian Lubars and Chenhao Tan. 2019. Ask not what AI can do, but what AI should do: Towards a framework of task delegability. In Advances in Neural Information Processing Systems , H. Wallach, H. Larochelle, A. Beygelzimer, F. d'Alché-Buc, E. Fox, and R. Garnett (Eds.), Vol. 32. Curran Associates, Inc.
Cited by
The Work Behind Delegation: A Framework for Supervising AI Coding AgentsPreprint
Park, Y., Arvi, N. A. P., Lee, H. R., Lim, S., Ma, Q., & Kim, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2609.24234 · Cited by 2
Self-citationKanerva, P. (2026) · Aaltodoc (Aalto University)
Yin, M., Chiang, A., Cox, S. R., & Xiao, R. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.24729
Trust the AI, Doubt Yourself: The Effect of Urgency on Self-Confidence in Human-AI Interaction
Shajari, B., Liu, X., Dagenais, K., & Dávid, I. (2026) · ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) · doi:10.1145/3803437.3806712
Permanently Under Construction: Hypertextual Friction in an AI-Augmented Zettelkasten
Millard, D. E. (2026) · ACM Conference on Hypertext and Social Media (HT) · doi:10.1145/3800935.3830837
Metadata
- Authors
- Park, Y. S., Arvi, N. A. P., Kim, S., & Kim, J.
- Affiliations
- Korea Advanced Institute of Science and Technology (KR)
- Venue
- Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems
- Publisher
- ACM
- Published
- 2026-04-13
- Pages
- 1-18
- OpenAlex
- W7154187432
- Cited by
- 8
- References
- 96
- Citations by year
- 2026: 8
- FWCI
- 29.26
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- CHI Conference on Human Factors in Computing Systems (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Funders
- National Research Foundation of Korea (RS-2025-00557726)
- Institute of Information & Communications Technology Planning & Evaluation of Korea (RS-2024-00443251)
- Topics
- Physical Sciences › Computer Science › Human-Computer Interaction › Innovative Human-Technology Interaction
- Social Sciences › Human Factors and Ergonomics › Human-Automation Interaction and Safety
- Physical Sciences › Computer Science › Human-Computer Interaction › Usability and User Interface Design
- Keywords
- authorship, large language models, human-LLM collaboration, self-efficacy, trust, prompting strategies, text editing
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing. https://app.cochat.ai/papers/10.1145/3772318.3790276
- The paper
- Park, Y. S., Arvi, N. A. P., Kim, S., & Kim, J. (2026). Authorship Drift: How Self-Efficacy and Trust Evolve During LLM-Assisted Writing. Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems. https://doi.org/10.1145/3772318.3790276
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
