

The DOI matches its Crossref record; 60 of the 61 references it cites were found in a registry or an index.
Redundancy in electronic health record corpora: analysis, impact on text mining performance and mitigation strategies
Open accessAbstract
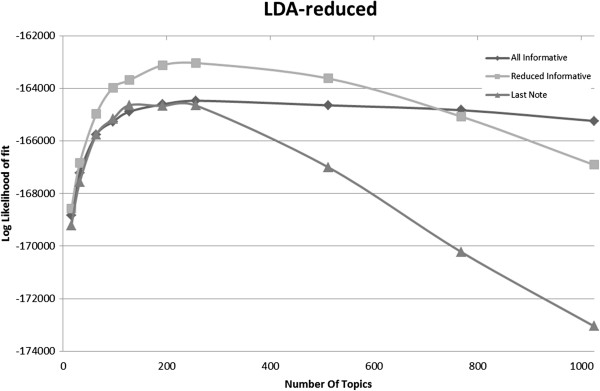
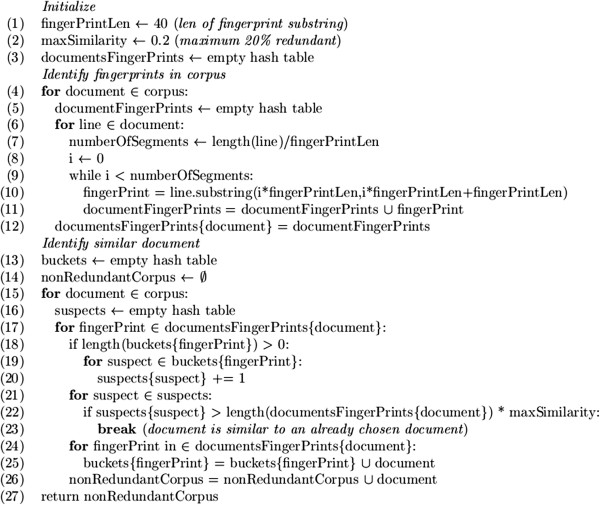
BACKGROUND: The increasing availability of Electronic Health Record (EHR) data and specifically free-text patient notes presents opportunities for phenotype extraction. Text-mining methods in particular can help disease modeling by mapping named-entities mentions to terminologies and clustering semantically related terms. EHR corpora, however, exhibit specific statistical and linguistic characteristics when compared with corpora in the biomedical literature domain. We focus on copy-and-paste redundancy: clinicians typically copy and paste information from previous notes when documenting a current patient encounter. Thus, within a longitudinal patient record, one expects to observe heavy redundancy. In this paper, we ask three research questions: (i) How can redundancy be quantified in large-scale text corpora? (ii) Conventional wisdom is that larger corpora yield better results in text mining. But how does the observed EHR redundancy affect text mining? Does such redundancy introduce a bias that distorts learned models? Or does the redundancy introduce benefits by highlighting stable and important subsets of the corpus? (iii) How can one mitigate the impact of redundancy on text mining? RESULTS: We analyze a large-scale EHR corpus and quantify redundancy both in terms of word and semantic concept repetition. We observe redundancy levels of about 30% and non-standard distribution of both words and concepts. We measure the impact of redundancy on two standard text-mining applications: collocation identification and topic modeling. We compare the results of these methods on synthetic data with controlled levels of redundancy and observe significant performance variation. Finally, we compare two mitigation strategies to avoid redundancy-induced bias: (i) a baseline strategy, keeping only the last note for each patient in the corpus; (ii) removing redundant notes with an efficient fingerprinting-based algorithm. (a)For text mining, preprocessing the EHR corpus with fingerprinting yields significantly better results. CONCLUSIONS: Before applying text-mining techniques, one must pay careful attention to the structure of the analyzed corpora. While the importance of data cleaning has been known for low-level text characteristics (e.g., encoding and spelling), high-level and difficult-to-quantify corpus characteristics, such as naturally occurring redundancy, can also hurt text mining. Fingerprinting enables text-mining techniques to leverage available data in the EHR corpus, while avoiding the bias introduced by redundancy.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“The over representation of certain SDoH factors because of the duplication impairs the training and evaluation of machine learning and deep learning models81,82.”
From Social determinants of health extraction from clinical notes across institutions using large language models (2025) · cites this paper as [82]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Basic local alignment search tool
Altschul, S. F., Gish, W., Miller, W., Myers, E. W., & Lipman, D. J. (1990) · Journal of Molecular Biology · doi:10.1006/jmbi.1990.9999 · Cited by 98,669
Gapped BLAST and PSI-BLAST: a new generation of protein database search programs
Altschul, S. (1997) · Nucleic Acids Research · doi:10.1093/nar/25.17.3389 · Cited by 73,302
(2003) · Journal of Machine Learning Research · doi:10.5555/944919.944937 · Cited by 32,337
Colowick, S. P., Joshi, M. D., Jagannathan, & KAPLAN, N. O. (1966) · Cited by 26,137
Advances in neural information processing systems 7
Cios, K. J., & Shields, M. E. (1997) · Neurocomputing · doi:10.1016/s0925-2312(97)90018-7 · Cited by 22,093
The Pfam Protein Families Database
Bateman, A. G. (2002) · Nucleic Acids Research · doi:10.1093/nar/30.1.276 · Cited by 14,075
Foundations of statistical natural language processing
Manning, C. D., & Schütze, H. (1999) · Cited by 9,816
(2004) · Cited by 9,718
The unified medical language system (UMLS): integrating biomedical terminology
Bodenreider, O. (2004) · Nucleic Acids Research · doi:10.1093/nar/gkh061 · Cited by 4,356
Advances in Neural Information Processing Systems 20
Bonilla, E. V., Chai, K. M. A., & Williams, C. K. I. (2008) · neural information processing systems · Cited by 2,701
Research works printed but not linked: 5
- Joshi M, Pedersen T, Maclin R Proceedings of the 2nd Indian International Conference on Artificial Intelligence (IICAI’05): 2005. A comparative study of support vector machines applied to the supervised word sense disambiguation problem in the medical domain 2005, 3449-3468.
- Zeng QT, Crowell J: Semantic classification of consumer health content. MEDNET Retrieved May 2008, 2006: 19.
- Yoshimasa Tsuruoka YT, Jin-Dong K, Tomoko O, Sophia A, Jun’ichi T Lecture Notes in Computer Science. Developing a Robust Part-of-Speech Tagger for Biomedical Text 2005.
- Baldridge J, Morton T, Bierner G Technical report, SourceForge. The opennlp maximum entropy package 2002.
- McCallum AK: Mallet: A machine learning for language toolkit. 2002.
Cited by
Sorted by citations
Miotto, R., Li, L., Kidd, B. A., & Dudley, J. T. (2016) · Scientific Reports · doi:10.1038/srep26094 · Cited by 1,710
De novo identification of differentially methylated regions in the human genome
Peters, T. J., Buckley, M. J., Statham, A. L., Pidsley, R., Samaras, K., Lord, R. V., Clark, S. J., & Molloy, P. L. (2015) · Epigenetics & Chromatin · doi:10.1186/1756-8935-8-6 · Cited by 982
Big data analytics for preventive medicine
Razzak, I., Imran, M. A., & Xu, G. (2019) · Neural Computing and Applications · doi:10.1007/s00521-019-04095-y · Cited by 362
Automated methods for the summarization of electronic health records
Perotte, R., & Elhadad, N. (2015) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocv032 · Cited by 227
Self-citationYou, Z., Chan, K. C. C., & Hu, P. (2015) · PLoS ONE · doi:10.1371/journal.pone.0125811 · Cited by 175
Metadata
- Authors
- Cohen, R., Elhadad, M., & Elhadad, N.
- Affiliations
- Ben-Gurion University of the Negev (IL)
- Columbia University (US)
- Corresponding author
- Cohen, Raphael
- Venue
- BMC Bioinformatics
- Published
- 2013-01-16
- Volume
- 14
- Issue
- 1
- Pages
- 10-10
- ISSN
- 1471-2105 (ISSN-L)
- PMC
- PMC3599108
- OpenAlex
- W2146408445
- Cited by
- 121
- References
- 61
- Citations by year
- 2026: 3 · 2025: 6 · 2024: 10 · 2023: 6 · 2022: 13 · 2021: 7 · 2020: 10 · 2019: 10 · 2018: 9 · 2017: 8 · 2016: 10 · 2015: 18 · 2014: 8 · 2013: 2
- FWCI
- 5.68
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- BMC Bioinformatics (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Funders
- U.S. National Library of Medicine
- Topics
- Health Sciences › Medicine › Health Informatics › Biomedical Text Mining and Ontologies
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Social Sciences › General Social Sciences › Computational and Text Analysis Methods
- Keywords
- electronic health records, clinical text, collocation identification, topic modeling, fingerprinting, data cleaning, named entity recognition, phenotype extraction, longitudinal patient records
- MeSH terms
- Algorithms, Humans, Semantics, Health Records, Personal, Data Mining, Electronic Health Records
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
