

Gene name errors: Lessons not learned
Open accessPublished version of a preprint
The DOI matches its Crossref record; 14 of the 15 references it cites were found in a registry or an index; 8 of the 9 sources its claims cite were checked for support.
Abstract
Erroneous conversion of gene names into other dates and other data types has been a frustration for computational biologists for years. We hypothesized that such errors in supplementary files might diminish after a report in 2016 highlighting the extent of the problem. To assess this, we performed a scan of supplementary files published in PubMed Central from 2014 to 2020. Overall, gene name errors continued to accumulate unabated in the period after 2016. An improved scanning software we developed identified gene name errors in 30.9% (3,436/11,117) of articles with supplementary Excel gene lists; a figure significantly higher than previously estimated. This is due to gene names being converted not just to dates and floating-point numbers, but also to internal date format (five-digit numbers). These findings further reinforce that spreadsheets are ill-suited to use with large genomic data.
Overview
CoChat Summary
TL;DR
Gene name errors in supplementary Excel files did not decline after a 2016 report; an improved scan found errors in 30.9% (3,436/11,117) of PubMed Central articles with supplementary Excel gene lists from 2014–2020. The higher rate is partly due to detection of five-digit internal date-format conversions, and errors remained stable over the period.
Key findings
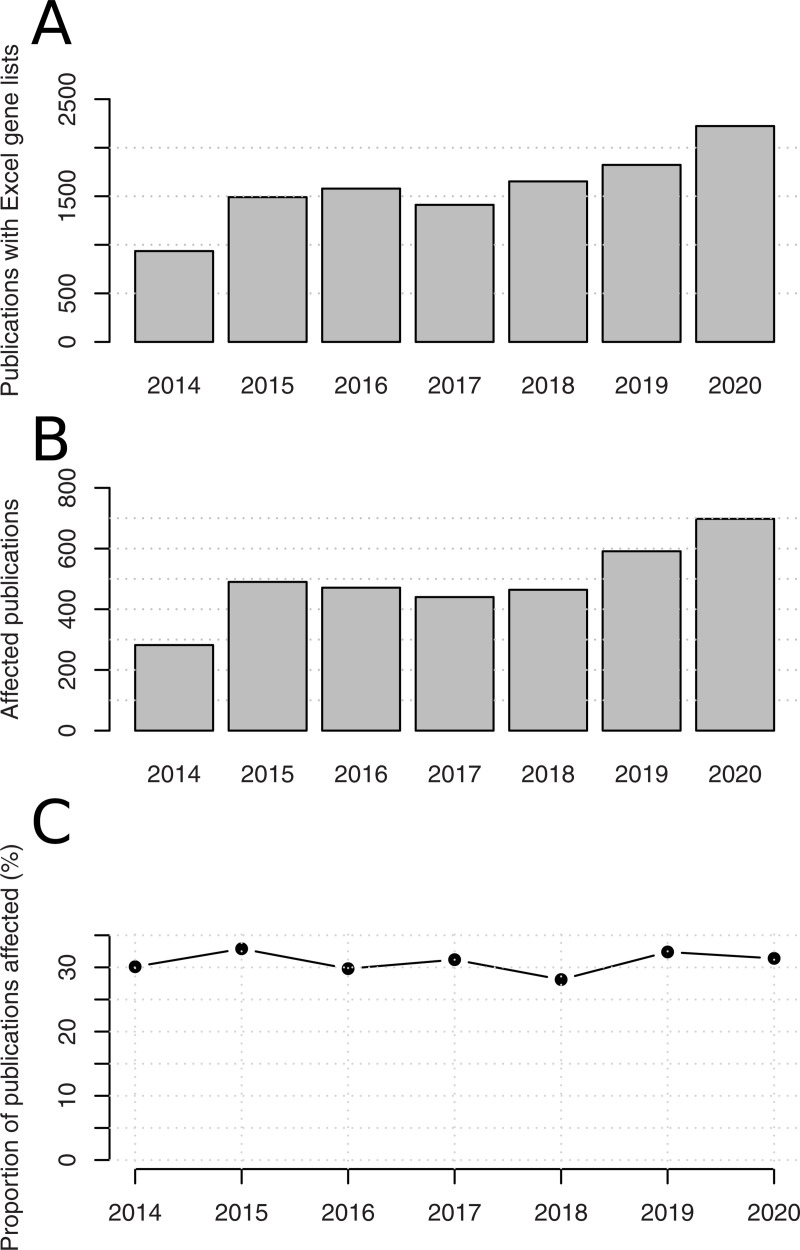
- In the PMC screen of 2014–2020, 166,139 publications were screened; 32,841 had Excel supplementary files, 11,117 had Excel gene lists, and 3,436 publications had confirmed gene name errors (30.9%), involving 5,086 spreadsheets. The proportion affected remained stable (e.g., 30.1% in 2014, 31.4% in 2020).
- Among 2,160 affected spreadsheet files, Mar-1/1-Mar dates accounted for 1,797 files (83.2%), DD/MM/YYYY for 19 (0.88%), floating-point numbers for 4 (0.18%), and five-digit numbers for 340 (15.7%); when five-digit numbers were formatted as dates, 292 (85.9%) fell in March and September.
- Across Eukarya, 1,544 gene names from 104 taxa were converted to dates; vertebrates had 1,325 affected genes in 76 taxa, fungi 140 genes in 12 taxa, plants 35 genes in 4 taxa, protists 27 genes in 9 taxa, and metazoa 17 genes in 3 taxa.
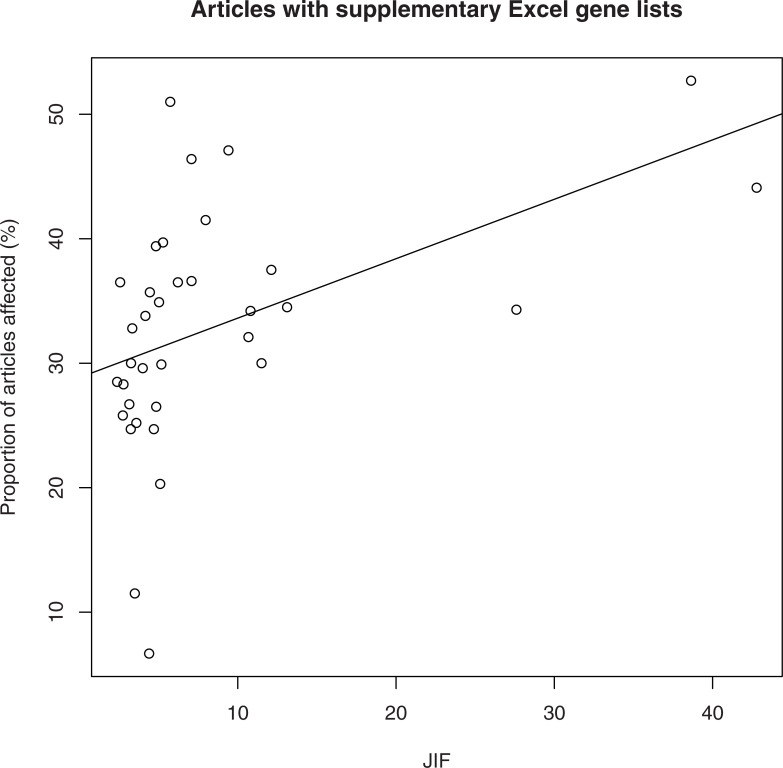
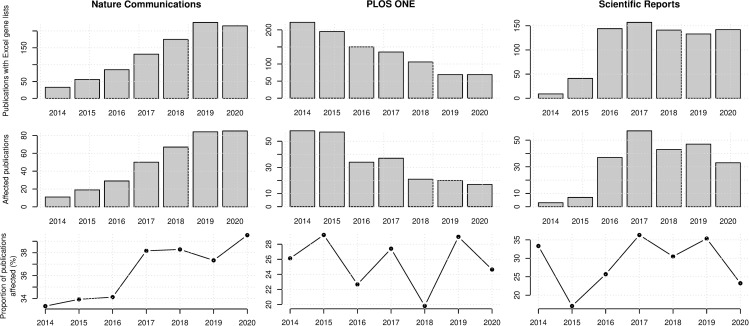
- By organism, the highest affected proportions were M. musculus 38.6% (609/1,577) and H. sapiens 30.5% (2,419/7,936), while lower rates included A. thaliana 14.9%, G. gallus 9.4%, and O. sativa 0.0%. Among journals with ≥50 articles with Excel gene lists, 37 journals accounted for 67.9% of affected publications, and journal impact factor correlated with affected proportion (Pearson p = 0.0052, r = 0.462; Spearman p = 1.95E-04, ρ = 0.589).
Methods
- Tested Microsoft Excel 365, Google Sheets, LibreOffice v6.4.6.2, and Gnumeric v1.12.46 for converting gene-name strings to dates via opening a text file, pasting data, and typing directly.
- Downloaded all eukaryotic gene annotation files from Ensembl (Vertebrates v102, Metazoa v49, Plants v49, Fungi v49, Protists v49), imported gene names into Excel, and sorted to count date conversions per taxon.
- Screened open-access PMC publications from 2014–2020 with “genom*” in the title or abstract; extracted .xls/.xlsx supplementary files; used R/readxl and ssconvert; flagged standard dates, floating-point numbers, and five-digit internal date formats; manually verified suspect files; and used R for summary statistics and two-sided Pearson/Spearman tests.
Limitations
- The paper states it only screened open-access articles in PMC, so results may not represent paywalled articles; it screened only a subset with “genom*” in the title or abstract, and it states it included only 116,139 (~5.0%) of 3,291,704 PMC articles from 2014–2020. The updated software yielded slightly more false positives but was manually verified; the script only identified vertical gene lists, so horizontal lists were likely missed.
- The paper states it did not quantitatively examine the hypothesis that the number and size of supplementary gene lists drive the journal/JIF trend.
- Evident from the text: the screening totals are inconsistent (166,139 reported in Results/Table 3 vs. 116,139 in Limitations), and the JIF association is observational, not causal.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
7 Valid · 3 Not valid · 1 Not checked · 60 Own results and interpretations
At least one cited source doesn’t support this claim or points to a different paper, and none confirmed it — see the verdicts below.
In the paper
“The proportion of publications with Excel gene lists that contain errors was 30.9%; substantially higher than previously reported [2].”
§ Gene name errors: Lessons not learned > Results > Gene name errors by year
What the sources say
- Disputedcites [2] Ziemann M, Eren Y, El-Osta A. Gene name errors are widespread in the scientific literature. Genome Biol. 2016; 17: 177. doi: 10.1186/s13059-016-1044-7 27552985 PMC4994289 sourceExperimental — accuracy not yet measured
The results passage (page unavailable) reports that 19.6% of papers with supplementary Excel gene lists in the 18 journals studied had gene-name errors, not 30.9%. The paper also does not say that this proportion was substantially higher than previously reported. (LLM, conf=0.88)
Checked by a reasoning model — may be wrong.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Disputed
Every source the paper cites for this claim was checked and supports it.
In the paper
“Previous work shows that gene name errors are made while researchers analyse and prepare supplementary files for publication [2].”
§ Gene name errors: Lessons not learned > Background
What the sources say
- Supportedcites [2] Ziemann M, Eren Y, El-Osta A. Gene name errors are widespread in the scientific literature. Genome Biol. 2016; 17: 177. doi: 10.1186/s13059-016-1044-7 27552985 PMC4994289 source
The paper reports that Excel inadvertently converts gene symbols to dates or numbers and confirms gene name errors in 987 supplementary files. It also recommends that researchers screen those files before submission, supporting the claim that such errors arise during analysis and preparation for publication. The passages in our copy have no page numbers. (LLM, conf=0.88)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“A screen of 18 journals found that one fifth of publications with supplementary Excel gene lists contained errors (704/3597).”
§ Gene name errors: Lessons not learned > Background
What the sources say
- Supportedcites [2] Ziemann M, Eren Y, El-Osta A. Gene name errors are widespread in the scientific literature. Genome Biol. 2016; 17: 177. doi: 10.1186/s13059-016-1044-7 27552985 PMC4994289 source
The results passage reports a screen of supplementary Excel files from 18 journals, finding gene lists in 3,597 papers and confirmed gene name errors in files from 704 of them. It gives the affected proportion as 19.6%, consistent with “one fifth.” (LLM, conf=0.95)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“The difficulty in auditing spreadsheets makes them generally incompatible with the principles of computational reproducibility [5].”
§ Gene name errors: Lessons not learned > Background
What the sources say
- Partly supportedcites [5] Peng R. Reproducible research in computational science. Science. 2011; 334; 1226– 1227. doi: 10.1126/science.1213847 22144613 PMC3383002 sourceExperimental — accuracy not yet measured
The paper's discussion of reproducibility (indexed as Abstract; no page given) says that analyses need available code and data, and that interactive software often fails to retain a record of users’ actions. This supports the concern about auditability, but the paper does not address spreadsheets specifically or say they are generally incompatible with computational reproducibility. (LLM, conf=0.84)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“This may seem counterintuitive, but is consistent with previous analysis [2].”
§ Gene name errors: Lessons not learned > Discussion
What the sources say
- Supportedcites [2] Ziemann M, Eren Y, El-Osta A. Gene name errors are widespread in the scientific literature. Genome Biol. 2016; 17: 177. doi: 10.1186/s13059-016-1044-7 27552985 PMC4994289 source
The passage indexed under “Abstract > Electronic supplementary material” (page not supplied) reports a positive correlation between journal impact factor and the proportion of supplementary gene lists affected by gene name errors. That supports the citing sentence’s statement that a higher error frequency in high-JIF journals is consistent with this previous analysis. (LLM, conf=0.93)
hedgedstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
31 more claims · 1 with their cited sources checked
Create a free account to see all 71 claims and every source verdict.
- It may state two separate claims as one. 24
- Probably not a substantial claim. 15
- The quote only partly states this claim. 1
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“Out of 3,291,704 articles in PMC published in the period 2014–2020, we included only 116,139 (~5.0%).”
§ Gene name errors: Lessons not learned > Discussion
Reported 5 · recomputed 3.528233
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Gene name errors: Lessons not learned > Results > Gene name errors by year
“We collated a list of 166,139 genomics articles published between 2014 and 2020”
§ Gene name errors: Lessons not learned > Discussion
“we included only 116,139 (~5.0%).”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Excel files with gene lists | 2286 | 3037 | 3331 | 3021 | 3566 | 3342 | 4496 | 23670 |”
§ Gene name errors: Lessons not learned > Results > Gene name errors by year
Reported 23670 · recomputed 23079
Citations
Cites
Reproducible research in computational science
Peng, R. D. (2011) · Science · doi:10.1126/science.1213847 · Cited by 1,449 · cited 2×
“The difficulty in auditing spreadsheets makes them generally incompatible with the principles of computational reproducibility [5].”
BackgroundWhat we know about spreadsheet errors
Panko, R. R. (1998) · Journal of Organizational and End User Computing · doi:10.4018/joeuc.1998040102 · Cited by 464
Baggerly, K. A., & Coombes, K. R. (2009) · The Annals of Applied Statistics · doi:10.1214/09-aoas291 · Cited by 312 · cited 1×
“In the biomedical research setting we know that spreadsheet errors can occur and impact downstream work involving clinical drug trials [14].”
BackgroundGuidelines for human gene nomenclature
Bruford, E. A., Braschi, B., Denny, P., Jones, T. E. M., Seal, R. L., & Tweedie, S. (2020) · Nature Genetics · doi:10.1038/s41588-020-0669-3 · Cited by 218
Prestigious Science Journals Struggle to Reach Even Average Reliability
Brembs, B. (2018) · Frontiers in Human Neuroscience · doi:10.3389/fnhum.2018.00037 · Cited by 213 · cited 1×
“Although it has been suggested that articles in highly prestigious journals are of an inferior methodological quality [6], the simpler explanation is that the number and size of supplementary gene lists accompanying articles is the main contributor to this trend (although we have not examined this hypothesis quantitat…”
BackgroundGene name errors are widespread in the scientific literature
Ziemann, M., Eren, Y., & El-Osta, A. (2016) · Genome Biology · doi:10.1186/s13059-016-1044-7 · Cited by 167
Self-citationZeeberg, B. R., Riss, J., Kane, D. W., Bussey, K. J., Uchio, E., Linehan, W. M., Barrett, J. C., & Weinstein, J. N. (2004) · BMC Bioinformatics · doi:10.1186/1471-2105-5-80 · Cited by 110
HGNChelper: identification and correction of invalid gene symbols for human and mouse
Oh, S., Abdelnabi, J., Al-Dulaimi, R., Aggarwal, A., Ramos, M., Davis, S. R., Riester, M., & Waldron, L. (2020) · F1000Research · doi:10.12688/f1000research.28033.1 · Cited by 70
Errors in Operational Spreadsheets
Powell, S. G., Baker, K. R., & Lawson, B. (2009) · Journal of Organizational and End User Computing · doi:10.4018/joeuc.2009070102 · Cited by 68
Hong, M. K. H., Yao, H. H. I., Pedersen, J. S., Peters, J. S., Costello, A. J., Murphy, D. G., Hovens, C. M., & Corcoran, N. M. (2013) · BMJ Open · doi:10.1136/bmjopen-2012-002406 · Cited by 67
Cited by
The five pillars of computational reproducibility: bioinformatics and beyond
Ziemann, M., Poulain, P., & Bora, A. (2023) · Briefings in Bioinformatics · doi:10.1093/bib/bbad375 · Cited by 121
“Indeed, spreadsheets are prone to data entry, manipulation and formula errors [30], leading to problems like inadvertent conversion of gene names to dates in databases and Supplementary Excel files available online at http://bib.oxfordjournals.org/ [31–33].”
BackgroundSelf-citationDempsey, W. P., Foster, I. T., Fraser, S. E., & Kesselman, C. (2022) · Harvard Data Science Review · doi:10.1162/99608f92.44d21b86 · Cited by 33
“Interestingly, this error frequency has not improved over time (Abeysooriya et al., 2021).”
Metadata integrity in bioinformatics: Bridging the gap between data and knowledge
Caliskan, A., Dangwal, S., & Dandekar, T. (2023) · Computational and Structural Biotechnology Journal · doi:10.1016/j.csbj.2023.10.006 · Cited by 32
“It has been known since 2004 that some gene names, such as MARCH3, SEPT8 and DEC1, can be autocorrected into dates in spread-sheets [67].”
BackgroundInfluentialTwo subtle problems with overrepresentation analysis
Ziemann, M., Schroeter, B., & Bora, A. (2024) · Bioinformatics Advances · doi:10.1093/bioadv/vbae159 · Cited by 39
Self-citationAuto-qPCR; a python-based web app for automated and reproducible analysis of qPCR data
Maussion, G., Thomas, R. A., Demirova, I., Gu, G., Cai, E., Chen, C. X. ‐., Abdian, N., Strauss, T. J. P., Kelaï, S., Nauleau-Javaudin, A., et al. (2021) · Scientific Reports · doi:10.1038/s41598-021-99727-6 · Cited by 25
Towards comprehensive integration and curation of chloroplast genomes
Hua, Z., Tian, D., Jiang, C., et al. (2022) · Plant Biotechnology Journal · doi:10.1111/pbi.13923 · Cited by 21
“With the accumulation of data, inaccurate taxonomic information (Locatelli et al., 2020), disunity of genomic terms (Abeysooriya et al., 2021), and other attendant problems have emerged, provoking significant challenges in employing chloroplast genomes.”
BackgroundEvolution and advancements in genomics and epigenomics in OA research: How far we have come
Ramos, Y. F., Rice, S. J., Ali, S. A., Pastrello, C., Jurišica, I., Rai, M. F., Collins, K. H., Lang, A., Maerz, T., Geurts, J., et al. (2024) · Osteoarthritis and Cartilage · doi:10.1016/j.joca.2024.02.656 · Cited by 21
Price, E., Feyertag, F., Evans, T. G., Miskin, J., Mitrophanous, K. A., & Dikicioǧlu, D. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae901 · Cited by 21
“Each bubble represents a specific cell line description, with the size indicating the frequency of occurrence in descriptions. often results in inadequate machine readability and inconsistencies, as demonstrated by the consistent gene name errors ( 24 ,25 ).”
Marone, M. P., Singh, H. C., Pozniak, C. J., & Mascher, M. (2022) · Plant Methods · doi:10.1186/s13007-022-00964-1 · Cited by 14
“One such application is Microsoft Excel, whose overzealous autocorrection unadapted to genomic sequence identi�ers poses certain risks (31), which we believe in the present case to be offset by the ease of editing in a graphical user interface most people are accustomed to.”
Background“Don’t let me be misunderstood”: Critical AI literacy for the constructive use of AI technology
Strauß, S. (2021) · TATuP - Zeitschrift für Technikfolgenabschätzung in Theorie und Praxis · doi:10.14512/tatup.30.3.44 · Cited by 44
Gene Updater: a web tool that autocorrects and updates for Excel misidentified gene names
Koh, C. W., Ooi, J. S. G., Joly, G. L. C., & Chan, K. R. (2022) · Scientific Reports · doi:10.1038/s41598-022-17104-3 · Cited by 11
Autocorrect errors in Excel still creating genomics headache
Lewis, D. (2021) · Nature · doi:10.1038/d41586-021-02211-4 · Cited by 13
Chen, T., Vahab, N., Tyagi, N., Cummins, E., Peleg, A. Y., & Tyagi, S. (2023) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2023.05.31.542682 · Cited by 8
Wiegand, F., Laehnemann, D., Mölder, F., Uzuner, H., Prinz, A. D., Schramm, A. R., & Köster, J. (2025) · PLoS ONE · doi:10.1371/journal.pone.0323079 · Cited by 8
Janča, O., Ochodková, E., Kriegová, E., Hořák, P., Skácelová, M., & Kudělka, M. (2023) · Applied Network Science · doi:10.1007/s41109-023-00582-3 · Cited by 7
“Since these problems prevail (Abeysooriya et al. 2021), data analysis methodology must adapt to overcome them.”
BackgroundYeung, A. W. K. (2022) · International Journal of Environmental Research and Public Health · doi:10.3390/ijerph19041933 · Cited by 6
“The renaming was due to clinico-histopathological considerations, unlike certain gene names being renamed due to paronomasia [38] or to avoid autocorrection errors by software such as Excel [39].”
MethodEleven quick tips for properly handling tabular data
Hertz, M. I., & McNeill, A. S. (2024) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1012604 · Cited by 6
“For example, faulty spreadsheet practices have led to errors in gene names [2,3], lost COVID-19 cases [4], and one study on healthcare in Ireland found that over 90% of the spreadsheets they examined were faulty [5].”
reanalyzerGSE: tackling the everlasting lack of reproducibility and reanalyses in transcriptomicsPreprint
Ruiz, J. L., Terron-Camero, L. C., Castillo-González, J., Fernández-Rengel, I., Delgado, M., González‐Rey, E., & Andrés‐León, E. (2023) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2023.07.12.548663 · Cited by 8
“…[31, 36, 37], or functional enrichment [38-40]), and 4) diverse errors ( e.g. insufficient reporting [41], errors in gene naming errors [42, 43], complex software [44-46], or data handling [47]) To overcome these, amongst others, we introduce here reanalyzerGSE, an easy-to-use pipeline…”
BackgroundChristen, P., & Schnell, R. (2024) · Harvard Data Science Review · doi:10.1162/99608f92.34f8e75b · Cited by 8
Reporting Chemical Data in the Environmental Sciences
Baskaran, S., Chirsir, P., Joudan, S., Wolf, R. L., Bolton, E., Thiessen, P. A., & Schymanski, E. (2025) · ACS Environmental Au · doi:10.1021/acsenvironau.5c00034 · Cited by 5
Juszczak, G. R., Pareek, C. S., Czarnik, U., & Pierzchała, M. (2025) · BMC Genomics · doi:10.1186/s12864-025-12329-8 · Cited by 3
Relational Databases for Behavior Science
Soto, P. L. (2025) · Perspectives on Behavior Science · doi:10.1007/s40614-025-00486-w · Cited by 3
“For example, Excel’s autocorrect feature has been repeatedly reported to cause issues with gene names that Excel interprets as dates (Abeysooriya et al., 2021; Zeeberg et al., 2004; Ziemann et al., 2016).”
Wang, T. D., Murphy, S. N., Castro, V. M., & Klann, J. G. (2025) · medRxiv · doi:10.1101/2025.04.17.25325962 · Cited by 2
Techniques, procedures, and applications in host genetic analysis
Bonilla, D. A., Orozco, C. A., Forero, D. A., & Odriozola, A. (2024) · Advances in genetics · doi:10.1016/bs.adgen.2024.05.001 · Cited by 3
Improving Reproducibility in Epidemiology
Dunbar, M. B., & Held, L. (2024) · Springer eBooks · doi:10.1007/978-1-4614-6625-3_73-1 · Cited by 9
Let's Put the Science in eScience
Kesselman, C., Schuler, R. E., & Foster, I. T. (2023) · IEEE International Conference on eScience · doi:10.1109/e-science58273.2023.10254914 · Cited by 1
Retracted articles use less free and open-source software and cite it worse
Schindler, D., Yan, E., Spors, S., & Krüger, F. (2023) · Quantitative Science Studies · doi:10.1162/qss_a_00275 · Cited by 2
“It has, for instance, been shown that about 31% of research data from human gene analyses processed with Microsoft Excel were altered by the software ’ s auto conversion features (Abeysooriya, Soria et al., 2021).”
BackgroundRetractedCreating a Tools Ecosystem for Cross-Discipline Environmental Data Reuse
Logan, J. S., Agasthya, G. A., Hanson, H. A., et al. (2021) · 2021 IEEE International Conference on Big Data (Big Data) · doi:10.1109/bigdata52589.2021.9671683 · Cited by 1
“Not only can this impact the ability to reuse or reproduce results later, but it can also mask significant (if accidental) data corruption issues like those that occurred with the use of Excel for genetic data [12] or COVID incidence [13].”
BackgroundThe Sequence and the Standard: An Account of Participatory Informational Format Exclusion (PIFE)
Sheehan, N. (2026) · Social Epistemology · doi:10.1080/02691728.2026.2682153
“The history of scientific error is littered with data type mistakes, but few cases have made the problem as legible as the discovery that Excel had been quietly renaming genes as dates for years (Abeysooriya et al. 2021).”
Reproducible Data Analysis With R in Laboratory Hematology
Obstfeld, A. E. (2026) · International Journal of Laboratory Hematology · doi:10.1111/ijlh.70147
Yeung, A. W. K. (2026) · Scientometrics · doi:10.1007/s11192-026-05642-w
“The original and follow-up reports have shown that the prevalence of such errors are in the range of 19.6–30.9% (Abeysooriya et al., 2021; Ziemann et al., 2016).”
InfluentialCatalyzing computational biology research at an academic institute through an interest network
Žák, J., Newman, I. A., Garcia, D. J. M., Parisi, D., Joy, J., Head, S. R., Ducom, J.-C., Natarajan, P., Cui, H., & Ul-Hasan, S. (2025) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1013453 · Cited by 1
“Similarly, default settings in software such as Microsoft Excel have led to preventable errors, such as converting gene names into calendar dates, causing data loss [9,10].”
PSManalyst: A Dashboard for Visual Quality Control of FragPipe Results
Chaves, A. F. A. (2025) · Journal of Proteome Research · doi:10.1021/acs.jproteome.5c00557
Wiegand, F., Laehnemann, D., Mölder, F., et al. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2025.04.03.647146
“Finally, multiple investigations of supplementary Excel files show, that the automated conversion of certain values can lead to the misinterpretation of data: for example, gene names such as SEPT2 (Septin 2) are inadvertently converted into dates, leading to errors in genomic research [1], [2].”
Catalyzing computational biology research at an academic institute through an interest networkPreprint
Žák, J., Newman, I. A., Garcia, D. J. M., et al. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2025.01.05.631403
Relational Databases with MariaDB
Wünschiers, R. (2025) · Springer eBooks · doi:10.1007/978-3-031-70314-0_16
Marone, M. P., Singh, H. C., Pozniak, C. J., et al. (2022) · Research Square · doi:10.21203/rs.3.rs-2059469/v1
Metadata
- Authors
- Abeysooriya, M., Soria, M., Kasu, M. S., & Ziemann, M.
- Affiliations
- Deakin University (AU)
- Corresponding author
- Ziemann, Mark
- Venue
- PLOS Computational Biology
- Publisher
- Public Library of Science (PLoS)
- Published
- 2021-07-30
- Volume
- 17
- Issue
- 7
- Pages
- e1008984
- ISSN
- 1553-734X (ISSN-L)
- 1553-7358
- PMC
- PMC8357140
- OpenAlex
- W3183904002
- Cited by
- 39
- References
- 15
- Citations by year
- 2026: 4 · 2025: 8 · 2024: 7 · 2023: 9 · 2022: 5 · 2021: 6
- FWCI
- 6.10
- Type
- journal article
- Language
- en
- Update notices
- new_version (2021-08-11)
- Open access
- gold
- doi.org
- Licence
- Locations
- PLoS Computational Biology (publishedVersion, cc-by)
- bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Figshare (submittedVersion, cc-by)
- Funders
- Monash University
- Topics
- Physical Sciences › Computer Science › Information Systems › Research Data Management Practices
- Health Sciences › Medicine › Health Informatics › Biomedical Text Mining and Ontologies
- Social Sciences › Decision Sciences › Information Systems and Management › Scientific Computing and Data Management
- Keywords
- spreadsheet software, Microsoft Excel, genomic data, data quality, PubMed Central, type conversion
- MeSH terms
- Genes, Humans, Terminology as Topic, Software, Computational Biology, PubMed, Molecular Sequence Annotation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-01, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-01 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
